

1. शुरू करने से पहले
एआई एजेंट, कई दिनों तक चलने वाली लंबी बातचीत को हैंडल करते हैं. साथ ही, वे कई चरणों वाले ऐसे टास्क पूरे करते हैं जिनमें लंबा समय लगता है. इसलिए, लार्ज लैंग्वेज मॉडल (एलएलएम) को सेशन के दौरान किसी भी तरह की जानकारी सेव करने की ज़रूरत नहीं होती. जब कोई उपयोगकर्ता अगले दिन किसी एजेंट के पास वापस आता है, तो मॉडल शुरू से काम करना शुरू कर देता है. ऐसा तब तक होता है, जब तक ऐप्लिकेशन ज़रूरी कॉन्टेक्स्ट को फिर से नहीं बना लेता.
इस समस्या को हल करने का एक सामान्य तरीका टोकन स्टफ़िंग है. इसमें बातचीत के पूरे इतिहास, टूल के इस्तेमाल के लॉग, और कोडबेस को सीधे तौर पर हर ऐक्टिव प्रॉम्प्ट में जोड़ दिया जाता है. तकनीकी तौर पर, लाखों टोकन वाली बड़ी कॉन्टेक्स्ट विंडो की मदद से ऐसा किया जा सकता है. हालांकि, कॉन्टेक्स्ट स्टफ़िंग से कई तरह की समस्याएं होती हैं: हर बार टोकन की लागत तेज़ी से बढ़ती है, जवाब मिलने में कई सेकंड लगते हैं, और मॉडल में "बीच में खो जाने" की समस्या होती है.
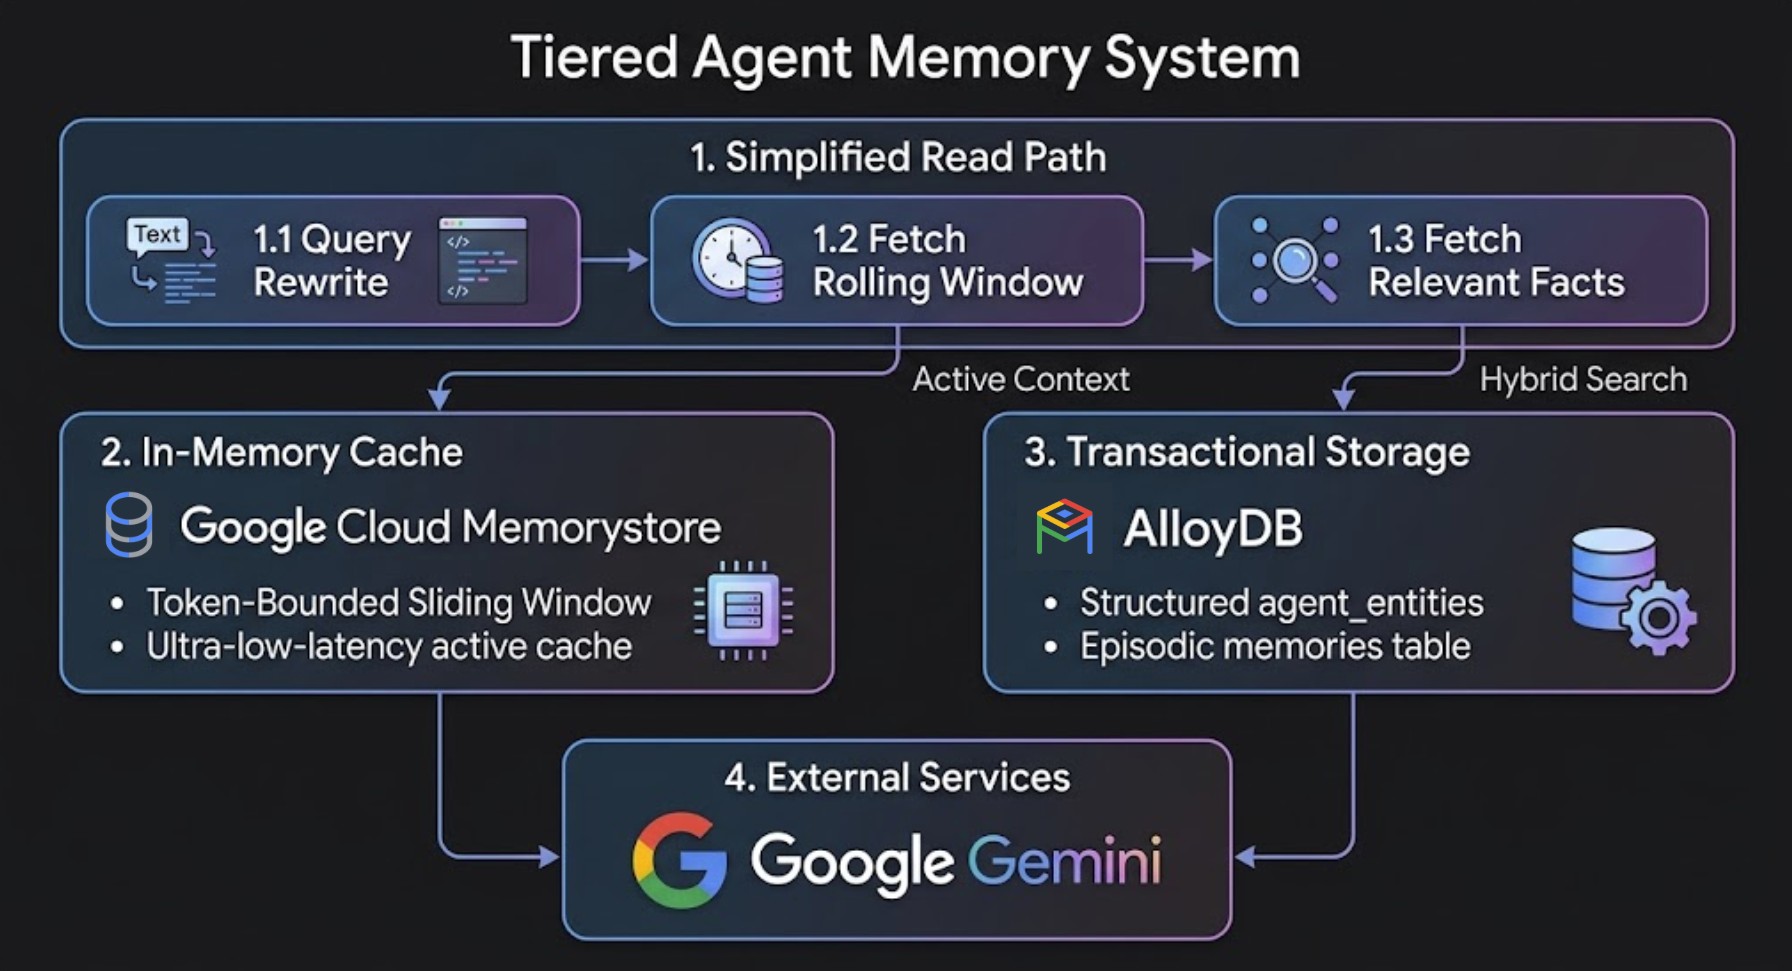
भरोसेमंद एआई एजेंट बनाने के लिए, आपको दो लेयर वाली मेमोरी आर्किटेक्चर की ज़रूरत होती है:
- कम समय के लिए सेशन बफ़र: यह टोकन-बाउंडेड स्लाइडिंग विंडो का इस्तेमाल करके, हाल ही में हुई बातचीत को ऐक्टिव मेमोरी में कैश मेमोरी के तौर पर सेव करता है. इस टियर में, हर टर्न पर मिलीसेकंड से भी कम समय में, मेमोरी में मौजूद डेटा को तेज़ी से ऐक्सेस करने की ज़रूरत होती है. इसलिए, Memorystore for Valkey सबसे सही विकल्प है.
- लंबे समय तक सेव रहने वाली मेमोरी: यह अलग-अलग सेशन में, स्ट्रक्चर्ड एंटिटी, उपयोगकर्ता की प्राथमिकताएं, और एपिसोड से जुड़े तथ्य सेव करती है. इस टियर के लिए, लेन-देन की अखंडता, एक से ज़्यादा किरायेदार के लिए सुरक्षा, और रिलेशनल डेटा और वेक्टर के बीच हाइब्रिड तरीके से डेटा वापस पाने की सुविधा ज़रूरी होती है. इसलिए, AlloyDB for PostgreSQL सही विकल्प है.
चार तरह की मेमोरी को समझना
मज़बूत मेमोरी आर्किटेक्चर, उपयोगकर्ता के पूरे सफ़र में चार तरह की मेमोरी पर निर्भर करता है:
मेमोरी का टाइप | यह कुकी क्या सेव करती है | स्टोरेज लेयर | जीवनकाल |
बफ़र (कम समय के लिए) | हाल ही में की गई बातचीत के सेट | Memorystore for Valkey | ऐक्टिव सेशन |
खास जानकारी वाली मेमोरी | बातचीत के पुराने टर्न का छोटा किया गया इतिहास | Memorystore for Valkey | सिलसिलेवार बातचीत की विंडो |
एपिसोडिक मेमोरी | पिछली कार्रवाइयां, इवेंट, और टूल के आउटपुट | AlloyDB for PostgreSQL (वेक्टर) | स्थायी |
इकाई और नियम की मेमोरी | उपयोगकर्ता की प्राथमिकताएं, शर्तें, और वीटो | AlloyDB for PostgreSQL (स्ट्रक्चर्ड SQL + वेक्टर) | स्थायी |
टायर्ड मेमोरी के असर का आकलन
कई बार बातचीत करने की सुविधा के साथ डेवलपमेंट डायलॉग (45 से ज़्यादा बार बातचीत करने की सुविधा और टूल के आउटपुट लॉग) के लिए, इंटरनल बेंचमार्क टेस्टिंग से पता चला है कि कॉन्टेक्स्ट स्टफ़िंग की तुलना में, काफ़ी बचत हुई है:
मेट्रिक / डाइमेंशन | कॉन्टेक्स्ट स्टफ़िंग | टायर्ड मेमोरी (AlloyDB + Memorystore) | जांच के दौरान कुल असर |
चालू प्रॉम्प्ट का साइज़ (टर्न 45) | 7,47,033 टोकन | 83,262 टोकन | 88.9% छोटा प्रॉम्प्ट |
जवाब देने में लगने वाले समय को 45 सेकंड पर सेट करना | 33.5 सेकंड | 6.7 सेकंड | 80.0% तेज़ी से जवाब मिलता है |
कुल सेशन टोकन | 1.79 करोड़ टोकन | 40 लाख 90 हज़ार टोकन | कुल टोकन और लागत में 72.0% की बचत हुई |
नियम और शर्तों को याद रखना | मोड़ पर कम हो जाती है | जवाब में ज़रूरी जानकारी को शामिल किया जाता है | हाइब्रिड सर्च के ज़रिए सुरक्षित रखा गया |
आपको क्या करना होगा
- PostgreSQL के लिए AlloyDB और Memorystore for Valkey को प्रोविज़न करें.
google_ml_integrationचालू करें और डेटाबेस-साइड ट्रांज़ैक्शनल ऑटो-एम्बेडिंग (ai.initialize_embeddings) को कॉन्फ़िगर करें.- 'जवाब छोटा करने से पहले जानकारी इकट्ठा करो' पाइपलाइन पैटर्न का इस्तेमाल करके, कम समय के लिए Valkey सेशन बफ़र लागू करें.
- AlloyDB के नेटिव एआई फ़ंक्शन (जैसे,
ai.generate) का इस्तेमाल करके, लंबी अवधि की इकाइयों को नेटिव तौर पर एक्सट्रैक्ट करना - AlloyDB के नेटिव हाइब्रिड सर्च फ़ंक्शन (
ai.hybrid_search) और Reciprocal Rank Fusion (RRF) रीरैंकिंग का इस्तेमाल करके, लंबे समय तक के तथ्यों के बारे में क्वेरी करें. साथ ही, सटीक और काम की जानकारी पाएं. - तीन टियर वाला एंटरप्राइज़ टूल, अनुमतियों का आकलन करने वाला टूल, और बैकग्राउंड मेमोरी कंपैक्शन इंजन बनाओ.
- Google एजेंट डेवलपमेंट किट (एडीके) का इस्तेमाल करके, दो टियर वाले मेमोरी आर्किटेक्चर को सीधे तौर पर अपने-आप काम करने वाले एजेंट में इंटिग्रेट करें.
आपको किन चीज़ों की ज़रूरत होगी
- बिलिंग की सुविधा वाला Google क्लाउड प्रोजेक्ट.
- कोई वेब ब्राउज़र, जैसे कि Chrome.
- Python और एसक्यूएल की बुनियादी जानकारी. साथ ही, Studio, CLI वगैरह से AlloyDB के ख़िलाफ़ एसक्यूएल क्वेरी चलाने का अनुभव.
ऑडियंस और लागत
- दर्शक: एआई डेवलपर, बैकएंड इंजीनियर, और डेटाबेस आर्किटेक्ट.
- अनुमानित लागत: इस कोडलैब में बनाए गए Google Cloud संसाधनों की लागत करीब 1.50 डॉलर होगी.
2. सेटअप और ज़रूरी शर्तें
Cloud Shell शुरू करना
इस कोडलैब में, Google Cloud Shell में कमांड चलाई जाएंगी. यह क्लाउड पर होस्ट किया गया टर्मिनल है, जिसमें gcloud, psql, और python3 पहले से कॉन्फ़िगर किए गए हैं.
- Google Cloud Console खोलें.
- Cloud Console में सबसे ऊपर दाईं ओर मौजूद, Cloud Shell चालू करें पर क्लिक करें.
- पुष्टि करें:
gcloud auth list
export PROJECT_ID=<YOUR_PROJECT_ID>
gcloud config set project $PROJECT_ID

export REGION=us-east1
export GENAI_LOCATION=us
export ZONE=us-east1-b
export ADBCLUSTER=agent-memory-cluster
export ADBINSTANCE=agent-memory-instance
export VALKEYINSTANCE=agent-memory-cache
export VM_NAME=agent-dev-vm
Google Cloud API चालू करना और डेवलपमेंट VM बनाना
ज़रूरी एपीआई चालू करने के लिए, Cloud Shell में यह कमांड चलाएं:
gcloud services enable \
  alloydb.googleapis.com \
  memorystore.googleapis.com \
  aiplatform.googleapis.com \
  compute.googleapis.com \
  servicenetworking.googleapis.com \
  networkconnectivity.googleapis.com
AlloyDB और Memorystore for Valkey के साथ-साथ Python डेवलपमेंट एनवायरमेंट को होस्ट करने के लिए, default वीपीसी नेटवर्क में Compute Engine VM इंस्टेंस बनाएं:
gcloud compute instances create $VM_NAME \
    --zone=$ZONE \
    --machine-type=e2-standard-2 \
    --scopes=cloud-platform \
    --network=default \
    --shielded-secure-boot
3. AlloyDB और Memorystore for Valkey को चालू करना
इस चरण में, आपको AlloyDB for PostgreSQL क्लस्टर और प्राइमरी इंस्टेंस को प्रोविज़न करना होगा. साथ ही, प्राइवेट सर्विस नेटवर्किंग सेट अप करनी होगी और Memorystore for Valkey इंस्टेंस को स्पिन अप करना होगा.
प्राइवेट सर्विस ऐक्सेस के लिए आईपी पतों की रेंज बनाना
AlloyDB के लिए, आपके वर्चुअल प्राइवेट क्लाउड (VPC) नेटवर्क में निजी आईपी पते की ज़रूरत होती है. मान लें कि default वीपीसी नेटवर्क का इस्तेमाल किया जा रहा है:
- निजी आईपी पते की रेंज असाइन करें:
gcloud compute addresses create psa-range \
    --global \
    --purpose=VPC_PEERING \
    --prefix-length=24 \
    --description="VPC private service access" \
    --network=default
- निजी वीपीसी पीयरिंग कनेक्शन बनाएं:
gcloud services vpc-peerings connect \
    --service=servicenetworking.googleapis.com \
    --ranges=psa-range \
    --network=default
AlloyDB क्लस्टर और प्राइमरी इंस्टेंस बनाना
- सिस्टम को शुरू करने के लिए, क्लस्टर का शुरुआती पासवर्ड बनाएं:
export PGPASSWORD=`openssl rand -hex 12`
- मुफ़्त में आज़माने की सुविधा वाला क्लस्टर बनाएं:
gcloud alloydb clusters create $ADBCLUSTER \
    --password=$PGPASSWORD \
    --network=default \
    --region=$REGION \
    --subscription-type=TRIAL
- प्राइमरी इंस्टेंस बनाएं:
gcloud alloydb instances create $ADBINSTANCE \
    --instance-type=PRIMARY \
    --cpu-count=2 \
    --region=$REGION \
    --cluster=$ADBCLUSTER
Memorystore for Valkey इंस्टेंस को प्रोविज़न करना
Memorystore for Valkey इंस्टेंस बनाने से पहले, आपके नेटवर्क और क्षेत्र में सेवा कनेक्शन नीति (gcp-memorystore) लागू होनी चाहिए.
- Memorystore के लिए सेवा कनेक्शन की नीति बनाएं:
gcloud network-connectivity service-connection-policies create memorystore-policy \
    --network=default \
    --region=$REGION \
    --service-class=gcp-memorystore \
    --subnets=projects/$PROJECT_ID/regions/$REGION/subnetworks/default
- Memorystore for Valkey इंस्टेंस बनाएं:
gcloud memorystore instances create $VALKEYINSTANCE \
    --location=$REGION \
    --shard-count=1 \
    --replica-count=0 \
    --node-type=SHARED_CORE_NANO \
    --psc-auto-connections="network=projects/$PROJECT_ID/global/networks/default,projectId=$PROJECT_ID"
Vertex AI के लिए IAM अनुमतियां देना
AlloyDB सेवा खाते को, Agent Platform के एम्बेडिंग मॉडल को चालू करने के लिए, ज़रूरी IAM अनुमतियां दें:
PROJECT_ID=$(gcloud config get-value project)

gcloud projects add-iam-policy-binding $PROJECT_ID \
  --member="serviceAccount:service-$(gcloud projects describe $PROJECT_ID --format="value(projectNumber)")@gcp-sa-alloydb.iam.gserviceaccount.com" \
  --role="roles/aiplatform.user"
4. Environment और Access Endpoints को शुरू करना
AlloyDB में आईएएम की मदद से पुष्टि करने की सुविधा और डेटाबेस फ़्लैग सेट अप करना
अपने AlloyDB इंस्टेंस पर, आईएएम डेटाबेस पुष्टि (alloydb.iam_authentication=on) और एआई क्वेरी इंजन (google_ml_integration.enable_ai_query_engine=on) को चालू करें:
gcloud beta alloydb instances update $ADBINSTANCE \
  --cluster=$ADBCLUSTER \
  --region=$REGION \
  --update-mode=FORCE_APPLY \
  --database-flags=alloydb.iam_authentication=on,google_ml_integration.enable_ai_query_engine=on
इसके बाद, अपने Google Cloud खाते को आईएएम पर आधारित डेटाबेस उपयोगकर्ता के तौर पर जोड़ें. इसके लिए, आपके पास सुपरयूज़र की अनुमतियां होनी चाहिए:
export USER_ACCOUNT=$(gcloud config get-value account)

gcloud alloydb users create $USER_ACCOUNT \
    --cluster=$ADBCLUSTER \
    --region=$REGION \
    --type=IAM_BASED \
    --db-roles=alloydbsuperuser
Cloud Shell में इंटरनल वीपीसी एंडपॉइंट वापस पाना
अपने डेवलपमेंट वीएम में SSH करने से पहले, Cloud Shell में AlloyDB और Memorystore for Valkey के लिए, इंटरनल वीपीसी आईपी पते पाएं:
# Export GCP Project ID, Region, and IAM User
export PROJECT_ID=$(gcloud config get-value project)
export REGION=us-east1
export DB_USER=$(gcloud config get-value account)

# Retrieve Internal VPC IP Addresses for AlloyDB & Memorystore for Valkey
export DB_HOST=$(gcloud alloydb instances describe $ADBINSTANCE --cluster=$ADBCLUSTER --region=$REGION --format="value(ipAddress)")
export DB_PORT=5432
export DB_NAME=postgres

export VALKEY_HOST=$(gcloud memorystore instances describe $VALKEYINSTANCE --location=$REGION --format="value(discoveryEndpoints[0].address)")
export VALKEY_PORT=6379

# Verify exported endpoints
echo "Project ID:        $PROJECT_ID"
echo "Region:            $REGION"
echo "AlloyDB Private IP: $DB_HOST"
echo "IAM DB User:       $DB_USER"
echo "Valkey Private IP:  $VALKEY_HOST"
डेवलपमेंट वीएम में एसएसएच करें और कनेक्शन वैरिएबल एक्सपोर्ट करें
Cloud Shell से, उसी VPC नेटवर्क में मौजूद Compute Engine डेवलपमेंट वीएम (agent-dev-vm) में एसएसएच करें:
gcloud compute ssh $VM_NAME --zone=$ZONE
अपने डेवलपमेंट VM में लॉग इन करने के बाद, ऊपर दिए गए प्रोजेक्ट कॉन्फ़िगरेशन और कनेक्शन एंडपॉइंट का आउटपुट एक्सपोर्ट करें. इसके लिए,
export PROJECT_ID=<YOUR_PROJECT_ID>
export REGION=us-east1
export GENAI_LOCATION=us
export DB_HOST=<YOUR_ALLOYDB_PRIVATE_IP>
export DB_PORT=5432
export DB_NAME=postgres
export DB_USER=<YOUR_IAM_DB_USER>
export VALKEY_HOST=<YOUR_VALKEY_PRIVATE_IP>
export VALKEY_PORT=6379
Python वर्चुअल एनवायरमेंट शुरू करना
अपने डेवलपमेंट वीएम में, सबसे पहले अपनी लोकल वर्किंग डायरेक्ट्री बनाएं:
mkdir -p ~/alloydb_agent_memory && cd ~/alloydb_agent_memory
अब, सिस्टम के Python वर्चुअल एनवायरमेंट पैकेज इंस्टॉल करें, ऐप्लिकेशन के डिफ़ॉल्ट क्रेडेंशियल (एडीसी) की पुष्टि करें, और अपना वर्कस्पेस सेट अप करें:
sudo apt-get update && sudo apt-get install -y python3-venv python3-pip

python3 -m venv venv
source venv/bin/activate
आखिर में, नए वर्चुअल एनवायरमेंट में हम डिपेंडेंसी इंस्टॉल करेंगे:
gcloud auth application-default login
pip install psycopg2-binary valkey redis google-genai
5. सिस्टम आर्किटेक्चर और कोड मॉड्यूल का क्रम
बनाए जा रहे प्रॉडक्ट की खास जानकारी
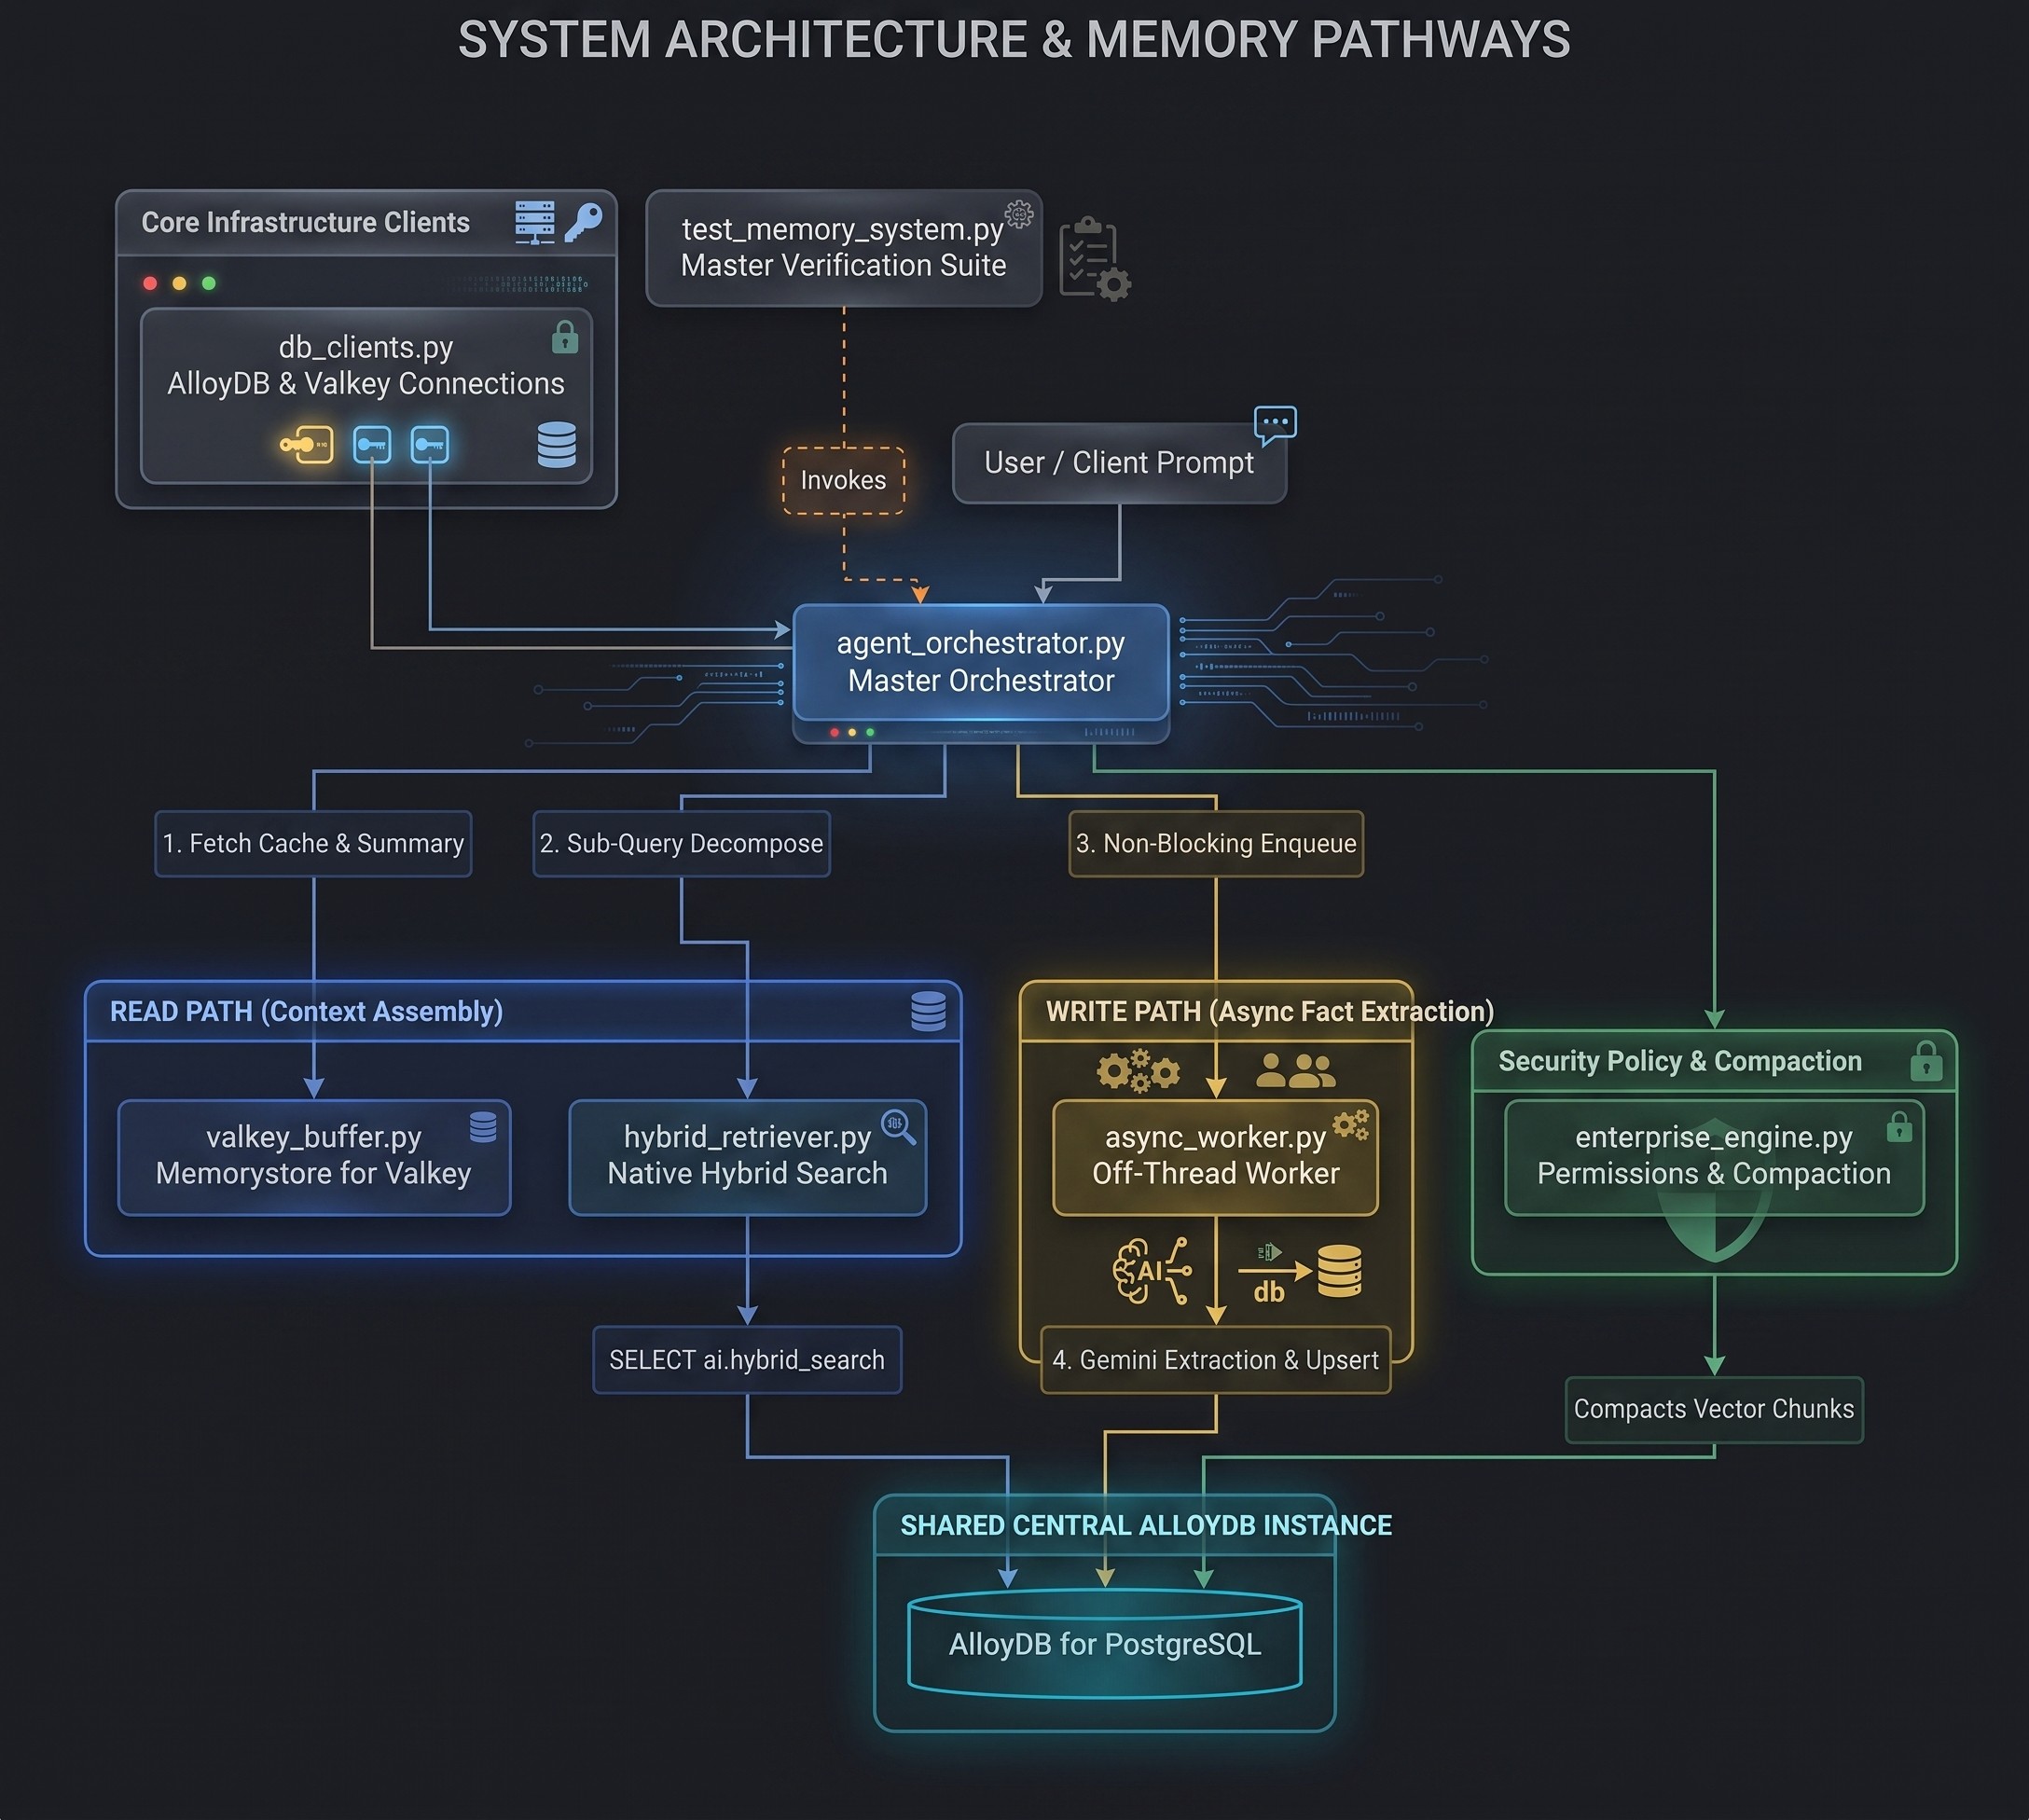
अलग-अलग Python स्क्रिप्ट लागू करने से पहले, यहां दिए गए सिस्टम आर्किटेक्चर की समीक्षा करें. इस सैंपल ऐप्लिकेशन को सात मॉड्यूलर Python स्क्रिप्ट में बांटा गया है. ये स्क्रिप्ट, दो मुख्य एक्ज़ीक्यूशन पाथ पर काम करती हैं. ये दोनों पाथ, एक ही AlloyDB for PostgreSQL डेटाबेस इंस्टेंस से इंटरैक्ट करते हैं:
- रीड पाथ (
hybrid_retriever.py): यह एक से ज़्यादा हिस्सों वाले मुश्किल सवालों को, एक पहलू वाली सब-क्वेरी में बदलता है. इसके लिए, सीधे तौर पर PostgreSQL में AlloyDB AIai.generate()का इस्तेमाल किया जाता है. साथ ही, यह AlloyDB की नेटिव हाइब्रिड खोज (ai.hybrid_search) का इस्तेमाल करके, लंबे समय तक सेव रखी गई जानकारी से क्वेरी करता है. - लिखने का पाथ (
async_worker.py): यह थ्रेड से बाहर काम करने वाला बैकग्राउंड वर्कर है. यह Gemini Flash का इस्तेमाल करके, बातचीत से स्ट्रक्चर्ड इकाई के तथ्यों को एसिंक्रोनस तरीके से निकालता है और उन्हेंagent_entitiesमें अपसर्ट करता है.
मॉड्यूल हैरारकी और सिस्टम की भूमिकाएं
मॉड्यूल फ़ाइल | सिस्टम लेयर | मुख्य ज़िम्मेदारी |
| कनेक्शन लेयर | यह AlloyDB के लिए, एसएसएल-एन्क्रिप्ट (सुरक्षित) किए गए IAM की पुष्टि करने की सुविधा और Memorystore for Valkey के लिए, सॉकेट-रेज़िलिएंट कनेक्शन की सुविधा उपलब्ध कराता है. |
| अल्पकालिक मेमोरी | यह कुकी, Valkey में मिलीसेकंड से भी कम समय के सेशन के इतिहास को मैनेज करती है. साथ ही, Summarize-Before-Trim रोलिंग की खास जानकारी को लागू करती है. |
| Write Path Worker | यह थ्रेड से बाहर काम करने वाला डेमॉन बैकग्राउंड क्यू वर्कर चलाता है. यह Gemini Flash का इस्तेमाल करके, इकाई के तथ्यों को निकालता है और उन्हें AlloyDB में अपसर्ट करता है. |
| पाथ रिट्रीवर के बारे में जानकारी | यह AlloyDB AI |
| मुख्य एजेंट लूप | यह एंड-टू-एंड टर्न एक्ज़ीक्यूशन लूप को कोऑर्डिनेट करता है: कम समय में फ़ेच करना, लंबे समय तक खोजना, प्रॉम्प्ट असेंबल करना, एलएलएम एक्ज़ीक्यूट करना, और एसिंक्यू इनक्यू करना. |
| शासन और एडमिन | यह टूल को चलाने के लिए, तीन लेवल वाली सुरक्षा नीतियां लागू करता है और पुरानी मेमोरी को इकट्ठा करता है. |
| टेस्ट और आकलन | मास्टर वेरिफ़िकेशन सुइट, कई बार और कई सेशन वाले उदाहरणों को लागू करता है. साथ ही, टोकन की बचत के प्रतिशत का आकलन करता है और मेमोरी की सटीक जानकारी की पुष्टि करता है. |
6. AlloyDB AI स्कीमा और लेन-देन से जुड़ी ऑटो-एम्बेडिंग सेट अप करना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, एपिसोडिक और लॉन्ग-टर्म मेमोरी के लिए AlloyDB के डेटाबेस स्कीमा, इंडेक्स की रणनीतियां, और डेटाबेस-साइड ऑटो-एंबेडिंग को तय किया जाएगा.
- एपिसोडिक वेक्टर स्टोर (
episodic_memory_embeddings): इसमें चैट ट्रांसक्रिप्ट के ऐसे अनस्ट्रक्चर्ड चंक होते हैं जिन्हें HNSW वेक्टर इंडेक्स (vector_cosine_ops) के साथ इंडेक्स किया जाता है. - लॉन्ग-टर्म एंटिटी स्टोर (
agent_entities): इसमें स्ट्रक्चर्ड फ़ैक्ट, उपयोगकर्ता की पसंद, और प्रोजेक्ट के नियम सेव किए जाते हैं. साथ ही, स्कोप मेटाडेटा (global,project,session) भी सेव किया जाता है. इसमें अपने-आप जनरेट होने वाला PostgreSQL फ़ुल-टेक्स्ट सर्च कॉलम (summary_tsv) शामिल होता है, जिसे RUM के ज़रिए इंडेक्स किया जाता है. - डेटाबेस-साइड ऑटो-एम्बेडिंग (
ai.initialize_embeddings): यह सुविधा, सादे टेक्स्ट वाली नई या अपडेट की गई लाइनों को बैकग्राउंड में एजेंट प्लैटफ़ॉर्मtext-embedding-005के ज़रिएsummary_embeddingमें अपने-आप एम्बेड करती है.
AlloyDB Studio से कनेक्ट करना
- Google Cloud Console में, AlloyDB for Postgres पेज पर जाएं.
- अपने प्राइमरी इंस्टेंस पर क्लिक करें.
- बाईं ओर मौजूद नेविगेशन में, AlloyDB Studio पर क्लिक करें.
postgresडेटाबेस चुनेंIAM database authenticationसे पुष्टि करें
लागू करने का तरीका और सोर्स कोड
AlloyDB PostgreSQL डेटाबेस से कनेक्ट होने के बाद, नीचे दी गई DDL क्वेरी को एक्ज़ीक्यूट करें:
-- 1. Enable google_ml_integration extension
CREATE EXTENSION IF NOT EXISTS google_ml_integration CASCADE;
CREATE EXTENSION IF NOT EXISTS vector CASCADE;
CREATE EXTENSION IF NOT EXISTS rum CASCADE;
SET google_ml_integration.enable_preview_ai_functions = true;

-- 2. Create Episodic Memory Vector Store Tables
CREATE TABLE IF NOT EXISTS episodic_memory_collections (
    uuid UUID PRIMARY KEY,
    name VARCHAR,
    cmetadata JSONB
);

CREATE TABLE IF NOT EXISTS episodic_memory_embeddings (
    uuid UUID PRIMARY KEY,
    collection_id UUID REFERENCES episodic_memory_collections(uuid) ON DELETE CASCADE,
    embedding VECTOR(768),
    document VARCHAR,
    cmetadata JSONB,
    custom_id VARCHAR,
    created_at TIMESTAMPTZ DEFAULT NOW()
);

CREATE INDEX IF NOT EXISTS episodic_memory_embedding_idx
ON episodic_memory_embeddings
USING hnsw (embedding vector_cosine_ops)
WITH (m = 16, ef_construction = 64);

-- 3. Create Entity & Preference Table with Metadata Scope & Auto-Generated TSVector Column
CREATE TABLE IF NOT EXISTS agent_entities (
    entity_id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    user_id TEXT NOT NULL,
    entity_name TEXT NOT NULL,
    project_id TEXT DEFAULT 'global',
    session_id TEXT,
    scope TEXT NOT NULL DEFAULT 'project', -- 'global', 'project', 'session'
    summary TEXT NOT NULL,
    summary_embedding VECTOR(768),
    summary_tsv TSVECTOR GENERATED ALWAYS AS (
        to_tsvector('english', entity_name || ' ' || summary)
    ) STORED,
    updated_at TIMESTAMPTZ DEFAULT NOW(),
    UNIQUE (user_id, entity_name)
);

CREATE INDEX IF NOT EXISTS agent_entities_scope_idx
ON agent_entities (user_id, project_id, scope);

CREATE INDEX IF NOT EXISTS agent_entities_embedding_idx
ON agent_entities USING hnsw (summary_embedding vector_cosine_ops);

CREATE INDEX IF NOT EXISTS agent_entities_tsv_idx
ON agent_entities USING rum (summary_tsv rum_tsvector_ops);

-- 4. Create User Permissions Table for Tool Execution Controls
CREATE TABLE IF NOT EXISTS user_permissions (
    permission_id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    user_id TEXT NOT NULL,
    project_id TEXT NOT NULL DEFAULT 'global',
    tool_name TEXT NOT NULL,
    command_pattern TEXT NOT NULL,
    action TEXT NOT NULL CHECK (action IN ('ALLOW', 'BLOCK')),
    created_at TIMESTAMPTZ DEFAULT NOW(),
    updated_at TIMESTAMPTZ DEFAULT NOW()
);

CREATE INDEX IF NOT EXISTS idx_user_permissions_lookup
ON user_permissions (user_id, project_id, tool_name);
-- 5. Register Gemini 3.5 Flash Model Endpoint in AlloyDB
-- Replace PROJECT_ID with your Google Cloud project ID
CALL google_ml.create_model(
    model_id => 'gemini-3.5-flash',
    model_request_url => 'https://aiplatform.googleapis.com/v1/projects/PROJECT_ID/locations/global/publishers/google/models/gemini-3.5-flash:generateContent',
    model_qualified_name => 'gemini-3.5-flash',
    model_provider => 'google',
    model_type => 'llm',
    model_auth_type => 'alloydb_service_agent_iam'
);
लेन-देन से जुड़ी ऑटो-एम्बेडिंग की सुविधा शुरू करना और Gemini मॉडल रजिस्टर करना
इसके बाद, CALL स्टेटमेंट को अलग-अलग क्वेरी एक्ज़ीक्यूशन ब्लॉक में एक्ज़ीक्यूट करें, ताकि ऑटो-एम्बेडिंग की बैकग्राउंड प्रोसेस और Gemini 3.5 Flash मॉडल एंडपॉइंट रजिस्टर हो सके:
-- 6. Register Database-Side Transactional Auto-Embedding
CALL ai.initialize_embeddings(
    model_id => 'text-embedding-005',
    table_name => 'agent_entities',
    content_column => 'summary',
    embedding_column => 'summary_embedding',
    incremental_refresh_mode => 'transactional',
    batch_size => 10
);
7. AlloyDB और Valkey कनेक्शन क्लाइंट कॉन्फ़िगर करना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, AlloyDB for PostgreSQL (लॉन्ग-टर्म मेमोरी) और Memorystore for Valkey (शॉर्ट-टर्म कैश) दोनों के लिए सुरक्षित नेटवर्क कनेक्शन बनाए जाएंगे.
- AlloyDB IAM Authentication: यह
gcloud auth application-default print-access-tokenका इस्तेमाल करके, बिना पासवर्ड वाले, एसएसएल-एन्क्रिप्ट (सुरक्षित) किए गए डेटाबेस कनेक्शन (sslmode="require") के लिए, कम समय के लिए मान्य OAuth2 टोकन को वापस पाता है. - Valkey Network Resilience: यह
redis.Redisको 5.0 सेकंड के सॉकेट टाइमआउट (socket_timeout=5.0) के साथ कॉन्फ़िगर करता है, ताकि सिंगल-नोड या क्लस्टर किए गए Valkey इंस्टेंस में वीपीसी नेटवर्क ऑपरेशनों को सुरक्षित तरीके से मैनेज किया जा सके.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में db_clients.py स्क्रिप्ट बनाएं:
import os
import subprocess
import psycopg2
import redis

# Initialize database & Valkey connection clients from environment variables
DB_HOST = os.getenv("DB_HOST", "127.0.0.1")
DB_PORT = os.getenv("DB_PORT", "5432")
DB_NAME = os.getenv("DB_NAME", "postgres")
DB_USER = os.getenv("DB_USER")

VALKEY_HOST = os.getenv("VALKEY_HOST", "127.0.0.1")
VALKEY_PORT = int(os.getenv("VALKEY_PORT", "6379"))

def get_db_connection():
    # Fetch Application Default Credentials (ADC) token for IAM Database Authentication & enable SSL encryption
    access_token = subprocess.check_output(
        ["gcloud", "auth", "application-default", "print-access-token"], text=True
    ).strip()
    return psycopg2.connect(
        host=DB_HOST,
        port=DB_PORT,
        dbname=DB_NAME,
        user=DB_USER,
        password=access_token,
        sslmode="require"
    )

def get_valkey_client():
    return redis.Redis(
        host=VALKEY_HOST,
        port=VALKEY_PORT,
        db=0,
        socket_timeout=5.0,
        socket_connect_timeout=5.0
    )

if __name__ == "__main__":
    print(f"Connecting to AlloyDB via IAM Auth ({DB_USER}) at {DB_HOST}:{DB_PORT} and Valkey at {VALKEY_HOST}:{VALKEY_PORT}...")
    print("Database and Valkey connection client modules loaded successfully.")
8. Memorystore for Valkey में, शॉर्ट-टर्म सेशन की स्थिति को कैश मेमोरी में सेव करना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, Memorystore for Valkey में एक मिलीसेकंड से भी कम समय में काम करने वाली, कम समय के लिए कॉन्टेक्स्ट को सेव करने वाली कैश मेमोरी बनाई जाएगी. इसमें, Summarize-Before-Trim पैटर्न अपने-आप लागू होगा.
- Valkey स्लाइडिंग विंडो: बातचीत के ऐक्टिव टर्न,
session:{session_id}:turnsकुंजी में JSON स्ट्रिंग के तौर पर सेव किए जाते हैं. - Redis हैश टैग (
{session_id}):session:{session_id}:turnsऔरsession:{session_id}:summaryके लिए, Redis क्लस्टर हैश टैग ({...}) का इस्तेमाल किया जाता है. इससे दोनों कुंजियों को एक ही हैश स्लॉट में रखा जाता है, ताकि यह पक्का किया जा सके कि सिंगल-नोड या क्लस्टर किए गए Valkey डिप्लॉयमेंट में, एटॉमिक एक्ज़ीक्यूशन हो. - Summarize-Before-Trim: जब बातचीत की संख्या
trigger_limitसे ज़्यादा हो जाती है, तो Gemini Flash, पुरानी बातचीत को छोटा करने से पहले, उसे रोलिंग टेक्स्ट समरी (session:{session_id}:summary) में बदल देता है. इसके बाद, बातचीत के इतिहास कोwindow_sizeतक छोटा कर दिया जाता है.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में valkey_buffer.py स्क्रिप्ट बनाएं:
import json
import logging
import time
from typing import Any, Dict, List
import redis

logger = logging.getLogger(__name__)

IN_MEMORY_VALKEY_FALLBACK: Dict[str, Any] = {}
VALKEY_COMPACTION_TOKENS = 0

def get_valkey_compaction_tokens() -> int:
    return VALKEY_COMPACTION_TOKENS

def append_session_turn_with_rolling_summary(
    valkey_client: redis.Redis,
    llm_client: Any,
    session_id: str,
    user_msg: str,
    ai_msg: str,
    trigger_limit: int = 10,
    window_size: int = 4
) -> None:
    """Appends turn to Valkey. Before trimming old turns, summarizes them into a rolling summary."""
    global VALKEY_COMPACTION_TOKENS
    # Use Redis Hash Tags {session_id} so both keys hash to the same cluster slot
    turns_key = "session:{" + session_id + "}:turns"
    summary_key = "session:{" + session_id + "}:summary"

    try:
        # 1. Append new turn messages
        valkey_client.rpush(turns_key, json.dumps({"role": "user", "content": user_msg}))
        valkey_client.rpush(turns_key, json.dumps({"role": "assistant", "content": ai_msg}))

        raw_turns = valkey_client.lrange(turns_key, 0, -1)

        # 2. Check if total turns exceed summary trigger threshold
        msg_trigger_count = trigger_limit * 2
        msg_window_count = window_size * 2

        if len(raw_turns) > msg_trigger_count:
            turns_to_prune = raw_turns[:-msg_window_count]
            existing_summary = valkey_client.get(summary_key)
            existing_summary_text = (
                existing_summary.decode('utf-8') if isinstance(existing_summary, bytes) else (existing_summary or "")
            )

            pruned_text = "\n".join([
                f"{json.loads(t)['role']}: {json.loads(t)['content']}" for t in turns_to_prune
            ])

            prompt = f"""Update the existing rolling conversation summary with the old turns about to be trimmed.
Retain key constraints, user choices, technical decisions, and ongoing goals.

Existing Summary:
{existing_summary_text if existing_summary_text else 'No prior summary.'}

Old turns about to be trimmed:
{pruned_text}

Updated Rolling Summary:"""

            VALKEY_COMPACTION_TOKENS += max(1, len(prompt) // 4)

            updated_summary_text = llm_client.models.generate_content(
                model="gemini-3.5-flash", contents=prompt
            ).text.strip()
            # Execute commands directly to support all Redis/Valkey cluster topologies
            valkey_client.set(summary_key, updated_summary_text)
            valkey_client.ltrim(turns_key, -msg_window_count, -1)
            logger.info("Updated rolling summary and trimmed Valkey buffer for session %s", session_id)

    except (redis.exceptions.RedisError, Exception) as e:
        logger.warning("Valkey operation warning (%s). Falling back to in-memory short-term buffer.", e)
        if turns_key not in IN_MEMORY_VALKEY_FALLBACK:
            IN_MEMORY_VALKEY_FALLBACK[turns_key] = []
        IN_MEMORY_VALKEY_FALLBACK[turns_key].append({"role": "user", "content": user_msg})
        IN_MEMORY_VALKEY_FALLBACK[turns_key].append({"role": "assistant", "content": ai_msg})

        # In-memory summarize-before-trim fallback logic
        msg_trigger_count = trigger_limit * 2
        msg_window_count = window_size * 2
        raw_fallback_turns = IN_MEMORY_VALKEY_FALLBACK[turns_key]

        if len(raw_fallback_turns) > msg_trigger_count:
            turns_to_prune = raw_fallback_turns[:-msg_window_count]
            existing_summary_text = IN_MEMORY_VALKEY_FALLBACK.get(summary_key, "")
            pruned_text = "\n".join([f"{t['role']}: {t['content']}" for t in turns_to_prune])

            prompt = f"""Update the existing rolling conversation summary with the old turns about to be trimmed.
Retain key constraints, user choices, technical decisions, and ongoing goals.

Existing Summary:
{existing_summary_text if existing_summary_text else 'No prior summary.'}

Old turns about to be trimmed:
{pruned_text}

Updated Rolling Summary:"""

            VALKEY_COMPACTION_TOKENS += max(1, len(prompt) // 4)

            for attempt in range(4):
                try:
                    updated_summary_text = llm_client.models.generate_content(
                        model="gemini-3.5-flash", contents=prompt
                    ).text.strip()
                    break
                except Exception as e:
                    if ("429" in str(e) or "RESOURCE_EXHAUSTED" in str(e)) and attempt < 3:
                        time.sleep(3 * (2 ** attempt))
                    else:
                        raise

            IN_MEMORY_VALKEY_FALLBACK[summary_key] = updated_summary_text
            IN_MEMORY_VALKEY_FALLBACK[turns_key] = raw_fallback_turns[-msg_window_count:]

def get_session_context_buffer(
    valkey_client: redis.Redis,
    session_id: str
) -> Dict[str, Any]:
    """Retrieves rolling summary + sliding window history from Valkey to build prompt context."""
    turns_key = "session:{" + session_id + "}:turns"
    summary_key = "session:{" + session_id + "}:summary"

    try:
        summary = valkey_client.get(summary_key)
        summary_text = summary.decode('utf-8') if isinstance(summary, bytes) else (summary or "")

        raw_turns = valkey_client.lrange(turns_key, 0, -1)
        recent_turns = [json.loads(t) for t in raw_turns]

        return {
            "rolling_summary": summary_text,
            "recent_turns": recent_turns
        }
    except (redis.exceptions.RedisError, Exception) as e:
        logger.warning("Valkey read error (%s). Using in-memory short-term fallback buffer.", e)
        summary_text = IN_MEMORY_VALKEY_FALLBACK.get(summary_key, "")
        recent_turns = IN_MEMORY_VALKEY_FALLBACK.get(turns_key, [])
        return {"rolling_summary": summary_text, "recent_turns": recent_turns}
9. Extract Entities Off-Thread (Background Memory Worker)
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, आपको ऑफ़-थ्रेड राइट-पाथ बैकग्राउंड एक्सट्रैक्शन वर्कर (AsyncMemoryWorker) बनाना होगा. यह वर्कर, इंटरैक्टिव एआई से मिले जवाबों की स्पीड कम किए बिना, लंबे समय तक मौजूद रहने वाली इकाइयों के बारे में जानकारी निकालता है.
- नॉन-ब्लॉकिंग क्यू वर्कर: यह एक डेमॉन थ्रेड (
queue.Queue) लॉन्च करता है, ताकि डेवलपर चैट तुरंत जवाब दे सके. इसके लिए, एलएलएम एक्सट्रैक्शन या डेटाबेस राइट का इंतज़ार नहीं करना पड़ता. - थ्रेड से बाहर की इकाई से तथ्य निकालना: यह सुविधा, बैकग्राउंड में Gemini Flash (
model="gemini-3.5-flash",response_mime_type="application/json") को कॉल करती है, ताकि स्ट्रक्चर्ड इकाइयों को पार्स किया जा सके. इससे, उपयोगकर्ता के साथ बातचीत में कोई रुकावट नहीं आती. - टेंपोरल कोरेफ़रेंस रिज़ॉल्यूशन (
build_temporal_rules_prompt): यह ऐसे नियमों को लागू करता है जो समय के हिसाब से तय किए गए एक्सप्रेशन (जैसे, "अभी", "पिछले सेशन") को साफ़ तौर पर बताए गए सेशन आईडी (जैसे,session_id) में बदलते हैं. - स्कीमा अपसर्ट: यह Gemini Flash को, इकाइयों (
entity_name,project_id,scope,summary) की JSON ऐरे दिखाने के लिए प्रॉम्प्ट करता है. साथ ही, पैरामीटर वाले PostgreSQLON CONFLICT DO UPDATEस्टेटमेंट के ज़रिएagent_entitiesमें सादा टेक्स्ट लिखता है.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में async_worker.py स्क्रिप्ट बनाएं:
import json
import logging
import queue
import threading
import time
from typing import Dict, Any, Optional
import psycopg2

logger = logging.getLogger(__name__)

def build_temporal_rules_prompt(active_session_id: str, prev_session_id: Optional[str] = None) -> str:
    """REUSABLE PROMPT HELPER: Defines temporal coreference rules for both Read and Write paths."""
    return f"""TEMPORAL COREFERENCE RULES:
1. Do not use relative temporal words like 'currently', 'now', 'this session', 'previous session', or 'last session'.
2. Replace any relative temporal reference with explicit session identifiers:
   - Active Session: '{active_session_id}'
   - Previous Session: '{prev_session_id if prev_session_id else active_session_id}'
   (e.g., write 'User prefers Python in session {active_session_id}' instead of 'User currently prefers Python')."""

class AsyncMemoryWorker:
    """Off-thread daemon queue worker performing background entity extraction and upserts into AlloyDB."""
    def __init__(self, conn_factory, llm_client):
        self.conn_factory = conn_factory
        self.llm_client = llm_client
        self.work_queue = queue.Queue()
        self.total_extraction_tokens = 0
        self.worker_thread = threading.Thread(target=self._run_worker, daemon=True)
        self.worker_thread.start()

    def enqueue_extraction(
        self, user_id: str, session_id: str, user_msg: str, ai_msg: str, prev_session_id: Optional[str] = None
    ):
        self.work_queue.put((user_id, session_id, user_msg, ai_msg, prev_session_id))

    def _run_worker(self):
        while True:
            item = self.work_queue.get()
            if item is None:
                break
            user_id, session_id, user_msg, ai_msg, prev_session_id = item
            try:
                self._extract_and_upsert(user_id, session_id, user_msg, ai_msg, prev_session_id)
            except Exception as e:
                logger.error("Background extraction failed: %s", e)
            finally:
                self.work_queue.task_done()

    def _extract_and_upsert(
        self, user_id: str, session_id: str, user_msg: str, ai_msg: str, prev_session_id: Optional[str] = None
    ):
        temporal_rules = build_temporal_rules_prompt(session_id, prev_session_id)
        json_fmt = '[{"entity_name": "...", "project_id": "...", "scope": "global|project|session", "summary": "..."}]'

        prompt = f"""Extract key preferences and named entities from this exchange.
Format output strictly as a JSON array of objects with structure: {json_fmt}.

{temporal_rules}

Rules for Scope:
- 'global': Universal developer preferences.
- 'project': Architecture, database choices, timeouts, and rules for a specific project.
- 'session': Ephemeral task state tied strictly to a single session.

User: {user_msg}
AI: {ai_msg}

Output (JSON array only):"""

        self.total_extraction_tokens += max(1, len(prompt) // 4)

        for attempt in range(4):
            try:
                response = self.llm_client.models.generate_content(
                    model="gemini-3.5-flash",
                    contents=prompt,
                    config={"response_mime_type": "application/json"}
                )
                break
            except Exception as e:
                if ("429" in str(e) or "RESOURCE_EXHAUSTED" in str(e)) and attempt < 3:
                    time.sleep(3 * (2 ** attempt))
                else:
                    raise
        content = str(response.text).strip()
        if not content:
            return

        extracted_list = json.loads(content)
        if not isinstance(extracted_list, list):
            return

        upsert_sql = """
            INSERT INTO agent_entities (user_id, entity_name, project_id, session_id, scope, summary, updated_at)
            VALUES (%s, %s, %s, %s, %s, %s, NOW())
            ON CONFLICT (user_id, entity_name)
            DO UPDATE SET
                project_id = EXCLUDED.project_id,
                session_id = EXCLUDED.session_id,
                scope = EXCLUDED.scope,
                summary = EXCLUDED.summary,
                updated_at = NOW();
        """

        conn = self.conn_factory()
        try:
            with conn:
                with conn.cursor() as cur:
                    for item in extracted_list:
                        e_name = item.get("entity_name", "General_Fact")
                        p_id = item.get("project_id", "global")
                        s_scope = item.get("scope", "project")
                        summary = item.get("summary", "")
                        if e_name and summary:
                            cur.execute(upsert_sql, (user_id, e_name, p_id, session_id, s_scope, summary))
            logger.info("Saved %d entities for user %s", len(extracted_list), user_id)
        finally:
            conn.close()
10. नेटिव हाइब्रिड सर्च की मदद से, लंबे समय तक सेव रहने वाली मेमोरी से क्वेरी करना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, रीड-पाथ सब-क्वेरी डीकंपोज़िशन, टाइमपोरल क्वेरी रीराइटिंग, मेटाडेटा स्कोप आइसोलेशन लागू किया जाएगा. साथ ही, AlloyDB की नेटिव हाइब्रिड सर्च (ai.hybrid_search) का इस्तेमाल किया जाएगा.
- डेटाबेस में सब-क्वेरी डीकंपोज़िशन (
rewrite_and_decompose_query): यह सुविधा, AlloyDB AI के बिल्ट-इन फ़ंक्शनai.generate()का इस्तेमाल करती है. यह फ़ंक्शन, PostgreSQL में सीधे तौर पर काम करता है. इसकी मदद से, एक से ज़्यादा पहलुओं वाले सवालों को एक पहलू वाली सब-क्वेरी में तोड़ा जा सकता है. साथ ही, सेशन आईडी को सामान्य बनाया जा सकता है. इससे, एक से ज़्यादा विषयों वाली क्वेरी की वजह से, वेक्टर सर्च की सटीक जानकारी कम नहीं होती. - इंडेक्स-लेवल पर स्कोप फ़िल्टर करना: यह डेटाबेस-साइड SQL फ़िल्टर (
filter_condition => "user_id = '%s' AND (project_id = '%s' OR scope = 'global')") बनाता है, ताकि हर उपयोगकर्ता और प्रोजेक्ट के हिसाब से यादें अलग की जा सकें. साथ ही, इसमें डेवलपर की ग्लोबल सेटिंग भी शामिल होती हैं. - AlloyDB में नेटिव हाइब्रिड सर्च (
ai.hybrid_search): यह सुविधा, AlloyDB में वेक्टर कोसाइन सिमिलैरिटी (public.<=>) और फ़ुल-टेक्स्ट सर्च (rum) को एक साथ इस्तेमाल करती है. इसके लिए, Reciprocal Rank Fusion (RRF) का इस्तेमाल किया जाता है, ताकि सटीक, ज़्यादा से ज़्यादा और काम के नतीजे मिल सकें.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में hybrid_retriever.py स्क्रिप्ट बनाएं:
import os
import json
import logging
from typing import Any, Dict, List, Optional
import psycopg2
from psycopg2.extras import RealDictCursor
from async_worker import build_temporal_rules_prompt

logger = logging.getLogger(__name__)

def rewrite_and_decompose_query(
    conn: Any,
    llm_client: Any,
    text: str,
    active_session_id: str,
    prev_session_id: Optional[str] = None
) -> List[str]:
    """Read-Path LLM Query Normalizer & Sub-Query Decomposer using AlloyDB AI ai.generate() directly in PostgreSQL."""
    temporal_rules = build_temporal_rules_prompt(active_session_id, prev_session_id)

    prompt = f"""You are a query normalization and decomposition tool for an AI agent's memory retrieval system.

Tasks:
1. Normalize any relative temporal phrases in the user query into explicit session identifiers.
{temporal_rules}

2. Decompose compound user queries asking about multiple distinct topics into up to 4 concise, single-topic search queries. Ensure all distinct questions (both general developer preferences and project-specific architecture/rules) are preserved as separate sub-queries.
3. Return ONLY a valid JSON array of strings containing the sub-queries.

Example Output Format:
["general developer coding preferences", "CloudRetail backend stack in session sess_2026_01", "CloudRetail timeout rules in session sess_2026_01"]

Text to Process: {text}
JSON Output:"""

    try:
        with conn.cursor() as cur:
            cur.execute("SET google_ml_integration.enable_preview_ai_functions = true;")
            cur.execute("SELECT ai.generate(prompt => %s::text, model_id => 'gemini-3.5-flash'::varchar(100));", (prompt,))
            row = cur.fetchone()
            if row and row[0]:
                res_text = str(row[0]).strip()
                clean_text = res_text
                if clean_text.startswith("```"):
                    clean_text = clean_text.removeprefix("```json").removeprefix("```").removesuffix("```").strip()
                parsed = json.loads(clean_text)
                if isinstance(parsed, list) and len(parsed) > 0:
                    return [str(q).strip() for q in parsed]
        return [text]
    except Exception as e:
        logger.error("Error in in-database ai.generate sub-query decomposition: %s", e)
        return [text]

def rewrite_temporal_query(
    conn: Any,
    llm_client: Any,
    text: str,
    active_session_id: str,
    prev_session_id: Optional[str] = None
) -> str:
    """Backward-compatible wrapper returning first decomposed query string."""
    queries = rewrite_and_decompose_query(conn, llm_client, text, active_session_id, prev_session_id)
    return queries[0] if queries else text

def retrieve_hybrid_entities(
    conn,
    llm_client: Any,
    user_id: str,
    active_session_id: str,
    query_text: str,
    query_embedding: Optional[List[float]] = None,
    prev_session_id: Optional[str] = None,
    project_id: Optional[str] = None,
    k: int = 20
) -> Dict[str, Any]:
    """Queries long-term entities using Sub-Query Decomposition, metadata scope filtering, and parameterized AlloyDB hybrid search."""
    sub_queries = rewrite_and_decompose_query(
        conn=conn, llm_client=llm_client, text=query_text, active_session_id=active_session_id, prev_session_id=prev_session_id
    )
    all_search_queries = list(dict.fromkeys(sub_queries + [query_text]))

    retrieved_entities: Dict[str, Any] = {}

    filter_cond = f"user_id = '{user_id}' AND (project_id = '{project_id}' OR scope = 'global')" if project_id else f"user_id = '{user_id}'"

    query_sql = """
        SELECT e.entity_name, e.summary, e.project_id, e.scope, e.updated_at
        FROM ai.hybrid_search(
          search_inputs => %s::JSONB[],
          include_json_output => false
        ) h
        JOIN agent_entities e ON e.entity_name = h.id
        WHERE e.user_id = %s
        LIMIT %s;
    """

    from google import genai
    embed_client = genai.Client(
        vertexai=True,
        project=os.getenv("PROJECT_ID"),
        location=os.getenv("REGION", "us-east1")
    )

    for sq in all_search_queries:
        try:
            emb_resp = embed_client.models.embed_content(model="text-embedding-005", contents=sq)
            sq_embedding = emb_resp.embeddings[0].values
            vector_literal = f"'{sq_embedding}'::vector"
        except Exception as e:
            logger.error(f"Failed to generate embedding for sub-query: {sq}. Error: {e}")
            # Fallback to zero vector to prevent Postgres from crashing
            sq_embedding = [0.0] * 768
            vector_literal = f"'{sq_embedding}'::vector"

        search_inputs = [
            json.dumps({
                "data_type": "vector",
                "weight": 0.4,
                "table_name": "agent_entities",
                "key_column": "entity_name",
                "vec_column": "summary_embedding",
                "distance_operator": "public.<=>",
                "limit": 20,
                "query_vector": vector_literal,
                "filter_condition": filter_cond
            }),
            json.dumps({
                "data_type": "text",
                "weight": 0.6,
                "table_name": "agent_entities",
                "key_column": "entity_name",
                "text_column": "summary_tsv",
                "limit": 20,
                "ranking_function": "ts_rank",
                "query_text_input": sq,
                "filter_condition": filter_cond
            })
        ]

        with conn.cursor(cursor_factory=RealDictCursor) as cur:
            try:
                cur.execute("SET google_ml_integration.enable_preview_ai_functions = true;")
                cur.execute(query_sql, (search_inputs, user_id, k))
                rows = cur.fetchall()

                for row in rows:
                    name = row["entity_name"]
                    if name not in retrieved_entities:
                        retrieved_entities[name] = {
                            "summary": row["summary"],
                            "project_id": row["project_id"],
                            "scope": row["scope"],
                            "updated_at": row["updated_at"].isoformat() if row["updated_at"] else None
                        }
            except Exception as e:
                logger.error("Error executing hybrid search for sub-query '%s': %s", sq, e)

    return retrieved_entities
11. एजेंट की मेमोरी के एंड-टू-एंड लूप को बनाना और चलाना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, आपको मुख्य एजेंट ऑर्केस्ट्रेशन फ़ंक्शन (run_agent_turn) बनाना होगा. इसमें कम समय के लिए कैश मेमोरी से जानकारी पाना, लंबे समय तक सेव की गई मेमोरी में खोज करना, प्रॉम्प्ट असेंबल करना, एलएलएम जनरेशन, और बैकग्राउंड मेमोरी एक्सट्रैक्शन को शामिल किया जाता है.
- कम समय का कॉन्टेक्स्ट: इससे, Valkey के चालू डायलॉग टर्न और रोलिंग समरी (
get_session_context_buffer) फ़ेच की जाती है. - लॉन्ग-टर्म सर्च: यह सुविधा,
retrieve_hybrid_entitiesके ज़रिए AlloyDB से क्वेरी करती है. इसके लिए, ऐक्टिव प्रोजेक्ट आईडी और ग्लोबल स्कोप के हिसाब से फ़िल्टर की गई सब-क्वेरी का इस्तेमाल किया जाता है. - सिस्टम प्रॉम्प्ट फ़ॉर्मैट करना: यह सुविधा,
build_agent_promptको एक साथ जोड़ती है. इसमें लंबे समय तक मौजूद रहने वाली इकाइयां, कम शब्दों में जानकारी, हाल ही का डायलॉग, और उपयोगकर्ता के प्रॉम्प्ट को टोकन-इफ़िशिएंट सिस्टम प्रॉम्प्ट में शामिल किया जाता है. - Async Queue Enqueue: यह Valkey में टर्न इन को कैश मेमोरी में सेव करता है और बैकग्राउंड एक्सट्रैक्शन को
AsyncMemoryWorkerमें शामिल करता है. इससे रिटर्न पेलोड ब्लॉक नहीं होता.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में agent_orchestrator.py स्क्रिप्ट बनाएं:
import logging
import time
from typing import Any, Dict, Optional, Tuple
import redis
from valkey_buffer import get_session_context_buffer, append_session_turn_with_rolling_summary
from hybrid_retriever import rewrite_temporal_query, retrieve_hybrid_entities
from async_worker import AsyncMemoryWorker

logger = logging.getLogger(__name__)

def build_agent_prompt(
    rolling_summary: str,
    recent_turns: list[Dict[str, Any]],
    retrieved_entities: Dict[str, Any],
    user_query: str
) -> str:
    """Assembles structured system prompt with long-term memory & short-term context."""
    entity_lines = [
        f"- {name}: {info['summary']}" for name, info in retrieved_entities.items()
    ]
    entity_context = "\n".join(entity_lines) if entity_lines else "No relevant entity facts."
    history_lines = [f"{t['role']}: {t['content']}" for t in recent_turns]
    history_str = "\n".join(history_lines)

    return f"""You are an intelligent, context-aware AI assistant.

[LONG-TERM PREFERENCES & ENTITIES]
{entity_context}

[SHORT-TERM ROLLING SUMMARY]
{rolling_summary if rolling_summary else 'No prior summary.'}

[RECENT DIALOGUE]
{history_str}

User: {user_query}
AI:"""

def run_agent_turn(
    db_conn,
    valkey_client: redis.Redis,
    async_worker: AsyncMemoryWorker,
    genai_client: Any,
    user_id: str,
    session_id: str,
    user_query: str,
    prev_session_id: Optional[str] = None,
    project_id: Optional[str] = None,
    trigger_limit: int = 10,
    window_size: int = 4
) -> Tuple[str, str, float]:
    """Executes a complete 2-tier agent memory turn loop, returning (response_text, system_prompt, latency_seconds)."""
    import time
    start_time = time.time()

    # 1. Fetch short-term rolling summary + recent turns from Valkey
    buffer_data = get_session_context_buffer(valkey_client, session_id)
    rolling_summary = buffer_data["rolling_summary"]
    recent_turns = buffer_data["recent_turns"]

    # 2. READ PATH: Rewrite incoming query via LLM coreference normalizer
    try:
        normalized_query = rewrite_temporal_query(
            db_conn, genai_client, user_query, active_session_id=session_id, prev_session_id=prev_session_id
        )
        emb_resp = genai_client.models.embed_content(model="text-embedding-005", contents=normalized_query)
        query_embedding = emb_resp.embeddings[0].values
    except Exception:
        query_embedding = None

    # Retrieve relevant long-term entities from AlloyDB via hybrid search
    retrieved_entities = retrieve_hybrid_entities(
        conn=db_conn,
        llm_client=genai_client,
        user_id=user_id,
        active_session_id=session_id,
        query_text=user_query,
        query_embedding=query_embedding,
        prev_session_id=prev_session_id,
        project_id=project_id,
        k=20
    )

    # 3. Assemble system prompt
    system_prompt = build_agent_prompt(
        rolling_summary, recent_turns, retrieved_entities, user_query
    )


    # 4. LLM inference for developer response with exponential backoff on 429 rate limit
    for attempt in range(4):
        try:
            response = genai_client.models.generate_content(
                model="gemini-3.5-flash", contents=system_prompt
            )
            break
        except Exception as e:
            if ("429" in str(e) or "RESOURCE_EXHAUSTED" in str(e)) and attempt < 3:
                time.sleep(3 * (2 ** attempt))
            else:
                raise
    ai_response = str(response.text)

    # 5. Cache turn in short-term Valkey buffer (with Summarize-Before-Trim check)
    append_session_turn_with_rolling_summary(
        valkey_client=valkey_client,
        llm_client=genai_client,
        session_id=session_id,
        user_msg=user_query,
        ai_msg=ai_response,
        trigger_limit=trigger_limit,
        window_size=window_size
    )

    # 6. WRITE PATH: Enqueue off-thread background entity extraction (single LLM call)
    async_worker.enqueue_extraction(user_id, session_id, user_query, ai_response, prev_session_id)

    latency = time.time() - start_time
    return ai_response, system_prompt, latency
12. एंटरप्राइज़ के लिए अनुमतियों को कंट्रोल करने की सुविधा और मेमोरी कंपैक्शन को लागू करना
मकसद और आर्किटेक्चर की खास जानकारी
इस मॉड्यूल में, आपको टूल को लागू करने और डेटाबेस मेमोरी कंपैक्शन (AgentMemoryEngine) के लिए, एंटरप्राइज़ सिक्योरिटी कंट्रोल बनाने के बारे में बताया जाएगा.
- अनुमति की जांच करने की तीन लेयर (
evaluate_tool_permission):- टियर 1 (एक बार इस्तेमाल की जा सकने वाली Valkey Grant): यह 300 सेकंड के टीटीएल के साथ, एक बार इस्तेमाल की जा सकने वाली Grant की कुंजियों (
one_time_perm:{session_id}:{cmd_hash}) की जांच करता है. यह मौजूद होने पर, कुंजी को तुरंत मिटा देता है औरALLOWदिखाता है. - टियर 2 और 3 (PostgreSQL के नीति से जुड़े नियम): क्वेरी
user_permissions, सबसे पहले प्रोजेक्ट के स्कोप वाले नियमों (project_id) से मैच करती हैं. इसके बाद, ग्लोबल नियमों ('global') से मैच करती हैं. - फ़ॉलबैक: अगर कोई मिलती-जुलती नीति मौजूद नहीं है, तो
PROMPT_USERदिखाता है.
- टियर 1 (एक बार इस्तेमाल की जा सकने वाली Valkey Grant): यह 300 सेकंड के टीटीएल के साथ, एक बार इस्तेमाल की जा सकने वाली Grant की कुंजियों (
- मेमोरी कंपैक्शन (
compact_old_memories): यह सुविधा,retention_daysसे ज़्यादा पुरानेepisodic_memory_embeddingsमें मौजूद, इतिहास से जुड़े रॉ वेक्टर इवेंट को एक साथ इकट्ठा करती है. इसके बाद, 50 लाइनों वाली एसक्यूएल सीटीई क्वेरी का इस्तेमाल करके,agent_entitiesमें एक ही जगह पर उनकी खास जानकारी दिखाती है.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में enterprise_engine.py स्क्रिप्ट बनाएं:
import hashlib
import logging
import re
from typing import Any, Dict, Tuple
import psycopg2
import redis

logger = logging.getLogger(__name__)

class AgentMemoryEngine:
    """Framework-agnostic Enterprise Memory Engine for tool execution permissions & safe compaction."""

    def __init__(self, valkey_client: redis.Redis, db_conn: Any):
        self.valkey_client = valkey_client
        self.db_conn = db_conn

    def evaluate_tool_permission(
        self,
        user_id: str,
        project_id: str,
        session_id: str,
        tool_name: str,
        tool_args: Dict[str, Any]
    ) -> Tuple[str, str]:
        """Evaluates 3-tier execution permissions: Allow-Once (Valkey), Project (AlloyDB), Global (AlloyDB)."""
        command_str = str(tool_args.get("CommandLine", "") or tool_args)

        # Tier 1: Allow-Once (Single-Use Valkey Check with 300s TTL)
        cmd_hash = hashlib.sha256(command_str.encode("utf-8")).hexdigest()[:16]
        valkey_key = f"one_time_perm:{session_id}:{cmd_hash}"

        if self.valkey_client.get(valkey_key):
            self.valkey_client.delete(valkey_key)  # Consume key immediately
            return ("ALLOW", "Single-use 'Allow Once' grant consumed.")

        # Tier 2 & Tier 3: Query AlloyDB user_permissions table
        query_sql = """
            SELECT command_pattern, action, project_id
            FROM user_permissions
            WHERE user_id = %s AND tool_name = %s AND project_id IN (%s, 'global')
            ORDER BY CASE WHEN project_id = %s THEN 1 ELSE 2 END;
        """

        with self.db_conn.cursor() as cur:
            cur.execute(query_sql, (user_id, tool_name, project_id, project_id))
            rules = cur.fetchall()
            for pattern, action, scope in rules:
                if re.search(pattern, command_str, flags=re.IGNORECASE):
                    return (action, f"Matched {scope}-scoped rule: {pattern}")

        # Fallback: Prompt Human User
        return ("PROMPT_USER", "No matching permission rule found.")

    def compact_old_memories(self, user_id: str, retention_days: int = 30) -> None:
        """Consolidates old episodic facts from episodic_memory_embeddings into a summary with a 50-row cap."""
        prompt_prefix = (
            "Summarize the following historical events into a high-density long-term memory paragraph. "
            "Retain key constraints, tool choices, and project rules:\n"
        )

        # Capped CTE prevents string_agg from exceeding model context window limits
        compaction_sql = """
            WITH old_events AS (
                SELECT document AS content
                FROM episodic_memory_embeddings
                WHERE cmetadata->>'user_id' = %s
                  AND created_at < NOW() - (INTERVAL '1 day' * %s)
                ORDER BY created_at ASC
                LIMIT 50
            ),
            consolidated AS (
                SELECT ai.generate(%s || string_agg(content, E'\n')) AS summary_text
                FROM old_events
            )
            INSERT INTO agent_entities (user_id, entity_name, summary, updated_at)
            SELECT %s, 'longterm_session_summary', summary_text, NOW()
            FROM consolidated
            WHERE summary_text IS NOT NULL
            ON CONFLICT (user_id, entity_name)
            DO UPDATE SET summary = EXCLUDED.summary, updated_at = NOW();
        """

        prune_sql = """
            DELETE FROM episodic_memory_embeddings
            WHERE uuid IN (
                SELECT uuid FROM episodic_memory_embeddings
                WHERE cmetadata->>'user_id' = %s
                  AND created_at < NOW() - (INTERVAL '1 day' * %s)
                ORDER BY created_at ASC
                LIMIT 50
            );
        """

        try:
            with self.db_conn:
                with self.db_conn.cursor() as cur:
                    cur.execute("SET google_ml_integration.enable_preview_ai_functions = true;")
                    cur.execute(compaction_sql, (user_id, retention_days, prompt_prefix, user_id))
                    cur.execute(prune_sql, (user_id, retention_days))
            logger.info("Successfully compacted old memories for user %s", user_id)
        except Exception as e:
            logger.error("Error during memory compaction: %s", e)
13. एंड-टू-एंड मल्टी-टर्न मेमोरी की पुष्टि करना
मकसद और आर्किटेक्चर की खास जानकारी
इस आखिरी मॉड्यूल में, आपको मास्टर एंड-टू-एंड पुष्टि करने वाली स्क्रिप्ट (test_memory_system.py) बनानी होगी और उसे लागू करना होगा. इससे, दो टियर वाले पूरे मेमोरी आर्किटेक्चर की पुष्टि की जा सकेगी.
- कई बार बातचीत करने और कई सेशन में बातचीत करने की सुविधा:
- सेशन 1 (टर्न 1): इसमें डेवलपर की सामान्य प्राथमिकताएं तय की जाती हैं (
scope='global': डार्क मोड यूज़र इंटरफ़ेस (यूआई), Python 3.11, PostgreSQL). - पहला सेशन (दूसरा टर्न): इसमें प्रोजेक्ट के हिसाब से आर्किटेक्चर तय किया जाता है (
project_id='CloudRetail': FastAPI, AlloyDB, Valkey, 30 सेकंड का टाइमआउट, us-east1). - पहला सेशन (तीसरा और चौथा मोड़): इसमें तकनीकी बातचीत की आवाज़ जनरेट होती है और
trigger_limit=3से ज़्यादा हो जाती है. इससे Valkey Summarize-Before-Trim की सुविधा चालू हो जाती है और रोलिंग सारांश को छोटा कर दिया जाता है. - दूसरा सेशन (पाँचवाँ टर्न - बिलकुल नया सेशन आईडी): यह एजेंट से अलग-अलग सेशन में सवाल पूछता है, ताकि यह पुष्टि की जा सके कि उसे ग्लोबल सेटिंग और प्रोजेक्ट के नियमों के बारे में जानकारी है या नहीं.
- सेशन 1 (टर्न 1): इसमें डेवलपर की सामान्य प्राथमिकताएं तय की जाती हैं (
- डाइनैमिक तौर पर असरदार होने और सटीक होने की पुष्टि करना: इससे प्रॉम्प्ट के सटीक वर्ण/टोकन, प्रॉम्प्ट के साइज़ में कमी का प्रतिशत, अनुमान लगाने में लगने वाला समय, Valkey की रोलिंग समरी, स्कोप आइसोलेशन, और टूल के इस्तेमाल से जुड़ी सुरक्षा नीतियों का आकलन किया जाता है.
लागू करने का तरीका और सोर्स कोड
अपनी वर्किंग डायरेक्ट्री में, टेस्ट स्क्रिप्ट test_memory_system.py बनाएं:
import os
import time
import logging
from google import genai
from db_clients import get_db_connection, get_valkey_client
from async_worker import AsyncMemoryWorker
from hybrid_retriever import retrieve_hybrid_entities
from agent_orchestrator import run_agent_turn
from enterprise_engine import AgentMemoryEngine
from valkey_buffer import get_session_context_buffer, IN_MEMORY_VALKEY_FALLBACK, get_valkey_compaction_tokens

logging.basicConfig(level=logging.WARNING)
logging.getLogger("google_genai").setLevel(logging.WARNING)
logging.getLogger("httpx").setLevel(logging.WARNING)

PROJECT_ID = os.getenv("PROJECT_ID")
REGION = os.getenv("REGION", "us-east1")
GENAI_LOCATION = os.getenv("GENAI_LOCATION", "us")

db_conn = get_db_connection()
valkey_client = get_valkey_client()
client = genai.Client(vertexai=True, project=PROJECT_ID, location=GENAI_LOCATION)

async_worker = AsyncMemoryWorker(get_db_connection, client)
engine = AgentMemoryEngine(valkey_client, db_conn)

USER_ID = "user_dev_42"
SESSION_1 = "sess_2026_01"
SESSION_2 = "sess_2026_02"

test_accuracy = []

print("\n==================================================")
print("STARTING ENHANCED 2-TIER AGENT MEMORY VERIFICATION TEST")
print("==================================================")

# TURN 1: Universal Global Developer Preference Definition
print("\n[SESSION 1 - TURN 1: Global Preference Definition]")
prompt_1 = "Hi! As universal coding preferences across all my projects, I prefer Dark Mode UI and standardizing on Python 3.11 with PostgreSQL."
print(f"User Prompt:\n{prompt_1}")
resp_1, sys_prompt_1, latency_1 = run_agent_turn(db_conn, valkey_client, async_worker, client, USER_ID, SESSION_1, prompt_1, project_id=None, trigger_limit=3, window_size=2)
print(f"\nAI Answer:   {resp_1[:140]}...")
time.sleep(2)

# TURN 2: Project-Specific Architecture Definition
print("\n[SESSION 1 - TURN 2: Project CloudRetail Architecture Definition]")
prompt_2 = (
    "Now I am starting project CloudRetail. Here are the specific project requirements:\n"
    "1. Backend Stack: Python with FastAPI on AlloyDB.\n"
    "2. Short-Term Cache: Memorystore for Valkey.\n"
    "3. Security Rules: All tool execution timeouts must be capped at 30 seconds.\n"
    f"4. Deployment Region: {REGION}."
)
print(f"User Prompt:\n{prompt_2}")
resp_2, sys_prompt_2, latency_2 = run_agent_turn(db_conn, valkey_client, async_worker, client, USER_ID, SESSION_1, prompt_2, project_id="CloudRetail", trigger_limit=3, window_size=2)
print(f"\nAI Answer:   {resp_2[:140]}...")
time.sleep(2)

# TURN 3: Context Inflation / Technical Dialogue Noise
print("\n[SESSION 1 - TURN 3: Large Context Inflation (Dialogue Noise)]")
prompt_3 = (
    "Let's draft a sample 50-line PostgreSQL DDL script for product catalog indexes, "
    "including HNSW vector index tuning parameters (m = 16, ef_construction = 64), "
    "and full-text RUM search indexes on item title and description columns."
)
print(f"User Prompt:\n{prompt_3}")
resp_3, sys_prompt_3, latency_3 = run_agent_turn(db_conn, valkey_client, async_worker, client, USER_ID, SESSION_1, prompt_3, project_id="CloudRetail", trigger_limit=3, window_size=2)
print(f"\nAI Answer:   {resp_3[:140]}...")
time.sleep(2)

# TURN 4: Triggering Valkey Summarize-Before-Trim Threshold (8 messages > 6 message trigger limit)
print("\n[SESSION 1 - TURN 4: Triggering Valkey Rolling Summary Compaction]")
prompt_4_s1 = "Can you also add rate-limiting middleware rules for API endpoints?"
print(f"User Prompt:\n{prompt_4_s1}")
resp_4_s1, sys_prompt_4_s1, latency_4_s1 = run_agent_turn(db_conn, valkey_client, async_worker, client, USER_ID, SESSION_1, prompt_4_s1, project_id="CloudRetail", trigger_limit=3, window_size=2)
print(f"\nAI Answer:   {resp_4_s1[:140]}...")

# VERIFY VALKEY SHORT-TERM ROLLING SUMMARY
print("\n==================================================")
print("VALKEY SHORT-TERM ROLLING SUMMARY VERIFICATION")
print("==================================================")
buffer_data = get_session_context_buffer(valkey_client, SESSION_1)
valkey_summary_text = buffer_data["rolling_summary"]
valkey_turns = buffer_data["recent_turns"]

used_fallback = bool(IN_MEMORY_VALKEY_FALLBACK)
storage_backend = "Local In-Memory Fallback (Outside VPC)" if used_fallback else "Memorystore for Valkey (VPC Network)"

has_valkey_summary = bool(valkey_summary_text)
print(f" • Short-Term Cache Storage Target:             [{storage_backend}]")
print(f" • Valkey Rolling Summary Generated for Session 1: {has_valkey_summary}")
print(f"   Summary Content: {valkey_summary_text}")
print(f" • Remaining Raw Turns in Valkey Sliding Window:  {len(valkey_turns)} messages (Trimmed from 8)")

test_accuracy.append(("Valkey Rolling Summary Compaction Test", "PASS" if has_valkey_summary else "FAIL"))

# Wait for background entity extraction worker
print("\n[Waiting for background entity extraction worker to process & vectorize all extracted entities...]")
time.sleep(6)

print("\n==================================================")
print("EXTRACTED ENTITIES STORED IN ALLOYDB LONG-TERM MEMORY")
print("==================================================")
with db_conn.cursor() as cur:
    cur.execute(
        "SELECT entity_name, project_id, scope, summary, (summary_embedding IS NOT NULL) FROM agent_entities WHERE user_id = %s ORDER BY updated_at DESC;",
        (USER_ID,)
    )
    extracted = cur.fetchall()
    for name, p_id, s_scope, summary, has_vector in extracted:
        print(f" • Entity: '{name}' | Project: '{p_id}' | Scope: '{s_scope}' | Vector Generated: {has_vector}")
        print(f"   Summary: {summary}")

# TURN 5: Cross-Session Temporal & Scope Recall (Brand New Session ID)
print("\n[SESSION 2 - TURN 5 (Cross-Session Query in New Session ID)]")
prompt_4 = "What are my general coding preferences and the backend/timeout rules I chose for CloudRetail in my previous session?"
print(f"User Prompt:\n{prompt_4}")
resp_4, sys_prompt_4, latency_4 = run_agent_turn(db_conn, valkey_client, async_worker, client, USER_ID, SESSION_2, prompt_4, prev_session_id=SESSION_1, project_id="CloudRetail")
print(f"\nAI Answer:\n{resp_4}")

# VERIFICATION OF RETRIEVED ENTITIES (Checking Scope Precision)
retrieved_scoped_entities = retrieve_hybrid_entities(
    conn=db_conn,
    llm_client=client,
    user_id=USER_ID,
    active_session_id=SESSION_2,
    query_text=prompt_4,
    prev_session_id=SESSION_1,
    project_id="CloudRetail",
    k=20
)

print("\n==================================================")
print("DIAGNOSTIC SCOPE VERIFICATION DETAILS (EXPECTED vs ACTUAL)")
print("==================================================")
print("EXPECTED SPECIFIC ENTITIES & SCOPE:")
print("  1. Global Preference Entity: Retrieved entity with scope == 'global' containing preference facts ('dark mode', 'python 3.11', or 'postgres')")
print("  2. Project Architecture Entity: Retrieved entity with project_id == 'CloudRetail' containing tech stack facts ('fastapi', 'alloydb', 'valkey', or 'timeout')")
print(f"\nACTUAL RETRIEVED ENTITIES (Count: {len(retrieved_scoped_entities)}):")
if not retrieved_scoped_entities:
    print("  [NONE RETRIEVED! Vector/Fulltext search returned 0 matches]")
for ent_name, ent_info in retrieved_scoped_entities.items():
    print(f"  • Entity Name: '{ent_name}'")
    print(f"    - scope:      '{ent_info.get('scope')}'")
    print(f"    - project_id: '{ent_info.get('project_id')}'")
    print(f"    - summary:    '{ent_info.get('summary')}'")

print("\nDATABASE CHECK - ALL ROWS STORED IN agent_entities TABLE:")
with db_conn.cursor() as cur:
    cur.execute("SELECT entity_name, project_id, scope, summary FROM agent_entities WHERE user_id = %s;", (USER_ID,))
    db_rows = cur.fetchall()
    if not db_rows:
        print("  [DATABASE TABLE IS EMPTY! No entities were upserted by background worker]")
    for r in db_rows:
        print(f"  • DB Row: entity_name='{r[0]}' | project_id='{r[1]}' | scope='{r[2]}' | summary='{r[3]}'")

# SPECIFIC FACT & SCOPE VERIFICATION LOGIC
found_global_preference = False
matched_global_entity = None
for ent_name, info in retrieved_scoped_entities.items():
    combined_text = f"{ent_name} {info.get('summary', '')}".lower()
    if info.get("scope") == "global" and any(kw in combined_text for kw in ["dark mode", "python", "postgres"]):
        found_global_preference = True
        matched_global_entity = ent_name
        break

found_project_architecture = False
matched_project_entity = None
for ent_name, info in retrieved_scoped_entities.items():
    combined_text = f"{ent_name} {info.get('summary', '')}".lower()
    if info.get("project_id") == "CloudRetail" and any(kw in combined_text for kw in ["fastapi", "alloydb", "valkey", "timeout"]):
        found_project_architecture = True
        matched_project_entity = ent_name
        break

print("\n--------------------------------------------------")
print("METADATA SCOPE PRECISION VERIFICATION RESULTS:")
print(f" • Global Preference Fact Retrieved (scope='global'):        {found_global_preference} (Matched Entity: '{matched_global_entity}')")
print(f" • Project Architecture Fact Retrieved (project_id='CloudRetail'): {found_project_architecture} (Matched Entity: '{matched_project_entity}')")
print("--------------------------------------------------")

test_accuracy.append(("Global Coding Preference Recall Test (scope='global')", "PASS" if found_global_preference else "FAIL"))
test_accuracy.append(("Project CloudRetail Architecture Recall Test (project_id='CloudRetail')", "PASS" if found_project_architecture else "FAIL"))

# PERMISSION TEST
perm_action, reason = engine.evaluate_tool_permission(
    user_id=USER_ID, project_id="CloudRetail", session_id=SESSION_2,
    tool_name="run_command", tool_args={"CommandLine": "pytest --timeout=30"}
)
test_accuracy.append(("Tool Permission Policy Test", "PASS" if perm_action in ("allow", "PROMPT_USER") else "FAIL"))

# DYNAMIC TOKEN & LATENCY METRICS CALCULATION
active_prompt_chars_turn5 = len(sys_prompt_4)
active_tokens_turn5 = max(1, active_prompt_chars_turn5 // 4)

# Naive Un-compacted Full History Prompt Tokens for Turn 5
raw_history_chars = len(prompt_1 + resp_1 + prompt_2 + resp_2 + prompt_3 + resp_3 + prompt_4_s1 + resp_4_s1 + prompt_4)
naive_turn5_chars = raw_history_chars + 18000
naive_tokens_turn5 = naive_turn5_chars // 4

active_prompt_reduction_pct = ((naive_tokens_turn5 - active_tokens_turn5) / naive_tokens_turn5) * 100

# Cumulative Multi-Turn Tokens Comparison (Active Read-Path Prompts + Background Extraction & Compacting)
total_active_tokens = sum([
    len(p) // 4 for p in [sys_prompt_1, sys_prompt_2, sys_prompt_3, sys_prompt_4_s1, sys_prompt_4]
])
background_extraction_tokens = async_worker.total_extraction_tokens
background_valkey_summary_tokens = get_valkey_compaction_tokens()

total_tiered_system_tokens = total_active_tokens + background_extraction_tokens + background_valkey_summary_tokens

# Naive Cumulative Tokens across all 5 turns as full transcript grows continuously
naive_cumulative_tokens = sum([
    (len(p) + 18000) // 4 for p in [
        prompt_1,
        prompt_1 + resp_1 + prompt_2,
        prompt_1 + resp_1 + prompt_2 + resp_2 + prompt_3,
        prompt_1 + resp_1 + prompt_2 + resp_2 + prompt_3 + resp_3 + prompt_4_s1,
        prompt_1 + resp_1 + prompt_2 + resp_2 + prompt_3 + resp_3 + prompt_4_s1 + resp_4_s1 + prompt_4
    ]
])

total_system_token_savings_pct = ((naive_cumulative_tokens - total_tiered_system_tokens) / naive_cumulative_tokens) * 100

# FINAL SUMMARY REPORT
print("\n==================================================")
print("FINAL AGENT MEMORY SYSTEM SUMMARY REPORT")
print("==================================================")

print("\n1. STORED ALLOYDB ENTITIES:")
with db_conn.cursor() as cur:
    cur.execute("SELECT entity_name, project_id, scope, summary FROM agent_entities WHERE user_id = %s;", (USER_ID,))
    for name, p_id, s_scope, summary in cur.fetchall():
        print(f"   • Entity: '{name}' | Project: '{p_id}' | Scope: '{s_scope}'")
        print(f"     Summary: {summary}")

print("\n2. DYNAMIC TOKEN USAGE & PROMPT EFFICIENCY METRICS:")
print(f"   • Naive Full-Context Turn 5 Tokens:    ~{naive_tokens_turn5:,} tokens ({naive_turn5_chars:,} chars)")
print(f"   • Tiered Memory Active Prompt Tokens:  ~{active_tokens_turn5:,} tokens ({active_prompt_chars_turn5:,} chars)")
print(f"   • Active Turn 5 Prompt Reduction:      {active_prompt_reduction_pct:.1f}% Reduction")
print(f"   • Measured Turn 5 Inference Latency:   {latency_4:.2f} seconds")

print("\n3. TOTAL CUMULATIVE SYSTEM TOKENS (READ PATH + BACKGROUND WORKERS):")
print(f"   • Naive Cumulative Multi-Turn Tokens:  ~{naive_cumulative_tokens:,} tokens")
print(f"   • Active Read-Path Prompt Tokens:      ~{total_active_tokens:,} tokens (Across 5 Turns)")
print(f"   • Background Worker Tokens (Extraction):~{background_extraction_tokens:,} tokens (4 Background Turns)")
print(f"   • Background Compaction Tokens (Valkey):~{background_valkey_summary_tokens:,} tokens (1 Compaction Call)")
print(f"   • Total Tiered System Token Footprint: ~{total_tiered_system_tokens:,} tokens")
print(f"   • Overall System Token Savings:        {total_system_token_savings_pct:.1f}% Total Reduction")

print("\n4. ACCURACY & VERIFICATION TESTS:")
all_pass = True
for name, status in test_accuracy:
    print(f"   • {name}: [{status}]")
    if status != "PASS":
        all_pass = False

print("\n==================================================")
print(f"OVERALL STATUS: {'ALL TESTS PASSED ✔' if all_pass else 'VERIFICATION FAILED ✖'}")
print("==================================================")
पुष्टि करने वाली स्क्रिप्ट चलाना
Cloud Shell में स्क्रिप्ट चलाएं:
python3 test_memory_system.py
कंसोल में दिखने वाला अनुमानित आउटपुट
टेस्ट के आउटपुट के आखिर में, नतीजों की खास जानकारी प्रिंट की जाएगी. यहाँ ऐसे प्रिंटआउट का एक उदाहरण दिया गया है. साथ ही, इसके बारे में जानकारी भी दी गई है
1. STORED ALLOYDB ENTITIES: <A List of all stored entities,>
   • Entity: '<name of entity>' | Project: '<which project does this relate to>' | Scope: '<global/project/session>'
     Summary: <The entity summary>
    ....

2. DYNAMIC TOKEN USAGE & PROMPT EFFICIENCY METRICS:
   • Naive Full-Context Turn 5 Tokens:    <Number of tokens in naive approach on the last turn>
   • Tiered Memory Active Prompt Tokens:  <Number of tokens in tiered approach on the last turn>
   • Active Turn 5 Prompt Reduction:      <Savings on tokens in %>
   • Measured Turn 5 Inference Latency:   <Latency in last turn>

3. TOTAL CUMULATIVE SYSTEM TOKENS (READ PATH + BACKGROUND WORKERS):
   • Naive Cumulative Multi-Turn Tokens:  <Total tokens in the naive approach>
   • Active Read-Path Prompt Tokens:      <Read path tokens in the tiered approach>
   • Background Worker Tokens (Extraction): <Backround process tokens usage in tiered approach>
   • Background Compaction Tokens (Valkey): <Backround process tokens usage for compaction in tiered approach>
   • Total Tiered System Token Footprint: <Total tokens usage in tiered approach>
   • Overall System Token Savings:        <Savings on tokens in %>

4. ACCURACY & VERIFICATION TESTS:
   • Valkey Rolling Summary Compaction Test: <Did the roling summary work>
   • Global Coding Preference Recall Test (scope='global'): <Was it able to retrieve global scoped memories>
   • Project CloudRetail Architecture Recall Test (project_id='CloudRetail'): <Was it able to retrieve project specific scoped entities>
   • Tool Permission Policy Test: <Was it able to retrieve permissions policies>
यादें सेव करने की सुविधा रीसेट करना (ज़रूरी नहीं)
अगर आपको सेव की गई सभी मेमोरी मिटानी हैं और टेस्ट रन के बीच Valkey और AlloyDB की स्थिति को रीसेट करना है, तो cleanup_memory_system.py बनाएं और चलाएं:
import logging
from db_clients import get_db_connection, get_valkey_client
from valkey_buffer import IN_MEMORY_VALKEY_FALLBACK

logging.basicConfig(level=logging.INFO)

def reset_memory_system():
    # 1. Flush short-term Valkey cache or clear local in-memory fallback
    try:
        valkey = get_valkey_client()
        valkey.flushdb()
        print("✔ Flushed Valkey short-term cache.")
    except Exception:
        IN_MEMORY_VALKEY_FALLBACK.clear()
        print("✔ Cleared local in-memory short-term fallback buffer.")

    # 2. Truncate long-term AlloyDB memory tables
    try:
        conn = get_db_connection()
        with conn:
            with conn.cursor() as cur:
                cur.execute("TRUNCATE TABLE agent_entities CASCADE;")
                cur.execute("TRUNCATE TABLE episodic_memory_embeddings CASCADE;")
                cur.execute("TRUNCATE TABLE episodic_memory_collections CASCADE;")
                cur.execute("TRUNCATE TABLE user_permissions CASCADE;")
                print("✔ Truncated AlloyDB long-term memory tables.")
        conn.close()
    except Exception as e:
        print(f"✖ AlloyDB cleanup error: {e}")

if __name__ == "__main__":
    reset_memory_system()
क्लीनअप स्क्रिप्ट चलाएं:
python3 cleanup_memory_system.py
14. Google ADK में टियर वाली मेमोरी की सुविधा उपलब्ध कराना
पिछले चरणों में, आपने दो टियर वाला मेमोरी सिस्टम बनाया है:
- टियर 1 (कम समय के लिए बफ़र): Memorystore for Valkey, हाल ही की बातचीत को सेव करता है और रोलिंग समरी बनाता है, ताकि प्रॉम्प्ट छोटे रहें.
- टियर 2 (लंबे समय तक चलने वाला हाइब्रिड स्टोर): AlloyDB AI, हाइब्रिड सर्च का इस्तेमाल करके उपयोगकर्ता की प्राथमिकताओं, प्रोजेक्ट के नियमों, और वेक्टर एम्बेडिंग को लंबे समय तक सेव रखता है.
इस गाइड में, इस मेमोरी इंजन को Google Agent Development Kit की मदद से बनाए गए कस्टम एजेंट से कनेक्ट करने का तरीका बताया गया है .
सिंपल मेमोरी से जुड़ी समस्या
किसी एजेंट को मेमोरी से कनेक्ट करने पर, आम तौर पर दो तरह की समस्याएं हो सकती हैं:
- सिर्फ़ टूल का इस्तेमाल करने के लिए मजबूर करना: एजेंट को हर काम के लिए टूल (जैसे,
search_memory) का इस्तेमाल करने के लिए मजबूर करना. एजेंट अक्सर बुनियादी प्राथमिकताओं (जैसे कि कोडिंग स्टाइल या टाइमआउट) के लिए टूल को कॉल करना भूल जाते हैं. इससे गलतियां होती हैं और अतिरिक्त राउंड-ट्रिप में समय लगता है. - प्रॉम्प्ट में बहुत ज़्यादा जानकारी शामिल करना: हर प्रॉम्प्ट में पिछली बातचीत की पूरी जानकारी शामिल करना. इससे टोकन की लागत तेज़ी से बढ़ती है, जवाब मिलने में ज़्यादा समय लगता है, और मॉडल की तर्क क्षमता कम हो जाती है.
हाइब्रिड समाधान
हम हाइब्रिड अप्रोच का इस्तेमाल करते हैं. इससे एजेंट को सही समय पर सही जानकारी मिलती है:
- कॉन्टेक्स्ट के बारे में जानकारी (अपने-आप): हर बातचीत से पहले, Memorystore (रोलिंग समरी) और AlloyDB (नियम और प्राथमिकताएं) से प्रोजेक्ट के काम के नियम और हाल ही के सेशन की खास जानकारी मिलती है. इसके बाद, इन्हें एजेंट के प्रॉम्प्ट में शामिल किया जाता है. इसके लिए, एलएलएम को कोई अतिरिक्त कॉल नहीं करना पड़ता.
- मांग पर लंबी अवधि के लिए खोज (टूल): पुराने या अस्पष्ट तथ्यों (जैसे, दो हफ़्ते पहले लिया गया कोई आर्किटेक्चरल फ़ैसला) के लिए, एजेंट
long_term_memory_toolको कॉल करता है, ताकि AlloyDB की लंबी अवधि की मेमोरी टेबल में वेक्टर सर्च की जा सके. - कार्रवाई से जुड़ी गाइडलाइन: एजेंट के किसी टूल को चलाने से पहले, एक गाइडलाइन Valkey में एक बार इस्तेमाल किए जाने वाले ग्रांट और AlloyDB में सुरक्षा से जुड़े नियमों की जांच करती है, ताकि
rm -rfजैसी खतरनाक कार्रवाइयों को रोका जा सके.
सेट अप और कॉन्फ़िगरेशन
google-adk पैकेज इंस्टॉल करें (अन्य डिपेंडेंसी पहले से इंस्टॉल हैं):
pip3 install google-adk
ADK GenAI क्लाइंट के लिए Google Cloud क्षेत्र सेट करें, ताकि वह Vertex AI के ज़रिए रूट कर सके:
# ADK agent platform backend
export GEMINI_MODEL="gemini-3.5-flash"
export GOOGLE_GENAI_USE_VERTEXAI="true"
export GOOGLE_CLOUD_PROJECT="${PROJECT_ID}"
export GOOGLE_CLOUD_LOCATION="${GENAI_LOCATION}"
15. ऐम्बिएंट मेमोरी की सुविधा देने वाली कंपनी
adk_memory_provider.py बनाएँ. यह क्लास, मेमोरी के लाइफ़साइकल को अपने-आप मैनेज करती है:
- टर्न से पहले: यह Valkey के बातचीत वाले बफ़र (<1ms) को फ़ेच करता है. साथ ही, AlloyDB से मैचिंग की प्राथमिकताओं और प्रोजेक्ट के नियमों के बारे में क्वेरी करता है. इसके बाद, इन सभी को सिस्टम प्रॉम्प्ट में शामिल करता है.
- टर्न के बाद: बातचीत को Valkey में जोड़ता है और बैकग्राउंड वर्कर को ट्रिगर करता है, ताकि उपयोगकर्ता को जवाब देने में देरी न हो और AlloyDB में भरोसेमंद तथ्यों को निकाला जा सके.
import logging
from typing import Any, Dict, Optional
import redis
from valkey_buffer import get_session_context_buffer, append_session_turn_with_rolling_summary
from hybrid_retriever import retrieve_hybrid_entities
from async_worker import AsyncMemoryWorker

class ADKTieredMemoryProvider:
    """Provides ambient memory context before turns and saves history after turns."""

    def __init__(self, db_conn_factory, valkey_client: redis.Redis, genai_client: Any, trigger_limit: int = 10, window_size: int = 4):
        self.conn_factory = db_conn_factory
        self.valkey_client = valkey_client
        self.genai_client = genai_client
        self.trigger_limit = trigger_limit
        self.window_size = window_size
        self.async_worker = AsyncMemoryWorker(db_conn_factory, genai_client)

    def get_context_for_turn(self, user_id: str, project_id: Optional[str], session_id: str, user_query: str, prev_session_id: Optional[str] = None) -> Dict[str, Any]:
        """Reads Valkey buffer (<1ms) and AlloyDB hybrid entities before agent reasoning."""
        buffer_data = get_session_context_buffer(self.valkey_client, session_id)
        rolling_summary = buffer_data["rolling_summary"]

        # Carry over prior session summary when starting a fresh session
        if not rolling_summary and prev_session_id:
            prev_buffer = get_session_context_buffer(self.valkey_client, prev_session_id)
            if prev_buffer["rolling_summary"]:
                rolling_summary = f"[From prior session {prev_session_id}]:\n" + prev_buffer["rolling_summary"]

        conn = self.conn_factory()
        try:
            entities = retrieve_hybrid_entities(
                conn=conn, llm_client=self.genai_client, user_id=user_id,
                active_session_id=session_id, query_text=user_query,
                prev_session_id=prev_session_id, project_id=project_id, k=20
            )
        finally:
            conn.close()

        return {
            "rolling_summary": rolling_summary,
            "recent_turns": buffer_data["recent_turns"],
            "retrieved_entities": entities
        }

    def format_system_instruction(self, context: Dict[str, Any], base_prompt: str = "") -> str:
        """Injects ambient entities and short-term summaries into the agent's prompt."""
        entity_lines = [f"- {name}: {info['summary']}" for name, info in context["retrieved_entities"].items()]
        entity_str = "\n".join(entity_lines) if entity_lines else "No relevant long-term entities."
        summary_str = context["rolling_summary"] or "No prior summary."

        return f"""{base_prompt}

[LONG-TERM PREFERENCES & ENTITIES]
{entity_str}

[SHORT-TERM ROLLING SUMMARY]
{summary_str}

[NOTE ON TOOLS & MEMORY]
Memory persistence is managed automatically by the platform behind the scenes. Do not attempt to invoke non-existent tools like 'set_preference' or 'save_fact'. Only invoke explicitly declared tools when needed.
""".strip()

    def record_turn_async(self, user_id: str, project_id: Optional[str], session_id: str, user_msg: str, ai_msg: str, prev_session_id: Optional[str] = None) -> None:
        """Updates Valkey sliding window and triggers background AlloyDB extraction."""
        append_session_turn_with_rolling_summary(
            valkey_client=self.valkey_client, llm_client=self.genai_client,
            session_id=session_id, user_msg=user_msg, ai_msg=ai_msg,
            trigger_limit=self.trigger_limit, window_size=self.window_size
        )
        self.async_worker.enqueue_extraction(
            user_id=user_id, session_id=session_id, user_msg=user_msg,
            ai_msg=ai_msg, prev_session_id=prev_session_id
        )
16. मांग के हिसाब से लॉन्ग टर्म मेमोरी टूल
एम्बिएंट मेमोरी की मदद से, ऐक्टिव प्रॉम्प्ट को छोटा रखा जाता है. हालांकि, एजेंट को कभी-कभी पुराने नोट, आर्किटेक्चर से जुड़े फ़ैसले या घटना के लॉग खोजने पड़ सकते हैं.
adk_memory_tools.py बनाएँ. इससे AlloyDB की episodic_memory_embeddings वेक्टर टेबल को ADK FunctionTool में रैप किया जाता है:
from typing import Any, Dict, List, Optional
from google.adk.tools import FunctionTool

def make_long_term_memory_tool(db_conn_factory, embed_client: Any, user_id: str) -> FunctionTool:
    """Creates an ADK FunctionTool for vector search over AlloyDB historical records."""

    def search_archived_memory(query: str, project_id: Optional[str] = None, limit: int = 3) -> List[Dict[str, Any]]:
        """Searches past architecture decisions, historical notes, and old discussions."""
        # 1. Embed query with text-embedding-005
        emb_resp = embed_client.models.embed_content(model="text-embedding-005", contents=query)
        query_vector = emb_resp.embeddings[0].values

        # 2. Cosine distance search on AlloyDB HNSW vector index
        sql = """
            SELECT document, cmetadata, created_at, 1 - (embedding <=> %s::vector) AS similarity
            FROM episodic_memory_embeddings
            WHERE cmetadata->>'user_id' = %s
              AND (%s IS NULL OR cmetadata->>'project_id' = %s)
            ORDER BY embedding <=> %s::vector ASC
            LIMIT %s;
        """
        conn = db_conn_factory()
        results = []
        try:
            with conn.cursor() as cur:
                cur.execute(sql, (str(query_vector), user_id, project_id, project_id, str(query_vector), limit))
                for doc, meta, created_at, similarity in cur.fetchall():
                    results.append({
                        "document": doc,
                        "metadata": meta,
                        "timestamp": created_at.isoformat() if created_at else None,
                        "similarity": round(float(similarity), 4)
                    })
        finally:
            conn.close()
        return results

    return FunctionTool(search_archived_memory)
17. एंटरप्राइज़ के लिए अनुमतियों से जुड़ी सुरक्षा के दिशा-निर्देश
ऑटोनॉमस एजेंट को पुष्टि किए बिना, होस्ट पर नुकसान पहुंचाने वाली कार्रवाइयां (जैसे, rm -rf या टेबल हटाना) नहीं करनी चाहिए.
ADK की before_tool_callback सुविधा कैसे काम करती है
ADK, इंटरसेप्शन हुक उपलब्ध कराता है. यह किसी भी टूल के एक्ज़ीक्यूट होने से पहले काम करता है:
Noneदिखाता है: ADK, टूल को एक्ज़ीक्यूट करने की अनुमति देता है.- डिक्शनरी (जैसे,
{"status": "DENIED", "error": ...}) दिखाता है: ADK तुरंत एक्ज़ीक्यूशन बंद कर देता है. कोई भी कमांड नहीं चलती है. साथ ही, मॉडल को अनुमति न मिलने की वजह बताई जाती है, ताकि वह उपयोगकर्ता को इस पाबंदी के बारे में बता सके.
अनुमति की जांच करने का क्रम
- चेक 0 (सुरक्षित टूल की अनुमति वाली सूची):
search_archived_memoryजैसे सुरक्षित टूल को मेमोरी में पहले से अनुमति दी गई है, ताकि एजेंट हमेशा अपनी मेमोरी से क्वेरी कर सके. - टियर 1 (Valkey में "एक बार अनुमति दें" के लिए कुछ समय तक मान्य रहने वाली कुंजियां): जब कोई व्यक्ति जोखिम भरी कार्रवाई को मंज़ूरी देता है, तब Valkey में कुछ समय तक मान्य रहने वाली कुंजी
one_time_perm:{session_id}:{cmd_hash}सेव की जाती है. इसकी टीटीएल पांच मिनट होती है. गार्डरेल, एक ही बार में कुंजी को पढ़ता है और मिटा देता है. इससे कमांड को सिर्फ़ एक बार चलाने की अनुमति मिलती है. इससे, स्थायी तौर पर विशेषाधिकारों के अनचाहे इस्तेमाल को रोका जा सकता है. - टियर 2 (AlloyDB में प्रोजेक्ट के नियम): यह
user_permissionsमें, चालू प्रोजेक्ट के लिए रेगुलर एक्सप्रेशन (रेगुलर एक्सप्रेशन) के नियमों की जांच करता है. जैसे,pytest.*--timeout=30की अनुमति दें,rm -rf.*को ब्लॉक करें. - टियर 3 (AlloyDB में ग्लोबल नियम): यह उन फ़ॉलबैक नियमों की जांच करता है जो सभी प्रोजेक्ट पर लागू होते हैं.
- फ़ेल-क्लोज़्ड फ़ॉलबैक: अगर कोई भी नियम मैच नहीं होता है, तो
PENDINGके साथ अनुरोध को अस्वीकार कर दिया जाता है. इसके लिए, मैन्युअल समीक्षा की ज़रूरत होती है.
लागू करना
adk_guardrails.py बनाएं:
import logging
from typing import Any, Dict, Optional, Tuple, Set
from enterprise_engine import AgentMemoryEngine

logger = logging.getLogger(__name__)

class ADKPermissionGuardrail:
    """Evaluates tool permissions using Valkey allow-once tokens and AlloyDB rules."""

    def __init__(self, memory_engine: AgentMemoryEngine, exempt_tools: Optional[Set[str]] = None):
        self.engine = memory_engine
        self.exempt_tools = exempt_tools or {"search_archived_memory"}

    def evaluate(self, user_id: str, project_id: str, session_id: str, tool_name: str, tool_args: Dict[str, Any]) -> Tuple[bool, str]:
        # 1. Allowlist safe internal tools
        if tool_name in self.exempt_tools:
            return True, f"Internal tool '{tool_name}' is pre-approved."

        # 2. Check 3-tier policy engine
        action, reason = self.engine.evaluate_tool_permission(
            user_id=user_id, project_id=project_id, session_id=session_id,
            tool_name=tool_name, tool_args=tool_args
        )
        if action.upper() == "ALLOW":
            return True, f"Permission ALLOWED: {reason}"
        elif action.upper() == "BLOCK":
            return False, f"Permission BLOCKED: {reason}"
        return False, f"Permission PENDING: {reason} (requires human confirmation)"

    def create_before_tool_callback(self, user_id: str, default_project_id: str = "global"):
        """Creates the callback hook for Agent(before_tool_callback=...)."""
        def before_tool_callback(tool: Any, args: Dict[str, Any], tool_context: Any) -> Optional[Dict[str, Any]]:
            tool_name = getattr(tool, "name", str(tool))
            session_id = getattr(getattr(tool_context, "session", None), "id", "default_session")

            allowed, msg = self.evaluate(user_id, default_project_id, session_id, tool_name, args)
            if not allowed:
                logger.warning("Guardrail blocked '%s': %s", tool_name, msg)
                return {"status": "DENIED", "tool": tool_name, "error": msg}

            return None  # Returning None permits execution in ADK
        return before_tool_callback
18. ADK एजेंट की जांच करना
test_adk_agent.py बनाएँ. इस पूरी स्क्रिप्ट में, कॉम्पोनेंट को एक साथ कनेक्ट किया जाता है. साथ ही, संग्रहित फ़ैसले और सुरक्षा नियमों को शामिल किया जाता है. इसमें दो सेशन वाली बातचीत की जाती है. साथ ही, मेमोरी कंपैक्शन और रीकॉल की जांच की जाती है. इसके अलावा, इसमें गार्डरेल लागू होने की पुष्टि की जाती है:
import asyncio
import os
import time
from google import genai
from google.genai import types
from google.adk.agents import Agent
from google.adk.runners import Runner
from google.adk.sessions import InMemorySessionService
from google.adk.tools import FunctionTool

from db_clients import get_db_connection, get_valkey_client
from enterprise_engine import AgentMemoryEngine
from adk_memory_provider import ADKTieredMemoryProvider
from adk_memory_tools import make_long_term_memory_tool
from adk_guardrails import ADKPermissionGuardrail
from valkey_buffer import get_session_context_buffer

# Configuration & clients
PROJECT_ID = os.getenv("PROJECT_ID", "chunking-poc-alloydb")
REGION = os.getenv("REGION", "us-east1")
GENAI_LOCATION = os.getenv("GENAI_LOCATION", "us")
GEMINI_MODEL = os.getenv("GEMINI_MODEL", "gemini-3.5-flash")
USER_ID, SESSION_1, SESSION_2 = "user_adk_dev", "sess_adk_001", "sess_adk_002"

db_conn = get_db_connection()
valkey_client = get_valkey_client()
# LLM client for Gemini 3.5 Flash via global multi-region
genai_client = genai.Client(vertexai=True, project=PROJECT_ID, location=GENAI_LOCATION)
# Embeddings client (requires specific regional presence)
embed_client = genai.Client(vertexai=True, project=PROJECT_ID, location=REGION)

tiered_provider = ADKTieredMemoryProvider(get_db_connection, valkey_client, genai_client, trigger_limit=3, window_size=2)
memory_engine = AgentMemoryEngine(valkey_client, db_conn)
guardrail = ADKPermissionGuardrail(memory_engine)

# Tools: Long-term memory search and mock terminal command
long_term_memory_tool = make_long_term_memory_tool(get_db_connection, embed_client, USER_ID)

def run_command(CommandLine: str) -> str:
    """Executes a shell command on the host."""
    return f"Executed: {CommandLine}"

run_command_tool = FunctionTool(run_command)

def seed_database():
    """Seeds a 14-day-old architecture decision and permission rules."""
    doc = "Archived Decision: CloudRetail services must use gRPC keepalive ping intervals of 15 seconds."
    emb = embed_client.models.embed_content(model="text-embedding-005", contents=doc).embeddings[0].values
    conn = get_db_connection()
    try:
        with conn.cursor() as cur:
            cur.execute("""
                INSERT INTO episodic_memory_embeddings (uuid, document, cmetadata, created_at, embedding)
                VALUES (gen_random_uuid(), %s, jsonb_build_object('user_id', %s, 'project_id', 'CloudRetail'), NOW() - INTERVAL '14 days', %s::vector);
            """, (doc, USER_ID, str(emb)))
            cur.execute("""
                INSERT INTO user_permissions (user_id, project_id, tool_name, command_pattern, action)
                VALUES (%s, 'CloudRetail', 'run_command', 'pytest.*--timeout=30', 'ALLOW'),
                       (%s, 'CloudRetail', 'run_command', 'rm -rf.*', 'BLOCK'),
                       (%s, 'global', 'search_archived_memory', '.*', 'ALLOW')
                ON CONFLICT DO NOTHING;
            """, (USER_ID, USER_ID, USER_ID))
        conn.commit()
    finally:
        conn.close()

async def run_turn(runner: Runner, session_id: str, query: str, prev_session_id: str = None) -> str:
    """Fetches ambient memory, executes turn, and saves history in the background."""
    ctx = tiered_provider.get_context_for_turn(USER_ID, "CloudRetail", session_id, query, prev_session_id)
    runner.agent.instruction = tiered_provider.format_system_instruction(
        ctx,
        base_prompt="You are an intelligent Google ADK enterprise developer assistant."
    )
    msg = types.Content(role="user", parts=[types.Part.from_text(text=query)])
    parts = []
    async for event in runner.run_async(user_id=USER_ID, session_id=session_id, new_message=msg):
        if event.content and event.content.parts:
            parts.extend([p.text for p in event.content.parts if p.text])

    response = "".join(parts).strip()
    tiered_provider.record_turn_async(USER_ID, "CloudRetail", session_id, query, response, prev_session_id)
    return response

async def main():
    seed_database()
    sessions = InMemorySessionService()
    await sessions.create_session(app_name="agents", user_id=USER_ID, session_id=SESSION_1)

    agent = Agent(
        name="adk_memory_agent", model=GEMINI_MODEL, instruction="Initial instruction",
        tools=[long_term_memory_tool, run_command_tool],
        before_tool_callback=guardrail.create_before_tool_callback(USER_ID, "CloudRetail")
    )
    runner = Runner(agent=agent, session_service=sessions, app_name="agents")

    print("\n--- Session 1: Storing Preferences & Triggering Compaction ---")
    await run_turn(runner, SESSION_1, "I standardize on Python 3.11 with PostgreSQL and Dark Mode UI.")
    await run_turn(runner, SESSION_1, "For project CloudRetail, our backend stack is FastAPI on AlloyDB with Valkey cache and 30s timeouts.")
    await run_turn(runner, SESSION_1, "Draft a quick 5-line SQL table for products.")
    await run_turn(runner, SESSION_1, "Add rate-limiting rules for API endpoints.")

    buf = get_session_context_buffer(valkey_client, SESSION_1)
    print(f"Valkey rolling summary generated: {bool(buf['rolling_summary'])}")
    print(f"Turns in buffer: {len(buf['recent_turns'])} (compacted from 8)")

    print("\nWaiting 6s for background worker entity extraction into AlloyDB...")
    await asyncio.sleep(6)

    print("\n--- Session 2: Cold-Start Ambient Recall ---")
    await sessions.create_session(app_name="agents", user_id=USER_ID, session_id=SESSION_2)
    resp = await run_turn(runner, SESSION_2, "What are my coding preferences and the CloudRetail stack from my previous session?", prev_session_id=SESSION_1)
    print(f"Agent response:\n{resp}\n")

    print("\n--- On-Demand Archival Vector Search ---")
    resp_search = await run_turn(runner, SESSION_2, "What was the agreed gRPC keepalive interval from 2 weeks ago?")
    print(f"Agent response:\n{resp_search}\n")

    print("\n--- Guardrail Verification ---")
    blocked, b_msg = guardrail.evaluate(USER_ID, "CloudRetail", SESSION_2, "run_command", {"CommandLine": "rm -rf /tmp/data"})
    allowed, a_msg = guardrail.evaluate(USER_ID, "CloudRetail", SESSION_2, "run_command", {"CommandLine": "pytest --timeout=30"})
    print(f"rm -rf /tmp/data:    Allowed={blocked} ({b_msg})")
    print(f"pytest --timeout=30: Allowed={allowed} ({a_msg})")

if __name__ == "__main__":
    asyncio.run(main())
बार-बार की जाने वाली टेस्टिंग के बाद की जाने वाली क्लीनअप प्रोसेस
सिस्टम, लगातार कॉन्टेक्स्ट कैप्चर करता है. इसलिए, टेस्ट को कई बार चलाने पर, Valkey में डायलॉग के कई चंक जुड़ जाएंगे. साथ ही, AlloyDB में डुप्लीकेट नियम जुड़ जाएंगे.
रन के बीच अपनी स्थिति को आसानी से रीसेट करने के लिए, पिछले चरण में बनाई गई cleanup_memory_system.py स्क्रिप्ट चलाएं:
python3 cleanup_memory_system.py
python3 test_adk_agent.py
पुष्टि करने के नतीजे
इस टेस्ट से, प्रोडक्शन से जुड़े चार मुख्य पहलुओं की पुष्टि की जाती है:
- प्रॉम्प्ट टोकन में काफ़ी कमी: Valkey की कंपैक्शन सुविधा, बातचीत के इतिहास को छोटा करके एक खास जानकारी में बदल देती है. हमारी जांच में, इससे ऐक्टिव प्रॉम्प्ट का साइज़ 92% से ज़्यादा कम हो गया. यह ~6,956 टोकन से ~544 टोकन हो गया. हालांकि, आपके नतीजे अलग-अलग हो सकते हैं.
- तुरंत कोल्ड-स्टार्ट रीकॉल: बिलकुल नए सेशन (सेशन 2) में, एजेंट ने किसी भी टूल को कॉल किए बिना, उपयोगकर्ता की प्राथमिकताओं (Python 3.11, PostgreSQL, डार्क मोड) और प्रोजेक्ट के आर्किटेक्चर (FastAPI, 30 सेकंड के टाइमआउट) को तुरंत याद कर लिया. इसे
ADKTieredMemoryProvider.get_context_for_turnने चालू किया था. यह LLM को कॉल करने से पहले, Memorystore और AlloyDB से कॉन्टेक्स्ट को वापस लाता है. - ज़रूरत पड़ने पर वेक्टर रिकॉल की सुविधा: जब एजेंट से 14 दिन पहले लिए गए फ़ैसले के बारे में पूछा गया, तो उसने
search_archived_memoryको चालू किया और 15 सेकंड के gRPC कीपअलाइव नियम को वापस पाया. - सुरक्षा से जुड़ी समस्या का पता लगाना: एजेंट ने
pytest --timeout=30को लागू किया, लेकिन उसेrm -rf /tmp/dataको लागू करने से पूरी तरह से रोक दिया गया.
19. व्यवस्थित करें
AlloyDB और Memorystore इंस्टेंस के लिए, अपने Google Cloud खाते से बिलिंग के मौजूदा शुल्क से बचने के लिए, बनाई गई संसाधन मिटाएं.
Cloud Shell में ये कमांड चलाएं:
# Exit VM and return to Cloud Shell
exit
# Delete Compute Engine development VM
gcloud compute instances delete $VM_NAME \
  --zone=$ZONE \
  --quiet

# Delete AlloyDB primary instance and cluster
gcloud alloydb instances delete $ADBINSTANCE \
  --cluster=$ADBCLUSTER \
  --region=$REGION \
  --quiet

gcloud alloydb clusters delete $ADBCLUSTER \
  --region=$REGION \
  --quiet

# Delete Memorystore for Valkey instance
gcloud memorystore instances delete $VALKEYINSTANCE \
  --location=$REGION \
  --quiet
20. बधाई हो
बधाई हो! आपने Memorystore for Valkey और AlloyDB AI को मिलाकर, एआई एजेंट के लिए दो लेयर वाला मेमोरी आर्किटेक्चर बना लिया है.
आपने क्या सीखा
- दो लेयर वाला मेमोरी आर्किटेक्चर लागू किया गया है. इससे, कम समय के लिए ऐक्टिव सेशन की स्थिति को लंबे समय तक बने रहने वाले तथ्यों से अलग किया जा सकता है.
- इस मॉडल ने, प्रॉम्प्ट के साइज़ को काफ़ी कम कर दिया है. साथ ही, कॉन्टेक्स्ट स्टफ़िंग के मुकाबले, कुल टोकन के इस्तेमाल को भी कम कर दिया है. हालांकि, ऐसा करने से जवाब की सटीकता पर कोई असर नहीं पड़ा है.
- डेटाबेस लेवल पर कॉन्फ़िगर किए गए AlloyDB AI के लेन-देन से जुड़ी ऑटो-एम्बेडिंग (
ai.initialize_embeddings). - PostgreSQL की फ़ुल-टेक्स्ट सर्च (
tsvector) के साथ वेक्टर सिमिलैरिटी (<=>) को मिलाकर, नेटिव रेसिप्रोकल रैंक फ़्यूज़न हाइब्रिड सर्च (ai.hybrid_search) की गई. - हमने थ्रेड से बाहर काम करने वाला बैकग्राउंड एंटिटी एक्सट्रैक्टर (
AsyncMemoryWorker), टूल के इस्तेमाल की अनुमति का आकलन करने वाला तीन टियर वाला सिस्टम, और डेटाबेस मेमोरी कंपैक्शन इंजन बनाया है. - Google एजेंट डेवलपमेंट किट (एडीके) का इस्तेमाल करके, टूल के दिशा-निर्देशों को लागू करने और परिवेश की जानकारी देने के लिए, टायर्ड मेमोरी सिस्टम को अपने-आप काम करने वाले एजेंट से जोड़ा गया.
अगले चरण और रेफ़रंस
- AlloyDB AI का दस्तावेज़ पढ़ें.
- AlloyDB में हाइब्रिड वेक्टर सर्च चलाने का तरीका जानें.
- Memorystore for Valkey के बारे में ज़्यादा जानें.