

1. परिचय
इस कोडलैब में, आपको Google Kubernetes Engine (GKE) पर AlloyDB Omni को डिप्लॉय करने का तरीका बताया जाएगा. साथ ही, एंबेडिंग और अनुमानों के लिए, EmbeddingGemma और Gemma 4 जैसे ओपन मॉडल के साथ इसका इस्तेमाल करने का तरीका बताया जाएगा. डेटाबेस और मॉडल, दोनों को एक ही क्लस्टर में चलाने से नेटवर्क की लेटेन्सी कम हो जाती है. साथ ही, तीसरे पक्ष की सेवा पर निर्भरता भी कम हो जाती है. इससे अनुपालन और डेटा रेज़िडेंसी से जुड़ी ज़रूरी शर्तों को पूरा करने में भी मदद मिलती है, क्योंकि आपका डेटा कभी भी आपके एनवायरमेंट से बाहर नहीं जाता.
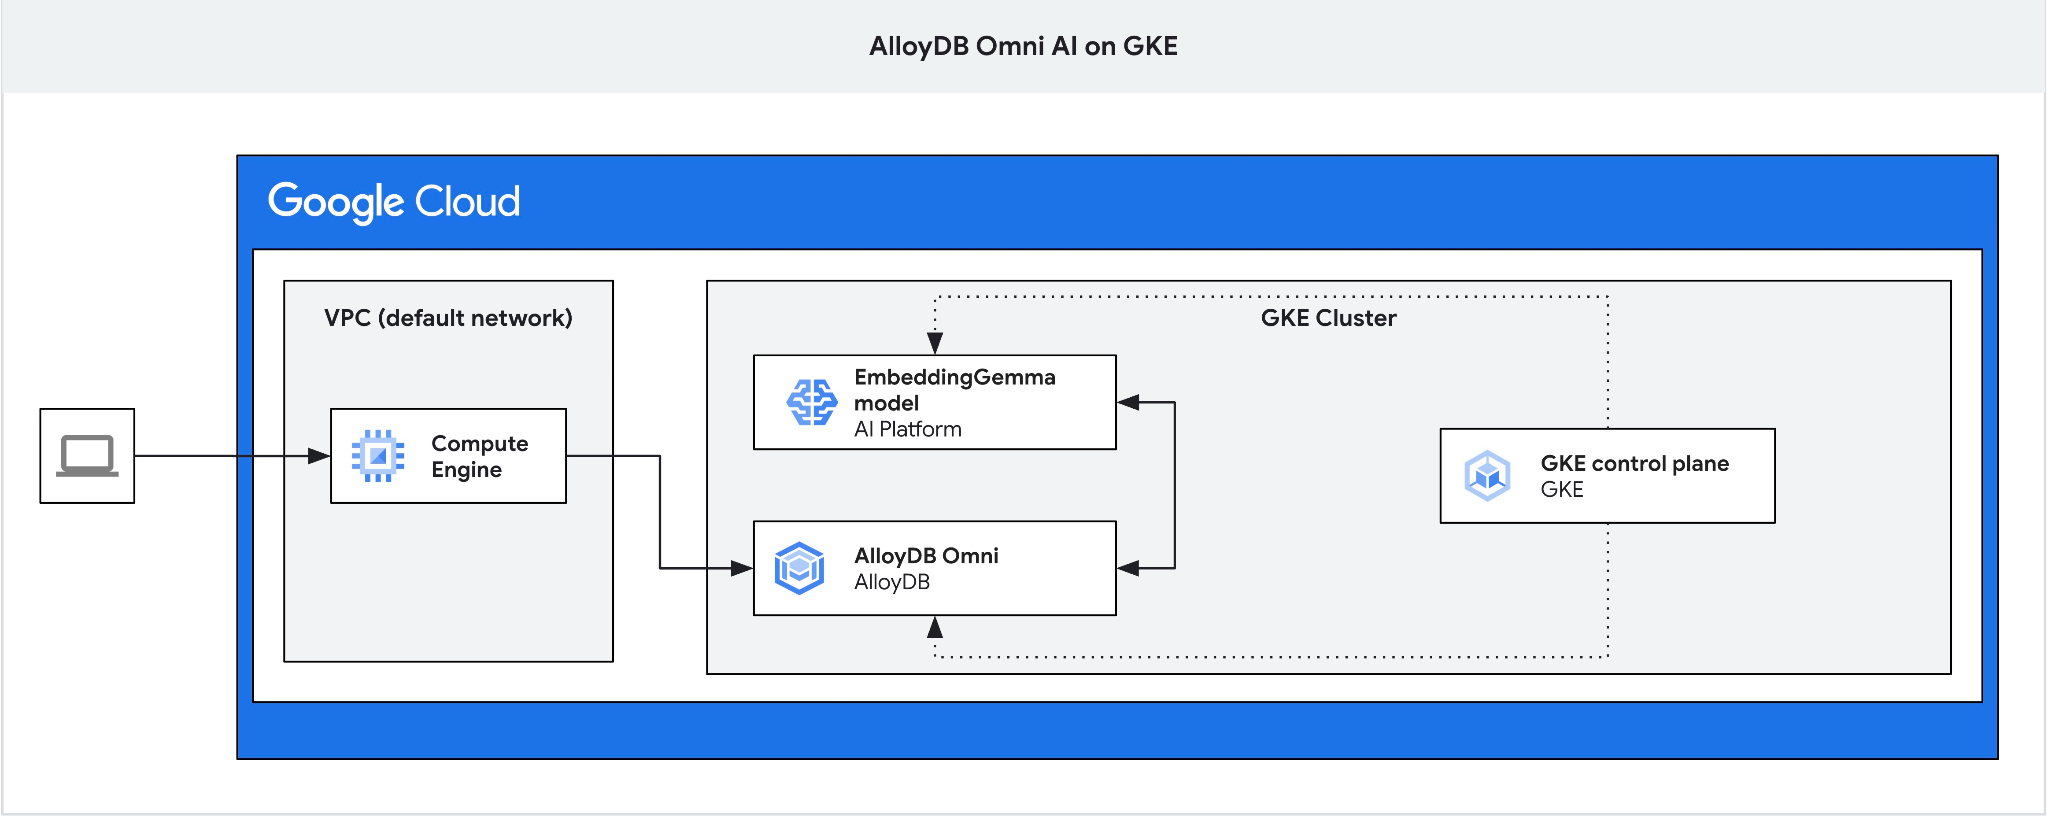
ज़रूरी शर्तें
- Google Cloud और Google Cloud Console के बारे में बुनियादी जानकारी
- Kubernetes और GKE की बुनियादी जानकारी
- कमांड-लाइन इंटरफ़ेस और Google Cloud Shell के बारे में जानकारी
आपको क्या सीखने को मिलेगा
- GKE क्लस्टर पर AlloyDB Omni को डिप्लॉय करने का तरीका
- AlloyDB Omni से कनेक्ट करने का तरीका
- AlloyDB Omni में डेटा लोड करने का तरीका
- GKE पर एआई मॉडल (एलएलएम और एंबेडिंग) डिप्लॉय करने का तरीका
- AlloyDB Omni में एआई मॉडल रजिस्टर करने का तरीका
- सिमैंटिक सर्च के लिए एम्बेडिंग जनरेट करने का तरीका
- AlloyDB Omni में सिमैंटिक सर्च क्वेरी चलाने का तरीका
- AlloyDB Omni में वेक्टर इंडेक्स बनाने और उनका इस्तेमाल करने का तरीका
आपको किन चीज़ों की ज़रूरत होगी
- Google Cloud खाता और Google Cloud प्रोजेक्ट
- कोई वेब ब्राउज़र, जैसे कि Chrome
2. सेट अप करने का तरीका और ज़रूरी शर्तें
प्रोजेक्ट सेटअप करना
- Google Cloud Console में साइन इन करें. अगर आपके पास Gmail या Google Workspace खाता नहीं है, तो खाता बनाएं. ऑफ़िस या स्कूल वाले खाते के बजाय, निजी खाते का इस्तेमाल करें.
- नया प्रोजेक्ट बनाएं या कोई मौजूदा प्रोजेक्ट चुनें. Google Cloud Console के हेडर में, कोई प्रोजेक्ट चुनें पर क्लिक करें. इसके बाद, नया प्रोजेक्ट पर क्लिक करें.
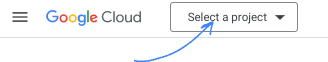
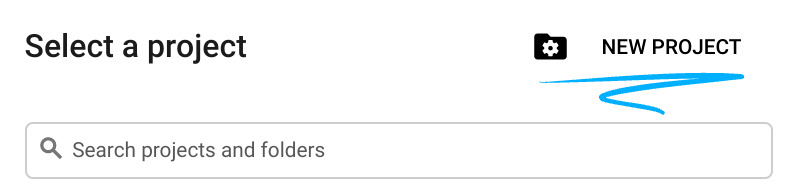
कोई प्रोजेक्ट चुनें विंडो में, प्रोजेक्ट बनाने का डायलॉग बॉक्स खोलने के लिए नया प्रोजेक्ट पर क्लिक करें.
डायलॉग बॉक्स में, प्रोजेक्ट का नाम डालें. इसके बाद, अपना संगठन या जगह चुनें.
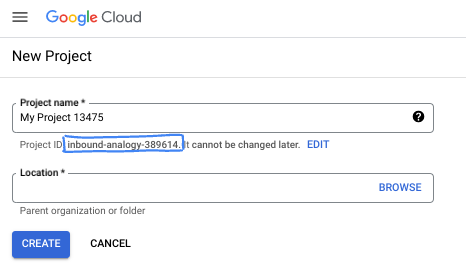
- प्रोजेक्ट का नाम, इस प्रोजेक्ट में हिस्सा लेने वाले लोगों के लिए डिसप्ले नेम होता है. प्रोजेक्ट के नाम का इस्तेमाल Google API नहीं करते हैं. इसे कभी भी बदला जा सकता है.
- प्रोजेक्ट आईडी, सभी Google Cloud प्रोजेक्ट के लिए यूनीक होता है. साथ ही, इसे बदला नहीं जा सकता. Google Cloud Console, अपने-आप एक यूनीक आईडी जनरेट करता है. हालांकि, आपके पास अपना आईडी देने का विकल्प भी होता है. इस कोडलैब में,
- प्रोजेक्ट नंबर, तीसरा आइडेंटिफ़ायर है. इसका इस्तेमाल कुछ एपीआई करते हैं. ज़्यादा जानकारी के लिए, Resource Manager का दस्तावेज़ देखें.
बिलिंग की सुविधा चालू करें
अगर आपने Google Cloud क्रेडिट का इस्तेमाल करके बिलिंग सेट अप की है, तो इस चरण को छोड़ा जा सकता है.
निजी बिलिंग खाता सेट अप करने के लिए, Google Cloud Console में बिलिंग की सुविधा चालू करें.
- इस लैब को पूरा करने में, Google Cloud संसाधनों पर पांच डॉलर से कम का खर्च आता है.
- संसाधन मिटाने और आगे लगने वाले शुल्क से बचने के लिए, इस लैब के आखिर में दिए गए क्लीनअप के चरणों का पालन करें.
- नए उपयोगकर्ता, 300 डॉलर का क्रेडिट मुफ़्त में आज़मा सकते हैं.
Cloud Shell शुरू करना
इस कोडलैब में, Google Cloud Shell का इस्तेमाल किया जाता है. यह क्लाउड में चलने वाला कमांड-लाइन एनवायरमेंट है.
Google Cloud Console में, सबसे ऊपर दाएं कोने में मौजूद टूलबार पर, Cloud Shell चालू करें आइकॉन पर क्लिक करें:
इसके अलावा, G और फिर S दबाएं या Google Cloud Shell सीधे तौर पर खोलें.
कनेक्ट होने पर, Cloud Shell में टर्मिनल प्रॉम्प्ट दिखता है:
Cloud Shell में परसिस्टेंट स्टोरेज और डेवलपमेंट टूल शामिल होते हैं. इस कोडलैब में दिए गए सभी चरणों को अपने ब्राउज़र से पूरा किया जा सकता है.
3. एपीआई चालू करें
AlloyDB Omni और मॉडल डिप्लॉयमेंट के लिए, Google Kubernetes Engine (GKE) का इस्तेमाल करने के लिए, अपने Google Cloud प्रोजेक्ट में Compute Engine और GKE API चालू करें.
Cloud Shell में जाकर पुष्टि करें कि आपका प्रोजेक्ट आईडी कॉन्फ़िगर किया गया है:
PROJECT_ID=$(gcloud config get-value project)
echo $PROJECT_ID
अगर आपका प्रोजेक्ट आईडी तय नहीं किया गया है, तो इसे कॉन्फ़िगर करें:
export PROJECT_ID=<YOUR_PROJECT_ID>
gcloud config set project $PROJECT_ID
ज़रूरी एपीआई चालू करें:
gcloud services enable compute.googleapis.com
gcloud services enable container.googleapis.com
अनुमानित आउटपुट:
student@cloudshell:~ (test-project-001-402417)$ PROJECT_ID=test-project-001-402417
student@cloudshell:~ (test-project-001-402417)$ gcloud config set project test-project-001-402417
Updated property [core/project].
student@cloudshell:~ (test-project-001-402417)$ gcloud services enable compute.googleapis.com
gcloud services enable container.googleapis.com
Operation "operations/acat.p2-4470404856-1f44ebd8-894e-4356-bea7-b84165a57442" finished successfully.
चालू किए गए हर एपीआई के बारे में, दस्तावेज़ में पढ़ा जा सकता है.
4. GKE पर AlloyDB Omni डिप्लॉय करना
GKE पर AlloyDB Omni को डिप्लॉय करने के लिए, AlloyDB Omni ऑपरेटर की ज़रूरी शर्तों के मुताबिक Kubernetes क्लस्टर तैयार करें.
GKE क्लस्टर बनाना
AlloyDB Omni, ऑपरेटर, और मॉनिटरिंग कंटेनर चलाने की क्षमता वाला स्टैंडर्ड GKE क्लस्टर डिप्लॉय करें. AlloyDB Omni के लिए, कम से कम दो सीपीयू और 8 जीबी रैम की ज़रूरत होती है. इस ट्यूटोरियल में, n2-standard-4 मशीन टाइप का इस्तेमाल किया गया है.
डिप्लॉयमेंट के लिए एनवायरमेंट वैरिएबल सेट करें:
export PROJECT_ID=$(gcloud config get-value project)
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
export MACHINE_TYPE=n2-standard-4
स्टैंडर्ड GKE क्लस्टर बनाएं:
gcloud container clusters create ${CLUSTER_NAME} \
  --project=${PROJECT_ID} \
  --region=${LOCATION} \
  --workload-pool=${PROJECT_ID}.svc.id.goog \
  --release-channel=rapid \
  --machine-type=${MACHINE_TYPE} \
  --num-nodes=1
अनुमानित कंसोल आउटपुट:
student@cloudshell:~ (test-project-001-402417)$ export PROJECT_ID=$(gcloud config get project)
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
export MACHINE_TYPE=n2-standard-4
Your active configuration is: [test-project-001-402417]
student@cloudshell:~ (test-project-001-402417)$ gcloud container clusters create ${CLUSTER_NAME} \
  --project=${PROJECT_ID} \
  --region=${LOCATION} \
  --workload-pool=${PROJECT_ID}.svc.id.goog \
  --release-channel=rapid \
  --machine-type=${MACHINE_TYPE} \
  --num-nodes=1
Note: Your Pod address range (`--cluster-ipv4-cidr`) can accommodate at most 1008 node(s).
Creating cluster alloydb-ai-gke in us-central1... Cluster is being health-checked (Kubernetes Control Plane is healthy)...done.
Created [https://container.googleapis.com/v1/projects/test-project-001-402417/zones/us-central1/clusters/alloydb-ai-gke].
To inspect the contents of your cluster, go to: https://console.cloud.google.com/kubernetes/workload_/gcloud/us-central1/alloydb-ai-gke?project=test-project-001-402417
kubeconfig entry generated for alloydb-ai-gke.
NAME: alloydb-ai-gke
LOCATION: us-central1
MASTER_VERSION: 1.36.3-gke.1640000
MASTER_IP: 34.121.243.65
MACHINE_TYPE: n2-standard-4
NODE_VERSION: 1.36.3-gke.1640000
NUM_NODES: 3
STATUS: RUNNING
STACK_TYPE: IPV4
क्लस्टर तैयार करना
ज़रूरी कॉम्पोनेंट इंस्टॉल करें. जैसे, cert-manager, Kubernetes के लिए नेटिव सर्टिफ़िकेट कंट्रोलर. ज़्यादा जानकारी के लिए, cert-manager को इंस्टॉल करने से जुड़ा दस्तावेज़ देखें.
Cloud Shell में Kubernetes कमांड-लाइन टूल kubectl शामिल होता है. gcloud का इस्तेमाल करके, क्लस्टर के क्रेडेंशियल पाएं:
gcloud container clusters get-credentials ${CLUSTER_NAME} --region=${LOCATION}
kubectl का इस्तेमाल करके cert-manager इंस्टॉल करें:
kubectl apply -f https://github.com/cert-manager/cert-manager/releases/download/v1.21.1/cert-manager.yaml
कंसोल में दिखने वाला अनुमानित आउटपुट (संशोधित):
student@cloudshell:~$ kubectl apply -f https://github.com/cert-manager/cert-manager/releases/download/v1.21.1/cert-manager.yaml
namespace/cert-manager created
customresourcedefinition.apiextensions.k8s.io/certificaterequests.cert-manager.io created
customresourcedefinition.apiextensions.k8s.io/certificates.cert-manager.io created
customresourcedefinition.apiextensions.k8s.io/challenges.acme.cert-manager.io created
customresourcedefinition.apiextensions.k8s.io/clusterissuers.cert-manager.io created
...
validatingwebhookconfiguration.admissionregistration.k8s.io/cert-manager-webhook created
AlloyDB Omni ऑपरेटर इंस्टॉल करना
Helm का इस्तेमाल करके, AlloyDB Omni ऑपरेटर इंस्टॉल करें.
AlloyDB Omni ऑपरेटर चार्ट डाउनलोड और इंस्टॉल करें:
helm install alloydbomni-operator oci://gcr.io/alloydb-omni/alloydbomni-operator \
--version 1.8.1 \
--create-namespace \
--namespace alloydb-omni-system \
--atomic \
--timeout 5m
कंसोल में दिखने वाला अनुमानित आउटपुट (संशोधित):
student@cloudshell:~$ helm install alloydbomni-operator oci://gcr.io/alloydb-omni/alloydbomni-operator \
> --version 1.8.0 \
> --create-namespace \
> --namespace alloydb-omni-system \
> --atomic \
> --timeout 5m
Flag --atomic has been deprecated, use --rollback-on-failure instead
Pulled: gcr.io/alloydb-omni/alloydbomni-operator:1.8.0
Digest: sha256:f2d98fa7a3b08dfc1e83b811582718b94e5c017b81aade700c83e917c59f0395
NAME: alloydbomni-operator
LAST DEPLOYED: Thu Aug 27 17:57:30 2026
NAMESPACE: alloydb-omni-system
STATUS: deployed
REVISION: 1
DESCRIPTION: Install complete
TEST SUITE: None
डेटाबेस क्लस्टर डिप्लॉय करें.
यहां दिया गया मेनिफ़ेस्ट, googleMLExtension सुविधा चालू करके और इंटरनल लोड बैलेंसर का इस्तेमाल करके, डेटाबेस क्लस्टर को कॉन्फ़िगर करता है:
cat << 'EOF' > my-omni.yaml
apiVersion: v1
kind: Secret
metadata:
  name: db-pw-my-omni
type: Opaque
data:
  my-omni: "VmVyeVN0cm9uZ1Bhc3N3b3Jk"
---
apiVersion: alloydbomni.dbadmin.goog/v1
kind: DBCluster
metadata:
  name: my-omni
spec:
  databaseVersion: "18.3.0"
  primarySpec:
    adminUser:
      passwordRef:
        name: db-pw-my-omni
    features:
      googleMLExtension:
        enabled: true
    resources:
      cpu: 1
      memory: 8Gi
      disks:
      - name: DataDisk
        size: 20Gi
        storageClass: standard
    dbLoadBalancerOptions:
      annotations:
        networking.gke.io/load-balancer-type: "internal"
  allowExternalIncomingTraffic: true
EOF
पासवर्ड सीक्रेट वैल्यू, VeryStrongPassword का Base64 फ़ॉर्मैट है. प्रोडक्शन एनवायरमेंट में, पासवर्ड मैनेज करने के लिए Google Secret Manager का इस्तेमाल करें. ज़्यादा जानकारी के लिए, Secret Manager का दस्तावेज़ देखें.
मेनिफ़ेस्ट को my-omni.yaml के तौर पर सेव किया जाता है. Cloud Shell में, टर्मिनल विंडो के सबसे ऊपर दाएं कोने में मौजूद एडिटर खोलें पर क्लिक करें और फ़ाइल पढ़ें.
my-omni.yaml मेनिफ़ेस्ट पढ़ने के बाद, कमांड प्रॉम्प्ट पर वापस जाने के लिए टर्मिनल खोलें पर क्लिक करें.
my-omni.yaml मेनिफ़ेस्ट लागू करें:
kubectl apply -f my-omni.yaml
अनुमानित कंसोल आउटपुट:
secret/db-pw-my-omni created
dbcluster.alloydbomni.dbadmin.goog/my-omni created
my-omni क्लस्टर का स्टेटस देखें:
kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default
डेटाबेस क्लस्टर को डिप्लॉय करते समय, सेटअप के अलग-अलग चरणों से गुज़रना पड़ता है. इसके बाद, यह DBClusterReady स्थिति में पहुंचता है.
अनुमानित कंसोल आउटपुट:
$ kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default
NAME      PRIMARYENDPOINT   PRIMARYPHASE   DBCLUSTERPHASE   HAREADYSTATUS   HAREADYREASON
my-omni   10.131.0.33        Ready          DBClusterReady
kubectl log कमांड का इस्तेमाल करके, क्लस्टर डिप्लॉयमेंट को मॉनिटर किया जा सकता है. हालांकि, ऐसा करना ज़रूरी नहीं है:
kubectl logs -l alloydbomni.internal.dbadmin.goog/dbcluster=my-omni --all-containers -f
AlloyDB Omni से कनेक्ट करना
क्लस्टर तैयार होने के बाद, PostgreSQL क्लाइंट (psql) का इस्तेमाल करके डेटाबेस पॉड से कनेक्ट करें. my-omni.yaml में बताए गए तरीके के मुताबिक, पासवर्ड VeryStrongPassword है:
DB_CLUSTER_NAME=my-omni
DB_CLUSTER_NAMESPACE=default
DBPOD=`kubectl get pod --selector=alloydbomni.internal.dbadmin.goog/dbcluster=$DB_CLUSTER_NAME,alloydbomni.internal.dbadmin.goog/task-type=database -n $DB_CLUSTER_NAMESPACE -o jsonpath='{.items[0].metadata.name}'`
kubectl exec -ti $DBPOD -n $DB_CLUSTER_NAMESPACE -c database -- psql -h localhost -U postgres
कंसोल आउटपुट का सैंपल:
DB_CLUSTER_NAME=my-omni
DB_CLUSTER_NAMESPACE=default
DBPOD=`kubectl get pod --selector=alloydbomni.internal.dbadmin.goog/dbcluster=$DB_CLUSTER_NAME,alloydbomni.internal.dbadmin.goog/task-type=database -n $DB_CLUSTER_NAMESPACE -o jsonpath='{.items[0].metadata.name}'`
kubectl exec -ti $DBPOD -n $DB_CLUSTER_NAMESPACE -c database -- psql -h localhost -U postgres
Password for user postgres:
psql (18.3)
SSL connection (protocol: TLSv1.3, cipher: TLS_AES_128_GCM_SHA256, compression: off, ALPN: postgresql)
Type "help" for help.

postgres=#
\q टाइप करके और Enter दबाकर, psql सेशन से बाहर निकलें:
postgres=# \q
5. GKE पर EmbeddingGemma मॉडल डिप्लॉय करना
स्थानीय मॉडल के साथ AlloyDB Omni के एआई इंटिग्रेशन को टेस्ट करने के लिए, GKE क्लस्टर में एंबेडिंग मॉडल डिप्लॉय करें. इस ट्यूटोरियल में, Google के EmbeddingGemma मॉडल का इस्तेमाल किया गया है.
मॉडल के लिए नोड पूल बनाना
मॉडल इन्फ़्रेंस चलाने के लिए, एक डेडीकेटेड नोड पूल तैयार करें. सीपीयू-ओनली नोड पूल या जीपीयू-ऐक्सलरेटेड नोड पूल (जैसे, NVIDIA L4 जीपीयू के साथ g2-standard-8) का इस्तेमाल किया जा सकता है. इस ट्यूटोरियल में, सीपीयू पर आधारित नोड पूल का इस्तेमाल किया गया है. इसमें c3-standard-8 मशीन टाइप हैं.
सिंगल-नोड सीपीयू नोड पूल बनाएं:
export PROJECT_ID=$(gcloud config get-value project)
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
gcloud container node-pools create cpupool \
  --project=${PROJECT_ID} \
  --location=${LOCATION} \
  --node-locations=${LOCATION}-a \
  --cluster=${CLUSTER_NAME} \
  --machine-type=c3-standard-8 \
  --num-nodes=1
अनुमानित आउटपुट:
student@cloudshell$ export PROJECT_ID=$(gcloud config get project)
Your active configuration is: [pant]
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
student@cloudshell$ gcloud container node-pools create cpupool \
>   --project=${PROJECT_ID} \
>   --location=${LOCATION} \
>   --node-locations=${LOCATION}-a \
>   --cluster=${CLUSTER_NAME} \
>   --machine-type=c3-standard-8 \
>   --num-nodes=1
Creating node pool cpupool...done.
Created [https://container.googleapis.com/v1/projects/gleb-test-short-003-483115/zones/us-central1/clusters/alloydb-ai-gke/nodePools/cpupool].
NAME     MACHINE_TYPE    DISK_SIZE_GB  NODE_VERSION
cpupool  c3-standard-8  100           1.34.1-gke.3355002
Hugging Face टोकन पाना
इस ट्यूटोरियल में, Hugging Face से EmbeddingGemma मॉडल को डिप्लॉय किया गया है. मॉडल के वेट ऐक्सेस करने के लिए, Hugging Face का ऐक्सेस टोकन जनरेट करें:
- Hugging Face पर साइन इन करें या खाता बनाएं.
- आपकी प्रोफ़ाइल > ऐक्सेस टोकन पर जाएं.
- नया टोकन बनाएं पर क्लिक करें.
- टोकन के लिए कोई नाम डालें और पढ़ें भूमिका चुनें.
- टोकन बनाएं पर क्लिक करें और जनरेट की गई टोकन वैल्यू को कॉपी करें.
- अगर आपने पहले कभी मॉडल की शर्तें स्वीकार नहीं की हैं, तो EmbeddingGemma मॉडल पेज पर जाकर, मॉडल की शर्तें स्वीकार करें.
Cloud Shell में, Hugging Face टोकन वाला Kubernetes सीक्रेट बनाएं. इसके लिए, टोकन प्लेसहोल्डर को अपने टोकन से बदलें:
export HF_TOKEN=<YOUR_HUGGING_FACE_TOKEN>
kubectl create secret generic hf-secret \
  --from-literal=hf_api_token=$HF_TOKEN \
  --dry-run=client -o yaml | kubectl apply -f -
डिप्लॉयमेंट मेनिफ़ेस्ट तैयार करना
मॉडल को डिप्लॉय करने के लिए, Hugging Face के Text Embeddings Inference (TEI) कंटेनर पैकेज का इस्तेमाल करें. ज़्यादा जानकारी के लिए, Hugging Face GKE TEI का दस्तावेज़ देखें.
GitHub से डिप्लॉयमेंट रिपॉज़िटरी को क्लोन करें:
git clone https://github.com/huggingface/Google-Cloud-Containers
सीपीयू कॉन्फ़िगरेशन मेनिफ़ेस्ट की जांच करें और उसमें बदलाव करें:
edit Google-Cloud-Containers/examples/gke/tei-deployment/cpu-config/deployment.yaml
सीपीयू डिप्लॉयमेंट के लिए अपडेट किया गया मेनिफ़ेस्ट:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: tei-deployment
spec:
  replicas: 1
  selector:
    matchLabels:
      app: tei-server
  template:
    metadata:
      labels:
        app: tei-server
        hf.co/model: Google--embeddinggemma-300m
        hf.co/task: text-embeddings
    spec:
      containers:
        - name: tei-container
          image: ghcr.io/huggingface/text-embeddings-inference:cpu-latest
          resources:
            requests:
              cpu: "6"
              memory: "24Gi"
            limits:
              cpu: "6"
              memory: "24Gi"
          env:
            - name: MODEL_ID
              value: google/embeddinggemma-300m
            - name: NUM_SHARD
              value: "1"
            - name: PORT
              value: "8080"
            - name: HF_TOKEN
              valueFrom:
                secretKeyRef:
                  name: hf-secret
                  key: hf_api_token
          volumeMounts:
            - mountPath: /tmp
              name: tmp
      volumes:
        - name: tmp
          emptyDir: {}
      nodeSelector:
        cloud.google.com/machine-family: "c3"
ctrl+s दबाकर बदलावों को सेव करें और वापस टर्मिनल पर जाएं.
मॉडल डिप्लॉय करना
TEI सर्वर को डिप्लॉय करने के लिए, मेनिफ़ेस्ट लागू करें:
kubectl apply -f Google-Cloud-Containers/examples/gke/tei-deployment/cpu-config
डिप्लॉयमेंट की स्थिति पर तब तक नज़र रखें, जब तक वह 'तैयार है' स्थिति में न आ जाए:
printf "Waiting for model to load..."; until kubectl logs -l app=tei-server --tail=50 2>/dev/null | grep -q "Ready"; do printf "."; sleep 3; done; printf '\n\033[1;32m========================================\n[SUCCESS] Model is loaded and ready!\nYou can now proceed to the next step.\n========================================\033[0m\n'
tei-service Kubernetes सेवा की जांच करें:
kubectl get service tei-service
अनुमानित आउटपुट:
student@cloudshell$ kubectl get service tei-service
NAME          TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)    AGE
tei-service   ClusterIP   34.118.233.48   <none>        8080/TCP   10m
CLUSTER-IP सेवा, अनुरोधों को http://34.118.233.48:8080/embed पर इंटरनल तौर पर पूरा करती है.
kubectl port-forward का इस्तेमाल करके, मॉडल एंडपॉइंट को स्थानीय तौर पर टेस्ट करें:
kubectl port-forward service/tei-service 8080:8080
टर्मिनल में सबसे ऊपर मौजूद, + पर क्लिक करके दूसरा Cloud Shell टैब खोलें:
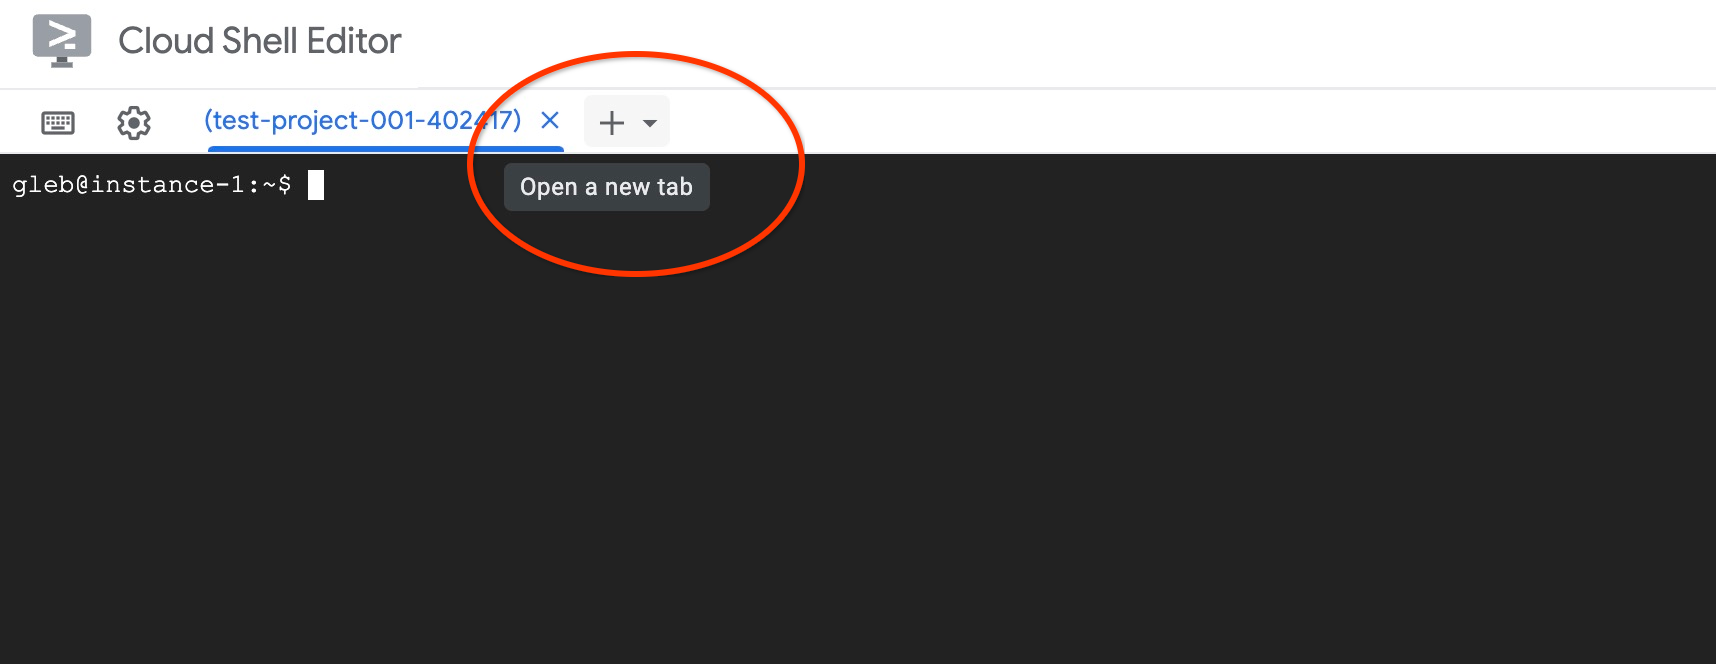
नए टैब में, curl की मदद से एम्बेडिंग जनरेट करने की सुविधा आज़माएं:
curl http://localhost:8080/embed \
  -X POST \
  -d '{"inputs":"Test"}' \
  -H 'Content-Type: application/json'
अनुमानित आउटपुट (वेक्टर ऐरे):
curl http://localhost:8080/embed \
>     -X POST \
>     -d '{"inputs":"Test"}' \
>     -H 'Content-Type: application/json'
[[-0.018975832,0.0071419072,0.06347208,0.022992613,0.014205903
...
-0.03677433,0.01636146,0.06731572]]
ctrl+c दबाकर, पहले टैब में पोर्ट-फ़ॉरवर्डिंग बंद करें.
6. AlloyDB Omni में एंबेडिंग मॉडल रजिस्टर करना
AlloyDB Omni से डिप्लॉय किए गए मॉडल का इस्तेमाल करने के लिए, एक डेटाबेस बनाएं, ट्रांसफ़ॉर्म फ़ंक्शन तय करें, और मॉडल एंडपॉइंट रजिस्टर करें.
क्लाइंट वीएम और डेटाबेस बनाना
उसी वीपीसी में एक Compute Engine वीएम इंस्टेंस बनाएं, ताकि वह क्लाइंट जंप होस्ट के तौर पर काम कर सके:
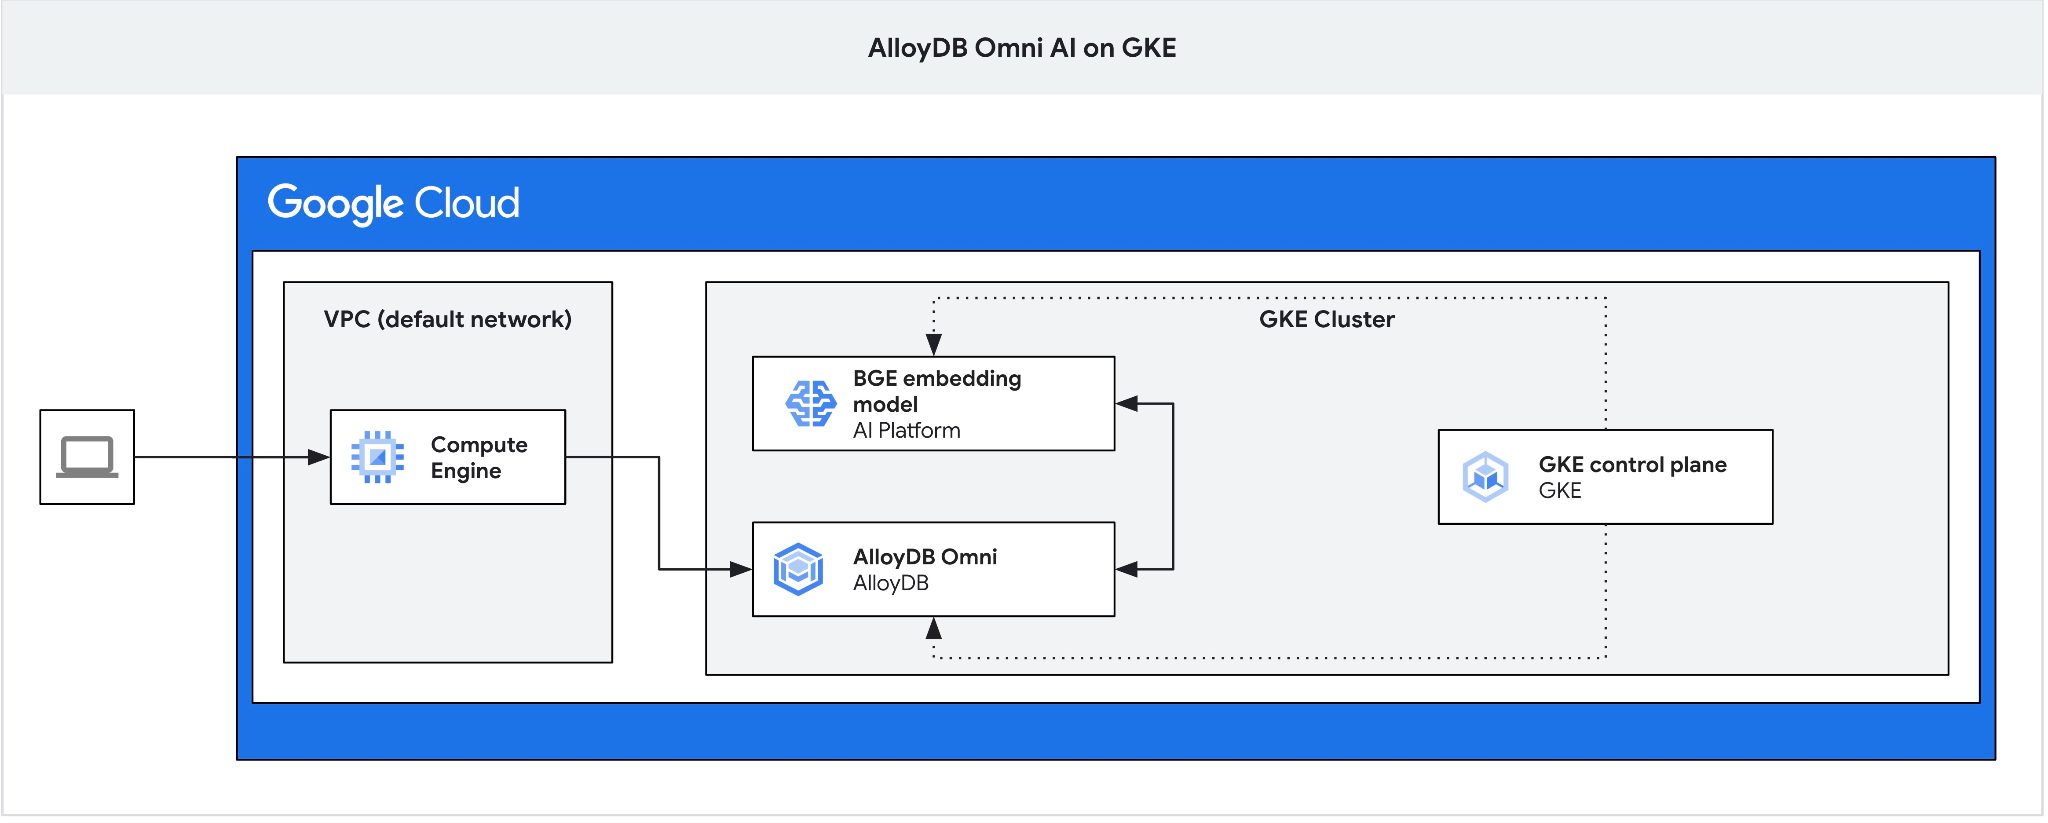
Cloud Shell में, क्लाइंट वीएम बनाएं:
export ZONE=us-central1-a
gcloud compute instances create instance-1 \
  --zone=$ZONE
AlloyDB Omni एंडपॉइंट का आईपी पता पाएं:
echo "INSTANCE_IP=$(kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default -o jsonpath='{.status.primary.endpoint}')"
अनुमानित आउटपुट:
INSTANCE_IP=10.128.0.33
INSTANCE_IP वैल्यू, AlloyDB Omni क्लस्टर के लिए इंटरनल लोड बैलेंसर का आईपी पता है. इस उदाहरण में, यह 10.131.0.33 है.
एसएसएच का इस्तेमाल करके, वीएम इंस्टेंस से कनेक्ट करें:
gcloud compute ssh instance-1 --zone=$ZONE
instance-1 पर एसएसएच सेशन में, PostgreSQL क्लाइंट इंस्टॉल करें:
sudo apt-get update && sudo apt-get install --yes postgresql-client
AlloyDB Omni लोड बैलेंसर आईपी एक्सपोर्ट करें (इसे अपने PRIMARYENDPOINT आईपी से बदलें):
export INSTANCE_IP=10.131.0.33
psql का इस्तेमाल करके, AlloyDB Omni से कनेक्ट करें (पासवर्ड VeryStrongPassword है):
psql "host=$INSTANCE_IP user=postgres sslmode=require"
psql सेशन में, demo डेटाबेस बनाएं:
CREATE DATABASE demo;
demo डेटाबेस पर स्विच करने के लिए:
\c demo
ट्रांसफ़ॉर्म फ़ंक्शन बनाना
कस्टम एम्बेडिंग एंडपॉइंट के लिए, इनपुट और आउटपुट ट्रांसफ़ॉर्म फ़ंक्शन की ज़रूरत होती है. इनकी मदद से, AlloyDB Omni और मॉडल एपीआई के बीच डेटा फ़ॉर्मैट को अडैप्ट किया जा सकता है.
इनपुट ट्रांसफ़ॉर्म फ़ंक्शन बनाएं:
CREATE OR REPLACE FUNCTION tei_text_input_transform(model_id VARCHAR(100), input_text TEXT)
RETURNS JSON
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_input JSON;
BEGIN
  SELECT json_build_object('inputs', input_text, 'truncate', true)::JSON INTO transformed_input;
  RETURN transformed_input;
END;
$$;
अनुमानित आउटपुट:
demo=# CREATE OR REPLACE FUNCTION tei_text_input_transform(model_id VARCHAR(100), input_text TEXT)
RETURNS JSON
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_input JSON;
BEGIN
  SELECT json_build_object('inputs', input_text, 'truncate', true)::JSON INTO transformed_input;
  RETURN transformed_input;
END;
$$;
CREATE FUNCTION
demo=#
वेक्टर ऐरे रिस्पॉन्स को पार्स करने के लिए, आउटपुट ट्रांसफ़ॉर्म फ़ंक्शन बनाएं:
CREATE OR REPLACE FUNCTION tei_text_output_transform(model_id VARCHAR(100), response_json JSON)
RETURNS REAL[]
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_output REAL[];
BEGIN
  SELECT ARRAY(SELECT json_array_elements_text(response_json->0)) INTO transformed_output;
  RETURN transformed_output;
END;
$$;
अनुमानित आउटपुट:
demo=# CREATE OR REPLACE FUNCTION tei_text_output_transform(model_id VARCHAR(100), response_json JSON)
RETURNS REAL[]
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_output REAL[];
BEGIN
  SELECT ARRAY(SELECT json_array_elements_text(response_json->0)) INTO transformed_output;
  RETURN transformed_output;
END;
$$;
CREATE FUNCTION
demo=#
मॉडल रजिस्टर करना
google_ml.create_model प्रक्रिया का इस्तेमाल करके, मॉडल को AlloyDB Omni में रजिस्टर करें. अनुरोधों को Kubernetes क्लस्टर सेवा पर रूट करने के लिए, http://tei-service:8080/embed को model_request_url के तौर पर सेट करें:
CALL
  google_ml.create_model(
    model_id => 'embeddinggemma',
    model_request_url => 'http://tei-service:8080/embed',
    model_provider => 'custom',
    model_type => 'text_embedding',
    model_in_transform_fn => 'tei_text_input_transform',
    model_out_transform_fn => 'tei_text_output_transform');
अनुमानित आउटपुट:
demo=# CALL
  google_ml.create_model(
    model_id => 'embeddinggemma',
    model_request_url => 'http://tei-service:8080/embed',
    model_provider => 'custom',
    model_type => 'text_embedding',
    model_in_transform_fn => 'tei_text_input_transform',
    model_out_transform_fn => 'tei_text_output_transform');
CALL
demo=#
रजिस्टर किए गए मॉडल को एसक्यूएल क्वेरी के सैंपल के साथ टेस्ट करें:
SELECT google_ml.embedding('embeddinggemma', 'What is AlloyDB Omni?');
यह फ़ंक्शन, GKE पर चल रहे स्थानीय EmbeddingGemma मॉडल से जनरेट किए गए, वास्तविक संख्याओं के ऐरे का प्रतिनिधित्व दिखाता है.
psql सेशन के प्रॉम्प्ट पर वापस जाने के लिए, q दबाएं.
psql सेशन से बाहर निकलने के लिए:
\q
7. सैंपल डेटा की मदद से मॉडल की जांच करना
डेटा का नमूना लोड करना
इस ट्यूटोरियल में, वेक्टर सिमिलैरिटी सर्च दिखाने के लिए, Cymbal के खुदरा डेटासेट का इस्तेमाल किया गया है. AlloyDB Omni में डेटा इंपोर्ट करने के लिए, Google Cloud SDK और PostgreSQL क्लाइंट का इस्तेमाल किया जाएगा.
एसएसएच सेशन में, instance-1 डेमो डेटाबेस से कनेक्ट करें और vector एक्सटेंशन चालू करें:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
psql सेशन में:
CREATE EXTENSION IF NOT EXISTS vector;
psql सेशन से बाहर निकलें:
\q
demo डेटाबेस में टेबल बनाने के लिए, स्कीमा डाउनलोड करें और उसे लागू करें:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_demo_schema.sql |psql "host=$INSTANCE_IP user=postgres dbname=demo"
अनुमानित आउटपुट:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_demo_schema.sql |psql "host=$INSTANCE_IP user=postgres dbname=demo"
Password for user postgres:
SET
SET
SET
SET
SET
 set_config
------------

(1 row)

SET
SET
SET
SET
SET
SET
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE SEQUENCE
ALTER TABLE
ALTER SEQUENCE
ALTER TABLE
ALTER TABLE
ALTER TABLE
student@cloudshell:~$
बनाई गई टेबल की पुष्टि करें:
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\dt+"
अनुमानित आउटपुट:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\dt+"
Password for user postgres:
                                           List of relations
 Schema |       Name       | Type  |  Owner   | Persistence | Access method |    Size    | Description
--------+------------------+-------+----------+-------------+---------------+------------+-------------
 public | cymbal_embedding | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_inventory | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_products  | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_stores    | table | postgres | permanent   | heap          | 8192 bytes |
(4 rows)
cymbal_products टेबल में डेटा लोड करने के लिए:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_products.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_products from stdin csv header"
अनुमानित आउटपुट:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_products.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_products from stdin csv header"
COPY 941
student@cloudshell:~$
यहां cymbal_products टेबल की कुछ लाइनों का सैंपल दिया गया है.
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT uniq_id,left(product_name,30),left(product_description,50),sale_price FROM cymbal_products limit 3"
अनुमानित आउटपुट:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT uniq_id,left(product_name,30),left(product_description,50),sale_price FROM cymbal_products limit 3"
Password for user postgres:
             uniq_id              |              left              |                        left                        | sale_price
----------------------------------+--------------------------------+----------------------------------------------------+------------
 a73d5f754f225ecb9fdc64232a57bc37 | Laundry Tub Strainer Cup       |   Laundry tub strainer cup Chrome For 1-.50, drain |      11.74
 41b8993891aa7d39352f092ace8f3a86 | LED Starry Star Night Light La |  LED Starry Star Night Light Laser Projector 3D Oc |      46.97
 ed4a5c1b02990a1bebec908d416fe801 | Surya Horizon HRZ-1060 Area Ru |  The 100% polypropylene construction of the Surya  |       77.4
(3 rows)
student@cloudshell:~$
cymbal_inventory टेबल में डेटा लोड करने के लिए:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_inventory.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_inventory from stdin csv header"
अनुमानित आउटपुट:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_inventory.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_inventory from stdin csv header"
Password for user postgres:
COPY 263861
student@cloudshell:~$
यहां cymbal_inventory टेबल की कुछ लाइनों का सैंपल दिया गया है.
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT * FROM cymbal_inventory LIMIT 3"
आउटपुट:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT * FROM cymbal_inventory LIMIT 3"
Password for user postgres:
 store_id |             uniq_id              | inventory
----------+----------------------------------+-----------
     1583 | adc4964a6138d1148b1d98c557546695 |         5
     1490 | adc4964a6138d1148b1d98c557546695 |         4
     1492 | adc4964a6138d1148b1d98c557546695 |         3
(3 rows)
student@cloudshell:~$
cymbal_stores टेबल में डेटा लोड करने के लिए:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_stores.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_stores from stdin csv header"
अनुमानित कंसोल आउटपुट:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_stores.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_stores from stdin csv header"
Password for user postgres:
COPY 4654
student@cloudshell:~$
यहां cymbal_stores टेबल की कुछ लाइनों का सैंपल दिया गया है.
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT store_id, name, zip_code FROM cymbal_stores limit 3"
आउटपुट:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT store_id, name, zip_code FROM cymbal_stores limit 3"
Password for user postgres:
 store_id |       name        | zip_code
----------+-------------------+----------
     1990 | Mayaguez Store    |      680
     2267 | Ware Supercenter  |     1082
     4359 | Ponce Supercenter |      780
(3 rows)
student@cloudshell:~$
एम्बेडिंग बनाना
psql का इस्तेमाल करके डेमो डेटाबेस से कनेक्ट करें. साथ ही, cymbal_products टेबल में बताए गए प्रॉडक्ट के लिए एम्बेडिंग बनाएं. ये एम्बेडिंग, प्रॉडक्ट के ब्यौरे के आधार पर बनाई जाएंगी.
डेमो डेटाबेस से कनेक्ट करें:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
प्रॉडक्ट की जानकारी के लिए जनरेट किए गए टेक्स्ट एम्बेडिंग को सेव करने के लिए, embedding टाइप के vector कॉलम का इस्तेमाल करें.
क्वेरी के समय की जानकारी देने की सुविधा चालू करें:
\timing
हर प्रॉडक्ट के ब्यौरे के लिए एम्बेडिंग जनरेट करें और उन्हें cymbal_embedding टेबल में सेव करें:
INSERT INTO cymbal_embedding (uniq_id, embedding)
SELECT uniq_id, google_ml.embedding('embeddinggemma', product_description)::vector
FROM cymbal_products;
अनुमानित आउटपुट:
demo=# INSERT INTO cymbal_embedding(uniq_id,embedding)  SELECT uniq_id, google_ml.embedding('embeddinggemma',product_description)::vector FROM cymbal_products;
INSERT 0 941
Time: 497878.136 ms (08:17.878)
demo=#
सिमैंटिक सर्च क्वेरी चलाना
psql सेशन में, कोसाइन दूरी (<=>) का इस्तेमाल करके, "What kind of fruit trees grow well here?" सवाल से मिलते-जुलते टॉप पांच प्रॉडक्ट ढूंढें:
SELECT
    cp.product_name,
    left(cp.product_description, 80) AS description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
अनुमानित आउटपुट:
demo=# SELECT
        cp.product_name,
        left(cp.product_description,80) as description,
        cp.sale_price,
        cs.zip_code,
        (ce.embedding <=> google_ml.embedding('embeddinggemma','What kind of fruit trees grow well here?')::vector) as distance
FROM
        cymbal_products cp
JOIN cymbal_embedding ce on ce.uniq_id=cp.uniq_id
JOIN cymbal_inventory ci on ci.uniq_id=cp.uniq_id
JOIN cymbal_stores cs on cs.store_id=ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
     product_name      |                                   description                                    | sale_price | zip_code |      distance
-----------------------+----------------------------------------------------------------------------------+------------+----------+--------------------
 Cherry Tree           | This is a beautiful cherry tree that will produce delicious cherries. It is an d |      75.00 |    93230 | 0.5210549378080666
 California Lilac      | This is a beautiful lilac tree that can grow to be over 10 feet tall. It is an d |       5.00 |    93230 | 0.5639421771781971
 Toyon                 | This is a beautiful toyon tree that can grow to be over 20 feet tall. It is an e |      10.00 |    93230 | 0.5670010914504852
 Rose Bush             | This is a beautiful rose bush that will produce fragrant roses. It is a perennia |      50.00 |    93230 | 0.5731542622882957
 California Peppertree | This is a beautiful peppertree that can grow to be over 30 feet tall. It is an e |      25.00 |    93230 | 0.5750934653011995
(5 rows)

Time: 83.610 ms
demo=#
क्वेरी को पूरा होने में 83 मि॰से॰ लगे. इसने cymbal_products टेबल से, अनुरोध से मेल खाने वाले और स्टोर 1583 में उपलब्ध इन्वेंट्री वाले ट्री की सूची दिखाई.
ANN इंडेक्स बनाना
डेटा सेट छोटा होने पर, सटीक खोज का इस्तेमाल करना आसान होता है. इससे सभी एम्बेडिंग स्कैन हो जाती हैं. हालांकि, डेटा बढ़ने पर लोड होने और जवाब मिलने में लगने वाला समय भी बढ़ जाता है. परफ़ॉर्मेंस को बेहतर बनाने के लिए, अपने एम्बेडिंग डेटा पर इंडेक्स बनाए जा सकते हैं. वेक्टर डेटा के लिए, Google ScaNN इंडेक्स का इस्तेमाल करके ऐसा करने का तरीका यहां बताया गया है.
अगर आपका कनेक्शन टूट गया है, तो डेमो डेटाबेस से फिर से कनेक्ट करें:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
alloydb_scann एक्सटेंशन चालू करें:
CREATE EXTENSION IF NOT EXISTS alloydb_scann;
embedding कॉलम पर ScaNN इंडेक्स बनाएं:
CREATE INDEX cymbal_products_embeddings_scann ON cymbal_embedding
  USING scann (embedding cosine)
  WITH (num_leaves=10, max_num_levels = 1);
एक्ज़ीक्यूशन की परफ़ॉर्मेंस की तुलना करने के लिए, सिमैंटिक सर्च क्वेरी को फिर से चलाएं:
SELECT
    cp.product_name,
    left(cp.product_description, 80) AS description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
अनुमानित आउटपुट:
demo=# SELECT
    cp.product_name,
    left(cp.product_description,80) as description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
     product_name      |                                   description                                    | sale_price | zip_code |      distance
-----------------------+----------------------------------------------------------------------------------+------------+----------+--------------------
 Cherry Tree           | This is a beautiful cherry tree that will produce delicious cherries. It is an d |      75.00 |    93230 | 0.5210549378080666
 California Lilac      | This is a beautiful lilac tree that can grow to be over 10 feet tall. It is an d |       5.00 |    93230 | 0.5639421771781971
 Toyon                 | This is a beautiful toyon tree that can grow to be over 20 feet tall. It is an e |      10.00 |    93230 | 0.5670010914504852
 Rose Bush             | This is a beautiful rose bush that will produce fragrant roses. It is a perennia |      50.00 |    93230 | 0.5731542622882957
 California Peppertree | This is a beautiful peppertree that can grow to be over 30 feet tall. It is an e |      25.00 |    93230 | 0.5750934653011995
(5 rows)

Time: 64.783 ms
क्वेरी को पूरा होने में लगने वाला समय थोड़ा कम हो गया है. बड़े डेटासेट के साथ, यह फ़ायदा ज़्यादा दिखेगा. इंडेक्स के बिना मिले डेटा और इंडेक्स के साथ मिले डेटा में कोई अंतर नहीं होना चाहिए या दोनों डेटा एक-दूसरे से बहुत मिलते-जुलते होने चाहिए.
अन्य क्वेरी आज़माएं और दस्तावेज़ में, वेक्टर इंडेक्स को ऑप्टिमाइज़ करने के बारे में ज़्यादा पढ़ें.
psql सेशन से बाहर निकलने के लिए:
\q
instance-1 ssh सेशन से डिस्कनेक्ट करके, Google Cloud Shell पर वापस जाएं. इसके लिए, CTRL+D दबाएं या exit टाइप करें.
8. vLLM की मदद से Gemma को डिप्लॉय करना
Gemma के लिए नोड पूल जोड़ना
सबसे पहले, देखें कि आपके इलाके में कौनसे नोड टाइप उपलब्ध हैं:
export LOCATION=us-central1-a
gcloud compute accelerator-types list --filter="zone:${LOCATION}"
आपको उपलब्ध ऐक्सलरेटर टाइप की सूची दिखेगी. इसमें nvidia-l4 ऐक्सलरेटर भी शामिल होगा. अब nvidia-l4 ऐक्सलरेटर टाइप वाला नोड पूल बनाएं:
export PROJECT_ID=$(gcloud config get project)
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
gcloud container node-pools create gpupool \
    --accelerator type=nvidia-l4,count=1,gpu-driver-version=latest \
    --project=${PROJECT_ID} \
    --location=${LOCATION} \
    --node-locations=${LOCATION}-a \
    --cluster=${CLUSTER_NAME} \
    --machine-type=g2-standard-8 \
    --num-nodes=1
vLLM का इस्तेमाल करके, Google Gemini 4 12B मॉडल के लिए डिप्लॉयमेंट मेनिफ़ेस्ट बनाएं:
cat << 'EOF' > gemma-12b-gpu-vllm-deployment.yaml
apiVersion: apps/v1
kind: Deployment
metadata:
  name: gemma-12b-gpu-vllm-deployment
spec:
  replicas: 1
  selector:
    matchLabels:
      app: gemma-12b-gpu-vllm
  template:
    metadata:
      labels:
        app: gemma-12b-gpu-vllm
        ai.gke.io/model: gemma-4-12b-it
        ai.gke.io/inference-server: vllm
        examples.ai.gke.io/source: user-guide
    spec:
      containers:
      - name: inference-server
        image: us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:latest
        resources:
          requests:
            cpu: "4"
            memory: "16Gi"
            ephemeral-storage: "30Gi"
            nvidia.com/gpu: "1"
          limits:
            cpu: "8"
            memory: "24Gi"
            ephemeral-storage: "30Gi"
            nvidia.com/gpu: "1"
        command: ["python3", "-m", "vllm.entrypoints.api_server"]
        args:
          - --model=$(MODEL_ID)
          - --host=0.0.0.0
          - --port=8000
          - --tensor-parallel-size=1
          - --enable-log-requests
          - --enable-chunked-prefill
          - --enable-prefix-caching
          - --enable-auto-tool-choice
          - --generation-config=auto
          - --tool-call-parser=gemma4
          - --dtype=bfloat16
          - --max-num-seqs=16
          - --max-model-len=32768
          - --gpu-memory-utilization=0.95
          - --reasoning-parser=gemma4
          - --trust-remote-code
          - --quantization=fp8
        env:
        - name: LD_LIBRARY_PATH
          value: ${LD_LIBRARY_PATH}:/usr/local/nvidia/lib64
        - name: MODEL_ID
          value: google/gemma-4-12b-it
        - name: HF_TOKEN
          valueFrom:
            secretKeyRef:
              name: hf-secret
              key: hf_api_token
        volumeMounts:
        - mountPath: /dev/shm
          name: dshm
      volumes:
      - name: dshm
        emptyDir:
            medium: Memory
      nodeSelector:
        cloud.google.com/gke-accelerator: nvidia-l4
        cloud.google.com/gke-gpu-driver-version: latest
---
apiVersion: v1
kind: Service
metadata:
  name: gemma-12b-gpu-vllm-service
spec:
  selector:
    app: gemma-12b-gpu-vllm
  type: ClusterIP
  ports:
    - protocol: TCP
      port: 8000
      targetPort: 8000
EOF
सेव किए गए � deployment को लागू करने के लिए:gemma-12b-gpu-vllm-deployment.yaml
kubectl apply -f gemma-12b-gpu-vllm-deployment.yaml
अनुमानित आउटपुट:
$ kubectl apply -f gemma-12b-gpu-vllm-deployment.yaml
deployment.apps/gemma-12b-gpu-vllm-deployment created
service/gemma-12b-gpu-vllm-service created
डप्लॉयमेंट पूरा होने और मॉडल लोड होने तक इंतज़ार करें. इसमें कुछ मिनट लग सकते हैं.
printf "Waiting for model to load..."; until kubectl logs -l app=gemma-12b-gpu-vllm --tail=50 2>/dev/null | grep -q "Application startup complete"; do printf "."; sleep 3; done; printf '\n\033[1;32m========================================\n[SUCCESS] Model is loaded and ready!\nYou can now proceed to the next step.\n========================================\033[0m\n'
अनुमानित आउटपुट:
Waiting for model to load...
========================================
[SUCCESS] Model is loaded and ready!
You can now proceed to the next step.
========================================
मॉडल को टेस्ट करें. मॉडल को ऐक्सेस करने के लिए, पोर्ट फ़ॉरवर्डिंग की सुविधा चालू करें:
kubectl port-forward svc/gemma-12b-gpu-vllm-service 8090:8000
किसी दूसरी टर्मिनल विंडो में, मॉडल को प्रॉम्प्ट भेजने के लिए curl का इस्तेमाल करें:
curl http://localhost:8090/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "messages": [
      {"role": "system", "content": "You are a helpful assistant running on GKE."},
      {"role": "user", "content": "What is AlloyDB Omni."}
    ],
    "temperature": 0.7
  }' | jq -r '.choices[0].message.content'
अनुमानित आउटपुट:
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100  3957  100  3761  100   196     85      4  0:00:49  0:00:43  0:00:06   830
**AlloyDB Omni** is a fully managed, PostgreSQL-compatible database engine from Google Cloud that can be run **on-premises, in other clouds, or in your own data centers.**

To understand it simply: It allows you to run the high-performance, enterprise-grade capabilities of Google's **AlloyDB** (a cloud-native database) on your own infrastructure.

Here is a breakdown of what makes it significant:

### 1. The "Best of Both Worlds" Architecture
Normally, you have to choose between:
*   **Managed Cloud Databases:** Easy to scale and manage, but you are locked into the cloud provider's infrastructure.
*   **Self-Managed Databases:** You have full control over the hardware/location, but you are responsible for scaling, patching, and high availability.

**AlloyDB Omni** bridges this gap. It provides the advanced features of a cloud-native database (like intelligent indexing, high availability, and massive scalability) while allowing you to run it anywhere.
अगर पहले टर्मिनल में पोर्ट फ़ॉरवर्डिंग अब भी चल रही है, तो Ctrl+C दबाकर उसे बंद करें.
9. AlloyDB Omni में Gemma 4 मॉडल रजिस्टर करना
google_ml.create_model प्रक्रिया का इस्तेमाल करके, Gemma 12B मॉडल को AlloyDB Omni में रजिस्टर करें. अनुरोधों को Kubernetes क्लस्टर सेवा पर रूट करने के लिए, http://gemma-12b-gpu-vllm-service:8000/v1/chat/completions को model_request_url के तौर पर सेट करें:
AlloyDB Omni एंडपॉइंट का आईपी पता पाएं:
echo "INSTANCE_IP=$(kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default -o jsonpath='{.status.primary.endpoint}')"
एसएसएच का इस्तेमाल करके, वीएम इंस्टेंस से कनेक्ट करें:
export ZONE=us-central1-a
gcloud compute ssh instance-1 --zone=$ZONE
वीएम से कनेक्ट करने के बाद, पिछले चरण से INSTANCE_IP वैरिएबल एक्सपोर्ट करें. उदाहरण के तौर पर, 10.128.0.33 वैल्यू दी गई है. इसे अपने आईपी से बदलें:
export INSTANCE_IP=10.128.0.33
AlloyDB का पासवर्ड एक्सपोर्ट करें:
export PGPASSWORD=VeryStrongPassword
demo डेटाबेस से कनेक्ट करें:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
psql सेशन में मॉडल रजिस्टर करें:
CALL
  google_ml.create_model(
    model_id => 'gemma-12b-gpu',
    model_request_url => 'http://gemma-12b-gpu-vllm-service:8000/v1/chat/completions',
    model_provider => 'custom',
    model_type => 'llm');
एसक्यूएल क्वेरी के सैंपल की मदद से मॉडल को टेस्ट करें:
SELECT google_ml.predict_row(
  model_id => 'gemma-12b-gpu',
  request_body => json_build_object(
    'messages', json_build_array(
      json_build_object('role', 'user', 'content', 'What is AlloyDB Omni?'))))->'choices'->0->'message'->'content';
नतीजों की विंडो से बाहर निकलने और वापस psql प्रॉम्प्ट पर जाने के लिए, q दबाएं
AlloyDB Omni में, वेक्टर सर्च को LLM RAG के साथ जोड़ना
एलएलएम के साथ आरएजी (Retrieval-Augmented Generation) को दिखाने के लिए, एलएलएम के अनुरोध के साथ वेक्टर सर्च का इस्तेमाल करें.
plsql में एसक्यूएल क्वेरी चलाएं:
WITH trees AS (
SELECT
        cp.product_name,
        cp.product_description AS description,
        cp.sale_price,
        cs.zip_code,
        cp.uniq_id AS product_id
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
        ci.inventory>0
        AND cs.store_id = 1583
ORDER BY
        (ce.embedding <=> embedding('embeddinggemma',
        'What kind of fruit trees grow well here?')::vector) ASC
LIMIT 1),
prompt AS (
SELECT
        'You are a friendly advisor helping to find a product based on the customer''s needs.
Based on the client request we have loaded a list of products closely related to search.
The list in JSON format with list of values like {"product_name":"name","product_description":"some description","sale_price":10}
Here is the list of products:' || json_agg(trees) || 'The customer asked "What kind of fruit trees grow well here?"
You should give information about the product, price and some supplemental information' AS prompt_text
FROM
        trees),
response AS (
SELECT
        google_ml.predict_row(
          model_id =>'gemma-12b-gpu',
          request_body => json_build_object(
            'messages', json_build_array(
              json_build_object('role', 'user', 'content',prompt_text)
            )))->'choices'->0->'message'->'content' AS resp
FROM
        prompt)
SELECT
REPLACE(resp::text, '\n', CHR(10))
FROM
        response;
अनुमानित आउटपुट:
----------------------------------------------------------------------------------------------------------------------------------------------
 "Hello there! I'd be happy to help you find the perfect tree for your garden.                                                               +
                                                                                                                                             +
 Based on your location, we have a wonderful option that would grow beautifully in your area:                                                +
                                                                                                                                             +
 **Cherry Tree**                                                                                                                             +
 *   **Price:** $75.00                                                                                                                       +
 *   **Description:** This is a stunning deciduous tree that not only provides a beautiful landscape but also produces delicious cherries.   +
 *   **Supplemental Information:**                                                                                                           +
     *   **Growth:** It grows to about 15 feet tall.                                                                                         +
     *   **Appearance:** You can look forward to dark green leaves in the summer that transform into a vibrant red in the fall.              +
     *   **Benefits:** It's a great choice if you're looking for both fruit and extra shade or privacy in your yard.                         +
     *   **Care Tips:** It performs best in a cool, moist climate with sandy soil. Since you are in a suitable zone, it should thrive nicely!+
                                                                                                                                             +
 Would you like more details on how to plant this, or would you like to proceed with an order?"
(1 row)
वेक्टर सर्च के नतीजों से, एलएलएम को प्रॉम्प्ट के बारे में ज़्यादा जानकारी मिलती है.
अन्य क्वेरी आज़माएं और आरएजी पैटर्न के साथ एक्सपेरिमेंट करें. पेश किए गए आर्किटेक्चर का फ़ायदा यह है कि यह पूरी तरह से आत्मनिर्भर है. डेटा को आपके क्लस्टर से बाहर नहीं भेजा जाता है. साथ ही, इसे पूरी तरह से अलग किए गए एनवायरमेंट में चलाया जा सकता है.
psql सेशन से बाहर निकलने के लिए:
\q
वीएम से एसएसएच सेशन को डिसकनेक्ट करने के लिए:
exit
यह न भूलें कि AlloyDB Omni में ज़्यादा सुविधाएं और लैब हैं.
10. स्टोरेज में जगह बनाएं
अपने Google Cloud खाते पर लगने वाले मौजूदा शुल्क से बचने के लिए, इस कोडलैब में बनाए गए संसाधनों को मिटाएं.
GKE क्लस्टर मिटाना
Cloud Shell में, GKE क्लस्टर मिटाएं:
export PROJECT_ID=$(gcloud config get-value project)
export LOCATION=us-central1
export CLUSTER_NAME=alloydb-ai-gke
gcloud container clusters delete ${CLUSTER_NAME} \
  --project=${PROJECT_ID} \
  --region=${LOCATION}
अनुमानित आउटपुट:
student@cloudshell:~$ gcloud container clusters delete ${CLUSTER_NAME} \
>   --project=${PROJECT_ID} \
>   --region=${LOCATION}
The following clusters will be deleted.
 - [alloydb-ai-gke] in [us-central1]

Do you want to continue (Y/n)?  Y

Deleting cluster alloydb-ai-gke...done.
Deleted
क्लाइंट वीएम मिटाएं
Cloud Shell में, Compute Engine इंस्टेंस मिटाएं:
export PROJECT_ID=$(gcloud config get-value project)
export ZONE=us-central1-a
gcloud compute instances delete instance-1 \
  --project=${PROJECT_ID} \
  --zone=${ZONE}
अनुमानित आउटपुट:
student@cloudshell:~$ export PROJECT_ID=$(gcloud config get project)
export ZONE=us-central1-a
gcloud compute instances delete instance-1 \
  --project=${PROJECT_ID} \
  --zone=${ZONE}
Your active configuration is: [cloudshell-5399]
The following instances will be deleted. Any attached disks configured to be auto-deleted will be deleted unless they are attached to any other instances or the `--keep-disks` flag is given and specifies them for keeping. Deleting a disk
is irreversible and any data on the disk will be lost.
 - [instance-1] in [us-central1-a]

Do you want to continue (Y/n)?  Y

Deleted
अगर आपने इस कोडलैब के लिए कोई नया प्रोजेक्ट बनाया है, तो आपके पास पूरे प्रोजेक्ट को Google Cloud Resource Manager में जाकर मिटाने का विकल्प होता है.
11. बधाई हो
कोडलैब पूरा करने के लिए बधाई!
आपने क्या कवर किया
- GKE क्लस्टर पर AlloyDB Omni को डिप्लॉय करने का तरीका
- AlloyDB Omni से कनेक्ट करने का तरीका
- AlloyDB Omni में डेटा लोड करने का तरीका
- GKE पर एआई मॉडल (एलएलएम और एंबेडिंग) डिप्लॉय करने का तरीका
- AlloyDB Omni में एआई मॉडल रजिस्टर करने का तरीका
- सिमैंटिक सर्च के लिए एम्बेडिंग जनरेट करने का तरीका
- AlloyDB Omni में सिमैंटिक सर्च क्वेरी चलाने का तरीका
- AlloyDB Omni में वेक्टर इंडेक्स बनाने और उनका इस्तेमाल करने का तरीका
AlloyDB Omni में एआई का इस्तेमाल करने के बारे में ज़्यादा जानने के लिए, दस्तावेज़ पढ़ें.
सर्वे
आउटपुट: