
1. 簡介
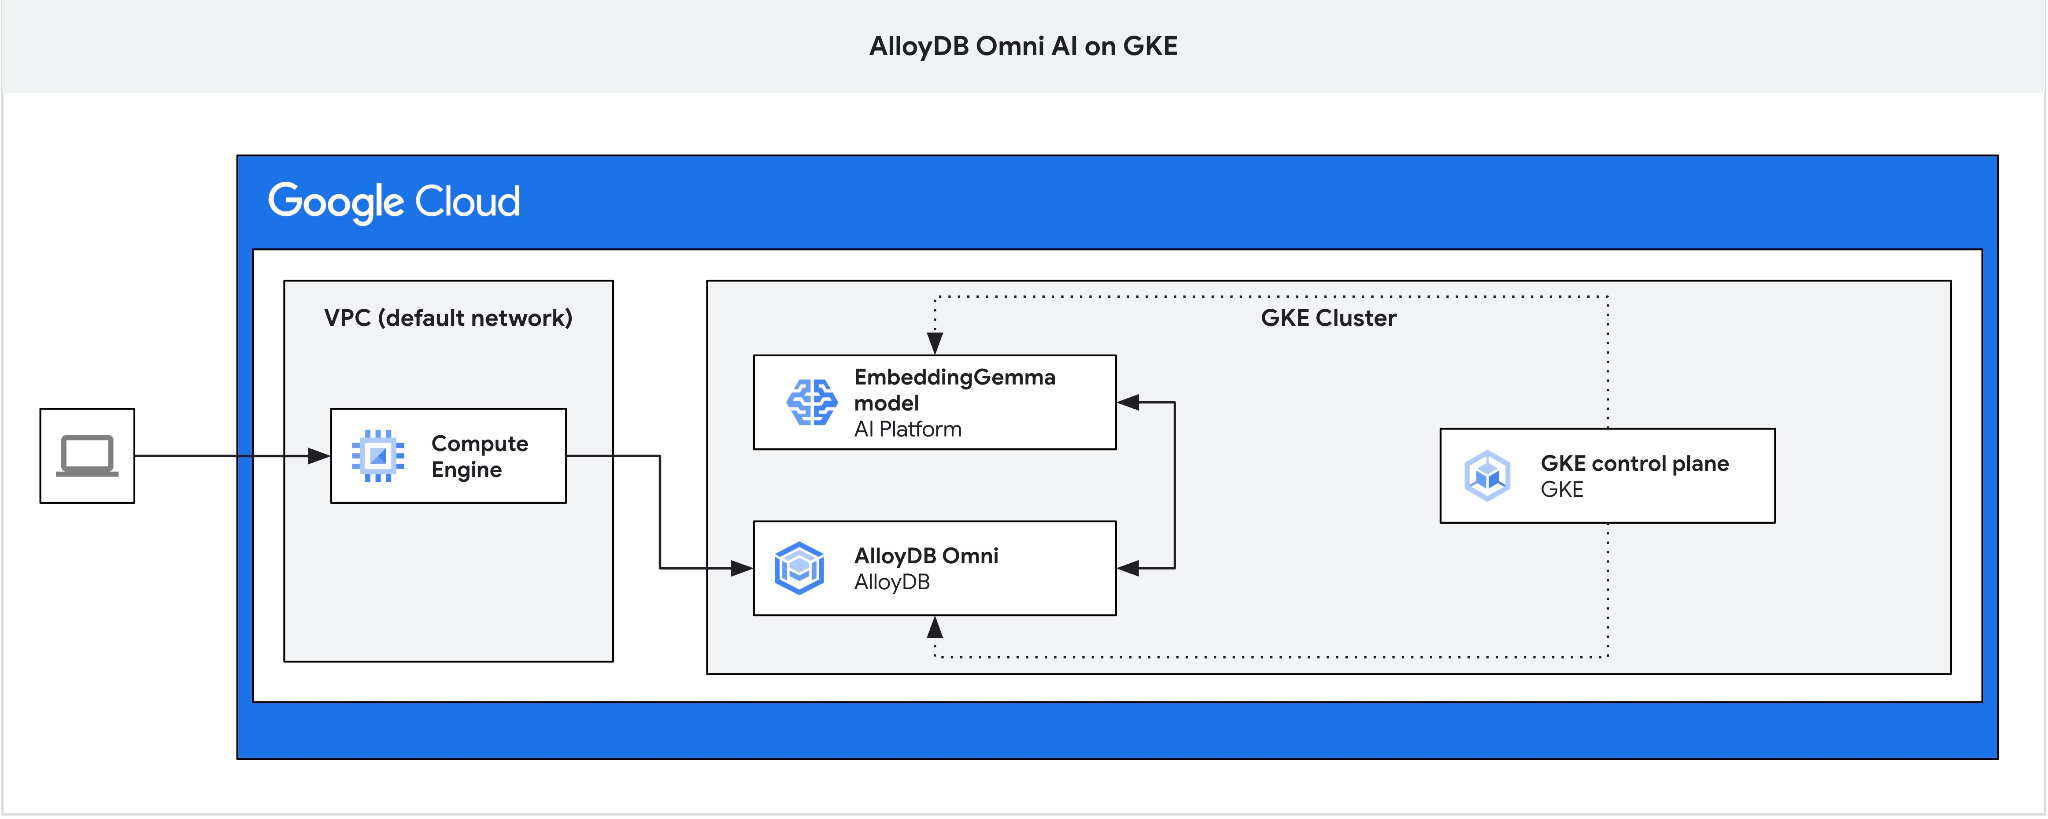
在本程式碼實驗室中,您將瞭解如何在 Google Kubernetes Engine (GKE) 部署 AlloyDB Omni,並搭配使用 EmbeddingGemma 和 Gemma 4 等開放式模型,進行嵌入和預測。在同一個叢集執行資料庫和模型,可減少網路延遲,並避免依賴第三方服務。此外,由於資料不會離開您的環境,因此也有助於滿足法規遵循和資料落地規定。
必要條件
- 對 Google Cloud 和 Google Cloud 控制台有基本瞭解
- 具備 Kubernetes 和 GKE 的基本知識
- 熟悉指令列介面和 Google Cloud Shell
課程內容
- 如何在 GKE 叢集部署 AlloyDB Omni
- 如何連線至 AlloyDB Omni
- 如何將資料載入 AlloyDB Omni
- 如何將 AI 模型 (嵌入和 LLM) 部署至 GKE
- 如何在 AlloyDB Omni 註冊 AI 模型
- 如何生成語意搜尋的嵌入
- 如何在 AlloyDB Omni 執行語意搜尋查詢
- 如何在 AlloyDB Omni 建立及使用向量索引
軟硬體需求
- Google Cloud 帳戶和 Google Cloud 專案
- 網路瀏覽器,例如 Chrome
2. 設定和需求
專案設定
- 登入 Google Cloud 控制台。如果您還沒有 Gmail 或 Google Workspace 帳戶,請建立帳戶。請改用個人帳戶,而非公司或學校帳戶。
- 建立新專案或選取現有專案。在 Google Cloud 控制台標頭中,依序點選「選取專案」和「新增專案」。
在「Select a project」(選取專案) 視窗中,按一下「New Project」(新增專案),開啟專案建立對話方塊。
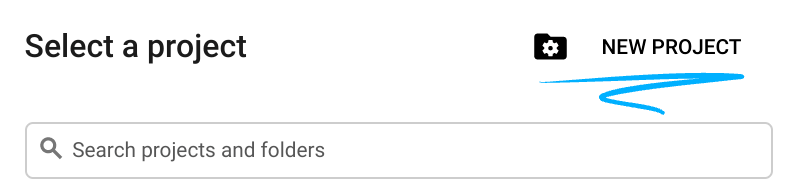
在對話方塊中輸入「專案名稱」,然後選取機構或位置。
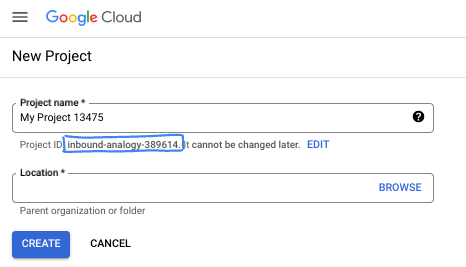
- 「專案名稱」是這項專案參與者的顯示名稱。Google API 不會使用專案名稱,您隨時可以變更。
- 專案 ID 在所有 Google Cloud 專案中都是不重複的,且無法變更 (設定後即無法變更)。Google Cloud 控制台會自動產生專屬 ID,您也可以自行提供。在本程式碼實驗室中,您會使用
- 專案編號是部分 API 使用的第三個 ID。詳情請參閱 Resource Manager 說明文件。
啟用計費功能
如果您使用 Google Cloud 抵免額設定計費功能,可以略過這個步驟。
如要設定個人帳單帳戶,請在 Google Cloud 控制台啟用計費功能。
- 完成本實驗室所需的 Google Cloud 資源費用不到 $5 美元。
- 請按照本實驗室結尾的清除步驟刪除資源,以免產生額外費用。
- 新使用者可享有價值$300 美元的免費試用。
啟動 Cloud Shell
在本程式碼實驗室中,您將使用 Google Cloud Shell,這是在雲端執行的指令列環境。
在 Google Cloud 控制台右上方的工具列,點選「啟用 Cloud Shell」圖示:
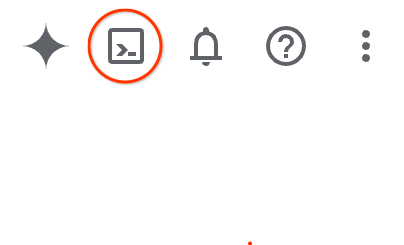
或者,您也可以依序按下 G 和 S 鍵,或直接開啟 Google Cloud Shell。
連線後,Cloud Shell 會顯示終端機提示:
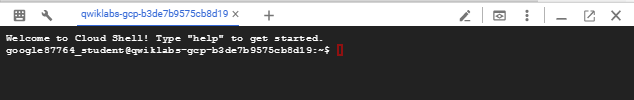
Cloud Shell 包含永久儲存空間和開發人員工具。您可以在瀏覽器中執行本程式碼實驗室的所有步驟。
3. 啟用 API
如要使用 Google Kubernetes Engine (GKE) 部署 AlloyDB Omni 和模型,請在 Google Cloud 雲端專案中啟用 Compute Engine 和 GKE API。
在 Cloud Shell 確認專案 ID 已設定完成:
PROJECT_ID=$(gcloud config get-value project)
echo $PROJECT_ID
如果未定義專案 ID,請加以設定:
export PROJECT_ID=<YOUR_PROJECT_ID>
gcloud config set project $PROJECT_ID
啟用必要的 API:
gcloud services enable compute.googleapis.com
gcloud services enable container.googleapis.com
預期輸出內容:
student@cloudshell:~ (test-project-001-402417)$ PROJECT_ID=test-project-001-402417
student@cloudshell:~ (test-project-001-402417)$ gcloud config set project test-project-001-402417
Updated property [core/project].
student@cloudshell:~ (test-project-001-402417)$ gcloud services enable compute.googleapis.com
gcloud services enable container.googleapis.com
Operation "operations/acat.p2-4470404856-1f44ebd8-894e-4356-bea7-b84165a57442" finished successfully.
如要瞭解各項已啟用的 API,請參閱說明文件。
4. 在 GKE 部署 AlloyDB Omni
如要在 GKE 部署 AlloyDB Omni,請按照 AlloyDB Omni operator 需求準備 Kubernetes 叢集。
建立 GKE 叢集
部署 Autopilot GKE 叢集,以便執行 AlloyDB Omni、運算子和監控容器。使用 Autopilot 模式可簡化部署作業,系統會自動指派 AlloyDB Omni operator、叢集和其他元件的所有資源。
選擇要部署資源的區域。選擇靠近您所在位置的區域:
export LOCATION=<your region>
設定部署作業的環境變數:
export PROJECT_ID=$(gcloud config get-value project)
export CLUSTER_NAME=alloydb-ai-gke
建立 Autopilot GKE 叢集:
gcloud container clusters create-auto ${CLUSTER_NAME} \
  --project=${PROJECT_ID} \
  --region=${LOCATION}
預期的控制台輸出內容:
student@cloudshell:~ (test-project-001-402417)$ export PROJECT_ID=$(gcloud config get project)
export CLUSTER_NAME=alloydb-ai-gke
Your active configuration is: [test-project-001-402417]
student@cloudshell:~ (test-project-001-402417)$ gcloud container clusters create-auto ${CLUSTER_NAME} \
>   --project=${PROJECT_ID} \
>   --region=${LOCATION}
Creating cluster alloydb-ai-gke in us-east4... Cluster is being health-checked.
..⠹
Creating cluster alloydb-ai-gke in us-east4... Cluster is being health-checked
(Kubernetes Control Plane is healthy)...done.
Created [https://container.googleapis.com/v1/projects/gleb-genai-002/zones/us-east4/clusters/alloydb-ai-gke].
To inspect the contents of your cluster, go to: https://console.cloud.google.com/kubernetes/workload_/gcloud/us-east4/alloydb-ai-gke?project=gleb-genai-002
kubeconfig entry generated for alloydb-ai-gke.
NAME            LOCATION  MASTER_VERSION      MASTER_IP      MACHINE_TYPE   NODE_VERSION        NUM_NODES  STATUS   STACK_TYPE
alloydb-ai-gke  us-east4  1.36.4-gke.1391002  34.145.214.51  ek-standard-8  1.36.4-gke.1391002  3          RUNNING  IPV4
準備叢集
安裝必要元件,例如 Kubernetes 的憑證控制器 cert-manager。詳情請參閱 cert-manager 安裝說明文件。
Cloud Shell 包含 Kubernetes 指令列工具 kubectl 和 helm。使用 gcloud 取得叢集憑證:
gcloud container clusters get-credentials ${CLUSTER_NAME} --region=${LOCATION}
使用 helm 安裝 cert-manager:
helm install \
  cert-manager oci://quay.io/jetstack/charts/cert-manager \
  --version v1.21.2 \
  --namespace cert-manager \
  --create-namespace \
  --set featureGates="ServerSideApply=true" \
  --set global.leaderElection.namespace=cert-manager \
  --set "extraArgs={--certificate-request-minimum-backoff-duration=15s,--certificate-request-maximum-backoff-duration=5m}" \
  --set crds.enabled=true
預期的控制台輸出內容 (已遮蓋):
student@cloudshell:~$ elm install \
>   cert-manager oci://quay.io/jetstack/charts/cert-manager \
>   --version v1.21.2 \
>   --namespace cert-manager \
>   --create-namespace \
>  --set featureGates="ServerSideApply=true" \
>  --set global.leaderElection.namespace=cert-manager \
>  --set "extraArgs={--certificate-request-minimum-backoff-duration=15s,--certificate-request-maximum-backoff-duration=5m}" \
>   --set crds.enabled=true
Pulled: quay.io/jetstack/charts/cert-manager:v1.21.2
Digest: sha256:634dce9c13b56677a2c05e2ab76c312d0be2664022d5dd05815da67e1fd5f610
I1016 12:25:06.128464   30644 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Deployment cert-manager/cert-manager-cainjector: defaulted unspecified 'cpu' resource for containers [cert-manager-cainjector] (see http://g.co/gke/autopilot-defaults)."
I1016 12:25:06.129972   30644 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Deployment cert-manager/cert-manager: defaulted unspecified 'cpu' resource for containers [cert-manager-controller] (see http://g.co/gke/autopilot-defaults)."
I1016 12:25:06.134580   30644 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Deployment cert-manager/cert-manager-webhook: defaulted unspecified 'cpu' resource for containers [cert-manager-webhook] (see http://g.co/gke/autopilot-defaults)."
I1016 12:25:06.250590   30644 warnings.go:107] "Warning: AdmissionWebhookController: mutated namespaceselector of the webhooks to enforce GKE Autopilot policies."
I1016 12:25:09.758249   30644 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Job cert-manager/cert-manager-startupapicheck: defaulted unspecified 'cpu' resource for containers [cert-manager-startupapicheck] (see http://g.co/gke/autopilot-defaults)."
NAME: cert-manager
LAST DEPLOYED: Fri Oct 16 12:24:57 2026
NAMESPACE: cert-manager
STATUS: deployed
REVISION: 1
DESCRIPTION: Install complete
TEST SUITE: None
NOTES:
cert-manager v1.21.2 has been deployed successfully!
安裝 AlloyDB Omni operator
使用 Helm 安裝 AlloyDB Omni operator。
下載並安裝 AlloyDB Omni operator chart:
helm install alloydbomni-operator oci://gcr.io/alloydb-omni/alloydbomni-operator \
--version 1.9.0 \
--create-namespace \
--namespace alloydb-omni-system \
$(helm install --help | grep -q -- '--rollback-on-failure' && echo '--rollback-on-failure' || echo '--atomic') \
--timeout 5m
預期的控制台輸出內容 (已遮蓋):
student@cloudshell:~$ helm install alloydbomni-operator oci://gcr.io/alloydb-omni/alloydbomni-operator \
> --version 1.9.0 \
> --create-namespace \
> --namespace alloydb-omni-system \
> $(helm install --help | grep -q -- '--rollback-on-failure' && echo '--rollback-on-failure' || echo '--atomic') \
> --timeout 5m

Pulled: gcr.io/alloydb-omni/alloydbomni-operator:1.9.0
Digest: sha256:4f6cc3f0c1fbe003ab7d0119afee516e5c67ec950cd2909b418e5a3f6f09d1f6
I1016 12:28:50.088533   30982 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Deployment alloydb-omni-system/fleet-controller-manager: adjusted 'cpu' resource to meet requirements for containers [fleet-manager] (see http://g.co/gke/autopilot-defaults)."
I1016 12:28:50.092917   30982 warnings.go:107] "Warning: autopilot-default-resources-mutator:Autopilot updated Deployment alloydb-omni-system/local-controller-manager: adjusted 'cpu' resource to meet requirements for containers [local-manager] (see http://g.co/gke/autopilot-defaults)."
I1016 12:28:50.229717   30982 warnings.go:107] "Warning: AdmissionWebhookController: mutated namespaceselector of the webhooks to enforce GKE Autopilot policies."
I1016 12:28:50.238578   30982 warnings.go:107] "Warning: AdmissionWebhookController: mutated namespaceselector of the webhooks to enforce GKE Autopilot policies."
NAME: alloydbomni-operator
LAST DEPLOYED: Fri Oct 16 12:28:45 2026
NAMESPACE: alloydb-omni-system
STATUS: deployed
REVISION: 1
DESCRIPTION: Install complete
TEST SUITE: None
部署資料庫叢集。
下列資訊清單會設定已啟用 googleMLExtension 的資料庫叢集和內部負載平衡器:
cat << 'EOF' > my-omni.yaml
apiVersion: v1
kind: Secret
metadata:
  name: db-pw-my-omni
type: Opaque
data:
  my-omni: "VmVyeVN0cm9uZ1Bhc3N3b3Jk"
---
apiVersion: alloydbomni.dbadmin.goog/v1
kind: DBCluster
metadata:
  name: my-omni
spec:
  databaseVersion: "18.4.0"
  primarySpec:
    adminUser:
      passwordRef:
        name: db-pw-my-omni
    features:
      googleMLExtension:
        enabled: true
    resources:
      cpu: 1
      memory: 8Gi
      disks:
      - name: DataDisk
        size: 20Gi
    dbLoadBalancerOptions:
      annotations:
        networking.gke.io/load-balancer-type: "internal"
  allowExternalIncomingTraffic: true
EOF
密碼 Secret 值是 VeryStrongPassword 的 Base64 表示法。在正式環境中,請使用 Google Secret Manager 管理密碼。詳情請參閱 Secret Manager 說明文件。
資訊清單會儲存為 my-omni.yaml。在 Cloud Shell 終端機視窗的右上角,按一下「開啟編輯器」,然後閱讀檔案。
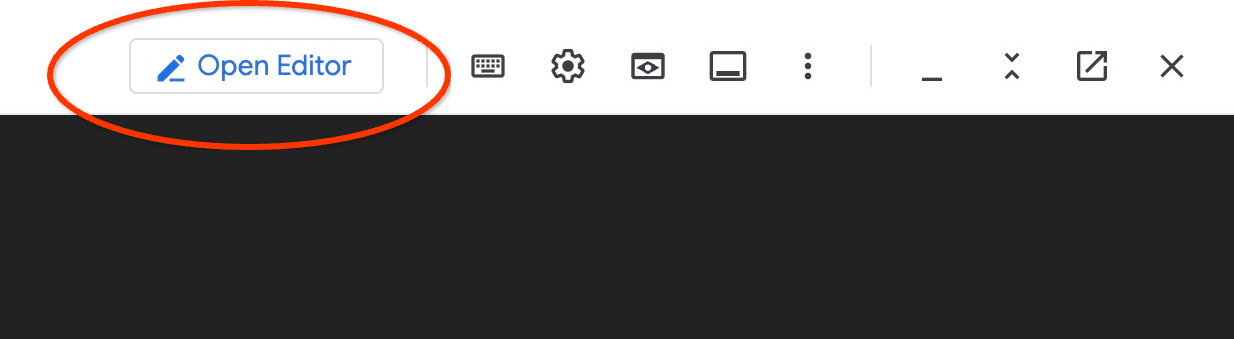
閱讀 my-omni.yaml 資訊清單後,按一下「Open Terminal」(開啟終端機),返回命令提示字元。
套用 my-omni.yaml 資訊清單:
kubectl apply -f my-omni.yaml
預期的控制台輸出內容:
secret/db-pw-my-omni created
dbcluster.alloydbomni.dbadmin.goog/my-omni created
檢查 my-omni 叢集的狀態:
kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default
部署期間,資料庫叢集會經過多個設定階段,直到進入 DBClusterReady 狀態。
預期的控制台輸出內容:
$ kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default
NAME      PRIMARYENDPOINT   PRIMARYPHASE   DBCLUSTERPHASE   HAREADYSTATUS   HAREADYREASON
my-omni   10.131.0.33        Ready          DBClusterReady
您也可以使用 kubectl log 指令監控叢集部署作業:
kubectl logs -l alloydbomni.internal.dbadmin.goog/dbcluster=my-omni --all-containers -f
連線至 AlloyDB Omni
叢集準備就緒後,請使用 PostgreSQL 用戶端 (psql) 連線至資料庫 Pod。密碼為 VeryStrongPassword,如 my-omni.yaml 中所定義:
DB_CLUSTER_NAME=my-omni
DB_CLUSTER_NAMESPACE=default
DBPOD=`kubectl get pod --selector=alloydbomni.internal.dbadmin.goog/dbcluster=$DB_CLUSTER_NAME,alloydbomni.internal.dbadmin.goog/task-type=database -n $DB_CLUSTER_NAMESPACE -o jsonpath='{.items[0].metadata.name}'`
kubectl exec -ti $DBPOD -n $DB_CLUSTER_NAMESPACE -c database -- psql -h localhost -U postgres
控制台輸出內容範例:
DB_CLUSTER_NAME=my-omni
DB_CLUSTER_NAMESPACE=default
DBPOD=`kubectl get pod --selector=alloydbomni.internal.dbadmin.goog/dbcluster=$DB_CLUSTER_NAME,alloydbomni.internal.dbadmin.goog/task-type=database -n $DB_CLUSTER_NAMESPACE -o jsonpath='{.items[0].metadata.name}'`
kubectl exec -ti $DBPOD -n $DB_CLUSTER_NAMESPACE -c database -- psql -h localhost -U postgres
Password for user postgres:
psql (18.4)
SSL connection (protocol: TLSv1.3, cipher: TLS_AES_128_GCM_SHA256, compression: off, ALPN: postgresql)
Type "help" for help.

postgres=#
輸入 \q 並按下 Enter 鍵,結束 psql 工作階段:
postgres=# \q
5. 在 GKE 部署 EmbeddingGemma 模型
如要測試 AlloyDB Omni AI 與本機模型的整合,請將嵌入模型部署至 GKE 叢集。本教學課程使用 Google 的 EmbeddingGemma 模型。
取得 Hugging Face 權杖
本教學課程會部署 Hugging Face 的 EmbeddingGemma 模型。如要存取模型權重,請生成 Hugging Face 存取權杖:
- 登入或建立 Hugging Face 帳戶。
- 依序前往「Your Profile」 >「存取權杖」。
- 按一下「Create new token」。
- 輸入權杖名稱,然後選取「Read」角色。
- 按一下「Create token」,然後複製產生的權杖值。
- 如果尚未接受模型條款,請前往 EmbeddingGemma 模型頁面接受。
在 Cloud Shell 中建立 Kubernetes Secret,並加入 Hugging Face 權杖 (請將權杖預留位置替換為您的權杖):
export HF_TOKEN=<YOUR_HUGGING_FACE_TOKEN>
kubectl create secret generic hf-secret \
  --from-literal=hf_api_token=$HF_TOKEN \
  --dry-run=client -o yaml | kubectl apply -f -
準備部署資訊清單
如要部署模型,請使用 Hugging Face 的文字嵌入推論 (TEI) 容器套件。詳情請參閱 Hugging Face GKE TEI 說明文件。
從 GitHub 複製部署存放區:
git clone https://github.com/huggingface/Google-Cloud-Containers
檢查並修改 CPU 設定資訊清單:
edit Google-Cloud-Containers/examples/gke/tei-deployment/cpu-config/deployment.yaml
CPU 部署作業的更新資訊清單:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: tei-deployment
spec:
  replicas: 1
  selector:
    matchLabels:
      app: tei-server
  template:
    metadata:
      labels:
        app: tei-server
        hf.co/model: Google--embeddinggemma-300m
        hf.co/task: text-embeddings
    spec:
      containers:
        - name: tei-container
          image: ghcr.io/huggingface/text-embeddings-inference:cpu-latest
          resources:
            requests:
              cpu: "6"
              memory: "24Gi"
            limits:
              cpu: "6"
              memory: "24Gi"
          env:
            - name: MODEL_ID
              value: google/embeddinggemma-300m
            - name: NUM_SHARD
              value: "1"
            - name: PORT
              value: "8080"
            - name: HF_TOKEN
              valueFrom:
                secretKeyRef:
                  name: hf-secret
                  key: hf_api_token
          volumeMounts:
            - mountPath: /tmp
              name: tmp
      volumes:
        - name: tmp
          emptyDir: {}
      nodeSelector:
        cloud.google.com/machine-family: "c3"
按下 ctrl+s 儲存變更,然後切換回終端機。
部署模型
套用資訊清單,部署 TEI 伺服器:
kubectl apply -f Google-Cloud-Containers/examples/gke/tei-deployment/cpu-config
監控部署作業,直到進入就緒狀態:
printf "Waiting for model to load..."; until kubectl logs -l app=tei-server --tail=50 2>/dev/null | grep -q "Ready"; do printf "."; sleep 3; done; printf '\n\033[1;32m========================================\n[SUCCESS] Model is loaded and ready!\nYou can now proceed to the next step.\n========================================\033[0m\n'
檢查 tei-service Kubernetes 服務:
kubectl get service tei-service
預期輸出內容:
student@cloudshell$ kubectl get service tei-service
NAME          TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)    AGE
tei-service   ClusterIP   34.118.233.48   <none>        8080/TCP   10m
服務「CLUSTER-IP」在內部透過 http://34.118.233.48:8080/embed 提供要求。
使用 kubectl port-forward 在本機測試模型端點:
kubectl port-forward service/tei-service 8080:8080
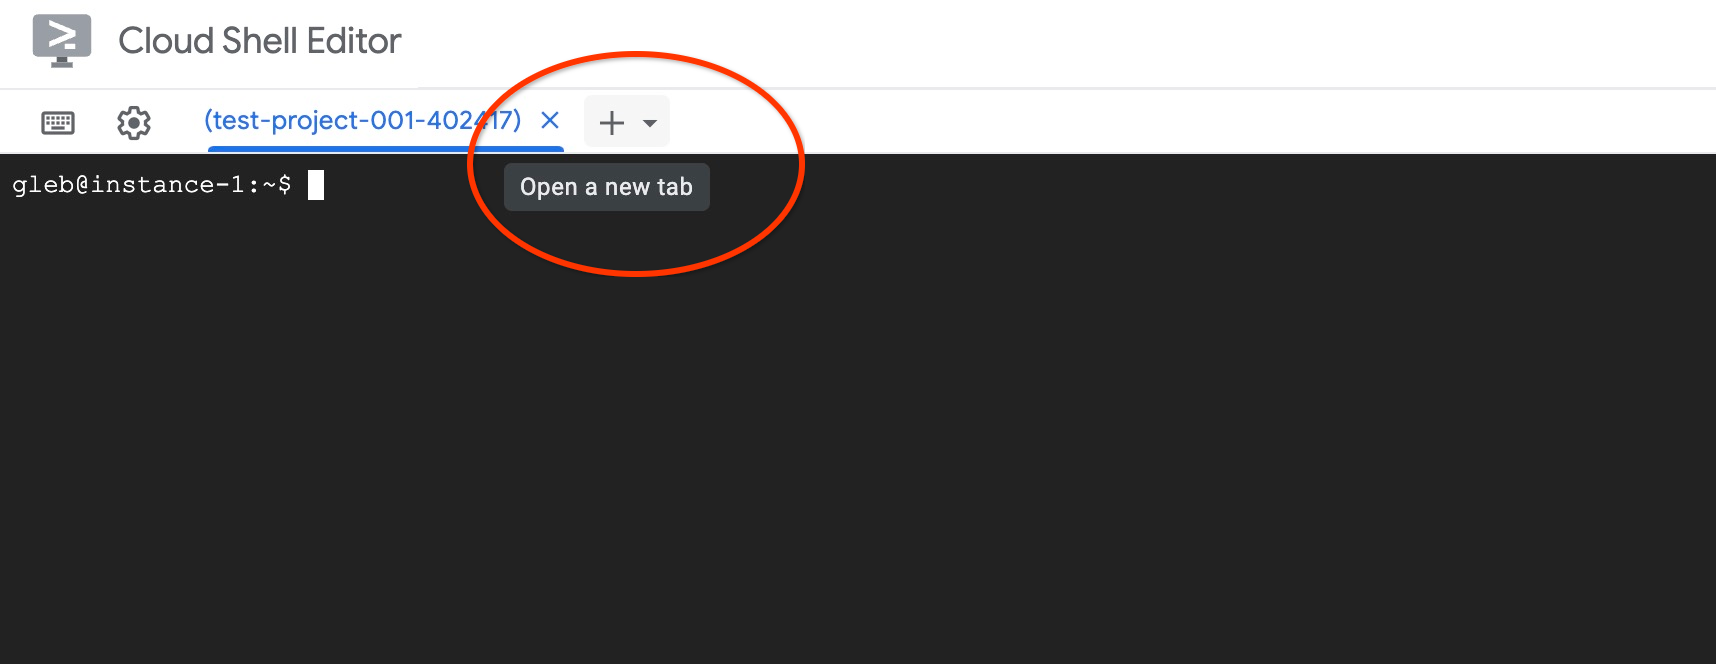
點選終端機頂端的「+」,開啟第二個 Cloud Shell 分頁:
在新分頁中,使用 curl 測試嵌入生成:
curl http://localhost:8080/embed \
  -X POST \
  -d '{"inputs":"Test"}' \
  -H 'Content-Type: application/json'
預期輸出內容 (向量陣列):
curl http://localhost:8080/embed \
>     -X POST \
>     -d '{"inputs":"Test"}' \
>     -H 'Content-Type: application/json'
[[-0.018975832,0.0071419072,0.06347208,0.022992613,0.014205903
...
-0.03677433,0.01636146,0.06731572]]
按下 ctrl+c,停止第一個分頁中的通訊埠轉送。
6. 在 AlloyDB Omni 註冊嵌入模型
如要透過 AlloyDB Omni 使用已部署的模型,請建立資料庫、定義轉換函式,並註冊模型端點。
建立用戶端 VM 和資料庫
在同一個虛擬私有雲中建立 Compute Engine VM 執行個體,做為用戶端跳板機:
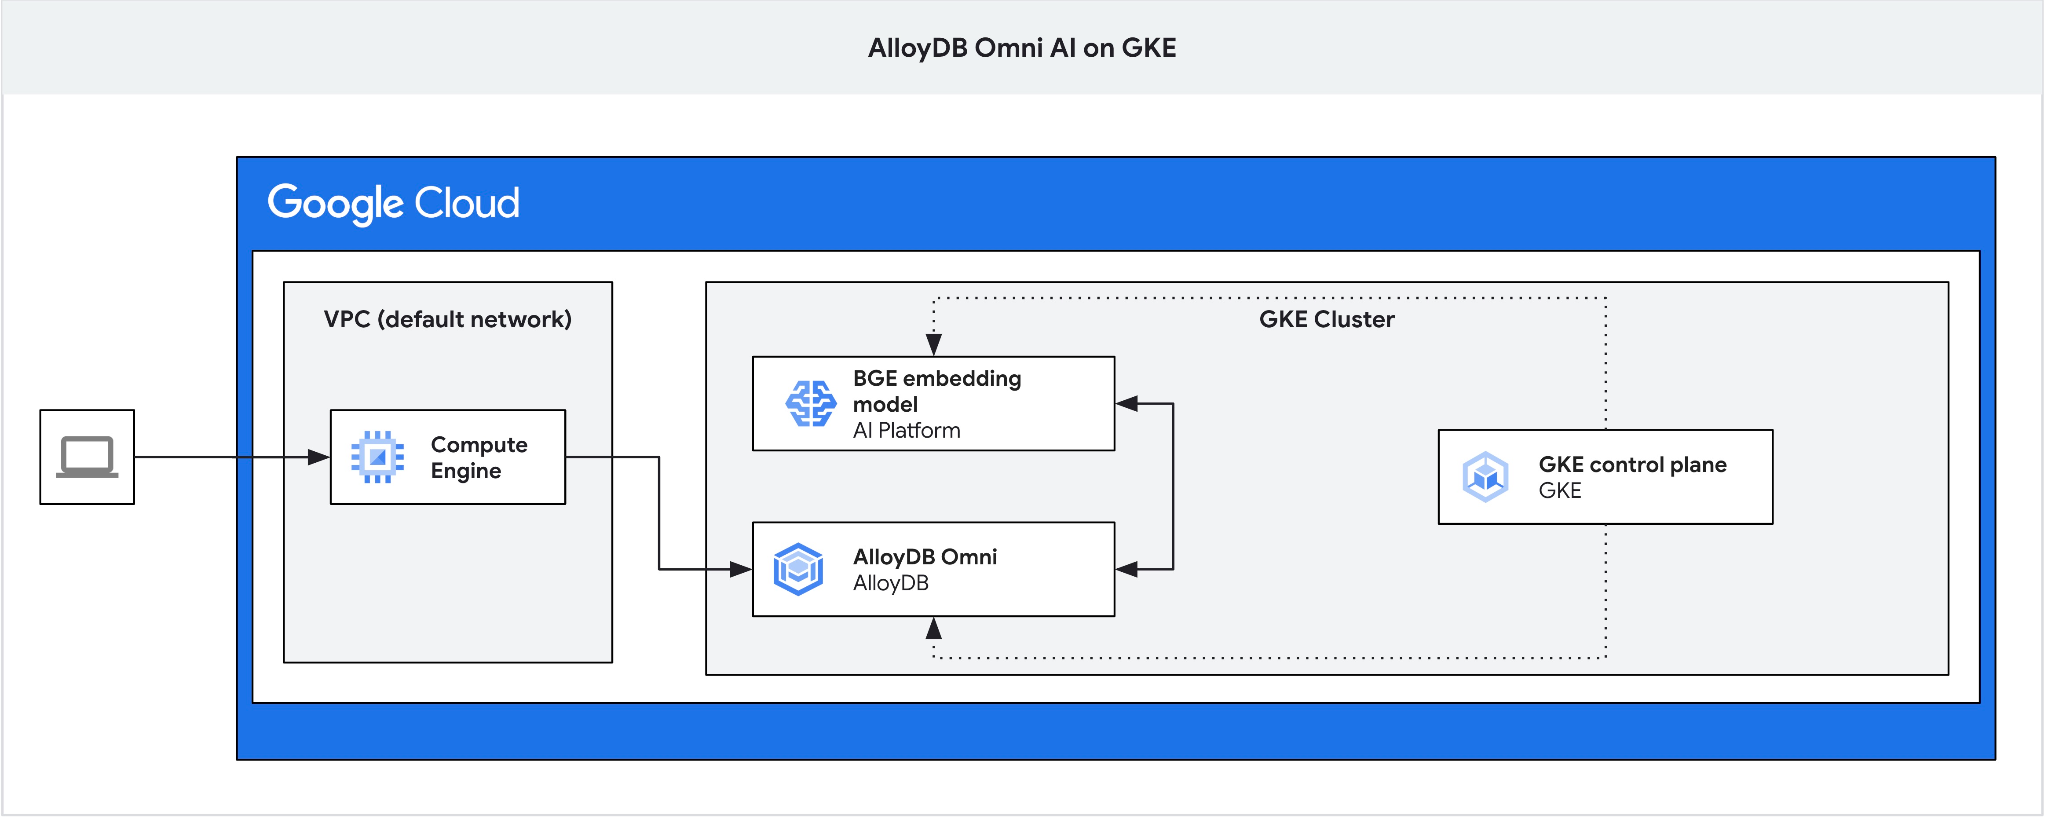
在 Cloud Shell 建立用戶端 VM:
export ZONE=${LOCATION}-a
gcloud compute instances create instance-1 \
  --zone=$ZONE
擷取 AlloyDB Omni 端點 IP:
echo "INSTANCE_IP=$(kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default -o jsonpath='{.status.primary.endpoint}')"
預期輸出內容:
INSTANCE_IP=10.128.0.33
INSTANCE_IP 值是 AlloyDB Omni 叢集的內部負載平衡器 IP。在本範例中,這個屬性的值是 10.131.0.33。
使用 SSH 連線至 VM 執行個體:
gcloud compute ssh instance-1 --zone=$ZONE
在 instance-1 的 SSH 工作階段中,安裝 PostgreSQL 用戶端:
sudo apt-get update && sudo apt-get install --yes postgresql-client
匯出 AlloyDB Omni 負載平衡器 IP (請替換為您的 PRIMARYENDPOINT IP):
export INSTANCE_IP=10.131.0.33
使用 psql 連線至 AlloyDB Omni (密碼為 VeryStrongPassword):
psql "host=$INSTANCE_IP user=postgres sslmode=require"
在 psql 工作階段中,建立 demo 資料庫:
CREATE DATABASE demo;
切換至 demo 資料庫:
\c demo
建立轉換函式
自訂嵌入端點需要輸入和輸出轉換函式,才能在 AlloyDB Omni 和模型 API 之間調整資料格式。
建立輸入轉換函式:
CREATE OR REPLACE FUNCTION tei_text_input_transform(model_id VARCHAR(100), input_text TEXT)
RETURNS JSON
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_input JSON;
BEGIN
  SELECT json_build_object('inputs', input_text, 'truncate', true)::JSON INTO transformed_input;
  RETURN transformed_input;
END;
$$;
預期輸出內容:
demo=# CREATE OR REPLACE FUNCTION tei_text_input_transform(model_id VARCHAR(100), input_text TEXT)
RETURNS JSON
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_input JSON;
BEGIN
  SELECT json_build_object('inputs', input_text, 'truncate', true)::JSON INTO transformed_input;
  RETURN transformed_input;
END;
$$;
CREATE FUNCTION
demo=#
建立輸出轉換函式,剖析向量陣列回應:
CREATE OR REPLACE FUNCTION tei_text_output_transform(model_id VARCHAR(100), response_json JSON)
RETURNS REAL[]
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_output REAL[];
BEGIN
  SELECT ARRAY(SELECT json_array_elements_text(response_json->0)) INTO transformed_output;
  RETURN transformed_output;
END;
$$;
預期輸出內容:
demo=# CREATE OR REPLACE FUNCTION tei_text_output_transform(model_id VARCHAR(100), response_json JSON)
RETURNS REAL[]
LANGUAGE plpgsql
AS $$
DECLARE
  transformed_output REAL[];
BEGIN
  SELECT ARRAY(SELECT json_array_elements_text(response_json->0)) INTO transformed_output;
  RETURN transformed_output;
END;
$$;
CREATE FUNCTION
demo=#
註冊模型
使用 google_ml.create_model 程序在 AlloyDB Omni 註冊模型。指定 http://tei-service:8080/embed 做為 model_request_url,將要求轉送至 Kubernetes 叢集服務:
CALL
  google_ml.create_model(
    model_id => 'embeddinggemma',
    model_request_url => 'http://tei-service:8080/embed',
    model_provider => 'custom',
    model_type => 'text_embedding',
    model_in_transform_fn => 'tei_text_input_transform',
    model_out_transform_fn => 'tei_text_output_transform');
預期輸出內容:
demo=# CALL
  google_ml.create_model(
    model_id => 'embeddinggemma',
    model_request_url => 'http://tei-service:8080/embed',
    model_provider => 'custom',
    model_type => 'text_embedding',
    model_in_transform_fn => 'tei_text_input_transform',
    model_out_transform_fn => 'tei_text_output_transform');
CALL
demo=#
使用 SQL 查詢範例測試已註冊的模型:
SELECT google_ml.embedding('embeddinggemma', 'What is AlloyDB Omni?');
這個函式會傳回實數陣列表示法,由 GKE 上執行的本機 EmbeddingGemma 模型生成。
按下 q 即可返回 psql 工作階段提示。
退出 psql 工作階段:
\q
7. 使用樣本資料測試模型
載入範例資料
本教學課程會使用 Cymbal 零售資料集,示範向量相似度搜尋。您將使用 Google Cloud SDK 和 PostgreSQL 用戶端,將資料匯入 AlloyDB Omni。
在 instance-1 的 SSH 工作階段中,連線至試用資料庫並啟用 vector 擴充功能:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
在 psql 工作階段中:
CREATE EXTENSION IF NOT EXISTS vector;
退出 psql 工作階段:
\q
下載並套用結構定義,在 demo 資料庫中建立資料表:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_demo_schema.sql |psql "host=$INSTANCE_IP user=postgres dbname=demo"
預期輸出內容:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_demo_schema.sql |psql "host=$INSTANCE_IP user=postgres dbname=demo"
Password for user postgres:
SET
SET
SET
SET
SET
 set_config
------------

(1 row)

SET
SET
SET
SET
SET
SET
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE TABLE
ALTER TABLE
CREATE SEQUENCE
ALTER TABLE
ALTER SEQUENCE
ALTER TABLE
ALTER TABLE
ALTER TABLE
student@cloudshell:~$
確認已建立的資料表:
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\dt+"
預期輸出內容:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\dt+"
Password for user postgres:
                                           List of relations
 Schema |       Name       | Type  |  Owner   | Persistence | Access method |    Size    | Description
--------+------------------+-------+----------+-------------+---------------+------------+-------------
 public | cymbal_embedding | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_inventory | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_products  | table | postgres | permanent   | heap          | 8192 bytes |
 public | cymbal_stores    | table | postgres | permanent   | heap          | 8192 bytes |
(4 rows)
將資料載入 cymbal_products 資料表:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_products.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_products from stdin csv header"
預期輸出內容:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_products.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_products from stdin csv header"
COPY 941
student@cloudshell:~$
以下是 cymbal_products 資料表中的幾列範例。
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT uniq_id,left(product_name,30),left(product_description,50),sale_price FROM cymbal_products limit 3"
預期輸出內容:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT uniq_id,left(product_name,30),left(product_description,50),sale_price FROM cymbal_products limit 3"
Password for user postgres:
             uniq_id              |              left              |                        left                        | sale_price
----------------------------------+--------------------------------+----------------------------------------------------+------------
 a73d5f754f225ecb9fdc64232a57bc37 | Laundry Tub Strainer Cup       |   Laundry tub strainer cup Chrome For 1-.50, drain |      11.74
 41b8993891aa7d39352f092ace8f3a86 | LED Starry Star Night Light La |  LED Starry Star Night Light Laser Projector 3D Oc |      46.97
 ed4a5c1b02990a1bebec908d416fe801 | Surya Horizon HRZ-1060 Area Ru |  The 100% polypropylene construction of the Surya  |       77.4
(3 rows)
student@cloudshell:~$
將資料載入 cymbal_inventory 資料表:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_inventory.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_inventory from stdin csv header"
預期輸出內容:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_inventory.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_inventory from stdin csv header"
Password for user postgres:
COPY 263861
student@cloudshell:~$
以下是 cymbal_inventory 資料表中的幾列範例。
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT * FROM cymbal_inventory LIMIT 3"
輸出內容:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT * FROM cymbal_inventory LIMIT 3"
Password for user postgres:
 store_id |             uniq_id              | inventory
----------+----------------------------------+-----------
     1583 | adc4964a6138d1148b1d98c557546695 |         5
     1490 | adc4964a6138d1148b1d98c557546695 |         4
     1492 | adc4964a6138d1148b1d98c557546695 |         3
(3 rows)
student@cloudshell:~$
將資料載入 cymbal_stores 資料表:
gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_stores.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_stores from stdin csv header"
預期的控制台輸出內容:
student@cloudshell:~$ gcloud storage cat gs://cloud-training/gcc/gcc-tech-004/cymbal_stores.csv |psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "\copy cymbal_stores from stdin csv header"
Password for user postgres:
COPY 4654
student@cloudshell:~$
以下是 cymbal_stores 資料表中的幾列範例。
psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT store_id, name, zip_code FROM cymbal_stores limit 3"
輸出內容:
student@cloudshell:~$ psql "host=$INSTANCE_IP user=postgres dbname=demo" -c "SELECT store_id, name, zip_code FROM cymbal_stores limit 3"
Password for user postgres:
 store_id |       name        | zip_code
----------+-------------------+----------
     1990 | Mayaguez Store    |      680
     2267 | Ware Supercenter  |     1082
     4359 | Ponce Supercenter |      780
(3 rows)
student@cloudshell:~$
建構嵌入
使用 psql 連線至示範資料庫,並根據 cymbal_products 資料表中的產品說明,為產品建立嵌入。
連線至示範資料庫:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
使用 vector 類型的 embedding 欄,儲存為產品說明生成的文字嵌入。
啟用查詢時間:
\timing
為每項產品說明生成嵌入,並儲存至 cymbal_embedding 資料表:
INSERT INTO cymbal_embedding (uniq_id, embedding)
SELECT uniq_id, google_ml.embedding('embeddinggemma', product_description)::vector
FROM cymbal_products;
預期輸出內容:
demo=# INSERT INTO cymbal_embedding(uniq_id,embedding)  SELECT uniq_id, google_ml.embedding('embeddinggemma',product_description)::vector FROM cymbal_products;
INSERT 0 941
Time: 497878.136 ms (08:17.878)
demo=#
執行語意搜尋查詢
在 psql 工作階段中,使用餘弦距離 (<=>) 找出與問題 "What kind of fruit trees grow well here?" 最相符的前五項產品:
SELECT
    cp.product_name,
    left(cp.product_description, 80) AS description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
預期輸出內容:
demo=# SELECT
        cp.product_name,
        left(cp.product_description,80) as description,
        cp.sale_price,
        cs.zip_code,
        (ce.embedding <=> google_ml.embedding('embeddinggemma','What kind of fruit trees grow well here?')::vector) as distance
FROM
        cymbal_products cp
JOIN cymbal_embedding ce on ce.uniq_id=cp.uniq_id
JOIN cymbal_inventory ci on ci.uniq_id=cp.uniq_id
JOIN cymbal_stores cs on cs.store_id=ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
     product_name      |                                   description                                    | sale_price | zip_code |      distance
-----------------------+----------------------------------------------------------------------------------+------------+----------+--------------------
 Cherry Tree           | This is a beautiful cherry tree that will produce delicious cherries. It is an d |      75.00 |    93230 | 0.5210549378080666
 California Lilac      | This is a beautiful lilac tree that can grow to be over 10 feet tall. It is an d |       5.00 |    93230 | 0.5639421771781971
 Toyon                 | This is a beautiful toyon tree that can grow to be over 20 feet tall. It is an e |      10.00 |    93230 | 0.5670010914504852
 Rose Bush             | This is a beautiful rose bush that will produce fragrant roses. It is a perennia |      50.00 |    93230 | 0.5731542622882957
 California Peppertree | This is a beautiful peppertree that can grow to be over 30 feet tall. It is an e |      25.00 |    93230 | 0.5750934653011995
(5 rows)

Time: 83.610 ms
demo=#
查詢執行了 83 毫秒,並從 cymbal_products 資料表傳回符合要求的樹木清單,且 1583 號商店有庫存。
建構 ANN 索引
如果資料集較小,可以輕鬆使用精確搜尋功能掃描所有嵌入,但資料量增加時,載入和回應時間也會增加。如要提升效能,您可以為嵌入資料建立索引。以下範例說明如何使用 Google ScaNN 索引處理向量資料。
如果連線中斷,請重新連線至示範資料庫:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
啟用 alloydb_scann 擴充功能:
CREATE EXTENSION IF NOT EXISTS alloydb_scann;
在 embedding 資料欄建立 ScaNN 索引:
CREATE INDEX cymbal_products_embeddings_scann ON cymbal_embedding
  USING scann (embedding cosine)
  WITH (num_leaves=10, max_num_levels = 1);
重新執行語意搜尋查詢,比較執行效能:
SELECT
    cp.product_name,
    left(cp.product_description, 80) AS description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
預期輸出內容:
demo=# SELECT
    cp.product_name,
    left(cp.product_description,80) as description,
    cp.sale_price,
    cs.zip_code,
    (ce.embedding <=> google_ml.embedding('embeddinggemma', 'What kind of fruit trees grow well here?')::vector) AS distance
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
    ci.inventory > 0
    AND cs.store_id = 1583
ORDER BY
    distance ASC
LIMIT 5;
     product_name      |                                   description                                    | sale_price | zip_code |      distance
-----------------------+----------------------------------------------------------------------------------+------------+----------+--------------------
 Cherry Tree           | This is a beautiful cherry tree that will produce delicious cherries. It is an d |      75.00 |    93230 | 0.5210549378080666
 California Lilac      | This is a beautiful lilac tree that can grow to be over 10 feet tall. It is an d |       5.00 |    93230 | 0.5639421771781971
 Toyon                 | This is a beautiful toyon tree that can grow to be over 20 feet tall. It is an e |      10.00 |    93230 | 0.5670010914504852
 Rose Bush             | This is a beautiful rose bush that will produce fragrant roses. It is a perennia |      50.00 |    93230 | 0.5731542622882957
 California Peppertree | This is a beautiful peppertree that can grow to be over 30 feet tall. It is an e |      25.00 |    93230 | 0.5750934653011995
(5 rows)

Time: 64.783 ms
查詢執行時間略有縮短,資料集越大,增幅就越明顯。傳回的資料應與沒有索引時取得的資料相同或非常相似。
嘗試其他查詢,並參閱說明文件,進一步瞭解如何最佳化向量索引。
退出 psql 工作階段:
\q
按下 CTRL+D 鍵或輸入 exit,中斷 instance-1 SSH 工作階段,返回 Google Cloud Shell。
8. 使用 vLLM 部署 Gemma
新增 Gemma 節點集區
首先,請查看您所在區域可用的節點類型:
gcloud compute accelerator-types list --filter="zone:${LOCATION}"
您應該會看到可用的加速器類型清單,包括 nvidia-l4 加速器。
使用 vLLM 為 Google Gemini 4 12B 模型建立 Deployment 資訊清單:
cat << 'EOF' > gemma-12b-gpu-vllm-deployment.yaml
apiVersion: apps/v1
kind: Deployment
metadata:
  name: gemma-12b-gpu-vllm-deployment
spec:
  replicas: 1
  selector:
    matchLabels:
      app: gemma-12b-gpu-vllm
  template:
    metadata:
      labels:
        app: gemma-12b-gpu-vllm
        ai.gke.io/model: gemma-4-12b-it
        ai.gke.io/inference-server: vllm
        examples.ai.gke.io/source: user-guide
    spec:
      containers:
      - name: inference-server
        image: us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:latest
        resources:
          requests:
            cpu: "4"
            memory: "16Gi"
            ephemeral-storage: "30Gi"
            nvidia.com/gpu: "1"
          limits:
            cpu: "8"
            memory: "24Gi"
            ephemeral-storage: "30Gi"
            nvidia.com/gpu: "1"
        command: ["python3", "-m", "vllm.entrypoints.api_server"]
        args:
          - --model=$(MODEL_ID)
          - --host=0.0.0.0
          - --port=8000
          - --tensor-parallel-size=1
          - --enable-log-requests
          - --enable-chunked-prefill
          - --enable-prefix-caching
          - --enable-auto-tool-choice
          - --generation-config=auto
          - --tool-call-parser=gemma4
          - --dtype=bfloat16
          - --max-num-seqs=16
          - --max-model-len=32768
          - --gpu-memory-utilization=0.95
          - --reasoning-parser=gemma4
          - --trust-remote-code
          - --quantization=fp8
        env:
        - name: LD_LIBRARY_PATH
          value: ${LD_LIBRARY_PATH}:/usr/local/nvidia/lib64
        - name: MODEL_ID
          value: google/gemma-4-12b-it
        - name: HF_TOKEN
          valueFrom:
            secretKeyRef:
              name: hf-secret
              key: hf_api_token
        volumeMounts:
        - mountPath: /dev/shm
          name: dshm
      volumes:
      - name: dshm
        emptyDir:
            medium: Memory
      nodeSelector:
        cloud.google.com/gke-accelerator: nvidia-l4
        cloud.google.com/gke-gpu-driver-version: latest
---
apiVersion: v1
kind: Service
metadata:
  name: gemma-12b-gpu-vllm-service
spec:
  selector:
    app: gemma-12b-gpu-vllm
  type: ClusterIP
  ports:
    - protocol: TCP
      port: 8000
      targetPort: 8000
EOF
套用已儲存的 gemma-12b-gpu-vllm-deployment.yaml 部署作業:
kubectl apply -f gemma-12b-gpu-vllm-deployment.yaml
預期輸出內容:
$ kubectl apply -f gemma-12b-gpu-vllm-deployment.yaml
deployment.apps/gemma-12b-gpu-vllm-deployment created
service/gemma-12b-gpu-vllm-service created
等待部署作業完成,模型載入完畢。這可能需要幾分鐘。
printf "Waiting for model to load..."; until kubectl logs -l app=gemma-12b-gpu-vllm --tail=50 2>/dev/null | grep -q "Application startup complete"; do printf "."; sleep 3; done; printf '\n\033[1;32m========================================\n[SUCCESS] Model is loaded and ready!\nYou can now proceed to the next step.\n========================================\033[0m\n'
預期輸出內容:
Waiting for model to load...
========================================
[SUCCESS] Model is loaded and ready!
You can now proceed to the next step.
========================================
測試模型。啟用通訊埠轉送功能,即可存取模型:
kubectl port-forward svc/gemma-12b-gpu-vllm-service 8090:8000
在另一個終端機視窗中,使用 curl 將提示傳送至模型:
curl http://localhost:8090/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "messages": [
      {"role": "system", "content": "You are a helpful assistant running on GKE."},
      {"role": "user", "content": "What is AlloyDB Omni."}
    ],
    "temperature": 0.7
  }' | jq -r '.choices[0].message.content'
預期輸出內容:
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100  3957  100  3761  100   196     85      4  0:00:49  0:00:43  0:00:06   830
**AlloyDB Omni** is a fully managed, PostgreSQL-compatible database engine from Google Cloud that can be run **on-premises, in other clouds, or in your own data centers.**

To understand it simply: It allows you to run the high-performance, enterprise-grade capabilities of Google's **AlloyDB** (a cloud-native database) on your own infrastructure.

Here is a breakdown of what makes it significant:

### 1. The "Best of Both Worlds" Architecture
Normally, you have to choose between:
*   **Managed Cloud Databases:** Easy to scale and manage, but you are locked into the cloud provider's infrastructure.
*   **Self-Managed Databases:** You have full control over the hardware/location, but you are responsible for scaling, patching, and high availability.

**AlloyDB Omni** bridges this gap. It provides the advanced features of a cloud-native database (like intelligent indexing, high availability, and massive scalability) while allowing you to run it anywhere.
按下 Ctrl+C,停止第一個終端機中的通訊埠轉送作業 (如果仍在執行)。
9. 在 AlloyDB Omni 註冊 Gemma 4 模型
使用 google_ml.create_model 程序,在 AlloyDB Omni 註冊 Gemma 12B 模型。指定 http://gemma-12b-gpu-vllm-service:8000/v1/chat/completions 做為 model_request_url,將要求轉送至 Kubernetes 叢集服務:
擷取 AlloyDB Omni 端點 IP:
echo "INSTANCE_IP=$(kubectl get dbclusters.alloydbomni.dbadmin.goog my-omni -n default -o jsonpath='{.status.primary.endpoint}')"
使用 SSH 連線至 VM 執行個體:
gcloud compute ssh instance-1 --zone=$ZONE
連線至 VM 後,匯出上一步的 INSTANCE_IP 變數 (10.128.0.33 值僅為範例,請替換成您的 IP):
export INSTANCE_IP=10.128.0.33
匯出 AlloyDB 密碼:
export PGPASSWORD=VeryStrongPassword
連線到 demo 資料庫:
psql "host=$INSTANCE_IP user=postgres sslmode=require dbname=demo"
在 psql 工作階段中註冊模型:
CALL
  google_ml.create_model(
    model_id => 'gemma-12b-gpu',
    model_request_url => 'http://gemma-12b-gpu-vllm-service:8000/v1/chat/completions',
    model_provider => 'custom',
    model_type => 'llm');
使用範例 SQL 查詢測試模型:
SELECT google_ml.predict_row(
  model_id => 'gemma-12b-gpu',
  request_body => json_build_object(
    'messages', json_build_array(
      json_build_object('role', 'user', 'content', 'What is AlloyDB Omni?'))))->'choices'->0->'message'->'content';
按下 q 鍵,即可從結果視窗返回 psql 提示
在 AlloyDB Omni 中結合向量搜尋與 LLM RAG
將向量搜尋與 LLM 要求搭配使用,示範如何透過 LLM 執行 RAG (檢索增強生成)。
在 plsql 中執行 SQL 查詢:
WITH trees AS (
SELECT
        cp.product_name,
        cp.product_description AS description,
        cp.sale_price,
        cs.zip_code,
        cp.uniq_id AS product_id
FROM
    cymbal_products cp
JOIN cymbal_embedding ce ON ce.uniq_id = cp.uniq_id
JOIN cymbal_inventory ci ON ci.uniq_id = cp.uniq_id
JOIN cymbal_stores cs ON cs.store_id = ci.store_id
WHERE
        ci.inventory>0
        AND cs.store_id = 1583
ORDER BY
        (ce.embedding <=> embedding('embeddinggemma',
        'What kind of fruit trees grow well here?')::vector) ASC
LIMIT 1),
prompt AS (
SELECT
        'You are a friendly advisor helping to find a product based on the customer''s needs.
Based on the client request we have loaded a list of products closely related to search.
The list in JSON format with list of values like {"product_name":"name","product_description":"some description","sale_price":10}
Here is the list of products:' || json_agg(trees) || 'The customer asked "What kind of fruit trees grow well here?"
You should give information about the product, price and some supplemental information' AS prompt_text
FROM
        trees),
response AS (
SELECT
        google_ml.predict_row(
          model_id =>'gemma-12b-gpu',
          request_body => json_build_object(
            'messages', json_build_array(
              json_build_object('role', 'user', 'content',prompt_text)
            )))->'choices'->0->'message'->'content' AS resp
FROM
        prompt)
SELECT
REPLACE(resp::text, '\n', CHR(10))
FROM
        response;
預期輸出內容:
----------------------------------------------------------------------------------------------------------------------------------------------
 "Hello there! I'd be happy to help you find the perfect tree for your garden.                                                               +
                                                                                                                                             +
 Based on your location, we have a wonderful option that would grow beautifully in your area:                                                +
                                                                                                                                             +
 **Cherry Tree**                                                                                                                             +
 *   **Price:** $75.00                                                                                                                       +
 *   **Description:** This is a stunning deciduous tree that not only provides a beautiful landscape but also produces delicious cherries.   +
 *   **Supplemental Information:**                                                                                                           +
     *   **Growth:** It grows to about 15 feet tall.                                                                                         +
     *   **Appearance:** You can look forward to dark green leaves in the summer that transform into a vibrant red in the fall.              +
     *   **Benefits:** It's a great choice if you're looking for both fruit and extra shade or privacy in your yard.                         +
     *   **Care Tips:** It performs best in a cool, moist climate with sandy soil. Since you are in a suitable zone, it should thrive nicely!+
                                                                                                                                             +
 Would you like more details on how to plant this, or would you like to proceed with an order?"
(1 row)
查詢會根據向量搜尋結果,補充 LLM 的提示。
嘗試其他查詢,並實驗 RAG 模式。這個架構的優點是完全自給自足。資料不會傳送至叢集外部,且可在完全隔離的環境中執行。
退出 psql 工作階段:
\q
中斷與 VM 的 SSH 工作階段連線:
exit
別忘了,AlloyDB Omni 還有更多功能和實驗室。
10. 清理環境
為避免系統持續向您的 Google Cloud 帳戶收取費用,請刪除在本程式碼實驗室建立的資源。
刪除 GKE 叢集
在 Cloud Shell 中刪除 GKE 叢集:
export PROJECT_ID=$(gcloud config get-value project)
export CLUSTER_NAME=alloydb-ai-gke
gcloud container clusters delete ${CLUSTER_NAME} \
  --project=${PROJECT_ID} \
  --region=${LOCATION}
預期輸出內容:
student@cloudshell:~$ gcloud container clusters delete ${CLUSTER_NAME} \
>   --project=${PROJECT_ID} \
>   --region=${LOCATION}
The following clusters will be deleted.
 - [alloydb-ai-gke] in [us-east4]

Do you want to continue (Y/n)?  Y

Deleting cluster alloydb-ai-gke...done.
Deleted
刪除用戶端 VM
在 Cloud Shell 刪除 Compute Engine 執行個體:
export PROJECT_ID=$(gcloud config get-value project)
gcloud compute instances delete instance-1 \
  --project=${PROJECT_ID} \
  --zone=${ZONE}
預期輸出內容:
student@cloudshell:~$ export PROJECT_ID=$(gcloud config get project)
export ZONE=us-east4-a
gcloud compute instances delete instance-1 \
  --project=${PROJECT_ID} \
  --zone=${ZONE}
Your active configuration is: [cloudshell-5399]
The following instances will be deleted. Any attached disks configured to be auto-deleted will be deleted unless they are attached to any other instances or the `--keep-disks` flag is given and specifies them for keeping. Deleting a disk
is irreversible and any data on the disk will be lost.
 - [instance-1] in [us-east4-a]

Do you want to continue (Y/n)?  Y

Deleted
如果您為這個程式碼實驗室建立了新專案,可以選擇在 Google Cloud Resource Manager 中刪除整個專案。
11. 恭喜
恭喜您完成程式碼實驗室!
涵蓋內容
- 如何在 GKE 叢集部署 AlloyDB Omni
- 如何連線至 AlloyDB Omni
- 如何將資料載入 AlloyDB Omni
- 如何將 AI 模型 (嵌入和 LLM) 部署至 GKE
- 如何在 AlloyDB Omni 註冊 AI 模型
- 如何生成語意搜尋的嵌入
- 如何在 AlloyDB Omni 執行語意搜尋查詢
- 如何在 AlloyDB Omni 建立及使用向量索引
如要進一步瞭解如何在 AlloyDB Omni 中使用 AI,請參閱說明文件。
問卷調查
輸出內容: