

1. 简介
此 Codelab 演示了如何在 Google Compute Engine (GCE) 虚拟机 (VM) 上部署 AlloyDB Omni 高可用性 (HA) 集群。在此 Codelab 结束时,您将预配一个包含 3 个数据库节点和 2 个 HAProxy 节点的高可用性参考架构,以及一个用于管理操作的控制节点。
前提条件
- 能够通过 Cloud 控制台访问 Google Cloud 项目和 Cloud Shell。
- 已安装并配置 Google Cloud SDK (
gcloud)。如需详细了解如何安装 gcloud,请参阅 gcloud-install - 已安装 Terraform v1.9.8。
学习内容
- 如何创建和准备 GCE 虚拟机以用于 AlloyDB Omni。
- 如何安装和运行 AlloyDB Omni RPM 编排器。
- 如何为高可用性参考架构安装和配置 AlloyDB Omni RPM。
所需条件
- 获取指向 AlloyDB Omni RPM 和 RPM 编排器的网址链接。为此,您需要填写 AlloyDB Omni 注册表单。链接会发送到您的电子邮件地址,其中包含代码库网址服务器。初始化以下环境变量,以便在 Codelab 中随时使用这些网址。
export ORCHESTRATOR_ANSIBLE_COLLECTION_PATH="..." export ALLOYDB_OMNI_REPOSITORY_URL="..." export ALLOYDB_OMNI_ORCHESTRATOR_REPOSITORY_URL="..." export ALLOYDB_OMNI_COMMON_REPOSITORY_URL="..." export ETCD_REPOSITORY_URL="..." - 一个可正常运行的终端,可访问 AlloyDB Omni 部署堆栈。您可以使用 Cloud Shell 来实现此目的。
2. 设置和要求
项目设置
创建 Google Cloud 项目
- 在 Google Cloud 控制台的项目选择器页面上,选择或创建一个 Google Cloud 项目。
- 确保您的 Cloud 项目已启用结算功能。了解如何检查项目是否已启用结算功能。
启动 Cloud Shell
虽然可以通过笔记本电脑对 Google Cloud 进行远程操作,但在此 Codelab 中,您将使用 Google Cloud Shell,这是一个在云端运行的命令行环境。
在 Google Cloud 控制台中,点击右上角工具栏中的 Cloud Shell 图标:
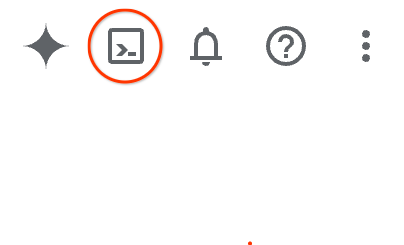
或者,您也可以按 G 键,然后按 S 键。如果您在 Google Cloud 控制台中,或者使用此链接,此序列将激活 Cloud Shell。
预配和连接到环境应该只需要片刻时间。完成后,您应该会看到如下内容:
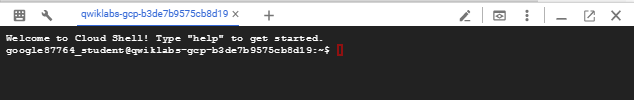
这个虚拟机已加载了您需要的所有开发者工具。它提供了一个持久的 5 GB 主目录,并且在 Google Cloud 中运行,大大增强了网络性能和身份验证功能。您在此 Codelab 中的所有工作都可以在浏览器中完成。您无需安装任何程序。
3. 创建 Google Cloud Compute Engine 虚拟机
准备 Terraform 脚本
- 为项目 ID 和所需的集群名称定义环境变量。您将在整个 Codelab 中使用这些变量。
export PROJECT="your-project-id" export CLUSTER="your-cluster-name" - 确保您已使用 Google Cloud 账号用户登录。
gcloud auth login - 为部署创建工作目录,并从代码库来源复制所需的 Terraform 配置文件。
mkdir -p ~/alloydb-omni/$PROJECT/$CLUSTER cd ~/alloydb-omni/$PROJECT/$CLUSTER gcloud storage cp gs://alloydb-omni-install/rpm-orchestrator/gce/terraform/*.tf . - 创建一个
terraform.tfvars文件,以根据参考架构指定所需参数,如下所示:cat > terraform.tfvars <<EOF # Required instance counts for reference architecture db_instance_count = 3 haproxy_instance_count = 2 control_instance_count = 1 # Optional: Customize if needed with the below variables # os_image = "rocky-linux-cloud/rocky-linux-9" # zone = "us-west4-c" # region_1 = "us-west4" # db_instance_type = "c4-highmem-4" # db_disk_type = "hyperdisk-balanced" # db_data_size = "50" # GB # data_dir = "/data" EOF
执行 Terraform 脚本并进行验证
- 您现在可以预配虚拟机了。
terraform init - 在创建虚拟机之前,请确保您拥有创建虚拟机和其他资源所需的访问权限。总而言之,您需要以下权限。
roles/compute.admin roles/iam.roleAdmin roles/compute.osAdminLogin roles/iam.serviceAccountCreator roles/iam.serviceAccountUser roles/artifactregistry.repoAdmin roles/storage.objectUser roles/resourcemanager.projectIamAdmin roles/serviceusage.serviceUsageAdmin - 验证配置并应用配置以预配资源。
terraform validate terraform apply --auto-approve - Terraform 完成后,使用
gcloud列出已创建的实例,验证虚拟机是否已成功创建。gcloud compute instances list --filter="name~$CLUSTER" --project=$PROJECTexport ZONE=$(gcloud compute instances list \ --filter="name=$CLUSTER-control" \ --format="value(zone)" --project=$PROJECT)
4. 准备虚拟机以进行部署
您需要创建与控制节点的 SSH 会话,并执行相应步骤以允许通过 SSH 访问所有虚拟机(也称为节点)。
- 确保已定义项目和集群的环境变量。
export PROJECT="your-project-id" export CLUSTER="your-cluster-name" - 创建 SSH 密钥,并添加该密钥以登录控制虚拟机。
# Replace values with your specific GCP project, cluster and zone details ssh-keygen -t ed25519 -f $HOME/.ssh/google_compute_engine gcloud compute os-login ssh-keys add --key-file=$HOME/.ssh/google_compute_engine.pub --project=$PROJECT - 创建防火墙规则,以允许 SSH 连接,并允许 VRRP 流量。
gcloud compute config-ssh --project=$PROJECT gcloud compute firewall-rules create $CLUSTER-allow-ssh --network=$CLUSTER --project=$PROJECT --direction=INGRESS --action=allow --rules=tcp:22 --source-ranges="0.0.0.0/0" gcloud compute firewall-rules create $CLUSTER-allow-vrrp --network=$CLUSTER --project=$PROJECT --allow=112 --source-ranges="0.0.0.0/0" - 通过 SSH 连接到控制虚拟机:
gcloud compute ssh "$CLUSTER-control" --zone=$ZONE --project=$PROJECT - 在控制节点上创建与用户名相同的 Linux 群组:
sudo groupadd -f $(id -un) sudo usermod -aG $(id -un) $(id -un) - Terraform 设置会创建一些配置脚本,并将它们暂存到控制虚拟机的
/tmp/目录中,其中包括集群名称、服务账号、项目名称等内容。使用控制节点上的设置脚本,创建从控制节点到所有集群节点的无密码 SSH 访问权限。/tmp/setup-ssh-for-cluster.sh - 在此 Codelab 中,我们可以停用所有节点上的 SELinux。Terraform 脚本添加了“/tmp/run-all.sh”,可用于此目的。
/tmp/run-all.sh sudo setenforce 0 - 如果您已注册 AlloyDB Omni 并获得了相关链接,现在可以开始将这些网址添加到环境变量中。
cat >> ~/.codelab.env <<EOF export ORCHESTRATOR_ANSIBLE_COLLECTION_PATH="..." export ALLOYDB_OMNI_REPOSITORY_URL="..." export ALLOYDB_OMNI_ORCHESTRATOR_REPOSITORY_URL="..." export ALLOYDB_OMNI_COMMON_REPOSITORY_URL="..." export ETCD_REPOSITORY_URL="..." EOFterraform/variables.tf中的 cidr_range 输入变量中为您的环境确定一个虚拟 IP,使其不与其他节点冲突,如以下示例所示:cat >> ~/.codelab.env <<EOF export VIRTUAL_IP="10.1.0.50" EOF
5. 在所有虚拟机上安装所需的软件组件
下一步是在虚拟机上安装所需的软件组件。这可以在控制节点上进行协调。以下所有命令都需要在控制节点上执行。
- 通过 SSH 连接到控制虚拟机(如果尚未在控制节点上)。
gcloud compute ssh "$CLUSTER-control" --zone=$ZONE --project=$PROJECTsource ~/.codelab.env - 在控制节点上,安装 Ansible 和所需的 Python 库。
sudo dnf install -y https://dl.fedoraproject.org/pub/epel/epel-release-latest-9.noarch.rpm -y sudo dnf install -y ansible sudo dnf install -y python3-grpcio python3-protobuf python3-googleapis-common-protos python3-grpcio-status - 接下来,下载 RPM Orchestrator Ansible 集 tar 文件,并安装该文件。
gcloud storage cp "gs://${ORCHESTRATOR_ANSIBLE_COLLECTION_PATH#https://storage.googleapis.com/}google-alloydbomni_orchestrator-*.tar.gz" .
COLLECTION_FILE=$(ls -1 google-alloydbomni_orchestrator-*.tar.gz \
  | sort -V | tail -n 1)
ansible-galaxy collection install "$COLLECTION_FILE"
ansible-galaxy collection list | grep alloydbomni_orchestrator
sort -V和tail -n 1命令会选择最新版本的文件。注意:请确保 ORCHESTRATOR_ANSIBLE_COLLECTION_PATH 变量末尾包含“/”。 - 编排器使用 Ansible 清单格式的部署规范文件来了解您的集群拓扑。在控制节点上创建一个名为 deployment_spec.yaml 的文件,其中包含您的节点详细信息。
cat > deployment_spec.yaml <<EOF alloydbomni: vars: cluster_manager: name: "$CLUSTER" etcd: setup: true config_forcewrite: true alloydbomni: major_version: "18" repo_url: $ALLOYDB_OMNI_REPOSITORY_URL alloydbomni_monitor: repo_url: $ALLOYDB_OMNI_COMMON_REPOSITORY_URL alloydbomni_cluster_manager: repo_url: $ALLOYDB_OMNI_ORCHESTRATOR_REPOSITORY_URL alloydbomni_node_manager: repo_url: $ALLOYDB_OMNI_ORCHESTRATOR_REPOSITORY_URL pgbouncer: repo_url: $ALLOYDB_OMNI_COMMON_REPOSITORY_URL pgbackrest: repo_url: $ALLOYDB_OMNI_COMMON_REPOSITORY_URL children: primary_instance_nodes: hosts: $CLUSTER-db1: $CLUSTER-db2: $CLUSTER-db3: load_balancer_nodes: hosts: $CLUSTER-haproxy1: $CLUSTER-haproxy2: EOF - 创建一个名为 install.yaml 的 playbook,用于引用编排器集合中的安装角色。
cat > install.yaml <<EOF - name: Install AlloyDB Omni cluster components hosts: all vars: ansible_become: true ansible_user: $SSH_USER ansible_ssh_private_key_file: $HOME/ssh-key-cluster-sa roles: - role: google.alloydbomni_orchestrator.install EOF - 使用您的清单文件执行 playbook,以在所有指定节点上下载并安装 RPM。
ansible-playbook -i deployment_spec.yaml install.yaml
6. 引导 AlloyDB Omni 集群
在此阶段,我们已在所有节点上安装了所有必需的组件。我们已准备好启动 AlloyDB Omni 集群。
- 通过 SSH 连接到控制虚拟机(如果尚未在控制节点上)。
gcloud compute ssh "$CLUSTER-control" --zone=$ZONE --project=$PROJECTsource ~/.codelab.env - 为密码生成哈希值,并获取已安装的 AlloyDB Omni 数据库版本:
encoded_password=$(echo -n "your unique password" | base64) DB_VERSION=$(/tmp/run-all.sh -t db 'rpm -q --qf "%{VERSION}\n" alloydbomni18' | tail -n 1) echo "$DB_VERSION" - 为了创建集群,AlloyDB Omni 必须知道如何配置它。为数据库集群规范创建文件名 dbcluster.yaml。
cat > dbcluster.yaml <<EOF Secret: metadata: name: db-pw-$CLUSTER spec: type: Opaque data: $CLUSTER: $encoded_password --- DBCluster: metadata: name: $CLUSTER spec: databaseVersion: $DB_VERSION mode: "" availability: numberOfStandbys: 2 enableAutoFailover: true enableAutoHeal: true autoFailoverTriggerThreshold: 2 autoHealTriggerThreshold: 2 healthcheckPeriodSeconds: 5 replayReplicationSlotsOnStandbys: false primarySpec: adminUser: passwordRef: name: db-pw-$CLUSTER resources: cpu: 4 memory: 32Gi disks: - name: DataDisk path: $PGDATA dbLoadBalancerOptions: gcp: loadBalancerIP: "$VIRTUAL_IP" loadBalancerType: "internal" loadBalancerInterface: "eth0" EOF - 创建名为 bootstrap.yaml 的 playbook,该 playbook 将引用用于创建 AlloyDB Omni 集群的引导 Ansible 角色。
cat > bootstrap.yaml <<EOF - name: Create DBCluster hosts: localhost roles: - role: google.alloydbomni_orchestrator.bootstrap EOF - 运行 playbook 以创建集群
ansible-playbook bootstrap.yaml -i deployment_spec.yaml -e resource_spec=dbcluster.yaml
7. (可选)配置 PgBouncer 连接池程序
AlloyDB Omni 支持使用 PgBouncer 进行轻量级连接池处理。您可以在集群完成预配后立即配置和启动 PgBouncer。
- 创建一个名为 pgbouncer.yaml 的资源规范文件,用于将连接池与数据库集群相关联:
cat > pgbouncer.yaml <<EOF PgBouncer: metadata: name: pgbouncer-pooler spec: dbclusterRef: $CLUSTER allowSuperUserAccess: true accessMode: "rw" port: 6432 EOF - 使用之前创建的同一 bootstrap.yaml playbook 引导 PgBouncer 连接池,并传递新的规范文件:
ansible-playbook bootstrap.yaml -i deployment_spec.yaml -e resource_spec=pgbouncer.yaml
8. 验证 AlloyDB Omni 集群
如需验证集群是否正常运行并且可以使用负载均衡器访问,您可以从控制节点使用标准 PostgreSQL 客户端连接到集群。
- 在控制节点上安装 PostgreSQL 18 客户端代码库和软件包:
sudo dnf install -y https://download.postgresql.org/pub/repos/yum/reporpms/EL-9-x86_64/pgdg-redhat-repo-latest.noarch.rpm sudo dnf install -y postgresql18 - 使用之前预留的虚拟 IP 连接到集群。系统会提示您输入在 dbcluster.yaml 中编码的密码:
/usr/pgsql-18/bin/psql -h $VIRTUAL_IP -U postgres -W - 连接后,您可以运行基本的 SQL 查询来验证集群状态,例如检查数据库版本:
postgres=# SELECT version();\q以退出提示。
9. (可选)使用 pgBackRest 备份数据
AlloyDB Omni 与 pgBackRest 集成,可直接将备份管理到 Cloud Storage。您可以配置备份方案,并触发按需备份到由 Terraform 设置创建的 GCS 存储桶。
- 创建一个名为 backup_plan.yaml 的备份方案规范文件,指向您已预配的 GCS 存储桶:
cat > backup_plan.yaml <<EOF BackupPlan: metadata: name: pgb-plan spec: dbclusterRef: $CLUSTER backupLocation: type: GCS gcsOptions: bucket: $CLUSTER-gcs-backups key: /backups EOF - 创建名为 backup.yaml 的 Ansible playbook,其中引用了备份管理角色:
cat > backup.yaml <<EOF - name: Manage AlloyDB Omni Backups hosts: localhost roles: - role: google.alloydbomni_orchestrator.backup EOF - 使用 backup.yaml playbook 应用备份方案:
ansible-playbook backup.yaml -i deployment_spec.yaml -e resource_spec=backup_plan.yaml - 成功建立方案后,创建一个名为 create_backup.yaml 的按需备份资源文件。
cat > create_backup.yaml <<EOF Backup: metadata: name: on-demand-backup spec: backupPlanRef: pgb-plan dbclusterRef: $CLUSTER EOF - 执行 playbook 以启动备份:
ansible-playbook backup.yaml -i deployment_spec.yaml -e resource_spec=create_backup.yaml - 如需验证备份的状态,请创建 status.yaml playbook:
cat > status.yaml <<EOF
- name: Fetch AlloyDB Omni Resource Status
  hosts: localhost
  roles:
    - role: google.alloydbomni_orchestrator.status
EOF
- 运行 playbook 以列出所有备份:
ansible-playbook status.yaml -i deployment_spec.yaml -e resource_type=Backup
- 或者,如需获取之前创建的特定备份的详细信息,请传递
-e resource_name=on-demand-backup:
ansible-playbook status.yaml -i deployment_spec.yaml \
  -e resource_type=Backup \
  -e resource_name=on-demand-backup
10. 清理资源
完成部署后,您可以销毁已预配的资源,以免产生费用。
- 创建名为 teardown.yaml 的 playbook:
cat > teardown.yaml <<EOF - name: Tear down AlloyDB Omni cluster hosts: localhost roles: - role: google.alloydbomni_orchestrator.delete EOF - 使用 ansible-playbook 执行 playbook。如果您已配置备份,请先删除备份和 BackupPlan 资源:
ansible-playbook teardown.yaml -i deployment_spec.yaml -e "resource_type=Backup" -e "resource_name=on-demand-backup" ansible-playbook teardown.yaml -i deployment_spec.yaml -e "resource_type=BackupPlan" -e "resource_name=pgb-plan"ansible-playbook teardown.yaml -i deployment_spec.yaml -e "resource_type=PgBouncer" -e "resource_name=pgbouncer-pooler"ansible-playbook teardown.yaml -i deployment_spec.yaml -e "resource_type=DBCluster" -e "resource_name=$CLUSTER" - 删除集群后,从控制节点退出,切换回终端并前往 Terraform 工作目录。
注意:如果您刚刚登录 Cloud Shell,请务必设置以下内容:export PROJECT="your-project-id" export CLUSTER="your-cluster-name" - 删除 VRRP 防火墙规则并销毁由 Terraform 管理的资源:
gcloud compute firewall-rules delete -q "$CLUSTER-allow-vrrp" --project="$PROJECT" gcloud compute firewall-rules delete -q "$CLUSTER-allow-ssh" --project="$PROJECT" terraform destroy - 在系统提示时,确认销毁。由于残留的网络资源或路由有时可能会阻止完全拆解,因此请运行以下安全清理命令,以确保完全移除所有关联的防火墙规则、NAT 网关、路由器、路由、子网和网络。将
REGION替换为您的具体部署区域,例如“us-central1”:# Delete any remaining firewall rules associated with the cluster gcloud compute firewall-rules list --project=$PROJECT 2> /dev/null | grep ^$CLUSTER- | cut -f1 -d' ' | \ while read rule; do gcloud compute firewall-rules delete --project=$PROJECT --quiet $rule; done # Delete the Cloud NAT gateway and router if they still exist gcloud compute routers nats describe $CLUSTER-nat-gw --router=$CLUSTER-router --region=REGION --project=$PROJECT 2>/dev/null \ && gcloud compute routers nats delete $CLUSTER-nat-gw --router=$CLUSTER-router --region=REGION --project=$PROJECT --quiet gcloud compute routers describe $CLUSTER-router --region=REGION --project=$PROJECT 2>/dev/null \ && gcloud compute routers delete $CLUSTER-router --region=REGION --project=$PROJECT --quiet # Delete any remaining custom routes gcloud compute routes list --project=$PROJECT --filter="network:$CLUSTER" --format="value(name)" 2>/dev/null | \ while read route; do gcloud compute routes delete --project=$PROJECT --quiet $route 2>/dev/null || true; done # Delete the subnet and network if they still exist gcloud compute networks subnets describe $CLUSTER --region=REGION --project=$PROJECT 2>/dev/null \ && gcloud compute networks subnets delete $CLUSTER --region=REGION --project=$PROJECT --quiet gcloud compute networks describe $CLUSTER --project $PROJECT 2> /dev/null \ && gcloud compute networks delete $CLUSTER --project $PROJECT --quiet
11. 恭喜
恭喜您完成此 Codelab。
所学内容
- 如何创建和准备 GCE 虚拟机以用于 AlloyDB Omni。
- 如何安装和运行 AlloyDB Omni RPM 编排器。
- 如何为高可用性参考架构安装和配置 AlloyDB Omni RPM。
如需详细了解 AlloyDB Omni,请参阅文档。