

1. はじめに
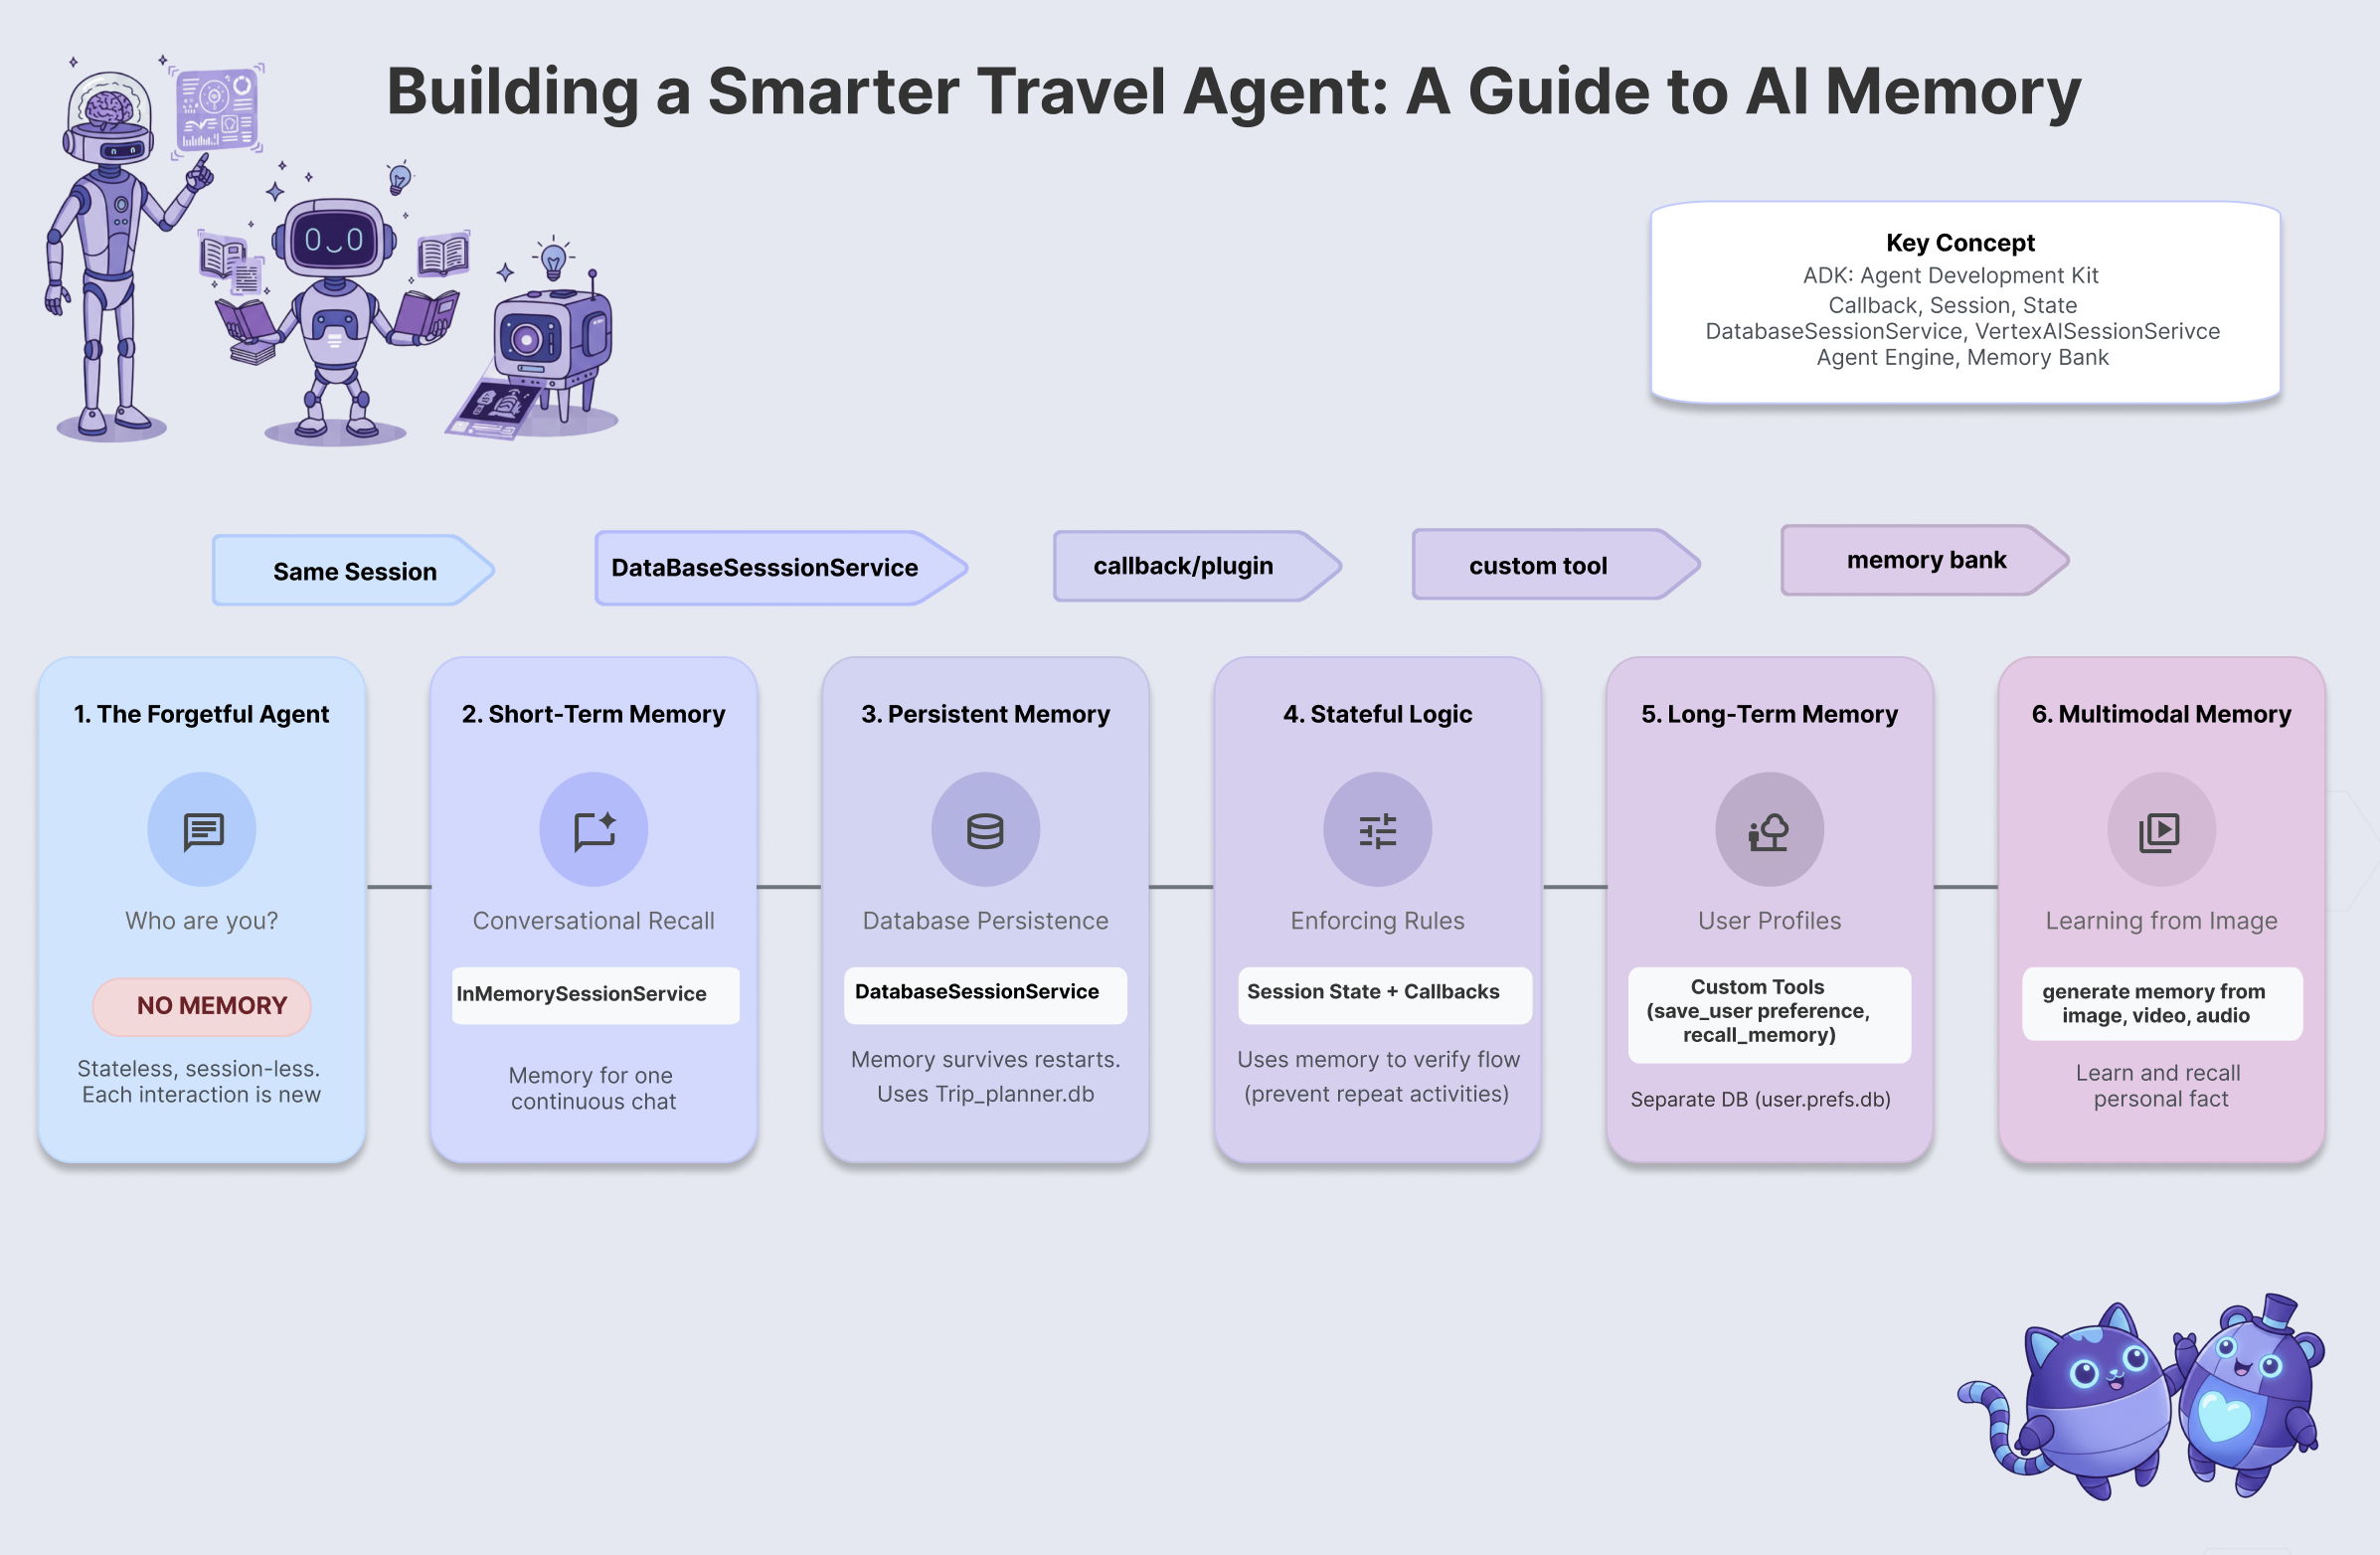
「Goldfish」プロブレム
東京への夢の旅行を計画するために、旅行代理店に依頼したとします。Session Agent を使用して、「金魚の問題」の動作を確認します。
あなたはオフィスに入り、次のように言います。
「お世話になっております。東京への 2 日間の旅行を計画したい。歴史的な場所とお寿司に興味があります。」
エージェントは熱心に次のように答えます。
「ありがとうございます。では、皇居を訪れ、すきやばし次郎で寿司を食べる予定です。」
あなたは笑顔で次のように言います。
「それはよさそうですね。旅程を送ってもらえますか?」
エージェントはあなたをぼんやりと見て、次のように尋ねます。
「お世話になっております。本日はどのようなご用件でしょうか?」
これは「金魚問題」と呼ばれています。記憶機能がない場合、すべてのインタラクションはブランク スレートの状態から始まります。インテリジェンスは存在し、エージェントは旅行の計画方法を知っていますが、継続性が欠けています。AI エージェントが真に有用であるためには、記憶力が必要です。
今日のミッション
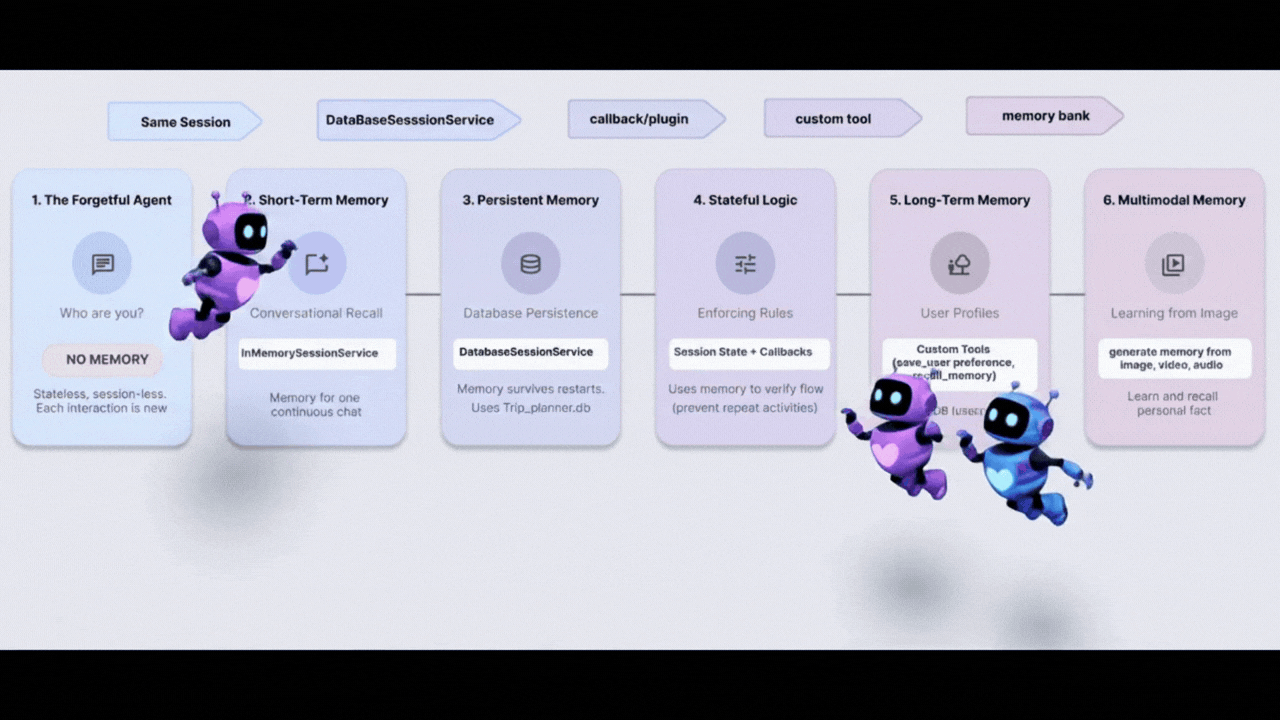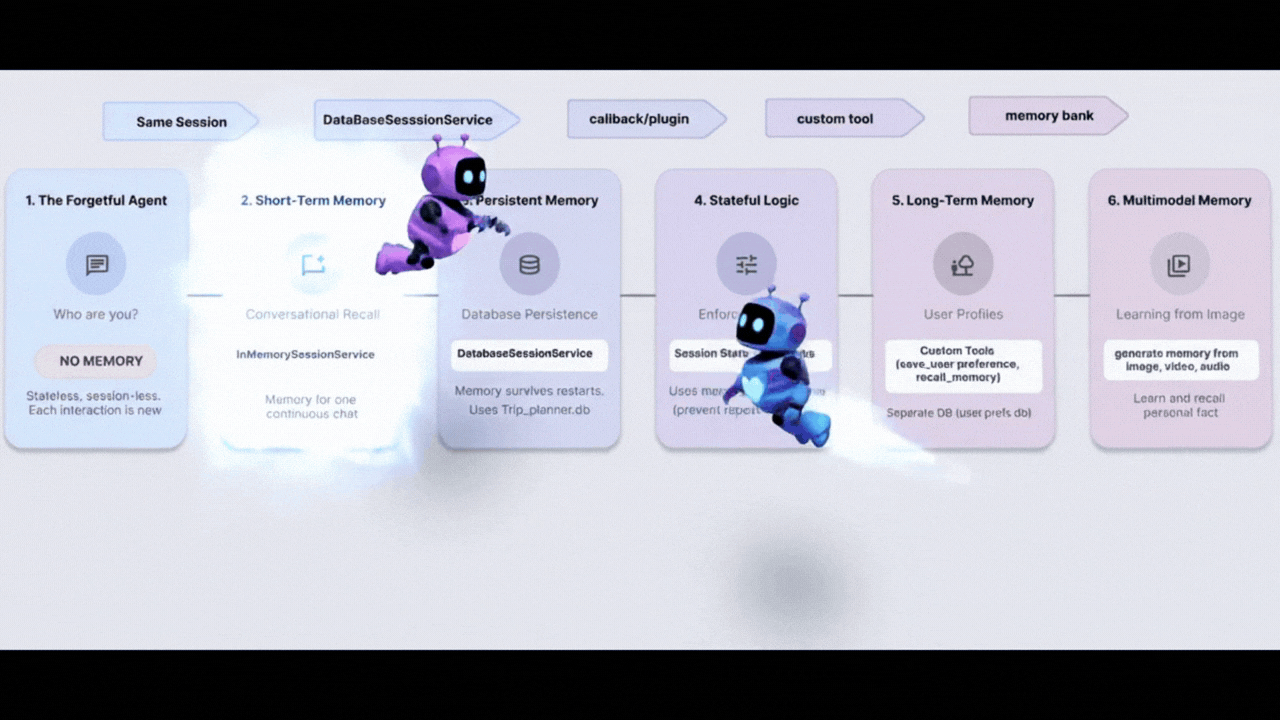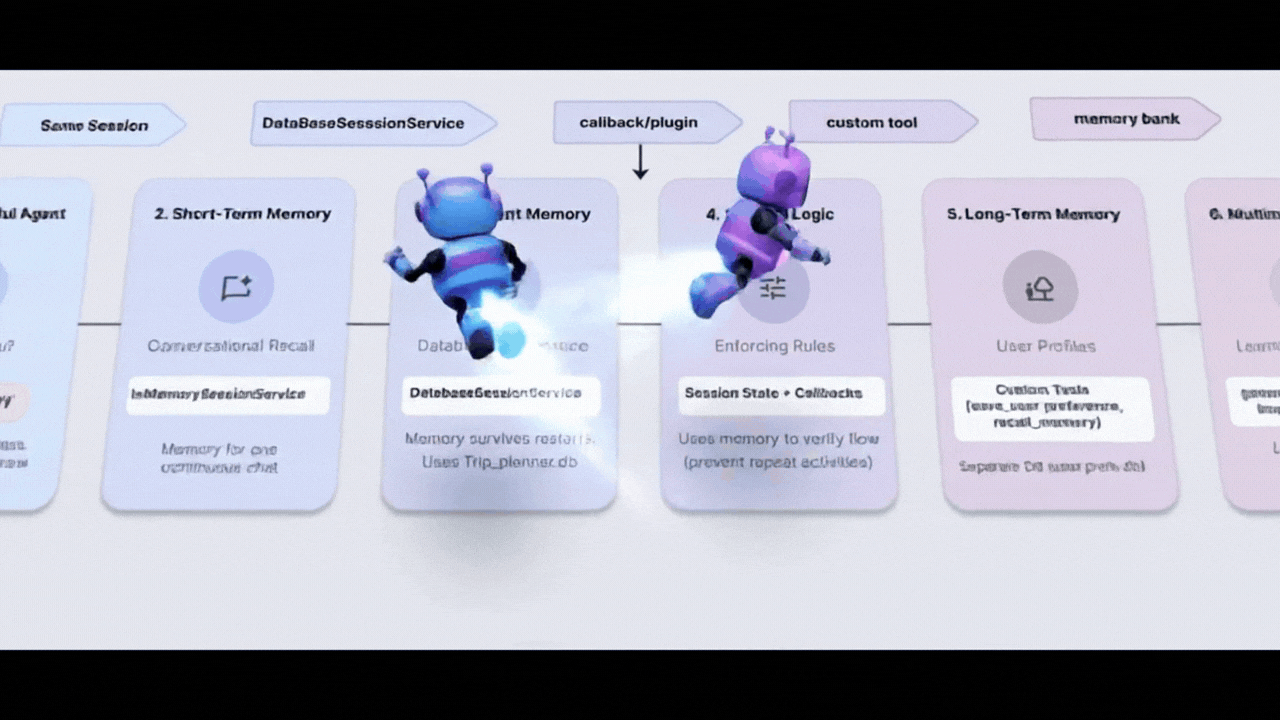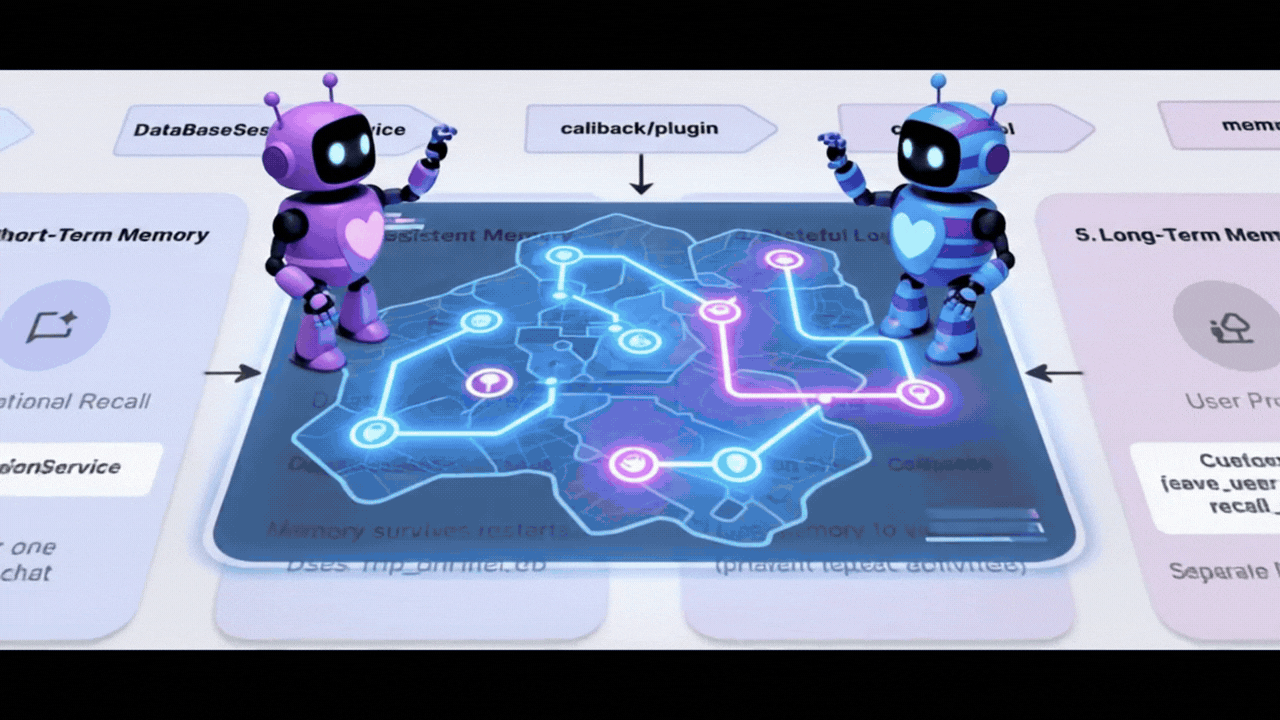
このワークショップでは、記憶、学習、適応が可能な旅行代理店を構築することで、ゴールドフィッシュ問題を解決します。エージェント メモリの 6 つのレベルを順に学習し、chatbot ではなく、専用のパーソナル アシスタントのように動作するシステムを作成します。
レベル | コンセプト | 「スーパーパワー」 |
レベル 1 | セッションと状態 | 会話を忘れることなく続ける |
レベル 2 | マルチエージェントの状態 | チームメンバー間でのメモの共有 |
レベル 3 | 永続性 | システムの再起動後もユーザーを記憶 |
レベル 4 | コールバック | メモリを完全に自律的に更新する |
レベル 5 | カスタムツール | 構造化されたユーザー プロフィールの読み取りと書き込み |
レベル 6 | マルチモーダル メモリ | 写真や動画を「見て」記憶する |
ADK メモリー スタック
コードを記述する前に、使用するツールについて理解しておきましょう。Google Agent Development Kit(ADK)は、メモリを処理するための構造化された方法を提供します。
- セッション: 会話のコンテナ。これまでの会話の履歴が保持されます。
- 状態: セッションにアタッチされた Key-Value の「スクラッチパッド」。エージェントは、これを使用して特定の事実(
destination="Tokyo"など)を保存します。 - MemoryService: 長期保存。ユーザー設定や分析済みドキュメントなど、永続的に保持するものをここに保存します。
2. 設定
AI エージェントを強化するには、基盤となる Google Cloud プロジェクトと、
パート 1: 請求先アカウントを有効にする
この Codelab を実行するには、クレジットのある請求先アカウントが必要です。この Codelab の上部にあるバナーのクレジットを使用して開始します。すでに請求先アカウントに接続している場合は、この手順をスキップできます。
パート 2: オープンな環境
- 👉 このリンクをクリックして、Cloud Shell エディタに直接移動します。
- 👉 本日、承認を求められた場合は、[承認] をクリックして続行します。
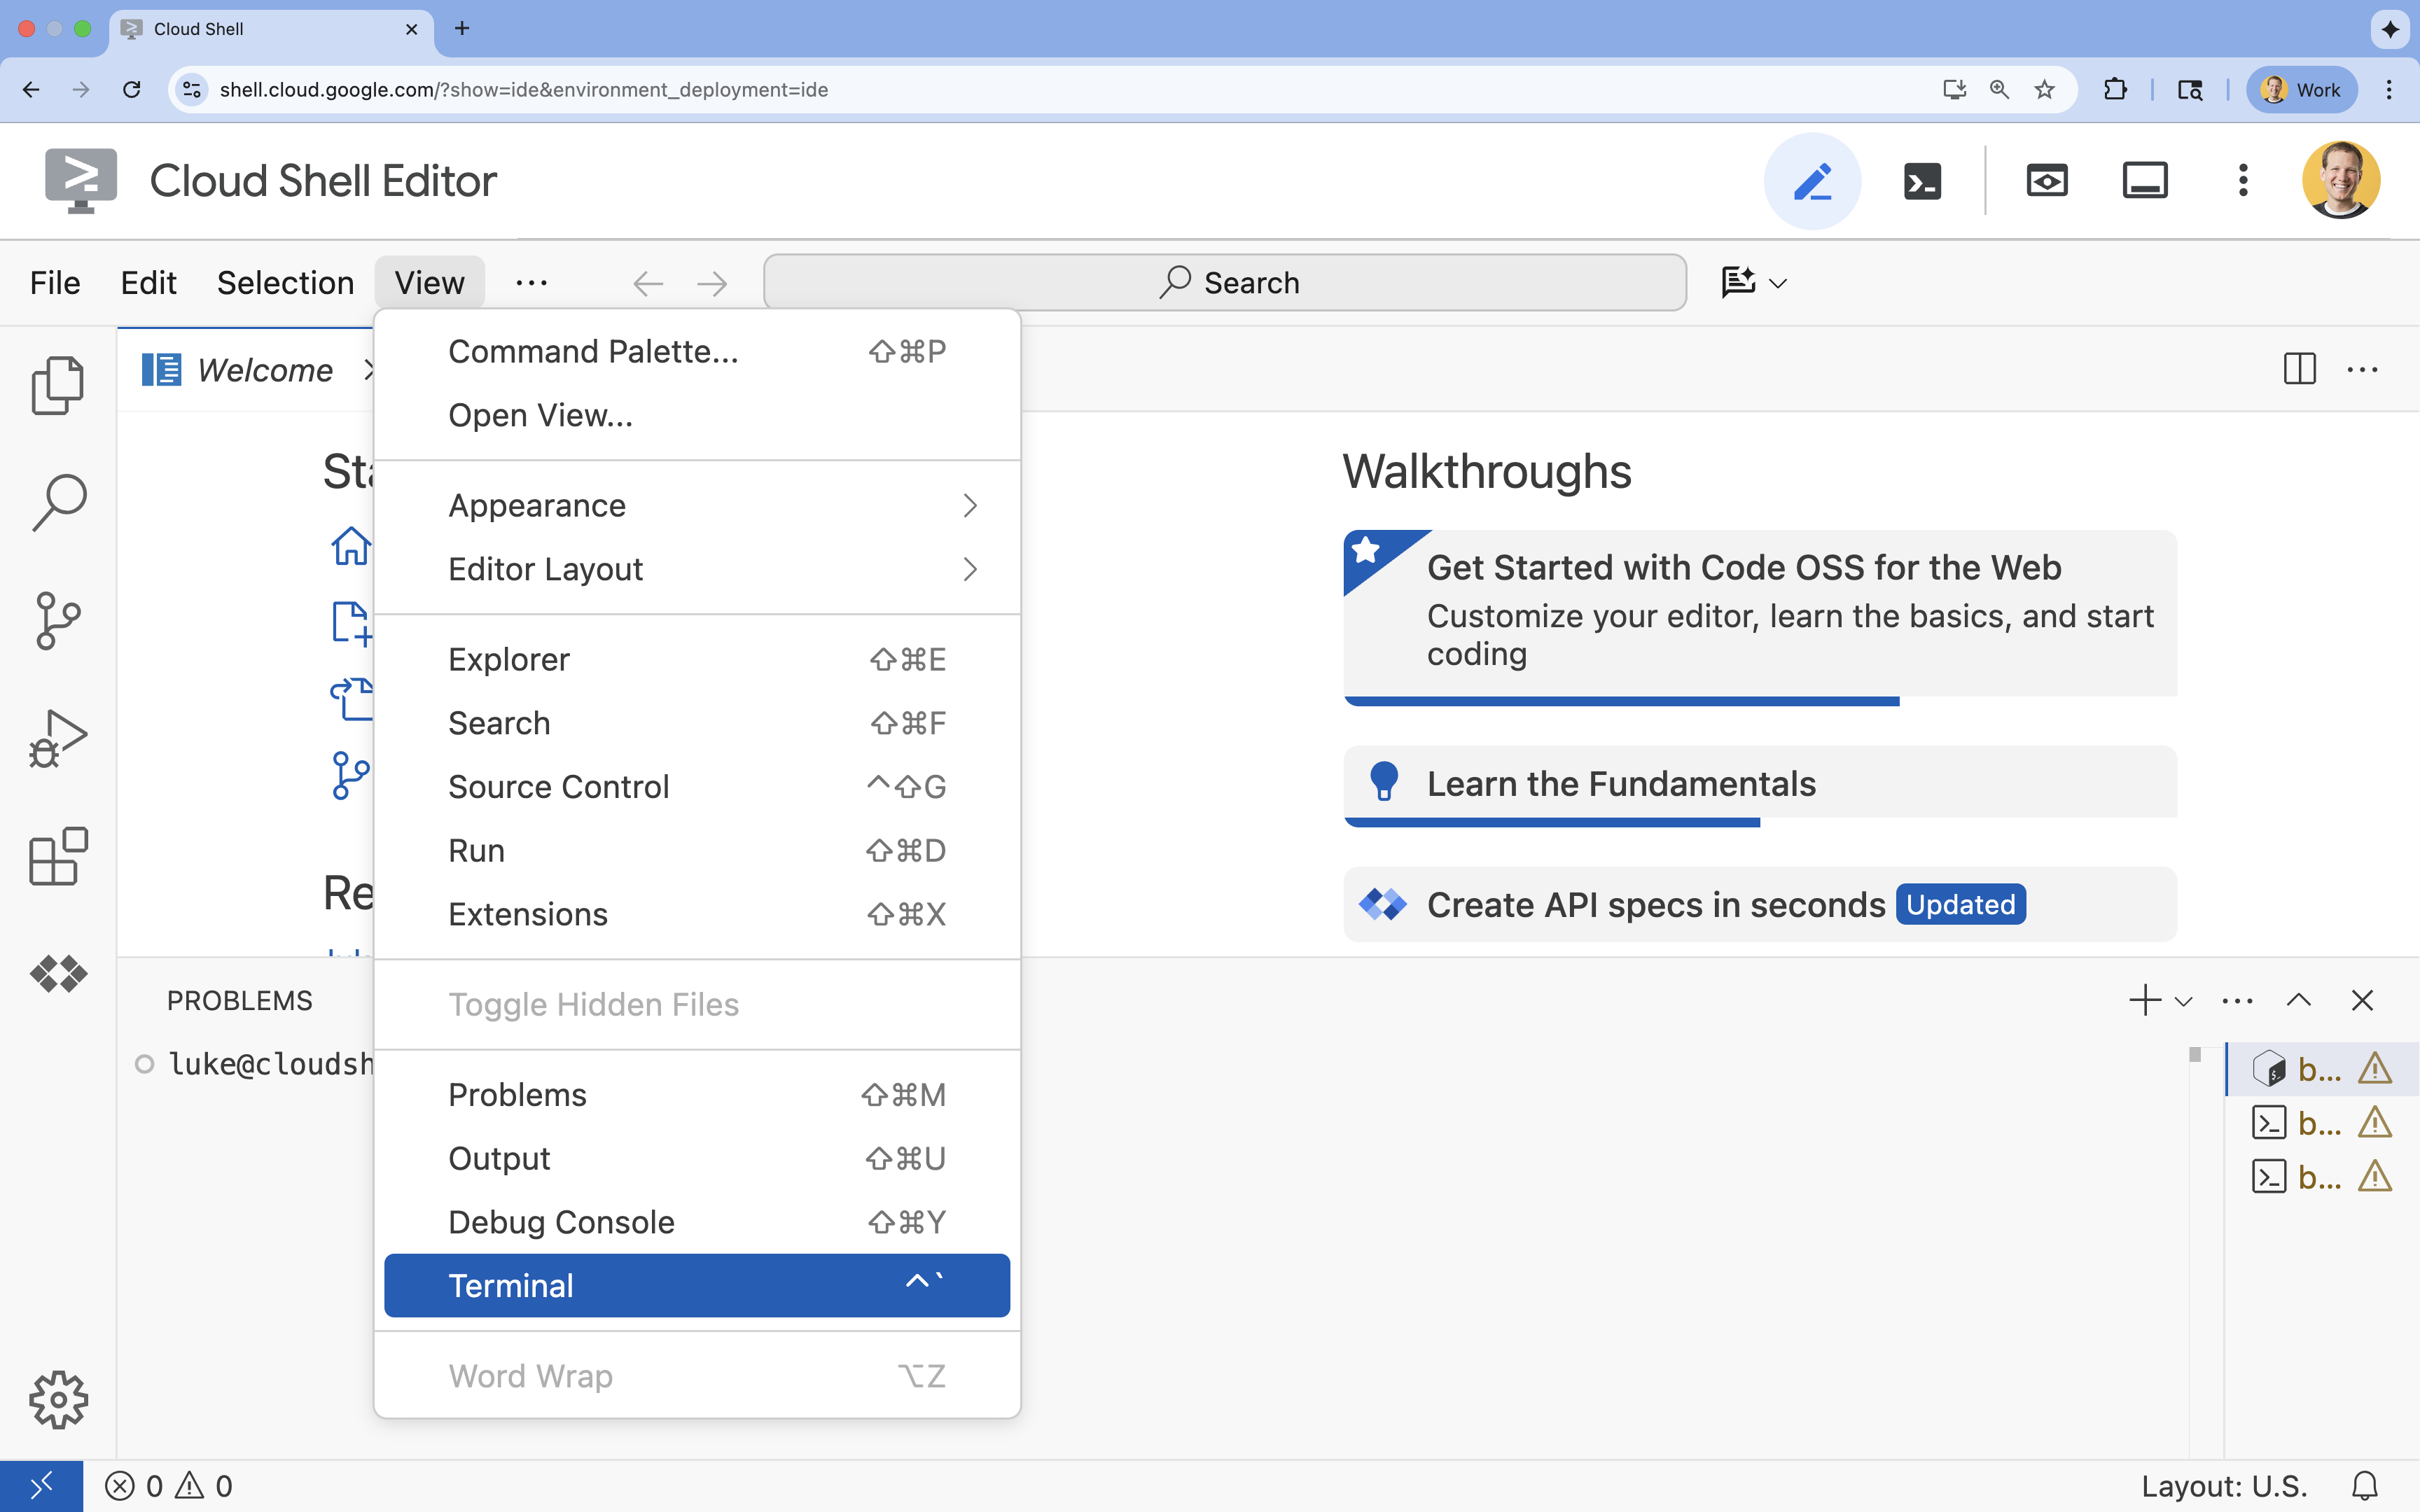
- 👉 画面の下部にターミナルが表示されない場合は、次の手順で開きます。
- [表示] をクリックします。
- [Terminal] をクリックします。
- 👉💻 ターミナルで、次のコマンドを使用して、すでに認証済みであることと、プロジェクトがプロジェクト ID に設定されていることを確認します。
gcloud auth list - 👉💻 GitHub からブートストラップ プロジェクトのクローンを作成します。
git clone https://github.com/cuppibla/memory_agent_starter - 👉💻 プロジェクト ディレクトリから設定スクリプトを実行します。
cd ~/memory_agent_starter ./init.sh - 👉💻 必要なプロジェクト ID を設定します。
gcloud config set project $(cat ~/project_id.txt) --quiet
パート 3: 権限の設定
- 👉💻 次のコマンドを使用して、必要な API を有効にします。これには数分かかることがあります。
gcloud services enable \ cloudresourcemanager.googleapis.com \ servicenetworking.googleapis.com \ run.googleapis.com \ aiplatform.googleapis.com \ compute.googleapis.com - 👉💻 ターミナルで次のコマンドを実行して、必要な権限を付与します。
. ~/memory_agent_starter/set_env.sh
.env ファイルが作成されていることを確認します。プロジェクト情報が表示されます。
3. 基盤 - セッションと状態
コンセプト: コンテキストが重要
最も基本的なメモリはセッション メモリです。これにより、エージェントは「それを買いたい」という文の「それ」が、10 秒前に話していた靴を指していることを認識できます。
ADK では、これを Session オブジェクトで管理します。
- ステートレス アプローチ: メッセージごとに新しいセッションを作成します。
- ステートフルなアプローチ: 1 つのセッションを作成し、会話全体で再利用します。
ステップ 1: エージェントを調べる
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/01_session_agent/agent.py
~/memory_agent_starter/01_session_agent/agent.py を開きます。
👉 agent.py 関数内のコメント # TODO: Create a root agent を見つけます。
この行全体を次のコードに置き換えます。
root_agent = LlmAgent(
    name="multi_day_trip_agent",
    model="gemini-2.5-flash",
    description="Agent that progressively plans a multi-day trip, remembering previous days and adapting to user feedback.",
    instruction="""
    You are the "Adaptive Trip Planner" 🗺️ - an AI assistant that builds multi-day travel itineraries step-by-step.

    Your Defining Feature:
    You have short-term memory. You MUST refer back to our conversation to understand the trip's context, what has already been planned, and the user's preferences. If the user asks for a change, you must adapt the plan while keeping the unchanged parts consistent.

    Your Mission:
    1.  **Initiate**: Start by asking for the destination, trip duration, and interests.
    2.  **Plan Progressively**: Plan ONLY ONE DAY at a time. After presenting a plan, ask for confirmation.
    3.  **Handle Feedback**: If a user dislikes a suggestion (e.g., "I don't like museums"), acknowledge their feedback, and provide a *new, alternative* suggestion for that time slot that still fits the overall theme.
    4.  **Maintain Context**: For each new day, ensure the activities are unique and build logically on the previous days. Do not suggest the same things repeatedly.
    5.  **Final Output**: Return each day's itinerary in MARKDOWN format.
    """,
    tools=[google_search]
)
この指示は LLM に記憶するよう指示していますが、コードは記憶する機能を提供する必要があります。
ステップ 2: 2 つのシナリオ
~/memory_agent_starter/01_session_agent/main.py を開きます。
👉 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/01_session_agent/main.py
~/memory_agent_starter/01_session_agent/main.py を開き、main.py 関数内のコメント # TODO: Create a runner with in memorysession service を見つけます。
この行全体を次のコードに置き換えます。
    runner = Runner(
        agent=agent,
        session_service=session_service,
        app_name=agent.name
    )
👉 main.py 関数内のコメント # TODO: create a different session to test を見つけます。
この行全体を次のコードに置き換えます。
    tokyo_session_2 = await session_service.create_session(
        app_name=multi_day_agent.name,
        user_id=user_id
    )
テスト
「金魚」と「象」の記憶の違いを示す 2 つの関数があります。
シナリオ 1: ステートフル(共有セッション)
async def run_trip_same_session_scenario(session_service, user_id):
    # 1. Create ONE session
    trip_session = await session_service.create_session(...)

    # 2. Turn 1
    await run_agent_query(..., trip_session, ...)

    # 3. Turn 2 - REUSING the same session!
    # The agent can "see" Turn 1 because it's in the session history.
    await run_agent_query(..., trip_session, ...)
シナリオ 2: ステートレス(毎回新しいセッション)
async def run_trip_different_session_scenario(session_service, user_id):
    # Turn 1
    tokyo_session = await session_service.create_session(...)
    await run_agent_query(..., tokyo_session, ...)

    # Turn 2 - Creating a FREASH session
    # The agent has NO IDEA what happened in Turn 1.
    tokyo_session_2 = await session_service.create_session(...)
    await run_agent_query(..., tokyo_session_2, ...)
ステップ 3: エージェントを実行する
違いを実際に見てみましょう。スクリプトを実行します。
👉💻 コマンドラインで、次のコマンドを実行します。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/01_session_agent/main.py
シナリオ 1 を確認する: エージェントは最初のメッセージからユーザーの好みを記憶し、2 番目のメッセージでプランを調整します。
シナリオ 2 を確認する: 2 回目のターン(「私が料理の何が気に入ったか覚えていますか?」)では、新しいセッションであるため、エージェントは完全に失敗します。これは実質的に「何のことかわからない」と言っているようなものです。
主なポイント
メモリのルール 1: 会話のコンテキストを維持するために、常に session.id を再利用します。Session オブジェクトは、エージェントの短期メモリバッファです。
4. チーム - マルチエージェントの状態
コンセプト: 「伝言ゲーム」
複数のエージェントが連携して機能する場合、エージェントはファイル フォルダをやり取りする同僚のようなものです。1 つのエージェントがフォルダにメモを書き込むと、次のエージェントがそれを読み取ることができます。
ADK では、この「フォルダ」が状態です。
- 状態は、セッション内に存在する辞書(
{"key": "value"})です。 - セッション内のエージェントは、このメモの読み取りと書き込みを行うことができます。
ステップ 1: ワークフローを調べる
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/02_multi_agent/agent.py
👉~/memory_agent_starter/02_multi_agent/agent.py ファイルで、コメント # TODO: foodie agent を見つけます。
この行全体を次のコードに置き換えます。
foodie_agent = LlmAgent(
    name="foodie_agent",
    model="gemini-2.5-flash",
    tools=[google_search],
    instruction="""You are an expert food critic. Your goal is to find the best restaurant based on a user's request.

    When you recommend a place, you must output *only* the name of the establishment and nothing else.
    For example, if the best sushi is at 'Jin Sho', you should output only: Jin Sho
    """,
    output_key="destination"  # ADK will save the agent's final response to state['destination']
)
👉 agent.py 関数内のコメント # TODO: transportation agent を見つけます。
この行全体を次のコードに置き換えます。
transportation_agent = LlmAgent(
    name="transportation_agent",
    model="gemini-2.5-flash",
    tools=[google_search],
    instruction="""You are a navigation assistant. Given a destination, provide clear directions.
    The user wants to go to: {destination}.

    Analyze the user's full original query to find their starting point.
    Then, provide clear directions from that starting point to {destination}.
    """,
)
👉 agent.py 関数内のコメント # TODO: root_agent を見つけます。
この行全体を次のコードに置き換えます。
root_agent = SequentialAgent(
    name="find_and_navigate_agent",
    sub_agents=[foodie_agent, transportation_agent],
    description="A workflow that first finds a location and then provides directions to it."
)
これで、2 つのエージェントが順番に動作するようになりました。
- Foodie Agent: レストランを検索します。
- 交通エージェント: そのレストランへの道案内を提供します。
マジック ハンドオフ: foodie_agent が transportation_agent にバトンを渡す方法に注目してください。
foodie_agent = LlmAgent(
    # ...
    # CRITICAL: This tells ADK to save the agent's output to state['destination']
    output_key="destination"
)

transportation_agent = LlmAgent(
    # ...
    # CRITICAL: This injects state['destination'] into the prompt
    instruction="""
    The user wants to go to: {destination}.
    Provide clear directions...
    """,
)
output_key="destination": Foodie Agent の回答が効率的に保存されます。{destination}: 交通機関エージェントがその回答を自動的に読み上げます。
(対応は不要)ステップ 2: オーケストレーター
02_multi_agent/main.py を開きます。
SequentialAgent を使用して、これらを順番に実行します。
# 1. Create a single session for the sequential agent
session = await session_service.create_session(...)

# 2. Run the query
# The SequentialAgent manages the state flow:
# Query -> Foodie -> state['destination'] -> Transportation -> Final Answer
await run_agent_query(root_agent, query, ...)
ユーザーが 1 つのプロンプトを送信します。
"Find best sushi in Palo Alto and then tell me how to get there."
エージェントは連携して回答します。
ステップ 3: チームを実行する
👉💻 Cloud Shell ターミナルで、マルチエージェント ワークフローを実行します。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/02_multi_agent/main.py
どうなるでしょうか
- Foodie Agent: 「Jin Sho」(または類似のレストラン)を見つけます。
- ADK: 「Jin Sho」を
state['destination']に保存します。 - 交通エージェント: 指示で「Jin Sho」を受け取ります。
- 結果: 「Caltrain 駅から Jin Sho に行くには、University Ave を歩いて...」
主なポイント
メモリのルール 2: 状態を使用して、エージェント間で構造化された情報を渡します。書き込みには output_key を、読み取りには {placeholders} を使用します。
5. 再起動 - 永続性
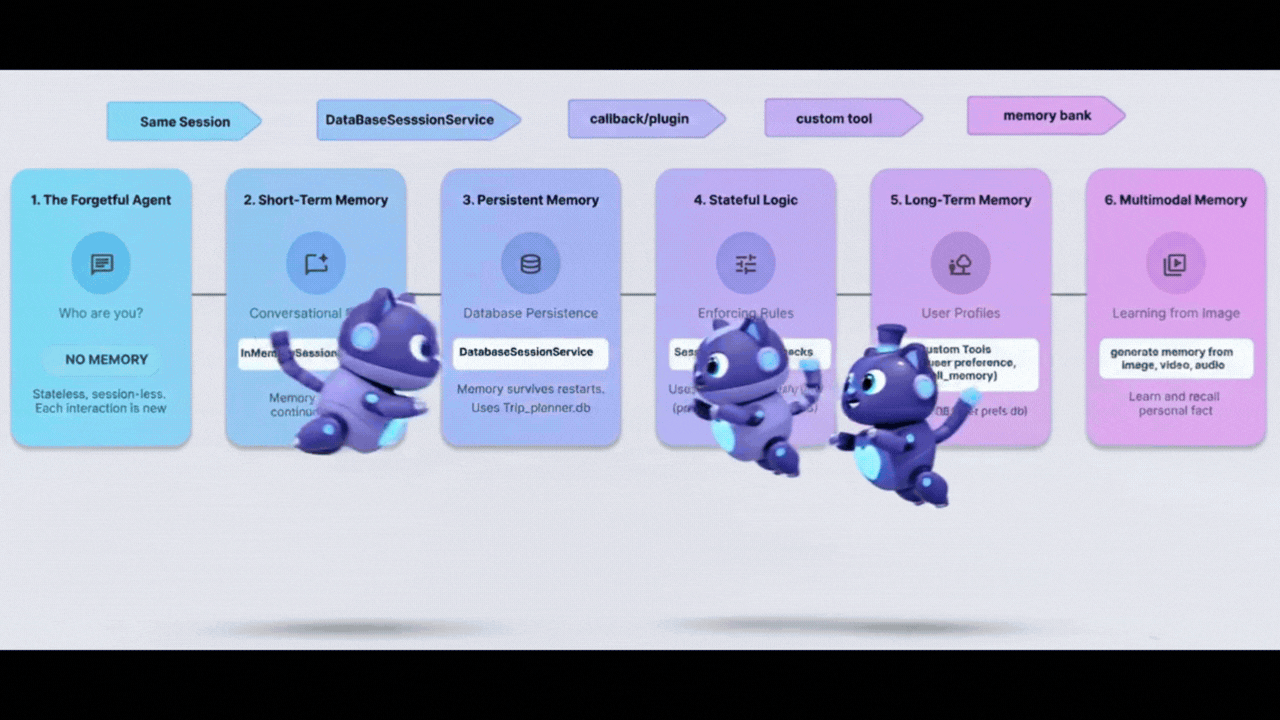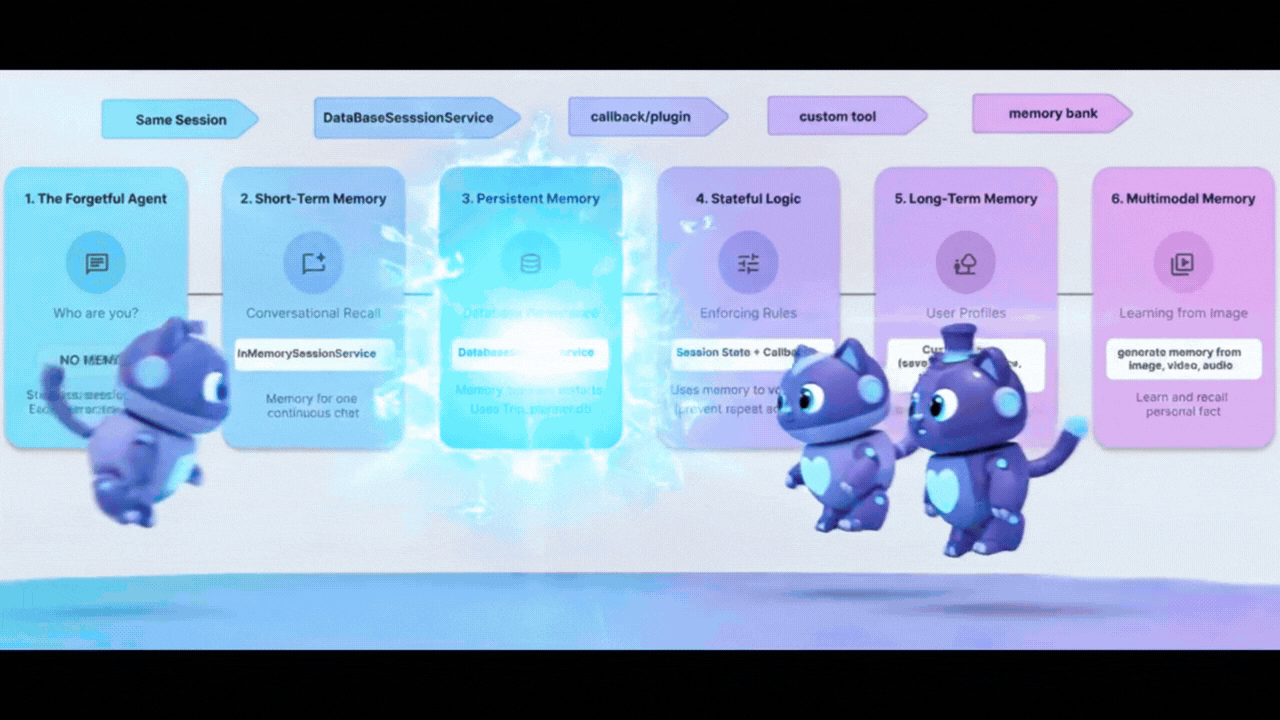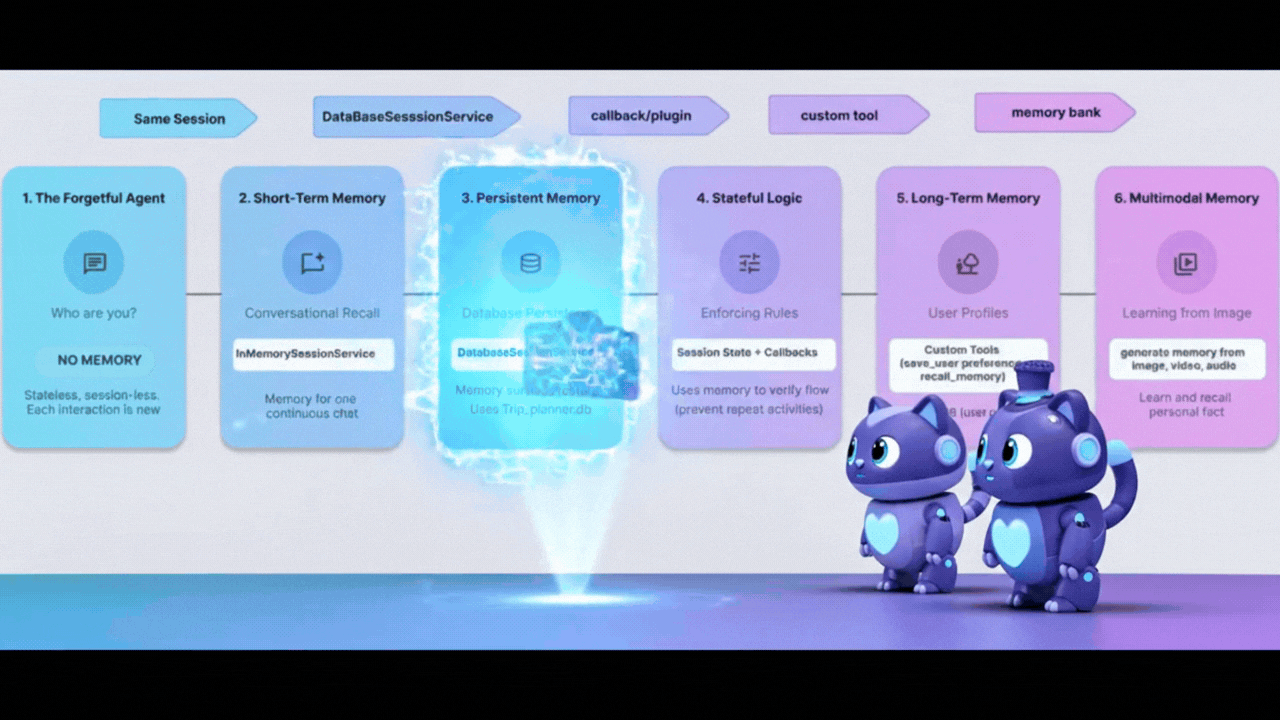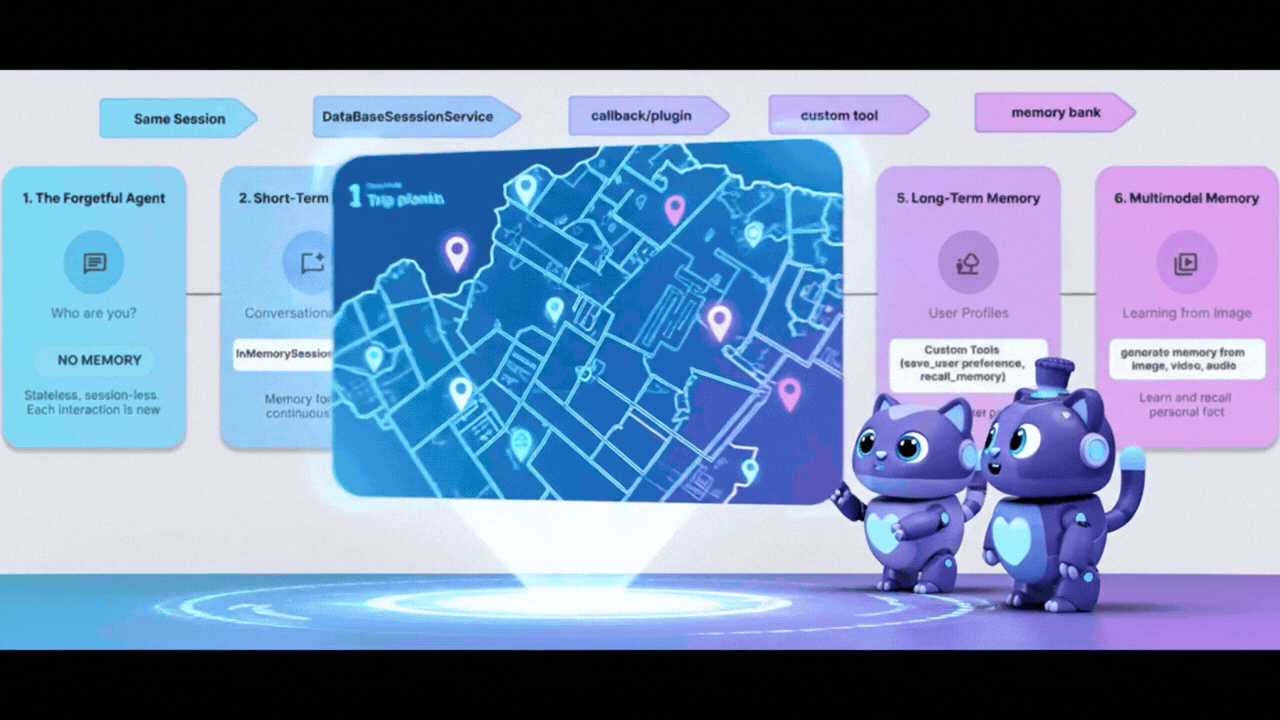
コンセプト: 「再起動の問題」
これまでのところ、メモリは InMemory です。スクリプトを停止して再起動すると、エージェントはすべてを忘れます。これは、電源を切るたびにハードドライブを消去するパソコンのようなものです。
これを解決するには、永続性が必要です。InMemorySessionService を DatabaseSessionService に交換します。
ステップ 1: データベースの切り替え
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/03_persistent_agent/main.py
👉 ~/memory_agent_starter/03_persistent_agent/main.py ファイルで、コメント # TODO: Configuration for Persistent Sessions を見つけます。
この行全体を次のコードに置き換えます。
SESSIONS_DIR = Path(os.path.expanduser("~")) / ".adk_codelab" / "sessions"
os.makedirs(SESSIONS_DIR, exist_ok=True)
SESSION_DB_FILE = SESSIONS_DIR / "trip_planner.db"
SESSION_URL = f"sqlite:///{SESSION_DB_FILE}"
これで、すべてのセッションとイベントが SQLite ファイルに保存されるようになります。
ステップ 2: セッションをまたいだ検索
永続性により、会話を再開するだけでなく、過去の会話から学習することもできます。
同じファイル ~/memory_agent_starter/03_persistent_agent/main.py で、テストケース 3: セッションをまたいだ取得を確認します。
👉 コメント # TODO: retrieve the previous session manually を探します。
この行全体を次のコードに置き換えます。
    old_session = await session_service.get_session(
        app_name=root_agent.name, user_id="user_01", session_id=session_id
    )
👉 main.py 関数内のコメント # TODO: Extract content from the OLD session を見つけます。
この行全体を次のコードに置き換えます。
previous_context += f"- {role}: {text}\n"
👉 main.py 関数内のコメント # TODO: Manually inject the context to the query を見つけます。
この行全体を次のコードに置き換えます。
    query_3 = f"""
    {previous_context}

    I'm planning a new trip to Osaka this time.
    Based on my previous preferences (above), what should I eat?
    """
これにより、ユーザーが数か月後に戻ってきた状況をシミュレートできます。古い履歴を取得できるのはデータベースのみです。
ステップ 3: 再起動後も維持する
👉💻 ターミナルで、次のスクリプトを実行します。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/03_persistent_agent/main.py
~/memory_agent_starter/trip_planner.db ファイルが作成されます。試してみる: スクリプトを 2 回実行します。
- 2 回目の実行では、「Resumed existing session」を探します。
- エージェントはデータベース ファイルから読み込むため、最初の実行時のコンテキストを記憶しています。
主なポイント
メモリのルール 3: 生成にはDatabaseSessionServiceを使用します。これにより、サーバーが再起動してもユーザーの会話が保持され、長期的な履歴分析が可能になります。
6. スパイ - コールバック
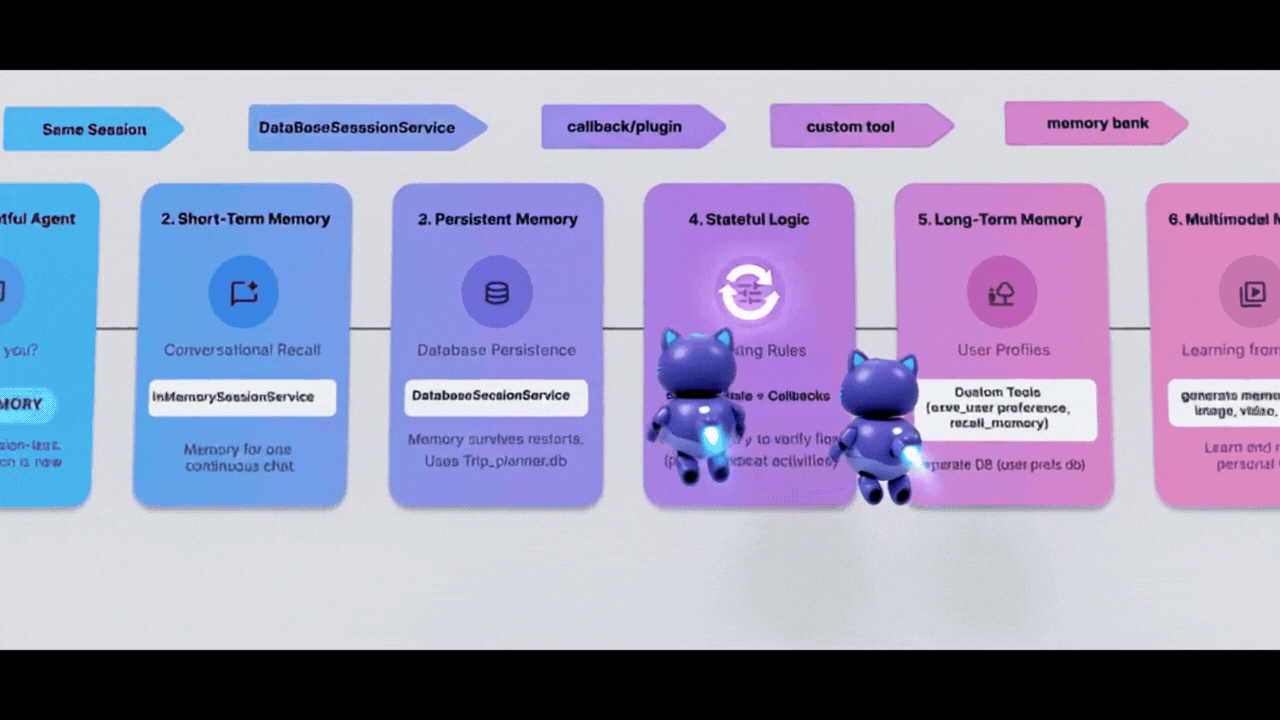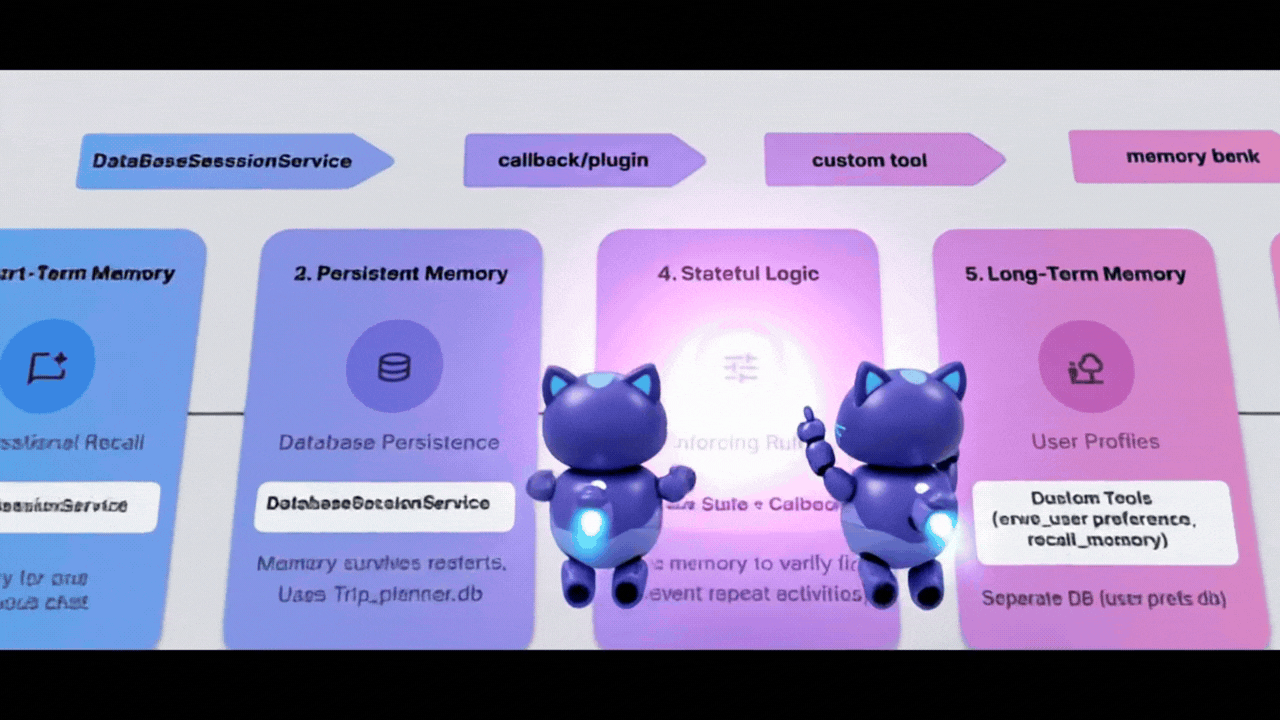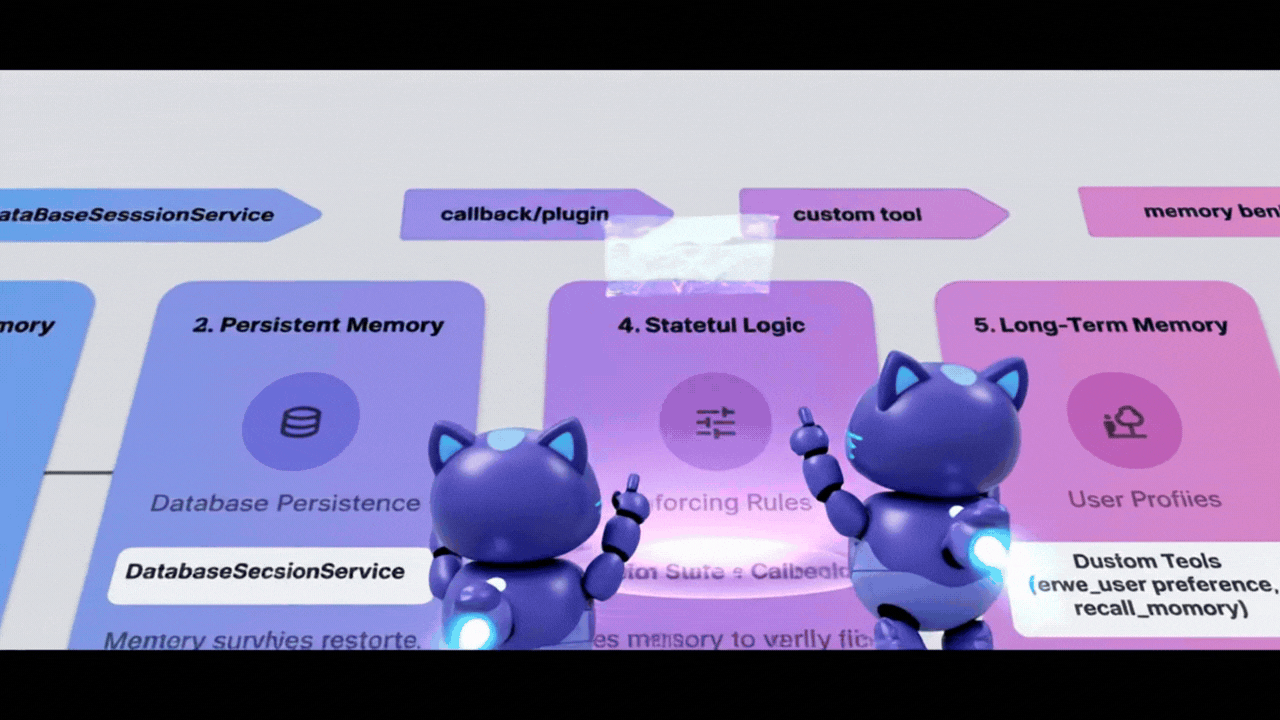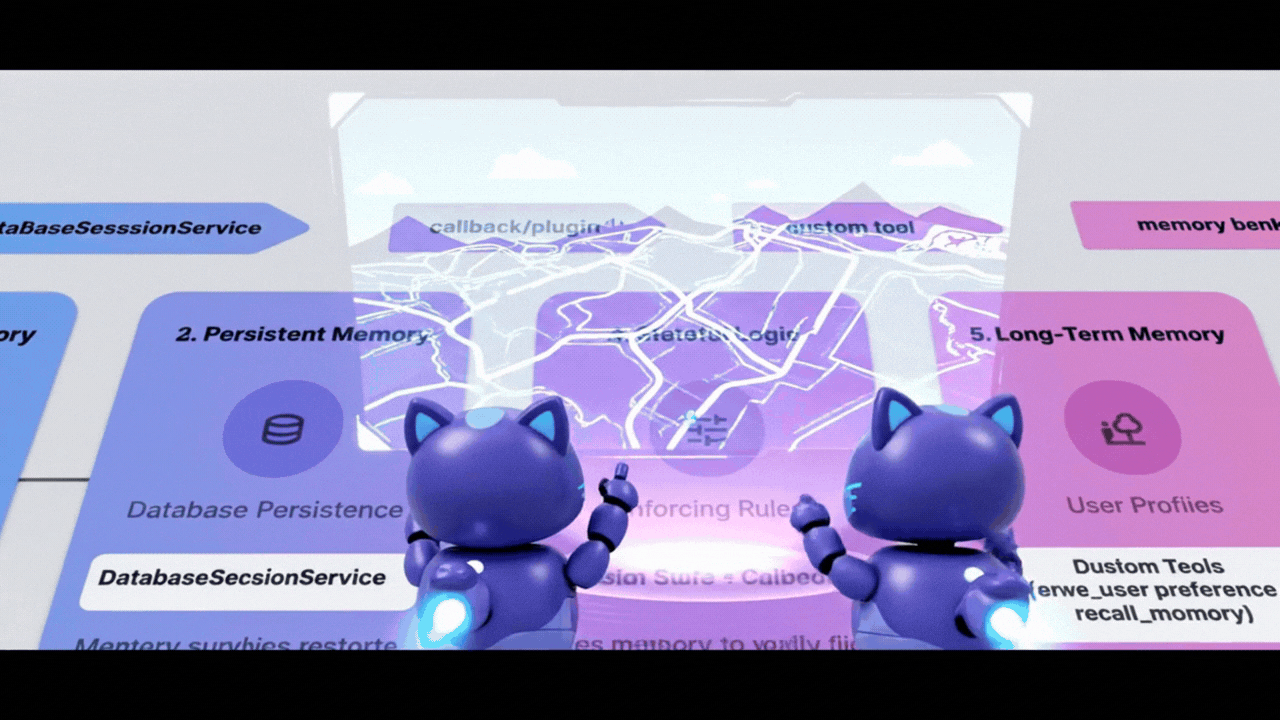
エージェントが言うことだけでなく、エージェントの動作に基づいて、メモリを自動的に更新する必要がある場合があります。エージェントを監視してメモを取る「スパイ」が必要です。
ADK では、このスパイがコールバックです。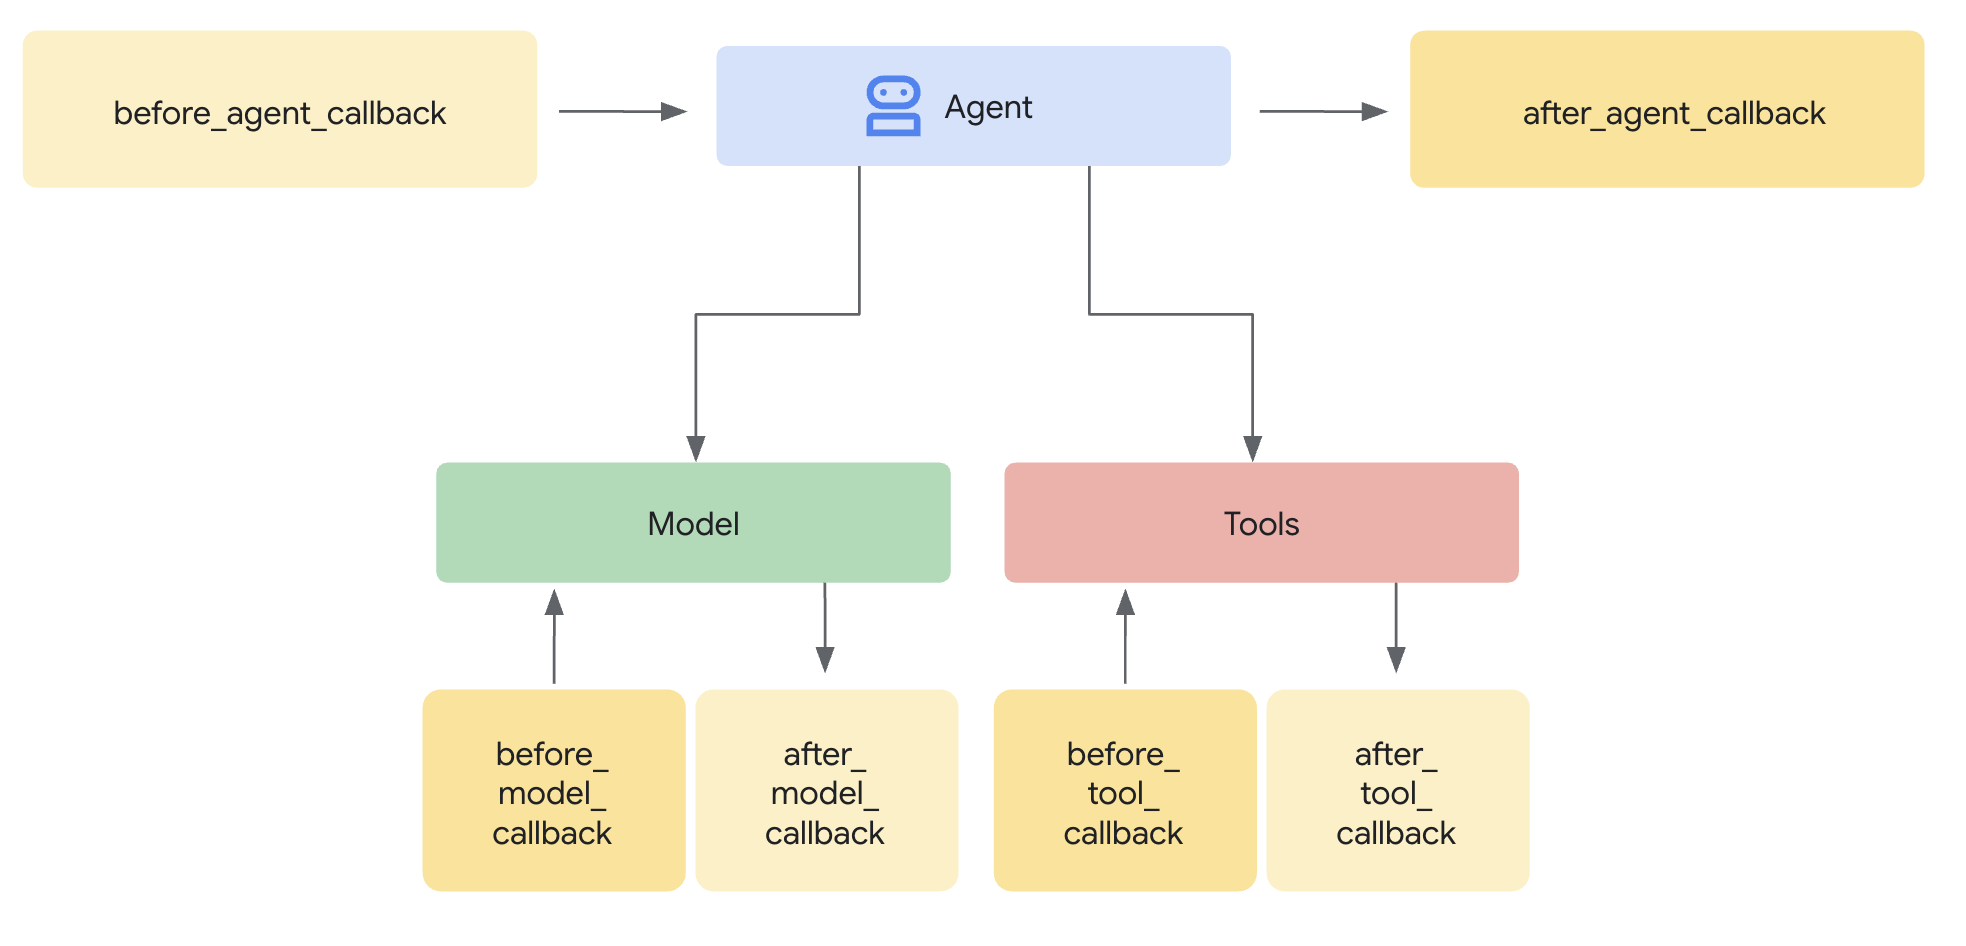
after_tool_callback: エージェントが動作するたびに実行される関数。ToolContext: その関数内から State に書き込む方法。
ステップ 1: ロジック
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/04_stateful_agent/agent.py
👉 ~/memory_agent_starter/04_stateful_agent/agent.py ファイルで、# TODO: Implement call back logic というコメントを見つけます。
この行全体を次のコードに置き換えます。
def save_activity_type_callback(
    tool,
    args: Dict[str, Any],
    tool_context: ToolContext,
    tool_response: Dict[str, Any],
) -> Optional[Dict[str, Any]]:
    """
    Callback to save the TYPE of activity just planned into the session state.
    """
    # 1. Get the actual agent name.
    if tool.name == "transfer_to_agent":
         agent_name = args.get("agent_name")
    else:
         agent_name = tool.name

    activity_type = "unknown"

    # 2. Determine the type based on which agent was actually used
    if agent_name == "museum_expert":
        activity_type = "CULTURAL"
    elif agent_name == "restaurant_expert":
        activity_type = "FOOD"
    elif agent_name == "outdoor_expert":
        activity_type = "OUTDOOR"

    print(f"\n🔔 [CALLBACK] The planner transferred to '{agent_name}'.")

    # 3. Update the state directly
    tool_context.state["last_activity_type"] = activity_type
    print(f"💾 [STATE UPDATE] 'last_activity_type' is now set to: {activity_type}\n")

    return tool_response
👉 同じファイルで、04_stateful_agent/agent.py 関数内のコメント # TODO: add callback to root agent を見つけます。
この行全体を次のコードに置き換えます。
after_tool_callback=save_activity_type_callback,
動的な指示: エージェントの指示は、文字列ではなく関数になりました。状態に基づいて変化します。
def get_planner_instruction(context):
    last_activity = context.state.get("last_activity_type", "None")

    return f"""
    The last activity was: {last_activity}

    If last_activity is 'CULTURAL' -> `museum_expert` is BANNED.
    """
ステップ 3: Spy をテストする
👉💻 ターミナルで、以下のコマンドをコピーして貼り付け、スクリプトを実行します。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/04_stateful_agent/main.py
このエージェントを実行すると、ループが表示されます。
- ターン 1: 博物館をリクエストします。スパイセット
last_activity="CULTURAL"。 - ターン 2: 別の美術館をリクエストします。
- エージェントへの指示の更新: 「CULTURAL は禁止」
- エージェント: 「もう美術館はいいよ。公園はどう?」
[CALLBACK] と [STATE UPDATE] のコンソールログを確認します。エージェントの動作に合わせて、メモリがリアルタイムで変化していることがわかります。
主なポイント
メモリのルール 4: コールバックを使用して状態管理を自動化する。エージェントは、単にジョブを実行するだけで独自のコンテキストを構築します。
7. ファイル キャビネット - カスタムツール
コンセプト: 「構造化メモリ」
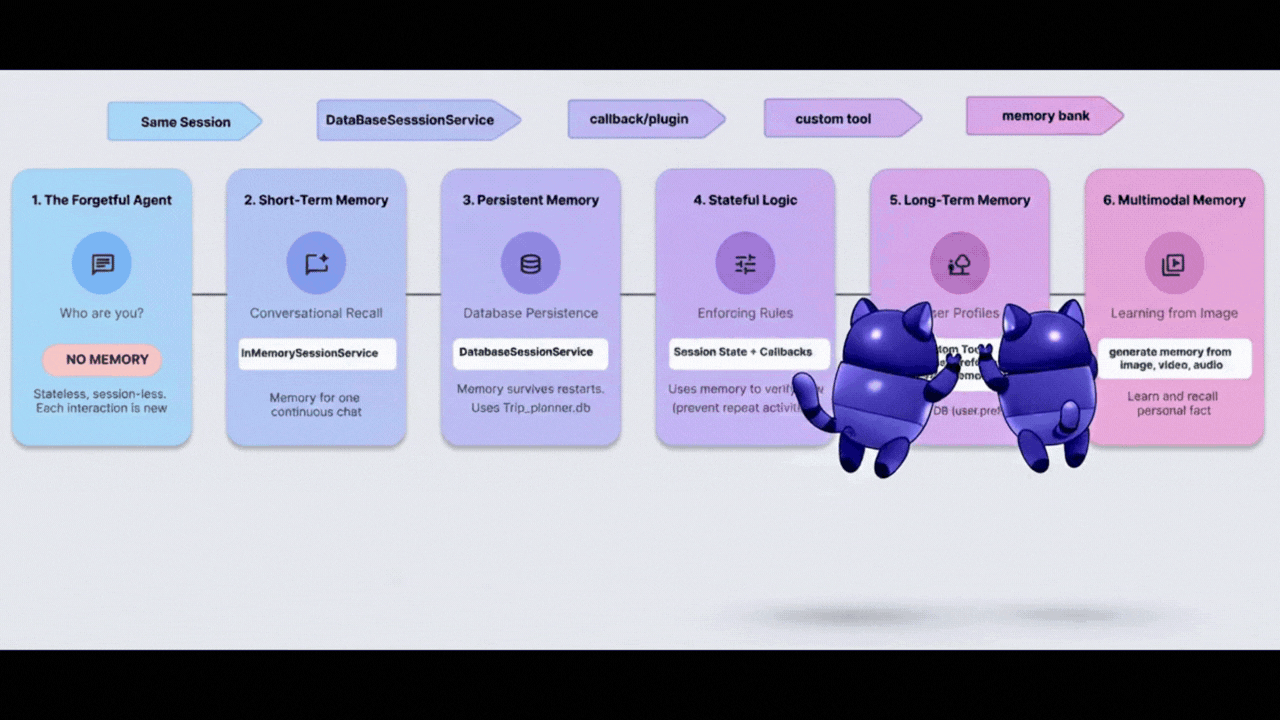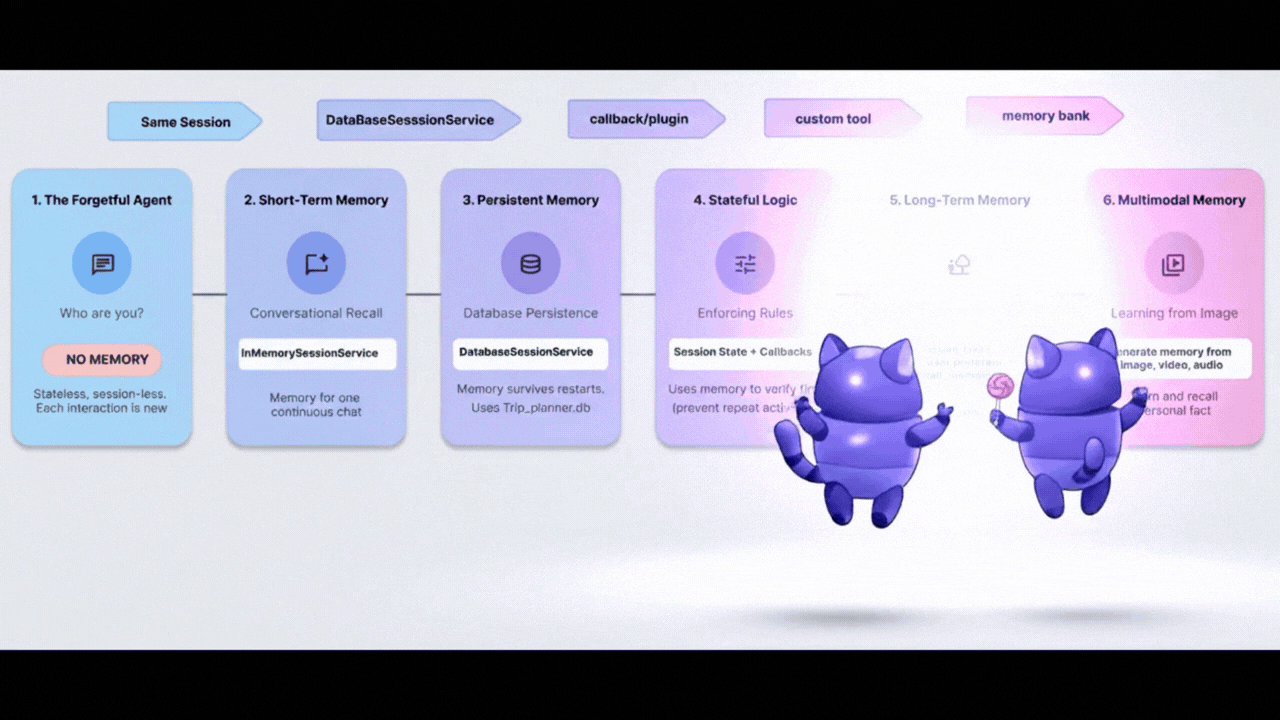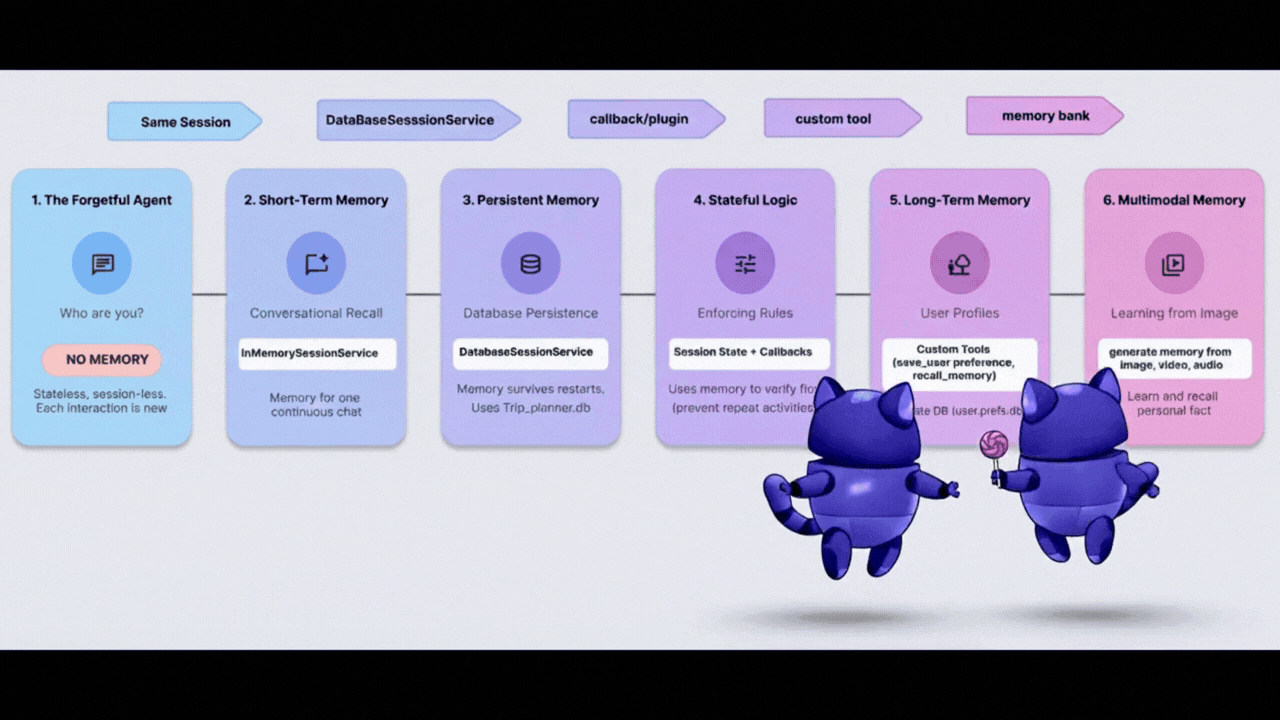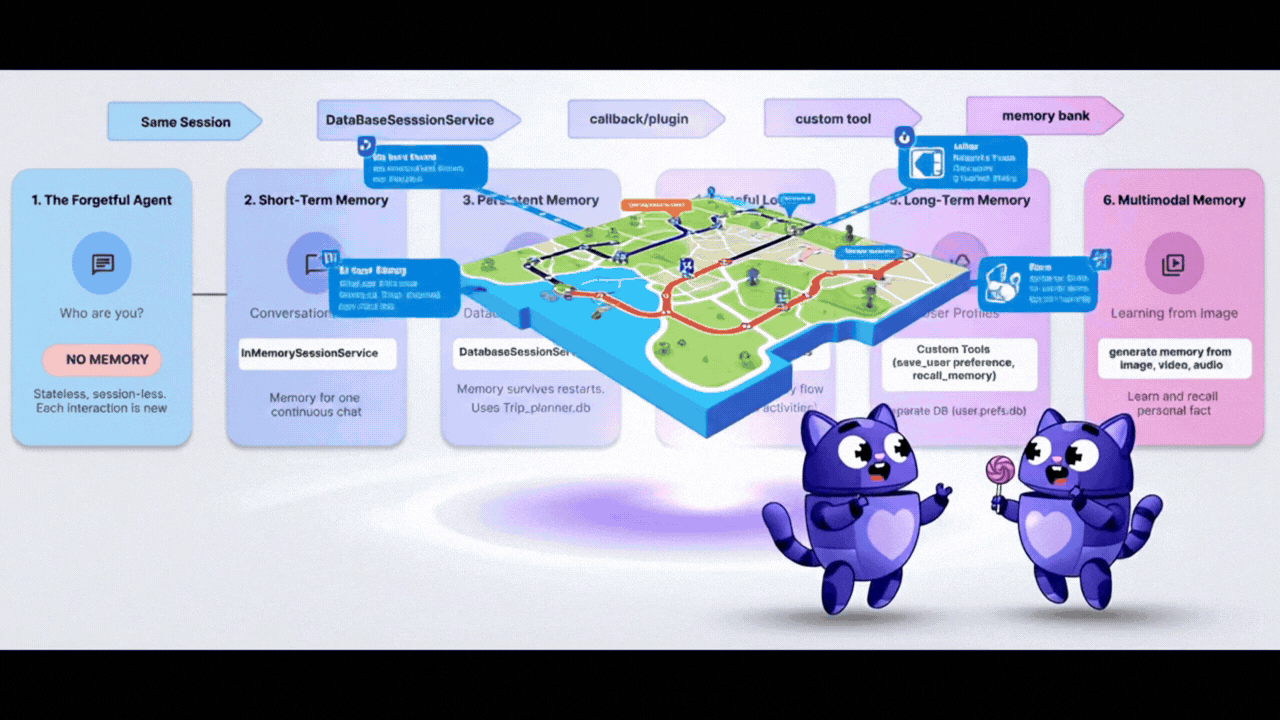
これまでの「メモリ」は、チャットログや単純な Key-Value ペアでした。しかし、複雑なユーザー プロファイル(diet: vegan, budget: high, pets: [cat, dog] など)を記憶する必要がある場合はどうすればよいでしょうか。
このため、メモリをツールとして扱います。エージェントは、ファイル キャビネットを開く(読み取り)タイミングと、レポートを提出する(書き込み)タイミングを明示的に決定します。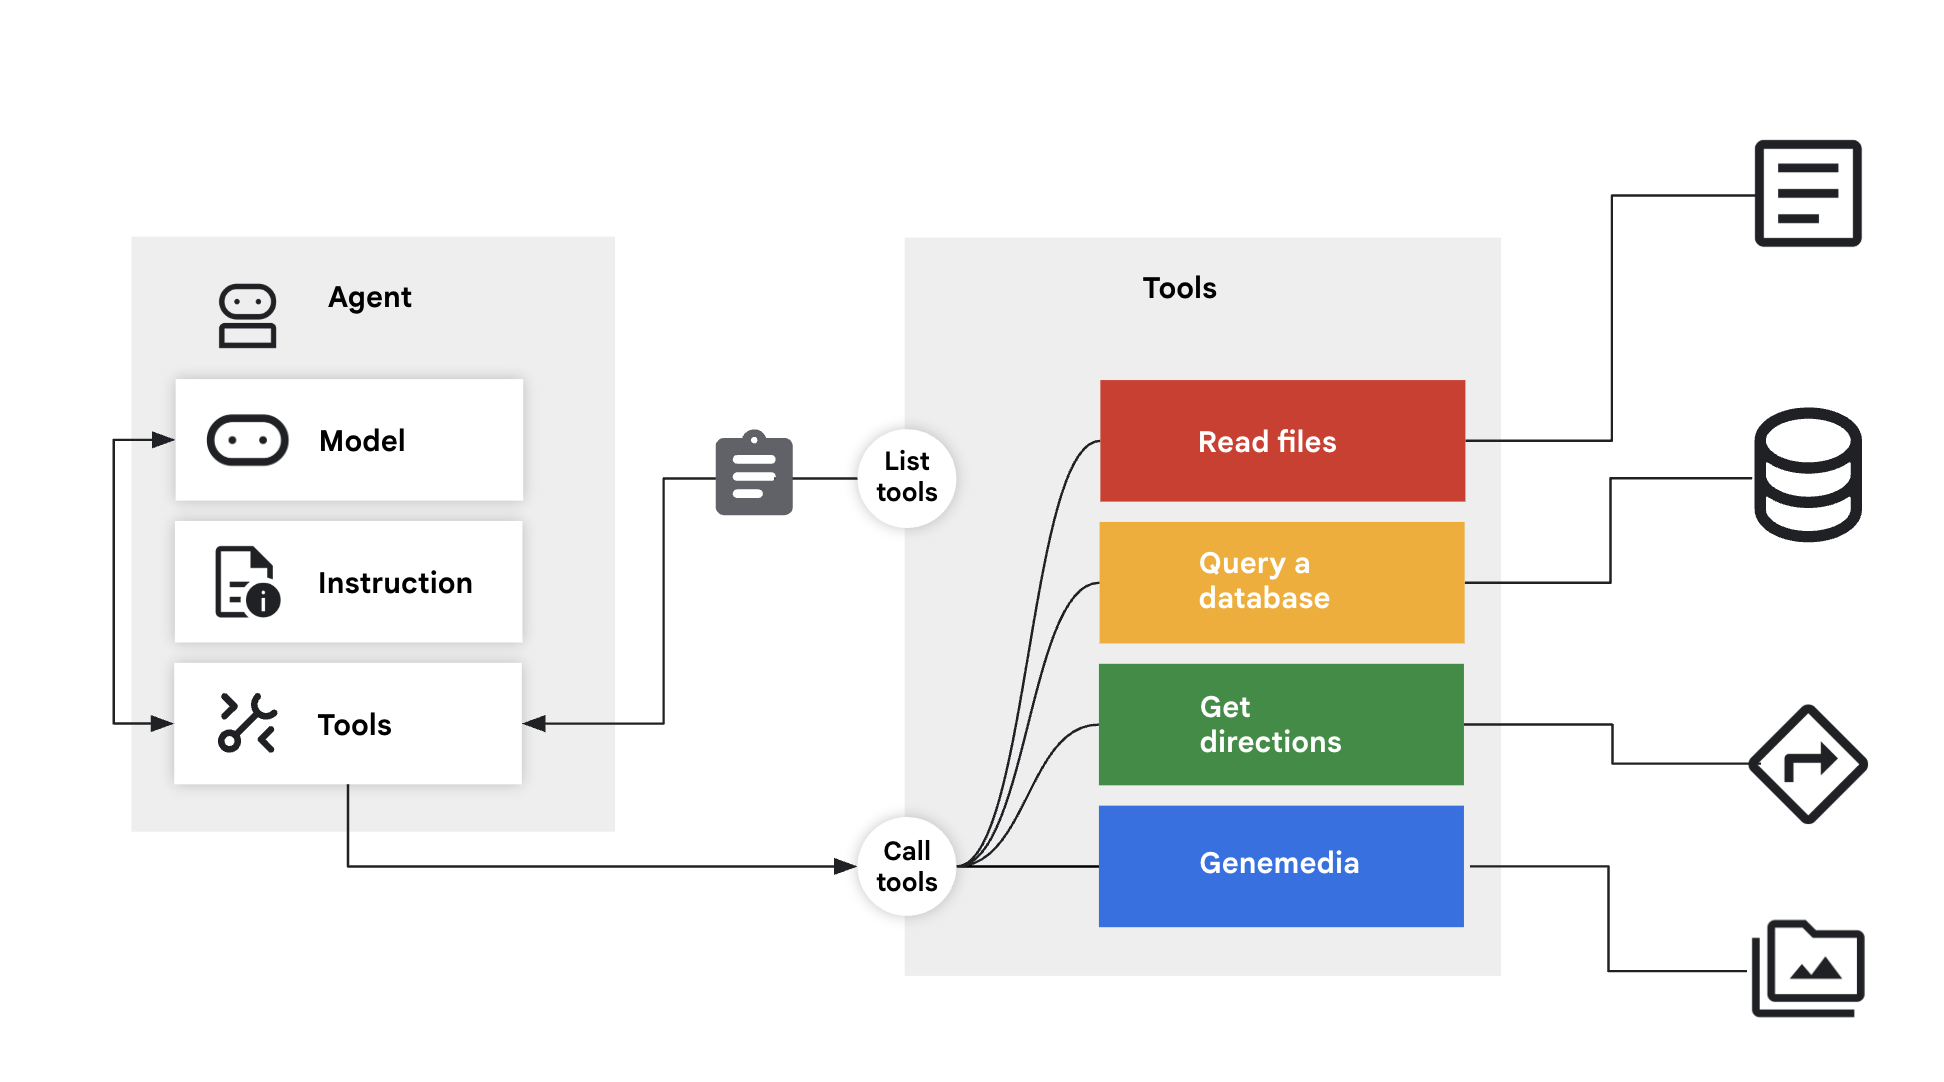
ステップ 1: ツール
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/05_profile_agent/tools.py
👉 このファイル: ~/memory_agent_starter/05_profile_agent/tools.py。
次の 2 つのツールを実装する必要があります。
save_user_preferences: データベースに書き込みます。recall_user_preferences: データベースから読み取ります。
~/memory_agent_starter/05_profile_agent/tools.py 関数内のコメント # TODO: implement save_user_preferences tools を見つけます。
この行全体を次のコードに置き換えます。
def save_user_preferences(tool_context: ToolContext, new_preferences: Dict[str, Any]) -> str:
    user_id = tool_context.session.user_id
    with sqlite3.connect(USER_DB_FILE) as conn:
        for key, value in new_preferences.items():
            conn.execute("INSERT INTO user_preferences (user_id, pref_key, pref_value) VALUES (?, ?, ?) ON CONFLICT(user_id, pref_key) DO UPDATE SET pref_value = excluded.pref_value;",
                         (user_id, key, json.dumps(value)))
    return f"Preferences updated: {list(new_preferences.keys())}"
👉 05/tools.py 関数内のコメント # TODO: implement recall_user_preferences tools を見つけます。
この行全体を次のコードに置き換えます。
def recall_user_preferences(tool_context: ToolContext) -> Dict[str, Any]:
    user_id = tool_context.session.user_id
    preferences = {}
    with sqlite3.connect(USER_DB_FILE) as conn:
        rows = conn.execute("SELECT pref_key, pref_value FROM user_preferences WHERE user_id = ?", (user_id,)).fetchall()
        if not rows: return {"message": "No preferences found."}
        for key, value_str in rows: preferences[key] = json.loads(value_str)
    return preferences
この指示により、ワークフローが強制されます。
instruction="""
1. RECALL FIRST: First action MUST be `recall_user_preferences`.
3. LEARN: If a user states a new preference, use `save_user_preferences`.
"""
ステップ 2: 実行
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/05_profile_agent/main.py
~/memory_agent_starter/05_profile_agent/main.py を開きます。
ADK が状態を自動的に処理していた以前のモジュールとは異なり、ここではエージェントが制御します。
- 最初に
recall_user_preferencesを呼び出すことを選択します。 - 「私はビーガンです」と言ったときに、
save_user_preferencesを呼び出すことを選択します。
ステップ 3: プロファイルをビルドする
👉💻 スクリプトを実行します。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/05_profile_agent/main.py
次の会話フローを試してください。
- 「夕食の献立を考えて。」-> エージェントが DB を確認し、何も見つからない。好みを尋ねる。
- 「私はビーガンです。」-> エージェントが「ビーガン」を DB に保存します。
- スクリプトを再起動します。
- 「夕食の献立を考えて。」-> エージェントがデータベースを確認し、「ビーガン」を見つけて、すぐにビーガン レストランを提案します。
主なポイント
メモリのルール 5: 複雑な構造化データの場合は、エージェントに読み取り / 書き込みツールを提供します。LLM に独自の長期ストレージを管理させる。
8. 脳 - マルチモーダル メモリ
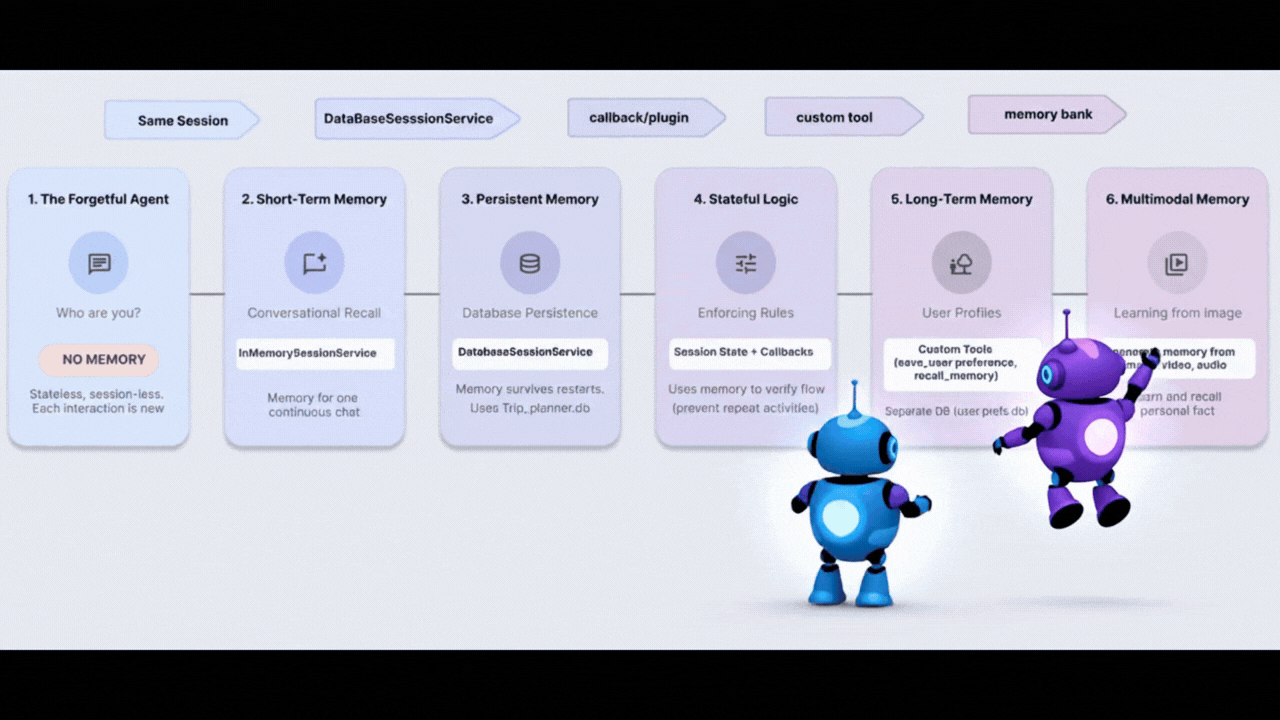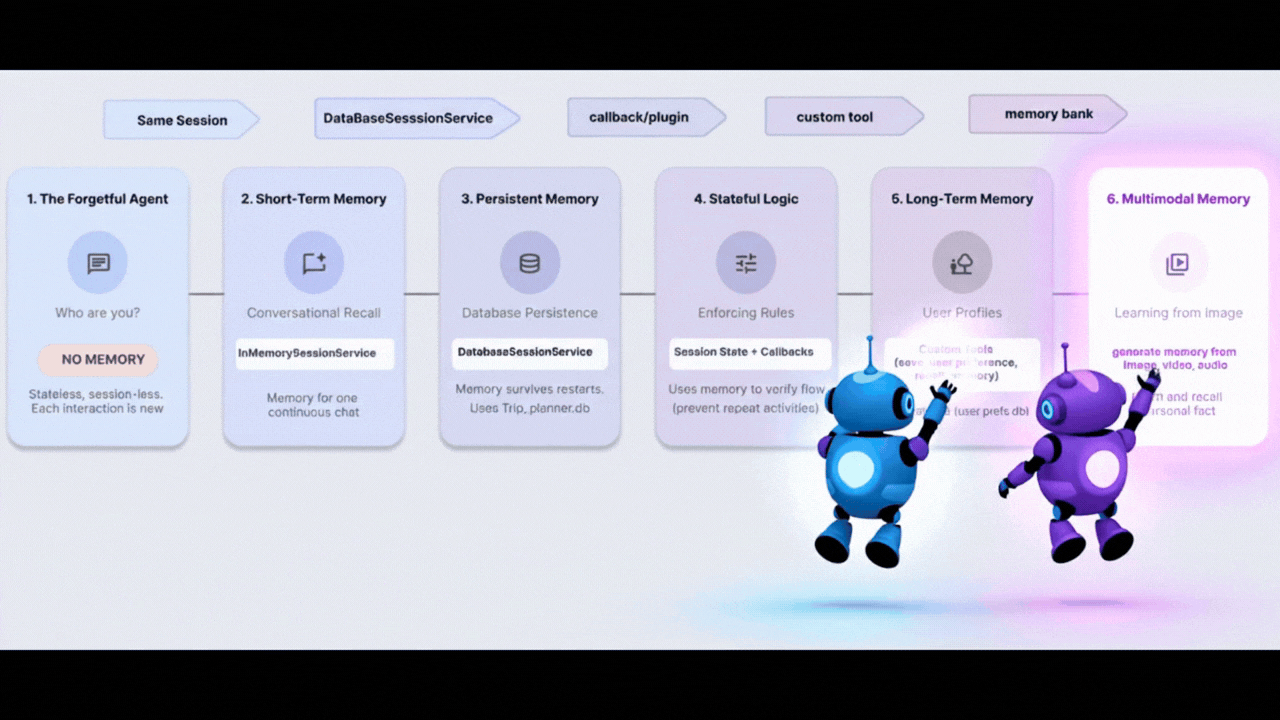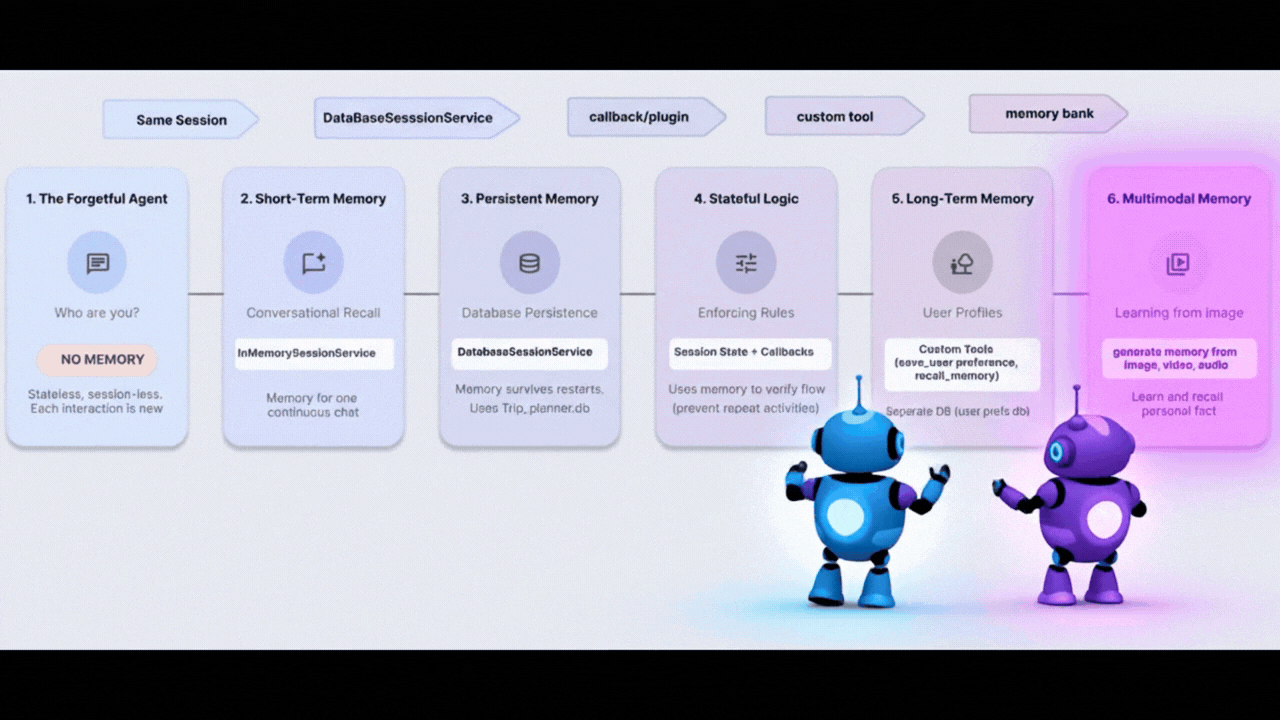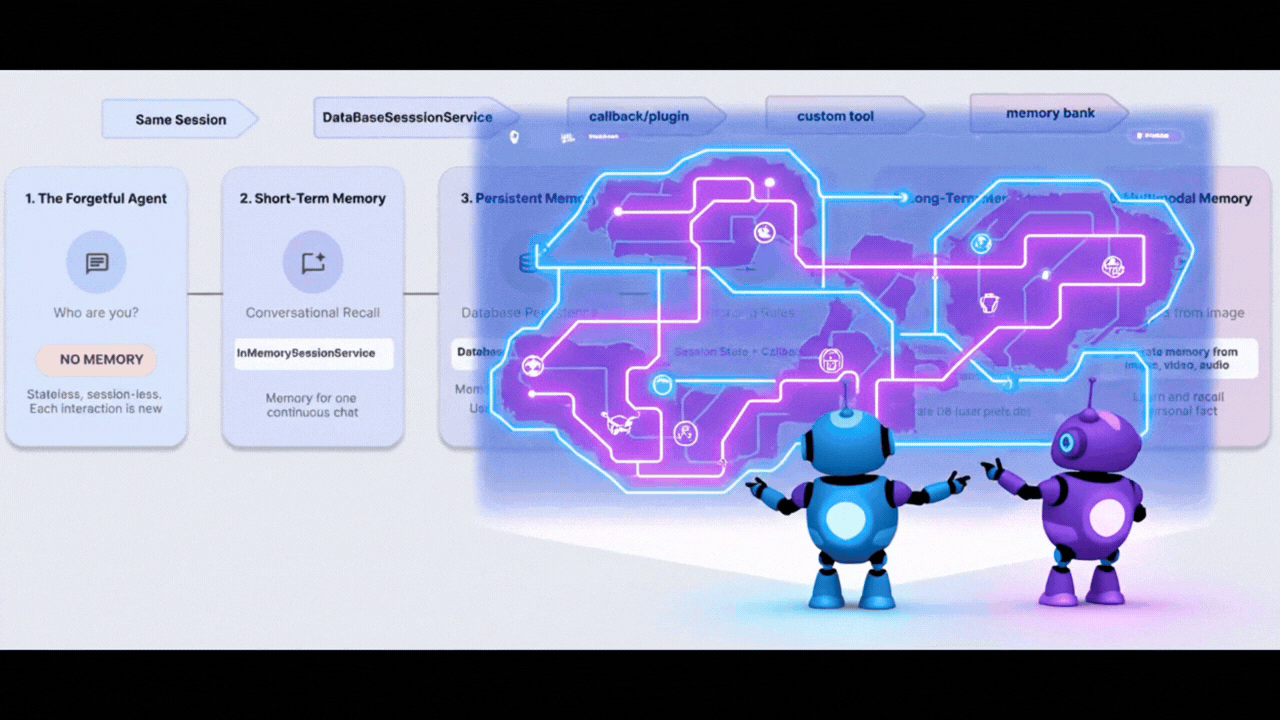
コンセプト: 「ヒューマン エクスペリエンス」
人間はテキスト以外の情報も記憶します。写真の雰囲気、声の響き、動画の印象を覚えています。
Vertex AI Memory Bank を使用すると、エージェントはマルチモーダル メモリを処理できます。画像、動画、音声を読み込んで「理解」し、後で取得できます。
ステップ 1: 構成
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/06_multimodal_agent/main.py
👉 06_multimodal_agent/main.py を開きます。コメント # TODO: Configure Memory Bank Topic を見つけます。
この行全体を次のコードに置き換えます。
travel_topics = [
    MemoryTopic(
        managed_memory_topic=ManagedMemoryTopic(
            managed_topic_enum=ManagedTopicEnum.USER_PREFERENCES
        )
    ),
    MemoryTopic(
        managed_memory_topic=ManagedMemoryTopic(
            managed_topic_enum=ManagedTopicEnum.USER_PERSONAL_INFO
        )
    ),
    MemoryTopic(
        custom_memory_topic=CustomMemoryTopic(
            label="travel_experiences",
            description="""Memorable travel experiences including:
                - Places visited and impressions
                - Favorite restaurants, cafes, and food experiences
                - Preferred accommodation types and locations
                - Activities enjoyed (museums, hiking, beaches, etc.)
                - Travel companions and social preferences
                - Photos and videos from trips with location context""",
        )
    ),
    MemoryTopic(
        custom_memory_topic=CustomMemoryTopic(
            label="travel_preferences",
            description="""Travel style and preferences:
                - Budget preferences (luxury, mid-range, budget)
                - Transportation preferences (flying, trains, driving)
                - Trip duration preferences
                - Season and weather preferences
                - Cultural interests and language abilities
                - Dietary restrictions and food preferences""",
        )
    ),
    MemoryTopic(
        custom_memory_topic=CustomMemoryTopic(
            label="travel_logistics",
            description="""Practical travel information:
                - Passport and visa information
                - Frequent flyer numbers and hotel loyalty programs
                - Emergency contacts
                - Medical considerations and insurance
                - Packing preferences and essentials
                - Time zone preferences and jet lag strategies""",
        )
    ),
]
コメント # TODO: Configure Memory Bank Customization を見つけます。
この行全体を次のコードに置き換えます。
memory_bank_config = {
    "customization_configs": [
        {
            "memory_topics": travel_topics,
        }
    ],
    "similarity_search_config": {
        "embedding_model": f"projects/{PROJECT_ID}/locations/{LOCATION}/publishers/google/models/gemini-embedding-001"
    },
    "generation_config": {
        "model": f"projects/{PROJECT_ID}/locations/{LOCATION}/publishers/google/models/gemini-2.5-flash"
    },
}
ステップ 2: 世界を取り込む
test_trip_planner では、以下を送信します。
- テキスト メッセージ(「Hello」)
- 画像(ランドマーク)
- 動画(地中海)
- 音声クリップ(ガエータに関する音声メモ)
6_multimodal_agent/main.py 関数内のコメント # TODO create session service and memory service を見つけます。
この行全体を次のコードに置き換えます。
session_service = VertexAiSessionService(
    project=PROJECT_ID, location=LOCATION, agent_engine_id=agent_engine_id
)
memory_service = VertexAiMemoryBankService(
    project=PROJECT_ID, location=LOCATION, agent_engine_id=agent_engine_id
)
👉 同じファイル 06_multimodal_agent/main.py で、コメント # TODO: create memory from session を見つけます。
この行全体を次のコードに置き換えます。
await memory_service.add_session_to_memory(final_session_state)
これがマジックラインです。このリッチメディアをすべて Vertex AI に送信し、Vertex AI が処理してインデックスに登録します。
ステップ 3: 取得
👉💻 Cloud Shell ターミナルで、次のコマンドを実行して Cloud Shell エディタでファイルを開きます。
cloudshell edit ~/memory_agent_starter/06_multimodal_agent/agent.py
エージェントに PreloadMemoryTool があります。
tools=[PreloadMemoryTool(), budget_tool]
新しいセッションが開始されると、このツールは Memory Bank で関連する過去の経験を自動的に検索し、コンテキストに挿入します。
ステップ 4: Brain を実行する
👉💻 Cloud Shell ターミナルで、スクリプトを実行します(注: これには、Vertex AI が有効になっている Google Cloud プロジェクトが必要です)。
cd ~/memory_agent_starter
uv run python ~/memory_agent_starter/06_multimodal_agent/main.py
オーナー確認の最後のステップ
「以前に共有した画像、動画、音声に基づいて...」
エージェントは次のように返信します。
「ガエータに行ってみてください。地中海の動画と、ガエータが大好きだと言っている音声クリップを見せてくれました。」
過去のさまざまなメディアタイプの点と点をつなぎました。
主なポイント
メモリのルール 6: 究極のメモリ エクスペリエンスを実現するには、Vertex AI Memory Bank を使用します。テキスト、画像、動画を 1 つの検索可能なブレインに統合します。
9. まとめ
忘れっぽい Goldfish からマルチモーダルな Elephant への進化を遂げました。
構築した | 機能 |
セッション エージェント | 短期的な会話のメモリー |
マルチエージェント | チームの共有メモリ |
永続エージェント | 長期的な履歴 |
ステートフル エージェント | 動的で自己更新型のメモリ |
Profile Agent | 構造化データメモリ |
マルチモーダル エージェント | 人間のような感覚記憶 |
信頼は記憶の上に築かれます。これらのパターンを実装することで、ユーザーの時間と履歴を尊重するエージェントを作成し、より深く効果的なインタラクションを実現できます。
今すぐパーソナライズされたエージェントの構築を始めましょう。