
1. Introduction
Brought to you by Google Cloud Americas' Advocacy team.
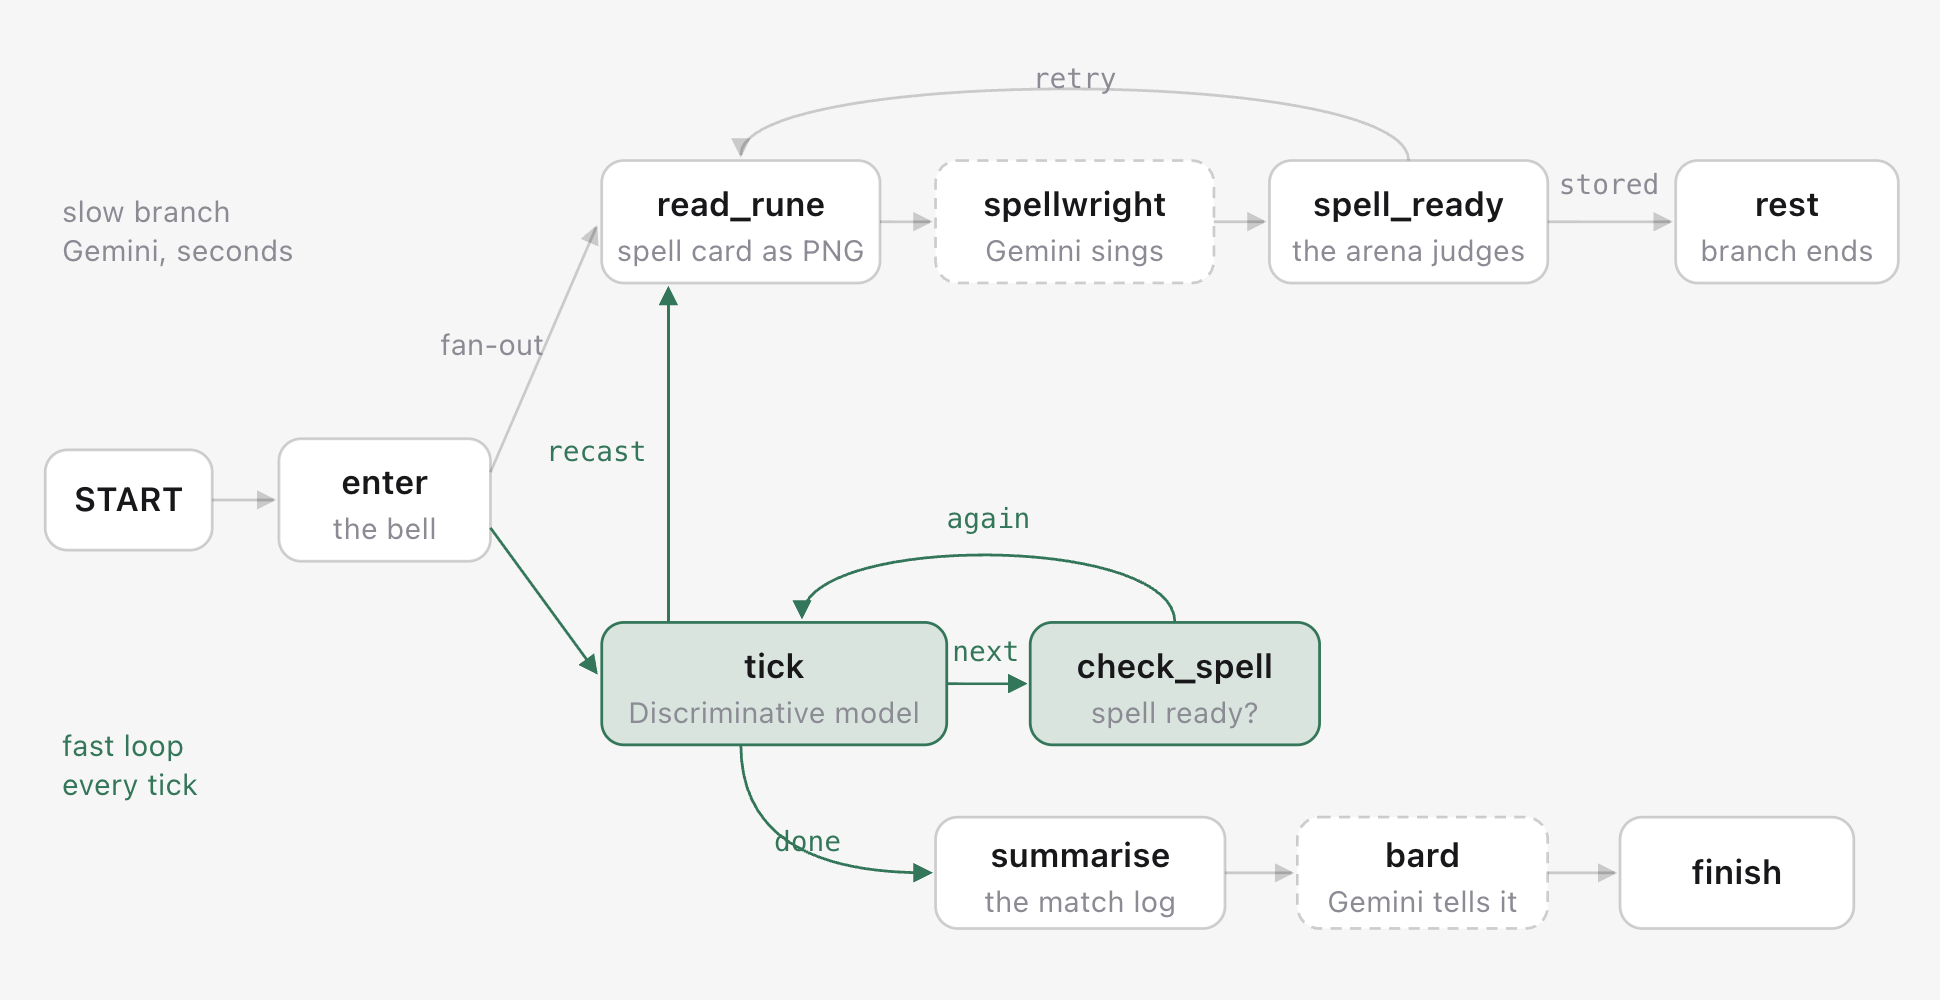
This one-hour workshop (about sixty minutes) introduces discriminative (System One) decision models and shows how to put one next to Gemini to build a fast and responsive agentic solution. In the interactive workbench, everything is built around a fighting game. You fight an ogre by hand first, hand the reflexes to a decision model, and then run an ADK workflow that wins the match with your chosen decision model deciding every tick, Gemini Decisions reading spell cards off the screen, and Gemini writing the tale at the end.
Overview
A discriminative model does not generate text. You send it state (text, JSON, a list, or an image when the model supports it) and typed questions (Choice, Score, Noul), and it returns typed answers with calibrated probabilities. Its job is the decision in front of, between, and behind language models, including routing, classification, gating, and here, a fighter's reflexes.
Step 2 of the workbench offers three decision models:
- Gemini Decisions (
gemini-decision-1) is Google's hosted model on the Gemini Developer API. Includes a no-cost tier, and also accepts images, which step 6 uses to read spell cards. - Jev (
jev-1.13, aliasjev-latest) is a hosted model from TypeSafe AI. - DiffusionGemma is Google's open-weights model. The workshop runs it on an NVIDIA L4 GPU VM in your own Google Cloud project, behind Jev's API via djev-run.
Output tokens are free on both hosted models.
A game as the example
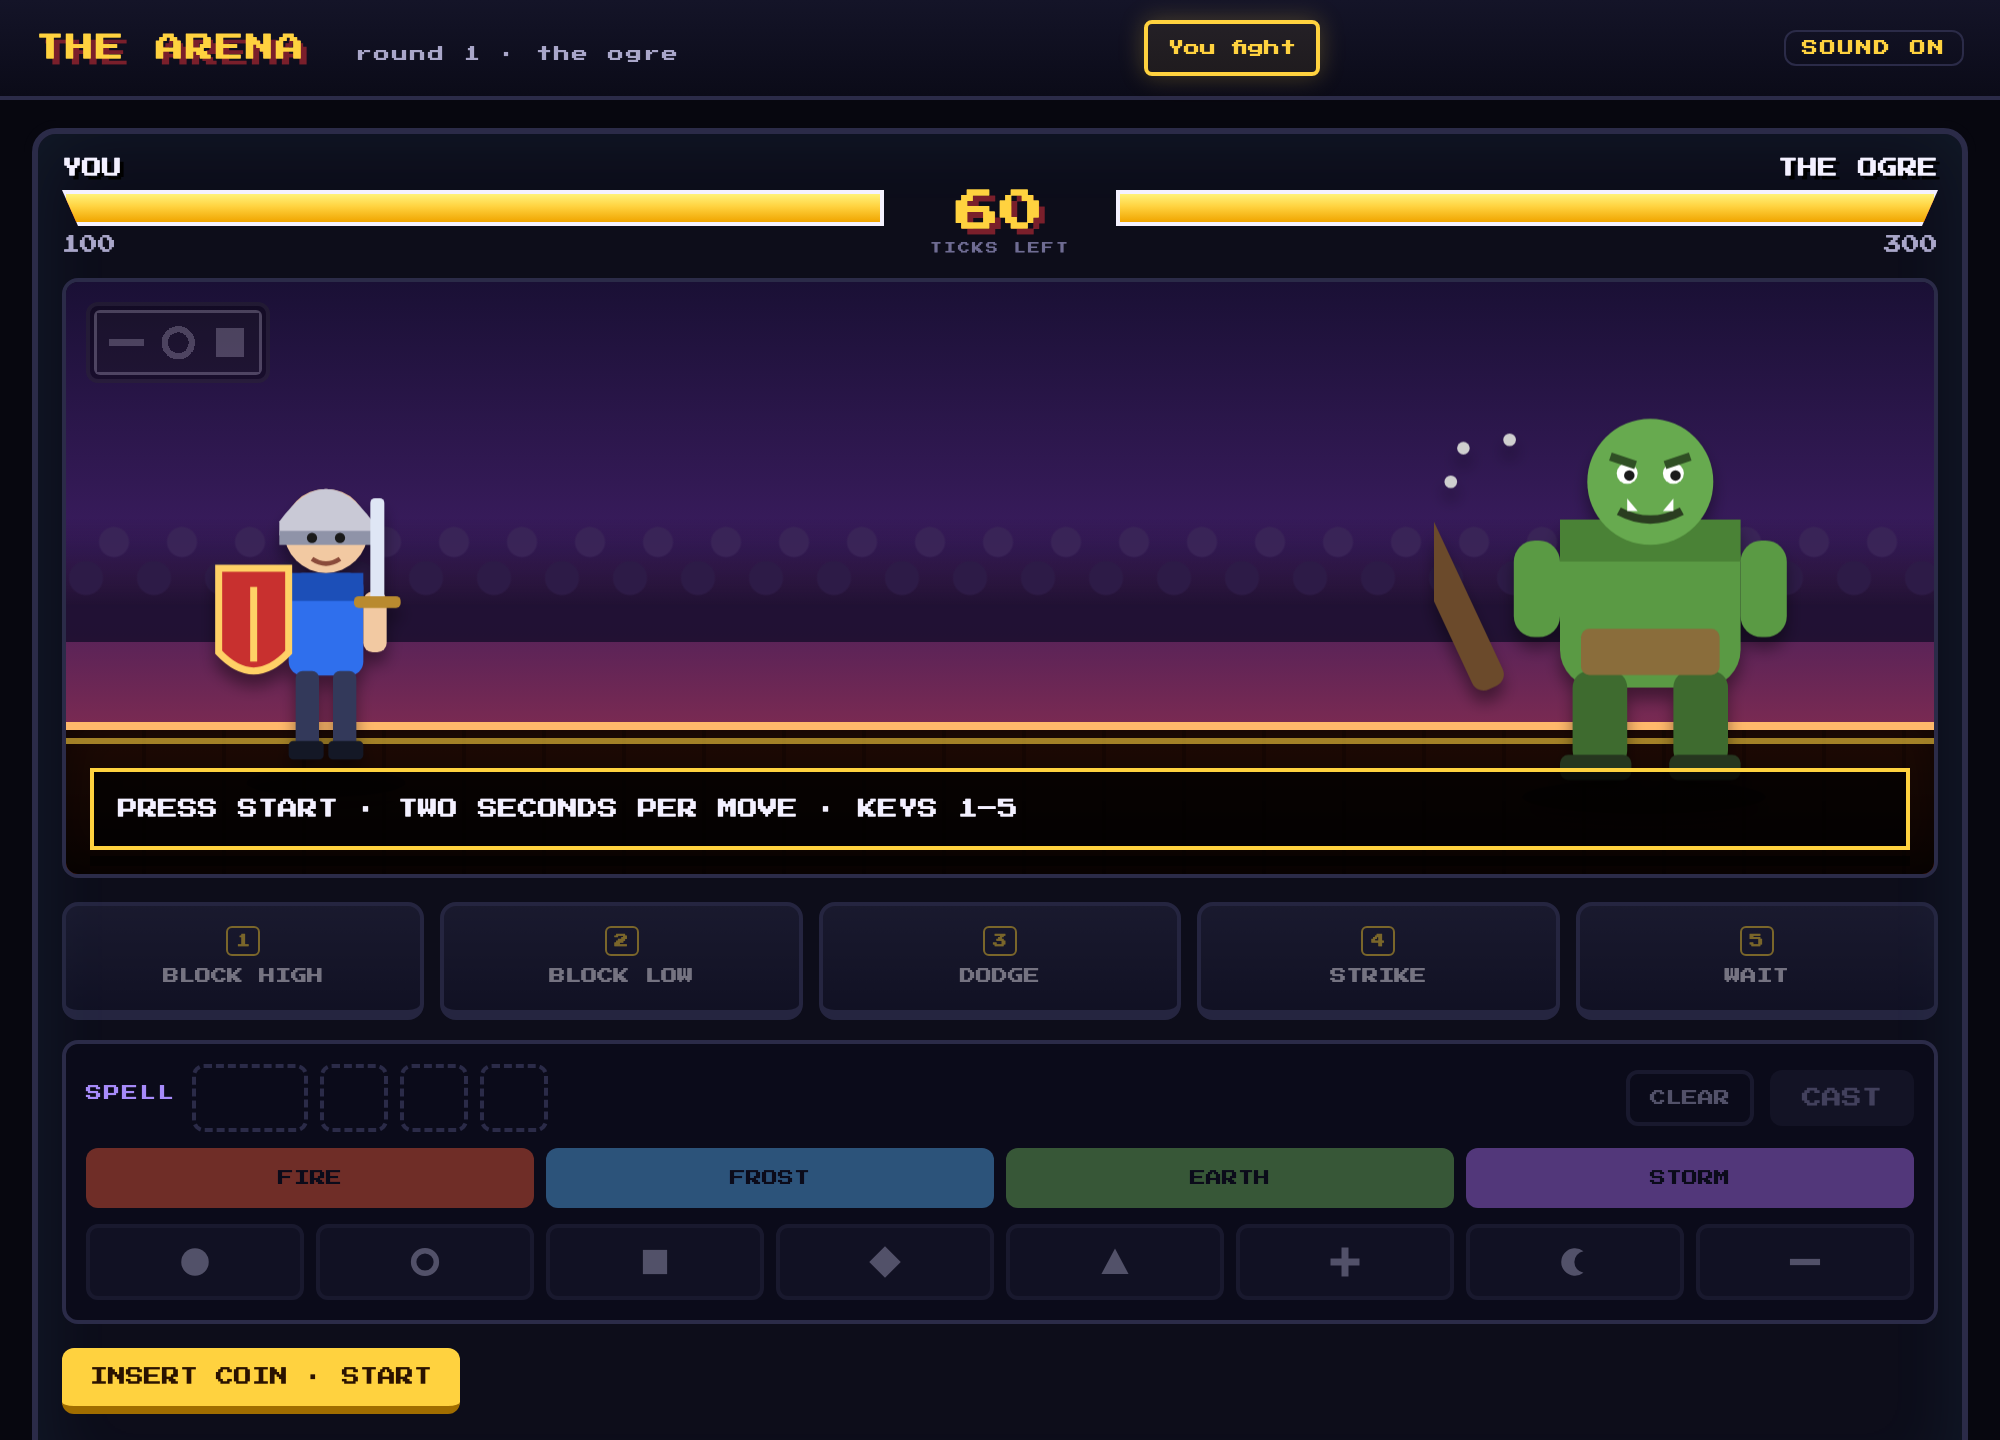
In the arena game, you face an ogre that attacks every two seconds. You have to read each move and pick the right counter before the timer runs out, or your fighter takes damage. At the same time, a spell card in the corner of the ring shows a color and three shapes in a row. Matching that card casts a spell that deals heavy damage. This workshop shows how to combine a decision model, deterministic code, and a language model so your fighter can counter every attack, read and cast spells, and win the match.
Each element of the game maps to a real system:
- The opponent's move is an incoming event, like a request or a transaction.
- The response is a bounded decision, made by a discriminative model and checked by code.
- The spell card is an image. Its color and shapes come from a fixed set, so reading it is also a bounded decision for a discriminative model that takes images.
- The match is the workflow, a loop that calls the right model at each step.
- The tale of the fight is open-ended text, written by a language model.
The focus is on combining these components to build a fast and reliable system.
What you will learn
- Explain how discriminative (System One) and generative (System Two) models differ, and when to use each.
- Describe how Jev, DiffusionGemma, and Gemini Decisions are served, and set one up for the workshop.
- Write
Choice,Score, andNoulquestions, and interpret probabilities and confidence. - Use thresholds in deterministic code to turn probabilities into actions.
- Build a request, send it with the TypeSafe SDK or the Google Gen AI SDK, and let the model choose every move in a game.
- Read an image with Gemini Decisions by asking choice questions about it.
- Build an ADK graph workflow that fights in a loop, reads the spell card on a branch beside it, and hands the result to Gemini for a written summary.
Architecture
Three processes run in Cloud Shell (or on your machine) and call outside services for the chosen decision model, Gemini Decisions, and Gemini. ② calls the decision model in "Discriminative model fights", and ③ calls all three in "Workflow fights".
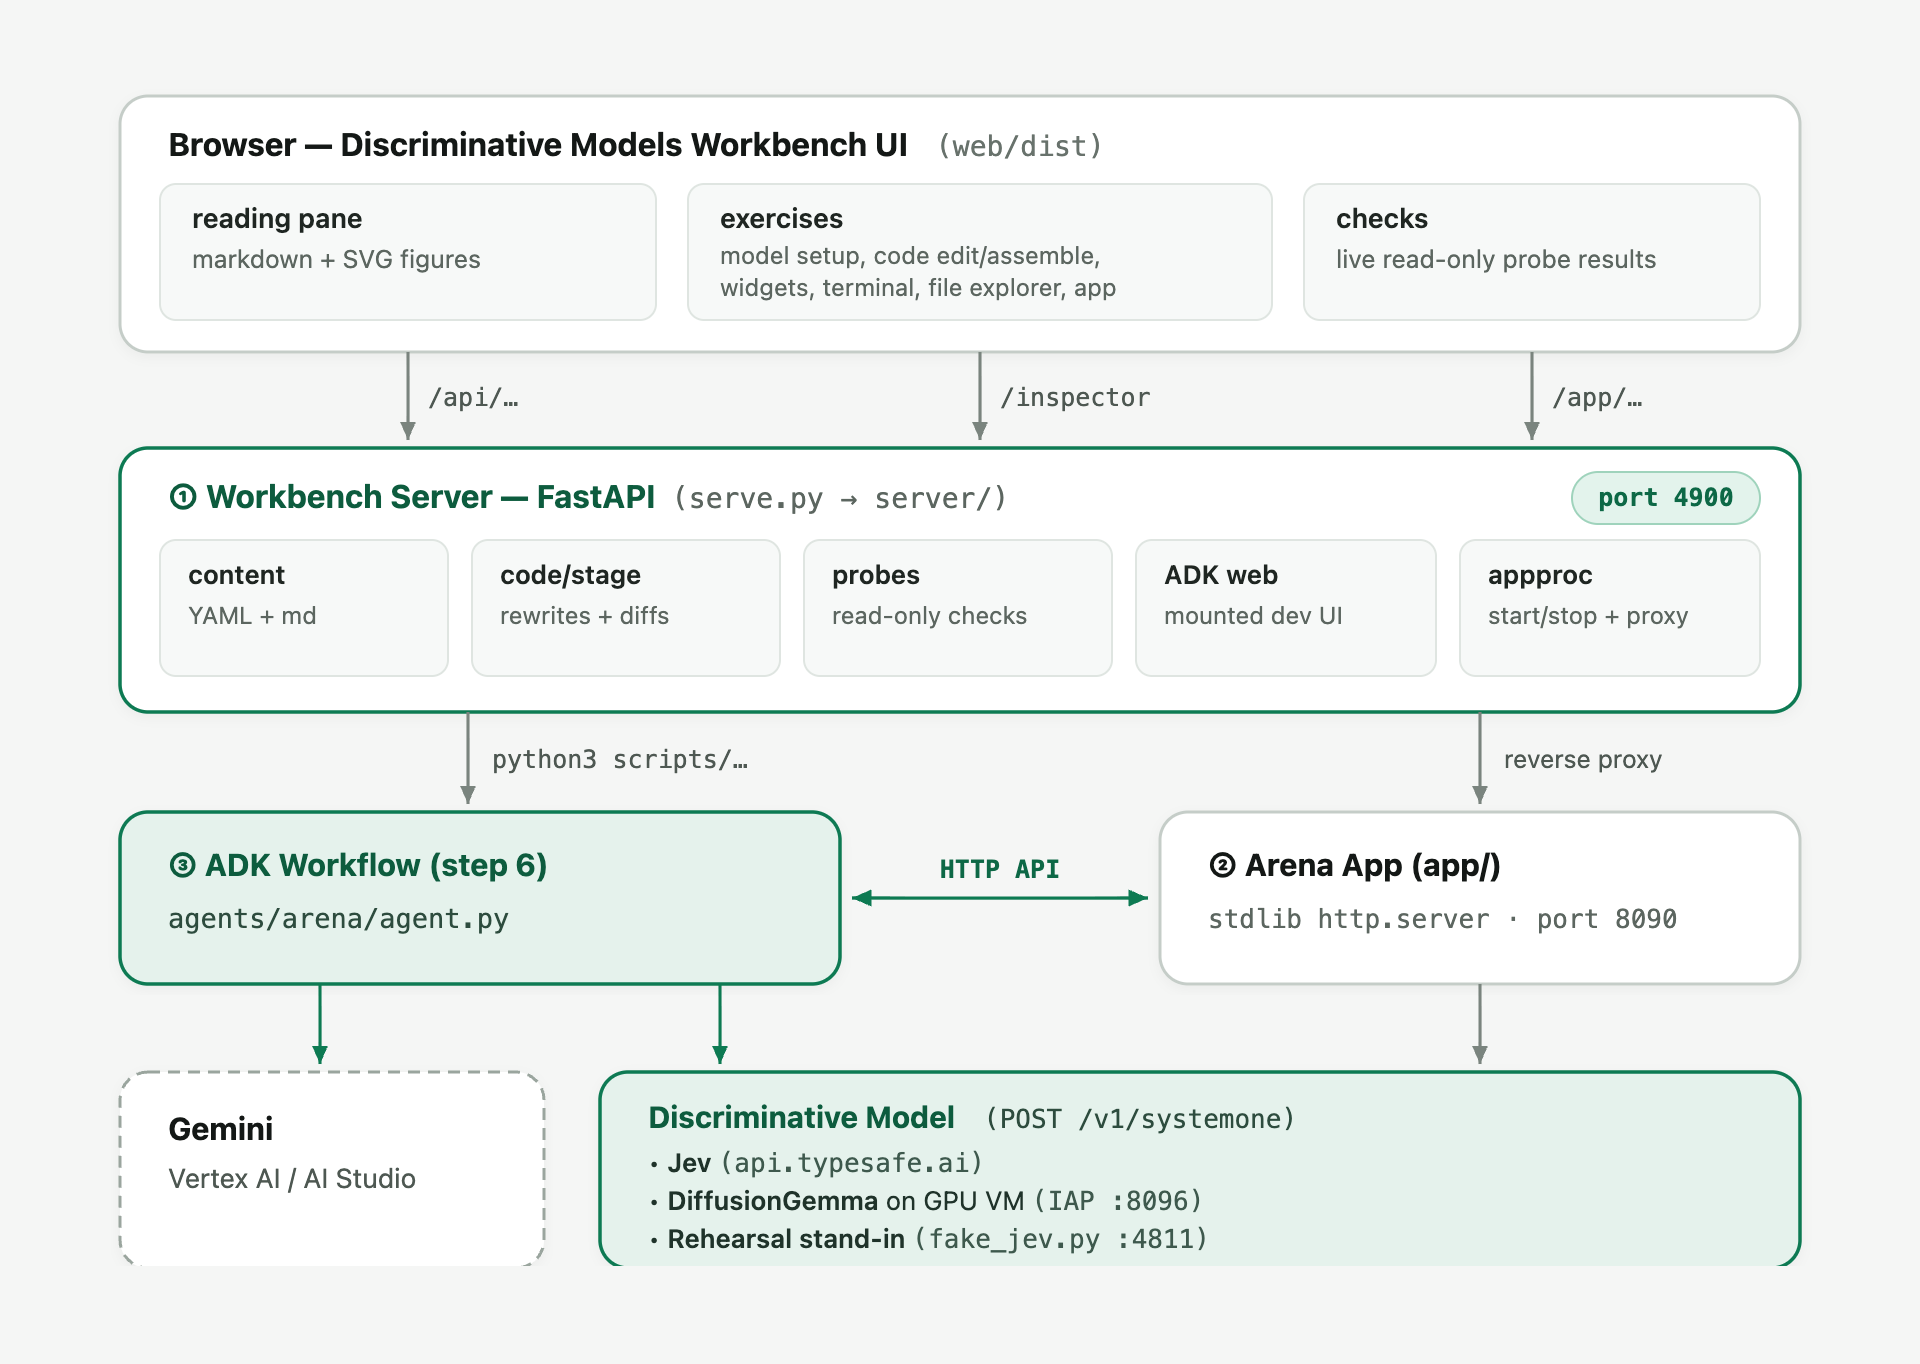
Who calls what. The browser only talks to ①. Every model call comes from Python on the machine:
Caller | Decision model (step 2's choice) | Gemini Decisions, on the card image | Gemini |
② arena, "Discriminative model fights" | every tick, | no | no |
③ workflow | every tick, | no | no |
③ workflow | no | at the bell and after each cast, | no |
③ workflow | no | no | the tale after the fight |
| yes | no | no |
| no | yes | no |
One tick, per mode.
- You fight. The page asks ② for a telegraph, shows it with a 2 s timer, and posts the button you press (or the spell you pick) back. ② resolves it.
- Discriminative model fights. The page asks ② for a tick. ② draws a telegraph, asks the chosen decision model three questions in one call, runs
choose(), and returns the answers and the outcome. The page draws the bars. - Workflow fights. Pressing Start makes ② launch ③ as a subprocess (logged in
runs/arena-workflow.log). ③ drives the fight by asking ② for each telegraph, calling the decision model, and posting the decision back.read_cardruns on its own branch at the same time, so the fight never waits for it. The page only polls ② and draws. Pause sets a flag on ② that ③ checks before each tick.
How the model is called. scripts/decisions.py wraps both SDKs behind ask(about, questions) and ask_async(about, questions). about is what the model judges; it is sent as state with typesafe-sdk (for Jev and DiffusionGemma) and as input with google-genai (for Gemini Decisions). Questions are written once as plain dicts, and the returned answers expose the same fields from either SDK.
Where the decision model is hosted. scripts/jevauth.py selects the backend and sets the key and timeout. Setting JEV101_MODEL=gemini selects Gemini Decisions; otherwise the backend follows TYPESAFE_BASE_URL:
Backend |
| Key | Set up by |
Jev on TypeSafe, hosted | unset ( |
| step 2, or |
DiffusionGemma on your L4 VM |
| none | step 2, or |
DiffusionGemma on Cloud Run |
| Google identity token, fetched hourly |
|
Any other Jev-compatible server | its address | none | by hand, in |
Gemini Decisions, hosted | not used |
| step 2, or |
The spell card's answer never leaves ②. The workflow receives only the PNG image, and ② judges the reading sent back.
2. Setup
Claim your workshop credits
If you were given a Google Cloud credit for this session, claim it first. It takes about a minute and creates the billing account for you.
Open Cloud Shell
Cloud Shell is a browser-based development environment with gcloud, Python, and git preinstalled.
To launch Cloud Shell:
- Navigate to the Google Cloud Shell.
A terminal session opens at the bottom of the browser window.
Launch the workbench
In Cloud Shell, or anywhere gcloud is signed in:
git clone https://github.com/gca-americas/discriminative-models-workshop.git
cd discriminative-models-workshop
./setup_project.sh     # a new project with billing, recorded in ~/project_id.txt
./setup_codelab.sh     # everything else, then the workbench on port 4900
setup_project.sh creates a project (discrim-models-XXXX), links billing to it (preferring an event credit account when you have one), and waits until the project can serve. Re-running it reuses the project in ~/project_id.txt. To use an existing project, write its ID to ~/project_id.txt and skip this script.
setup_codelab.sh reads the project ID from ~/project_id.txt, or prompts for an existing project ID if that file is missing. It installs uv and the Python packages, writes GOOGLE_CLOUD_PROJECT to .env, creates a Gemini API key in the project (gcloud services api-keys create under key ID jev-workshop-gemini, restricted to the Generative Language API), verifies the key with a real request, sets Gemini Decisions as the initial decision model, places the starter exercise files, builds the frontend, starts the workbench in the background on port 4900, and runs scripts/check_setup.py. If an organization policy prevents creating an API key automatically, you can create one at Google AI Studio and paste it in step 2. Re-running setup_codelab.sh preserves your exercise files; scripts/starter.sh resets them. Compute Engine and IAP are enabled later by scripts/setup_gemma.sh, only if you choose DiffusionGemma.
To open the workbench UI in Cloud Shell:
- Click the preview link printed at the end of
./setup_codelab.sh, or click Web Preview in the top-right corner of the Cloud Shell toolbar. - Select Change port, enter 4900, and click Change and Preview.
All Gemini and Gemini Decisions calls use the Gemini Developer API through .env at the repository root:
GEMINI_API_KEY=AIza...                   # Gemini Decisions, and step 6, whichever model you pick
JEV101_MODEL=gemini                      # jev, gemma or gemini
TYPESAFE_API_KEY=apikey_...              # Jev only
TYPESAFE_BASE_URL=http://127.0.0.1:8096  # DiffusionGemma only, written by setup_gemma.sh
GOOGLE_CLOUD_PROJECT=your-project        # DiffusionGemma's project
You can choose or switch the decision model in step 2 of the workbench, or from a terminal with scripts/setup_model.sh. Every choice also needs GEMINI_API_KEY, because step 6 reads the spell card with Gemini Decisions and writes the tale with Gemini:
Choice | Needs | Setup | Cost |
Jev (TypeSafe, hosted) | a TypeSafe API key ( | none | $0.042 per 1M input tokens |
DiffusionGemma (Google, open weights) | billing + Compute Engine quota for 1 × NVIDIA L4 | ~15 min, automatic | ~$0.71/h while the VM runs |
Gemini Decisions (Google, hosted) | a Gemini API key ( | none | $0.10 per 1M input tokens, with a no-cost tier |
DiffusionGemma on a Compute Engine VM
scripts/setup_gemma.sh (called by scripts/setup_model.sh when you pick DiffusionGemma) checks L4 GPU quota first, then creates one g2-standard-4 VM (1 × L4 24 GB, 4 vCPU, 16 GB RAM, 100 GB disk) from Google's Deep Learning VM image with NVIDIA driver 580. On first boot, the VM installs Docker, downloads the open weights from Hugging Face (nvidia/diffusiongemma-26B-A4B-it-NVFP4, 17.5 GB, public, no token), and runs djev-run, which serves DiffusionGemma behind Jev's API on port 8080. Port 8080 is not open to the internet; the workbench reaches it through an IAP tunnel on localhost:8096, opened automatically by scripts/start.sh.
Task | Command |
Pause or resume the VM |
|
Manage the tunnel |
|
Remove VM and firewall rule |
|
Preview the commands |
|
Repository layout
app/                the arena app, as built so far
  main.py           the server, the "You fight" mode, and the plugin loader
  engine.py         the rules and the ogre's moves, the one copy
  sigil.py          spell cards: a color and three shapes, judged and drawn (a tiny PNG rasteriser)
  static/           the page: HP bars, the telegraph and timer, the spell card; modes/ holds plugins
  static/sounds/    bgm.mp3 plus optional effects (.mp3); a missing file is silent
  reflex.py         step 5: the three questions and choose()
  mode_model.py     step 5: the server side of "Discriminative model fights"
  mode_workflow.py  step 6: the server side of "Workflow fights"
stages/             the source of app/: one folder per step, each laid on top of the last
agents/arena/agent.py   the ADK Workflow (root_agent), also served by ADK web at /inspector
branches/           step 6b's exercises: each part of the graph as a workflow of its own
  read_card.py      Gemini Decisions reads spell_card.png and is checked against spell_card.json
  fight_loop.py     the decision model decides on a list of moves, in a loop
  cards/            the spell cards the exercise can choose from
starter/            unedited copies restored by scripts/starter.sh:
                    scripts/first_call.py, branches/read_card.py, branches/fight_loop.py
scripts/
  setup_model.sh    chooses the decision model and checks it: --model jev|gemma|gemini
  decisions.py      ask() and ask_async(): the one call to the chosen model, through either SDK
  jevauth.py        where the decision model lives, and how to authenticate to it
  check_setup.py    reports what is configured
  stage.py          builds app/ up to a step: python3 scripts/stage.py 5
  first_call.py     step 5a's request: TELEGRAPH and a choice question; --curl
  ask.py            any question, as noul / --choice / --score, about a telegraph
  fight.py          a whole fight in the terminal, using the decision model only
  arena.py          runs the ADK workflow with a timestamped timeline
content/            course.yaml and one directory per step
server/             FastAPI backend for the workbench
web/                React + Vite + Tailwind frontend for the workbench
3. Summary
Clean up your environment
When you finish the workshop, complete the steps below to tear down any DiffusionGemma GPU resources, stop the background workbench server, delete your API key if you are keeping the project, remove the workshop files from Cloud Shell, and optionally shut down your workshop Google Cloud project.
- Delete the DiffusionGemma GPU VM and firewall rule (if created): If you provisioned DiffusionGemma on a Compute Engine GPU VM in step 2, remove the VM, disk, and IAP firewall rule so no compute or disk charges continue:
cd ~/discriminative-models-workshop ./scripts/teardown_gemma.sh - Stop the workbench process in Cloud Shell: Stop the background workbench server:
cd ~/discriminative-models-workshop ./scripts/stop.sh - Delete the Gemini API key (if keeping your project): If
setup_codelab.shcreated thejev-workshop-geminikey in your project and you plan to keep the project, delete the key before removing~/project_id.txt:gcloud services api-keys delete jev-workshop-gemini --project "$(cat ~/project_id.txt)" - Delete the workshop folder from Cloud Shell: Return to your home directory and remove the cloned repository and project ID file:
cd ~ rm -rf ~/discriminative-models-workshop ~/project_id.txt - Delete your Google Cloud project (optional): If
./setup_project.shcreated a dedicated workshop project (such asdiscrim-models-XXXX), shutting down the project deletes all resources created inside it while leaving your Cloud Billing account intact:- Open the Manage resources page in the Google Cloud console.
- Select your workshop project from the resource list.
- Click Delete in the top toolbar, type your project ID to confirm, and click Shut down.
You have completed this workshop.
Lab summary
In this lab you:
- Chose a discriminative model (Jev, DiffusionGemma on a Compute Engine GPU VM, or Gemini Decisions) and checked that it answers.
- Played the arena by hand, against the clock, to learn its rules.
- Learned how a discriminative model answers with
Choice,Score, andNoulquestions, probabilities, and confidence, and how your code applies thresholds to them. - Sent your first request, saw it through both SDKs, and let the model choose every move in the arena, with
choose()turning its answers into actions. - Read a spell card image with Gemini Decisions, and ran the fight loop on its own.
- Joined them in one ADK workflow that fights in a loop, reads each card on a branch beside it, casts on an opening, and has Gemini write the tale.
From conversation to decisions
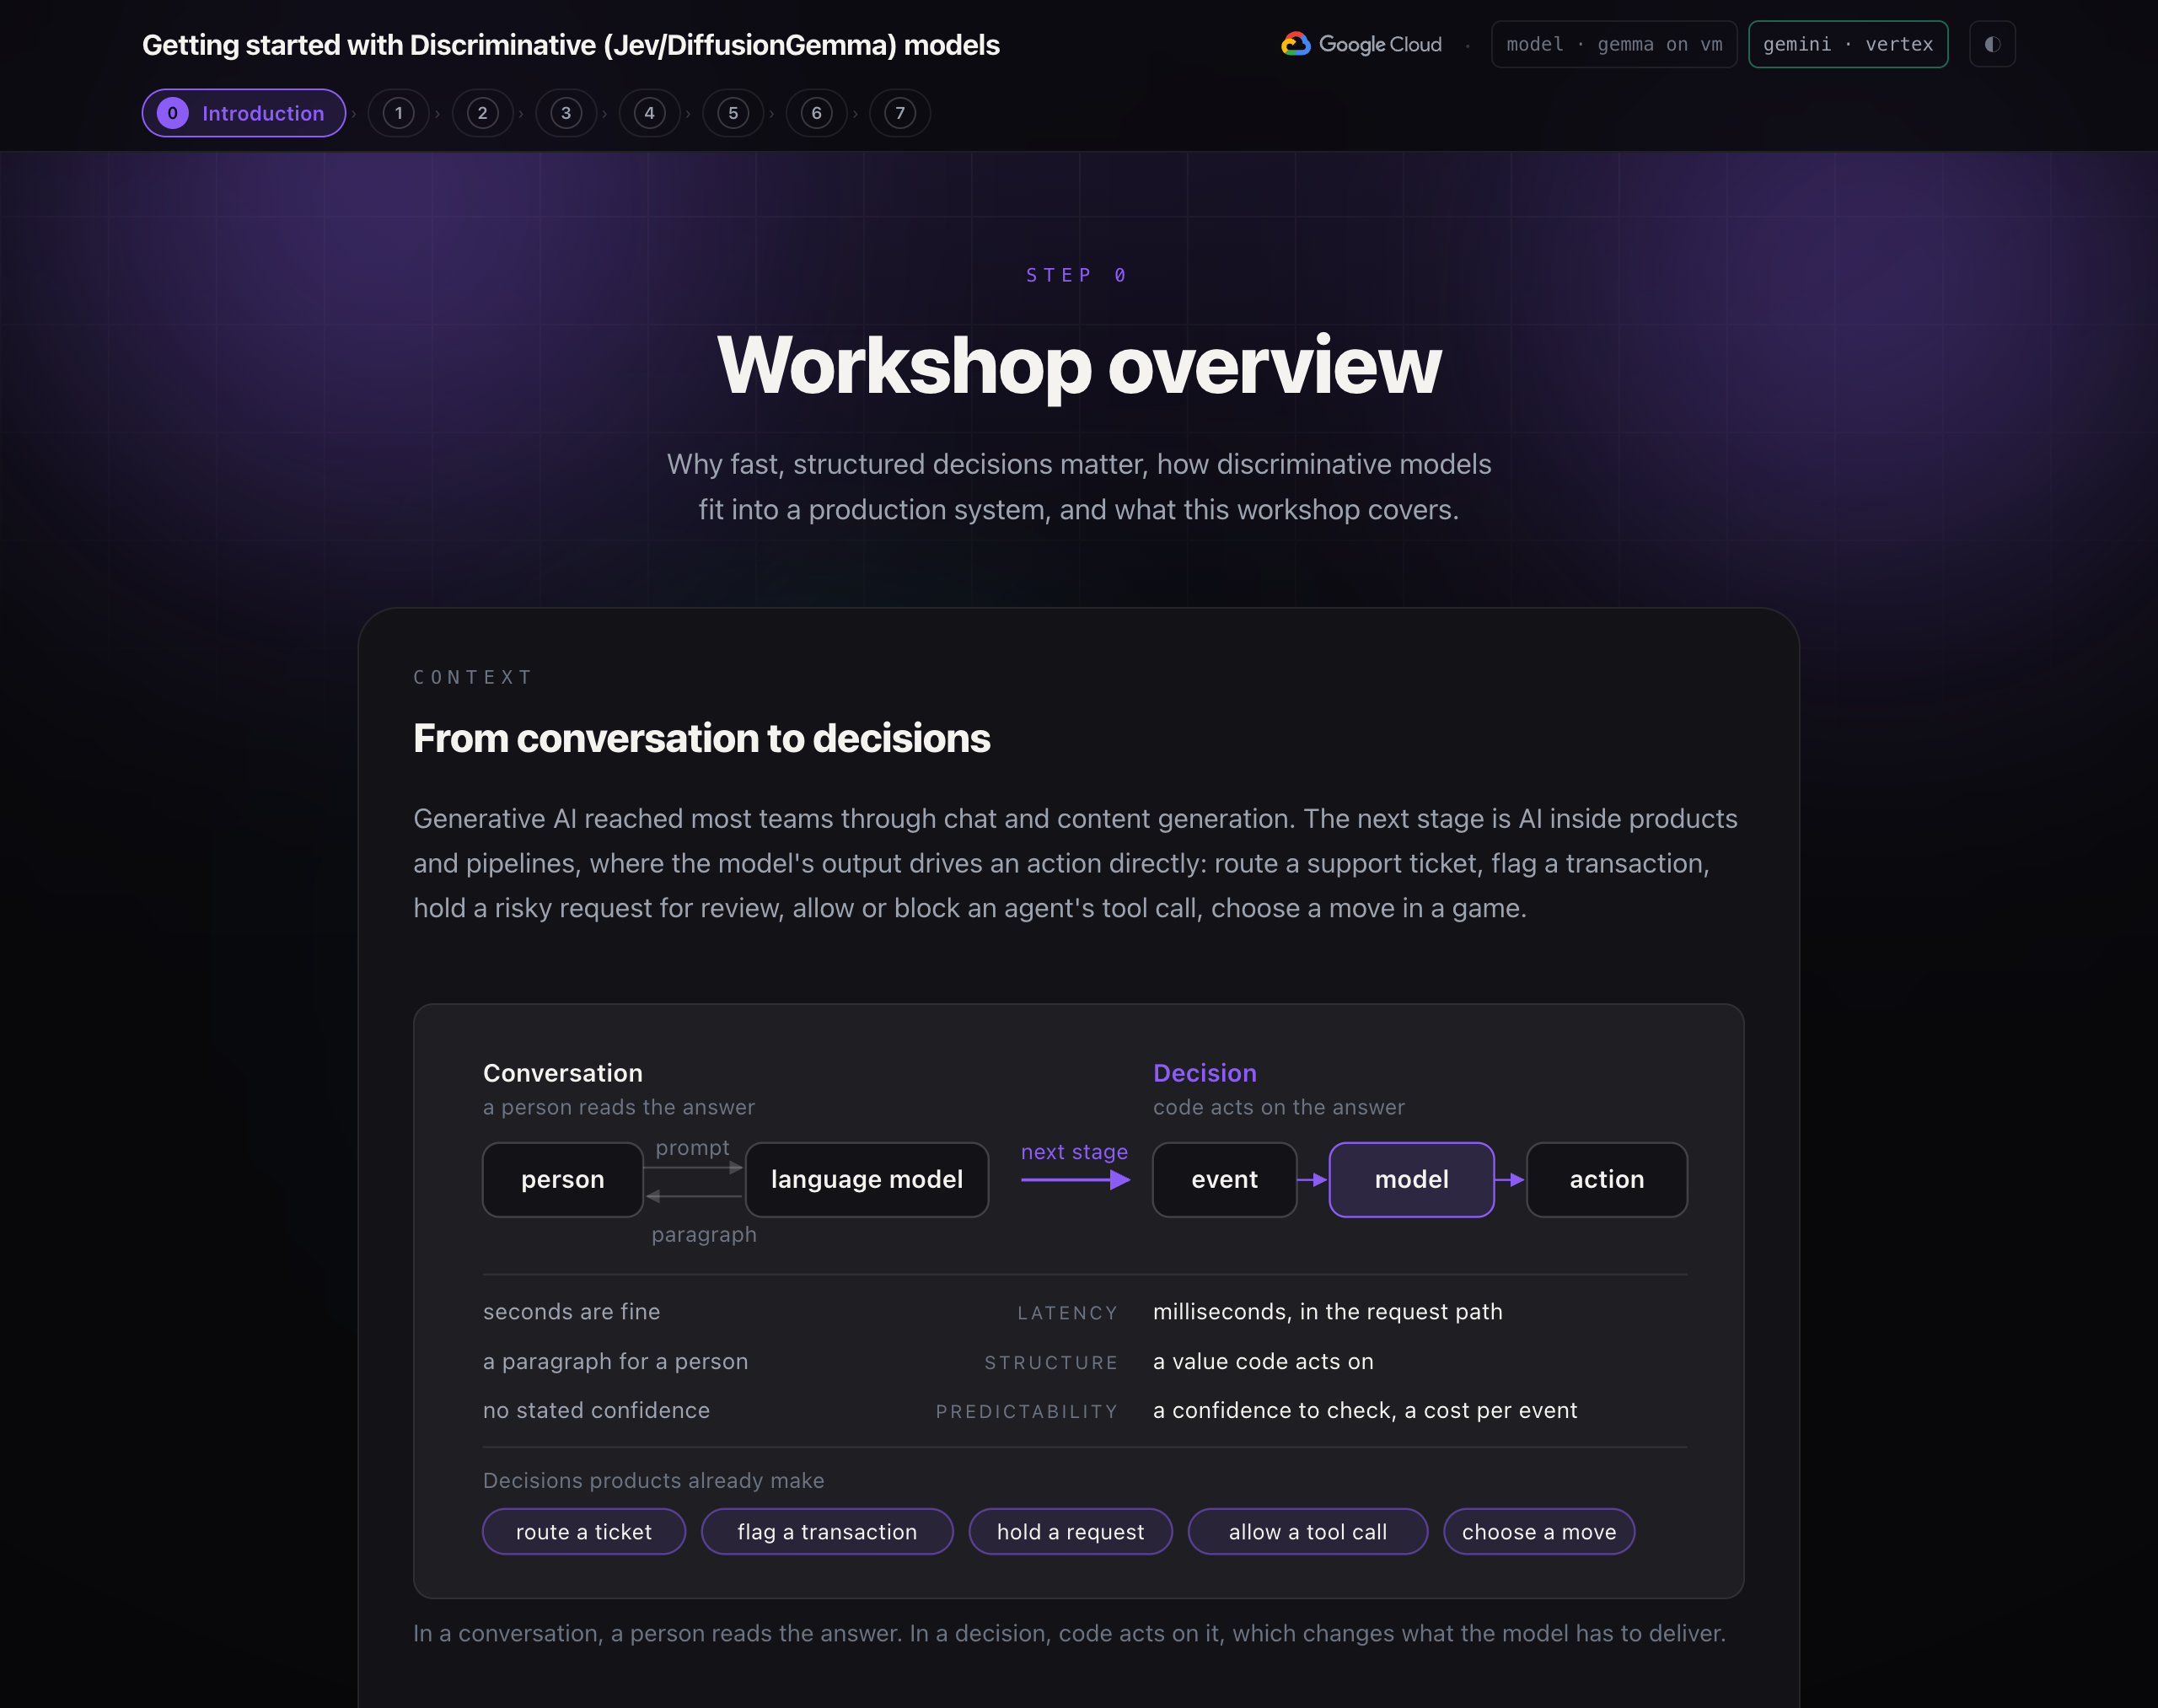
Generative AI reached most teams through chat and content generation. The next stage is AI inside products and pipelines, where the model's output drives an action directly, such as routing a support ticket, flagging a transaction, holding a risky request for review, allowing or blocking an agent's tool call, or choosing a move in a game.
These decisions share three requirements that chat does not have:
- Latency. The answer is often in a user's request path or a real-time loop, so it has to arrive in milliseconds, not seconds.
- Structure. The caller is code, so the answer has to be a value it can act on, not a paragraph it has to parse.
- Predictability. Every decision needs a confidence the code can check, and a cost low enough to ask on every event.
A language model generates text one token at a time. It can be prompted into a yes or no, but it is slow for a real-time loop, its output has to be parsed, and it does not report how sure it is.
Models built for decisions
A discriminative model answers a typed question with a probability for each allowed option, in a single pass. It does not generate text. This workshop provides three options to run:
Model | Provider | Where the model runs in this workshop |
Jev | TypeSafe AI | TypeSafe's hosted service, called with an API key |
DiffusionGemma | Google, open weights | Self-hosted on a GPU VM in your own Google Cloud project |
Gemini Decisions | Google's hosted service on the Gemini Developer API, called with an API key |
The models can be swapped based on your needs. Jev and DiffusionGemma are called with the TypeSafe SDK, and Gemini Decisions is called with the Google Gen AI SDK. The workshop keeps both calls in scripts/decisions.py, so the rest of the code does not change when you switch.
Combine components
A production system combines four components, giving each the work it handles best:
Component | Role | In this workshop |
Workflow | Orchestrates steps, runs branches side by side, holds shared state | An ADK graph workflow |
Deterministic code | Rules, thresholds, validation. Instant, free, and auditable | The game rules, |
Discriminative model | Fast, bounded decisions with a confidence score | Choosing a response every tick, and reading the spell card image |
Language model | Open-ended text | Gemini writes the tale of the fight |
Model serving architecture
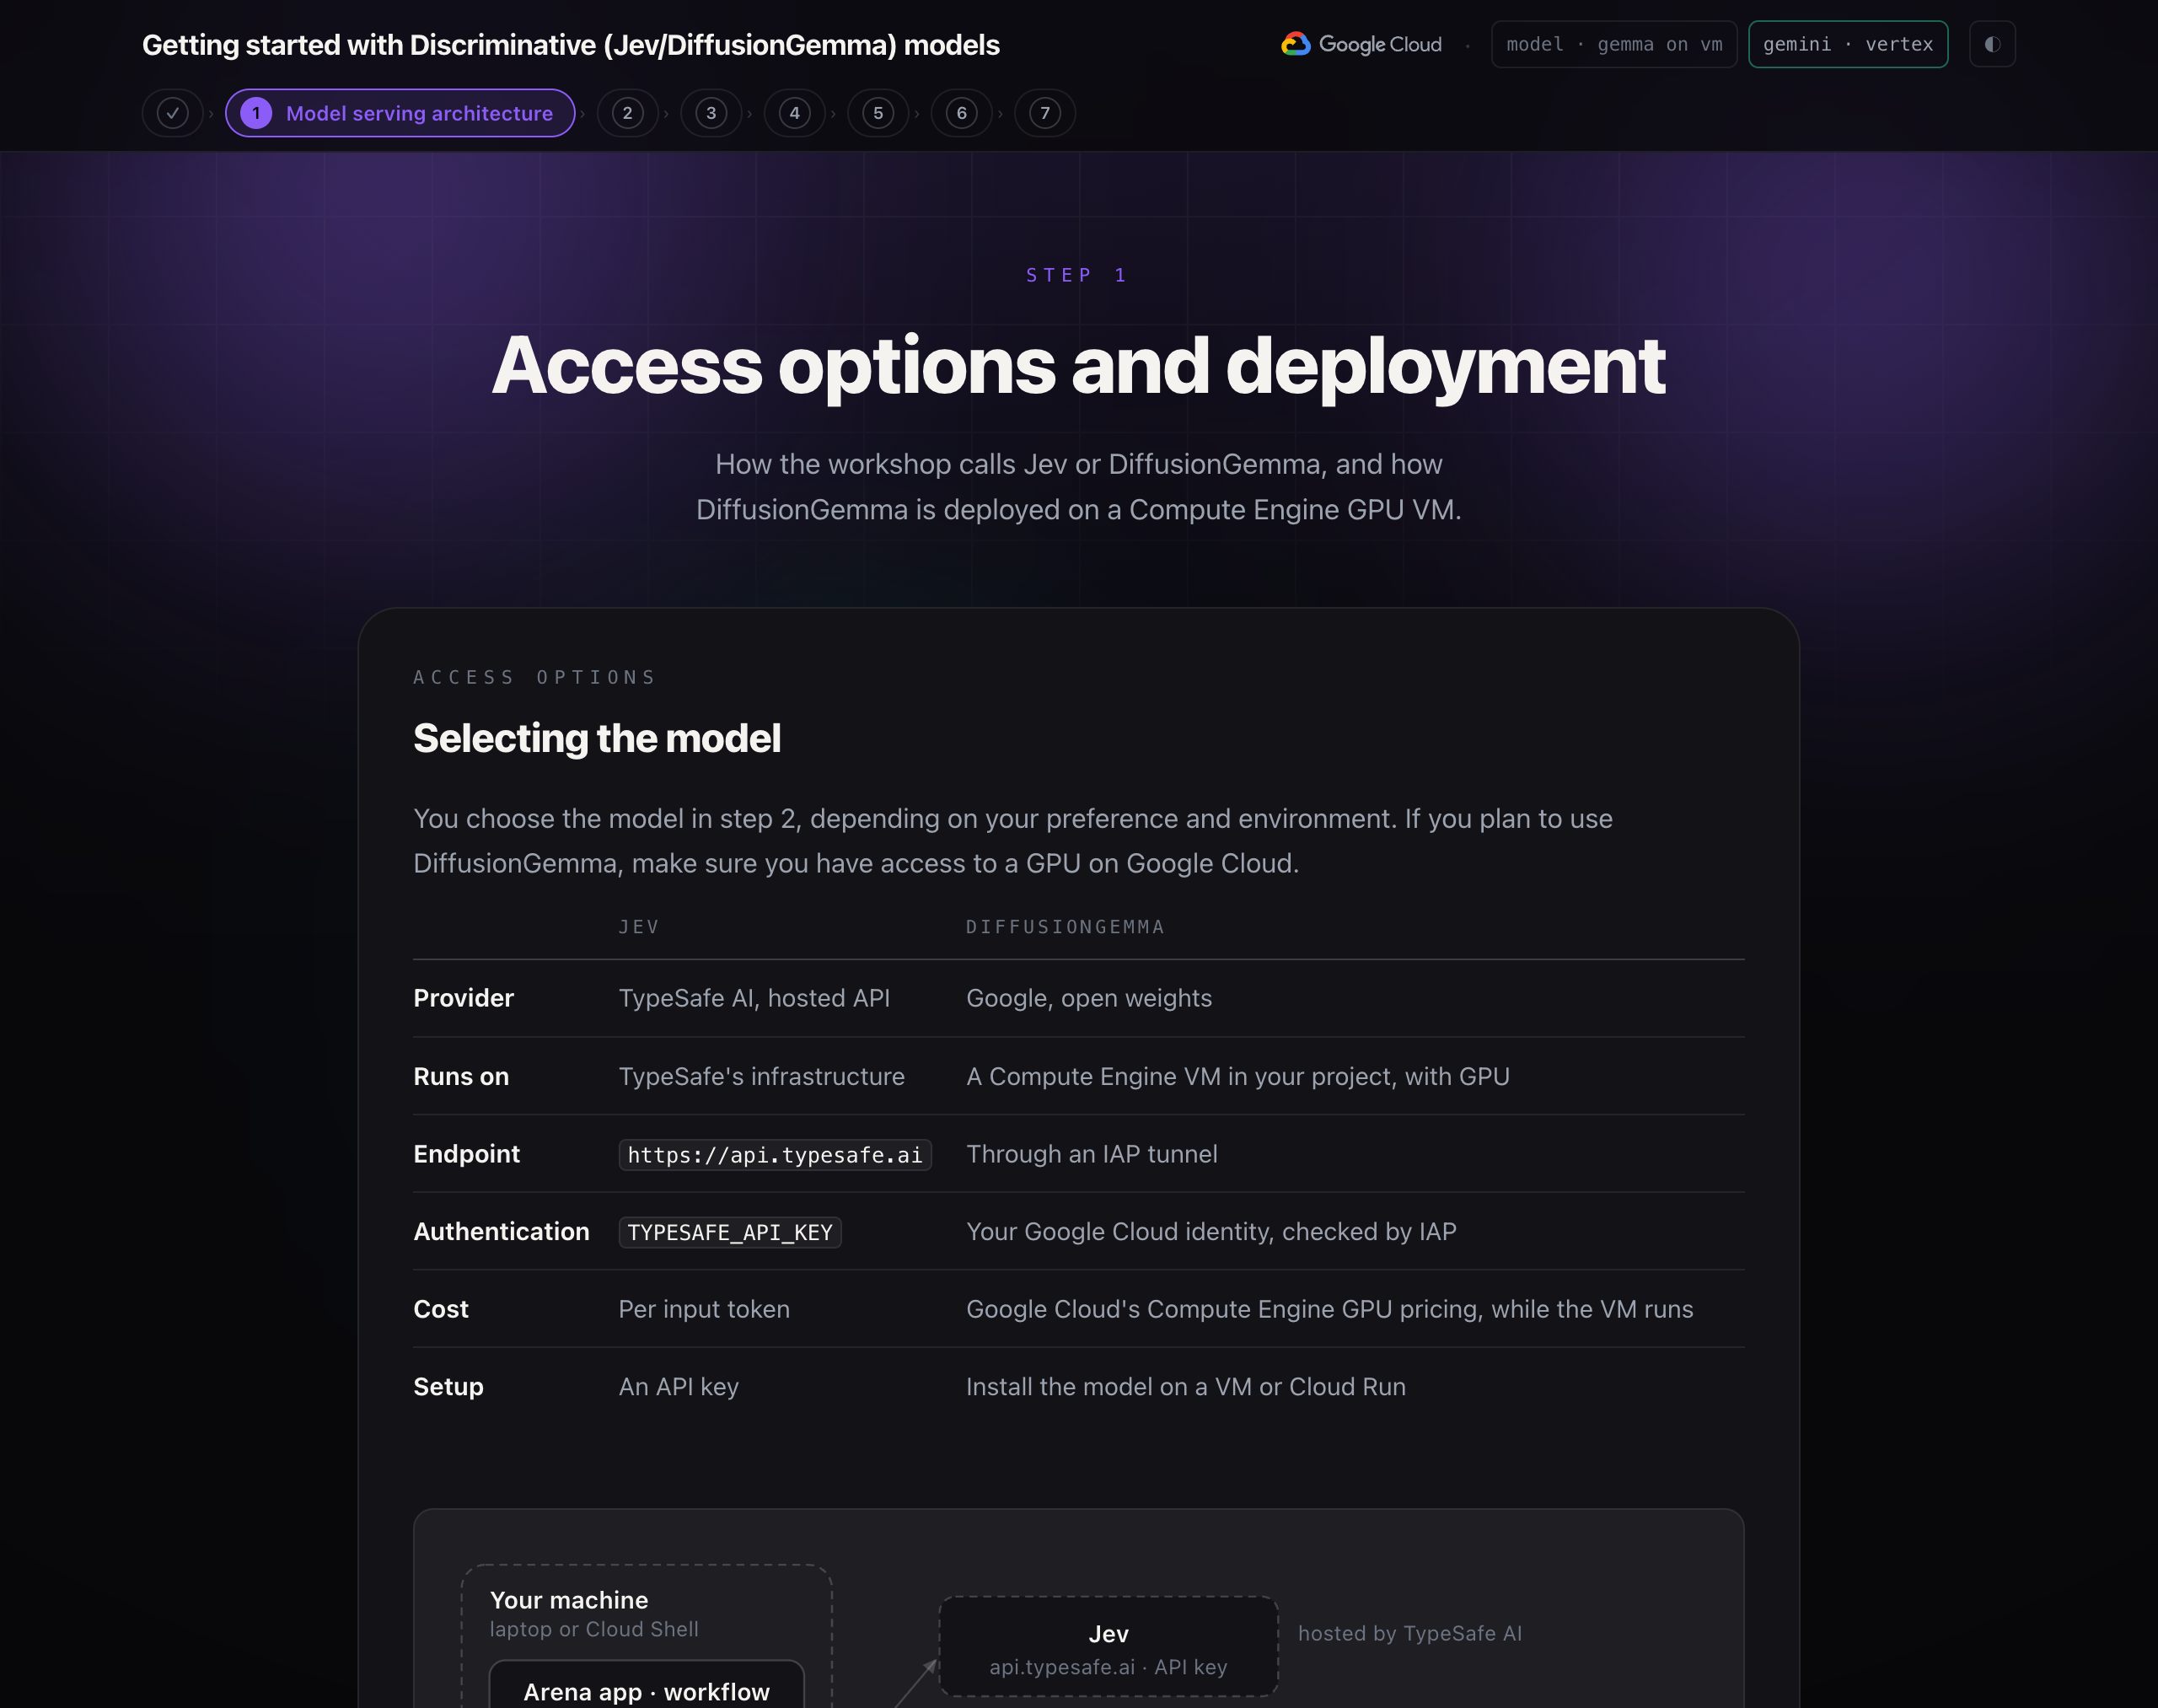
You choose the decision model in step 2 based on your preference and environment. Jev and Gemini Decisions are hosted and need only an API key. If you plan to use DiffusionGemma, make sure your Google Cloud project has GPU quota. Whichever model you choose for the fight, step 6 also calls Gemini Decisions to read the spell card, so every setup uses a Gemini API key.
Jev | DiffusionGemma | Gemini Decisions | |
Provider | TypeSafe AI, hosted API | Google, open weights | Google, hosted API |
Runs on | TypeSafe's infrastructure | A Compute Engine VM in your project, with GPU | The Gemini Developer API |
Endpoint |
| Through an IAP tunnel |
|
Authentication |
| Your Google Cloud identity, checked by IAP |
|
SDK |
|
|
|
Input | Text | Text | Text, images, audio, video, PDF |
Cost | Per input token | Compute Engine GPU pricing while the VM runs | Per input token, with a no-cost tier |
Setup | An API key | Install the model on a Compute Engine VM | An API key |
Data flow
- The arena app or the ADK workflow builds a request containing what the opponent did and three questions.
scripts/decisions.pyhands the request to the SDK for the model you chose.- For Jev, the TypeSafe SDK sends
POST /v1/systemoneover HTTPS toapi.typesafe.ai, with the API key as a bearer token. - For DiffusionGemma, the TypeSafe SDK sends the same request to
localhost:8096. A backgroundgcloud compute start-iap-tunnelprocess forwards it through Identity-Aware Proxy, which checks your Google identity, to port 8080 on the VM. On the VM, djev-run runs DiffusionGemma through vLLM on the GPU and reads the probability of each allowed option. - For Gemini Decisions, the Google Gen AI SDK sends
POST /v1beta/decisionsover HTTPS togenerativelanguage.googleapis.com, with the API key in thex-goog-api-keyheader and modelgemini-decision-1. - All three return the same kind of response: an answer per question, with probabilities and a confidence score. The workshop code applies its thresholds and acts.
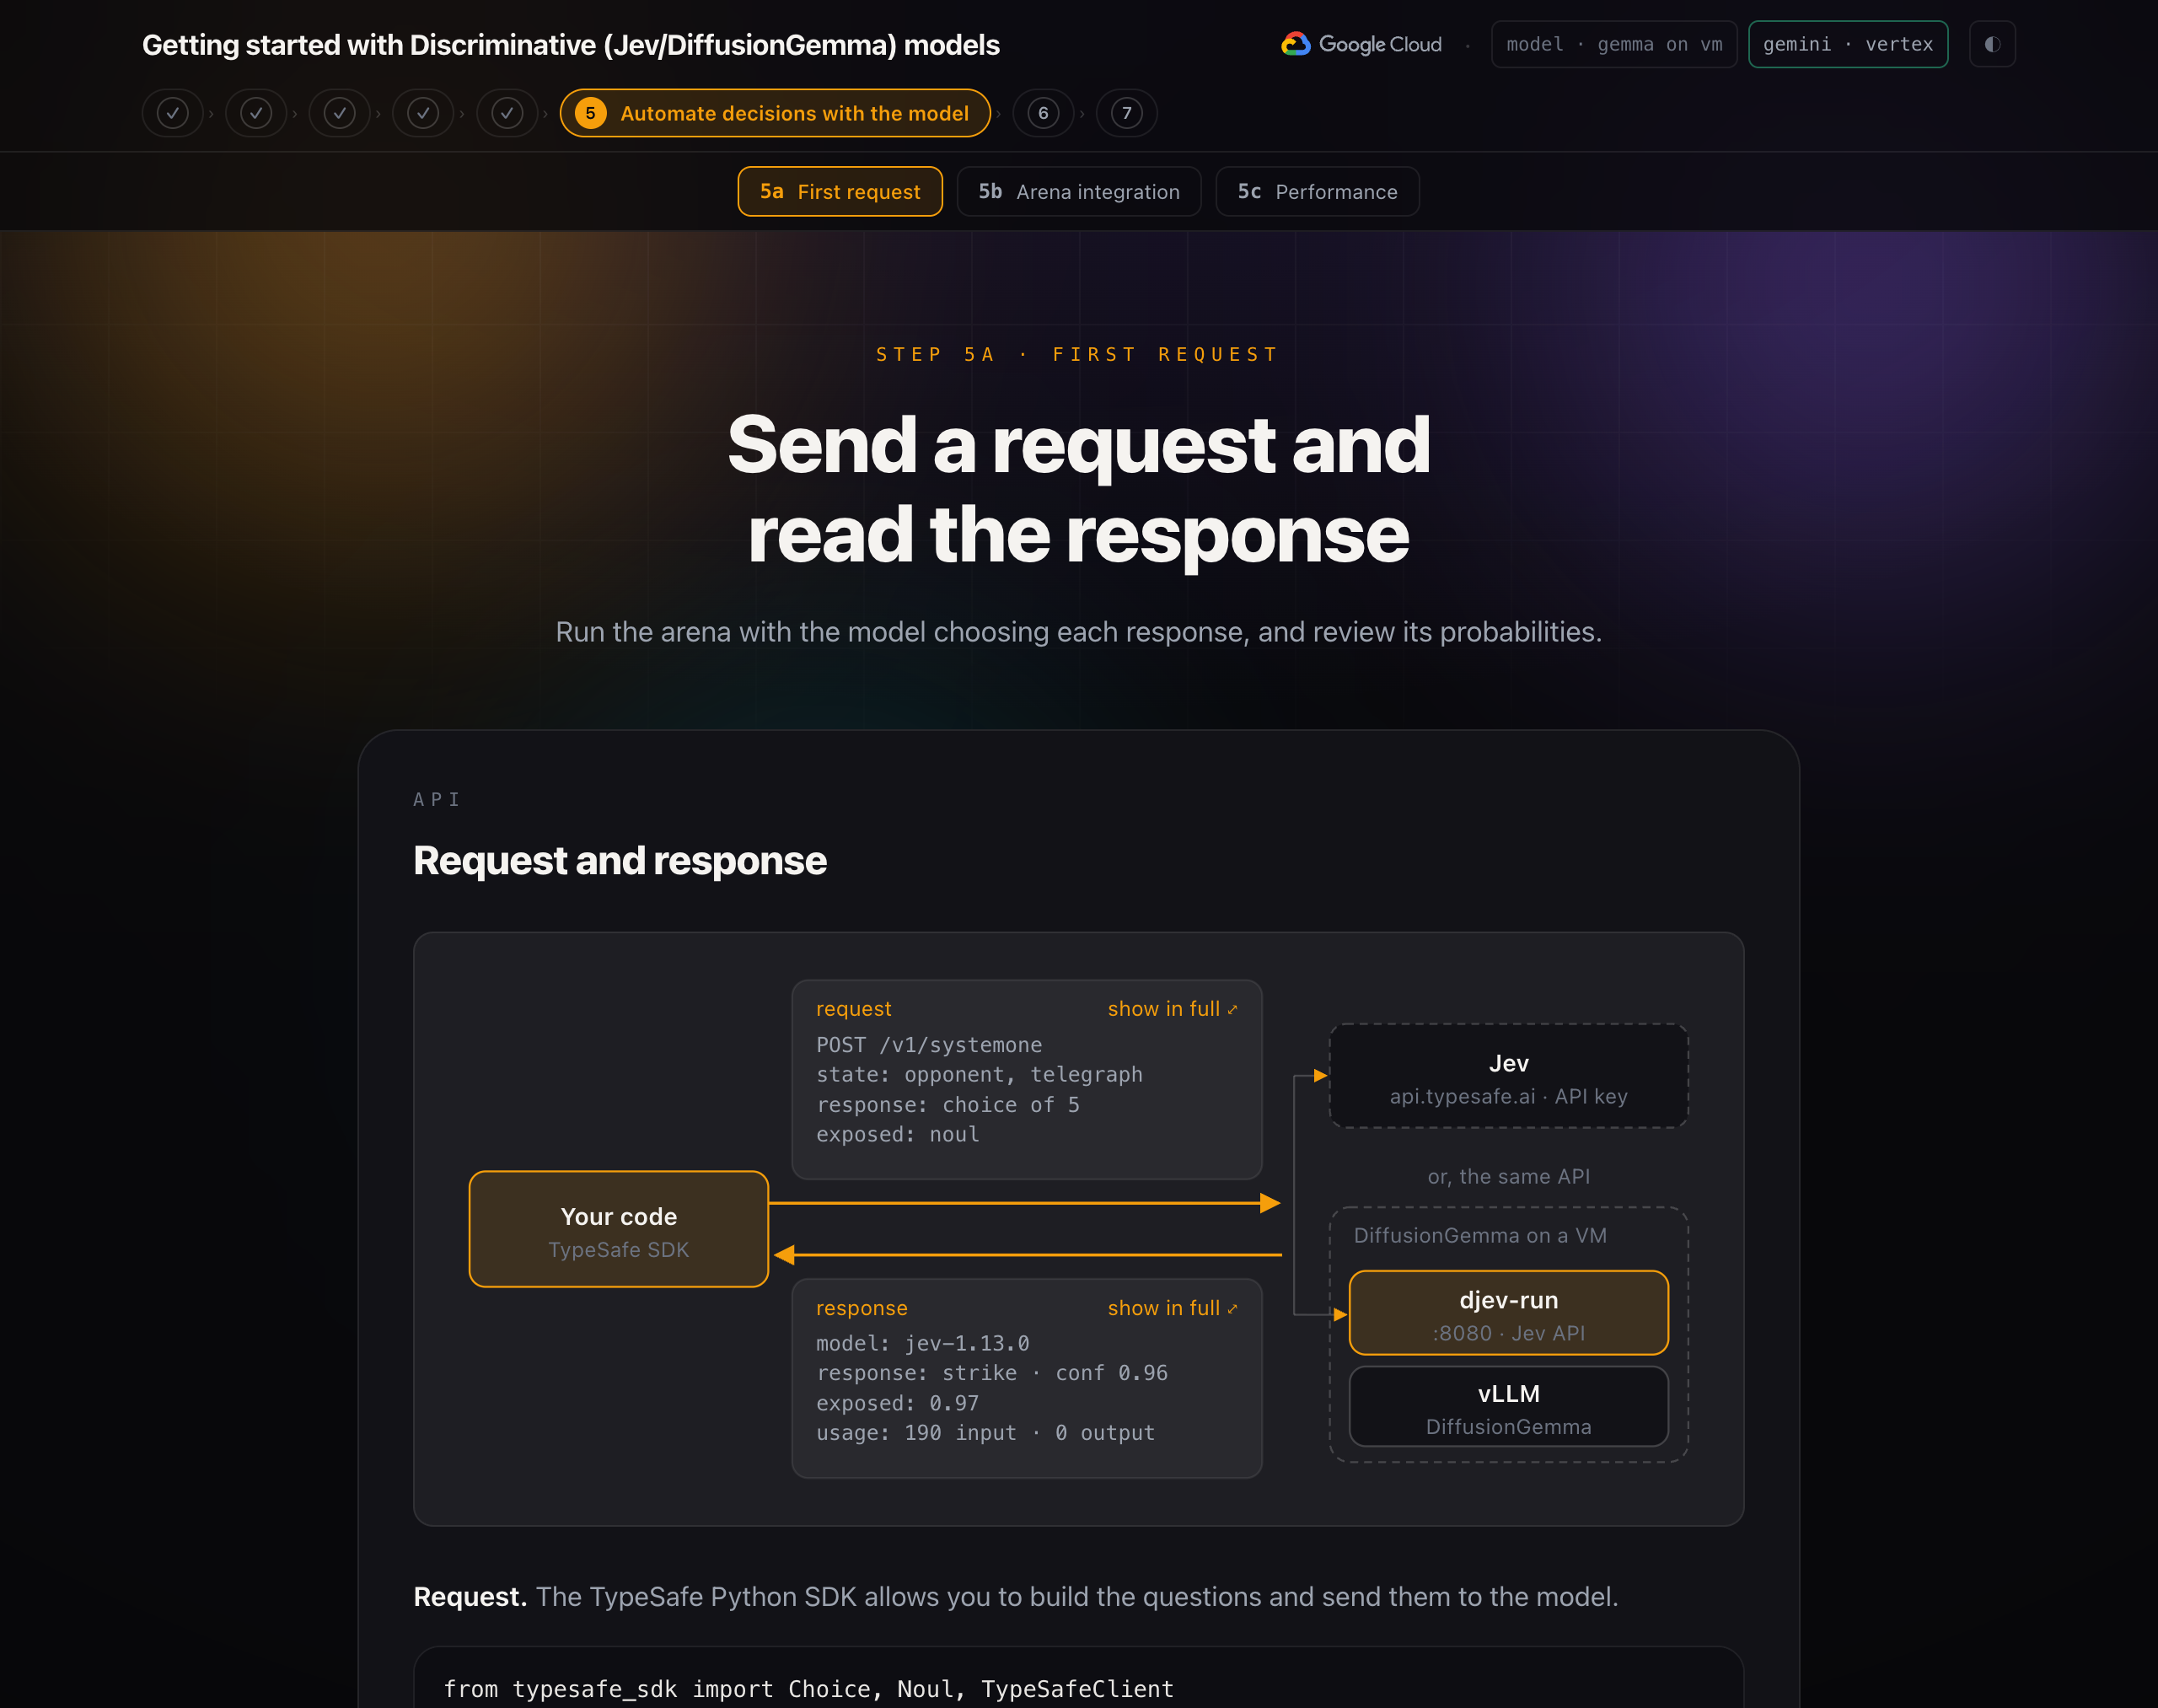
Two SDKs for the same request
Both SDKs take a set of named questions (Choice, Score, or Noul) and return one typed answer per question:
TypeSafe SDK | Google Gen AI SDK | |
Package |
|
|
Client |
|
|
Call |
|
|
What to judge |
|
|
Model | set on the client, |
|
Questions |
| the same three types, as plain dicts |
Answers |
| the same fields |
DiffusionGemma on Compute Engine
scripts/setup_gemma.sh builds this stack in your project:
- Checks that the region has quota for an NVIDIA L4 GPU.
- Enables the Compute Engine and IAP APIs, and creates the firewall rule
allow-iap-djev, which admits only the IAP address range on ports 22 and 8080. - Creates the VM
djev-l4with machine typeg2-standard-4(4 vCPUs, 16 GB memory), an L4 GPU with 24 GB VRAM, a 100 GB disk, and the Deep Learning VM image with NVIDIA driver 580. If a zone has no GPU capacity, it tries the next zone. - On first boot, the VM startup script installs Docker and the NVIDIA Container Toolkit, pulls the djev-run container image, downloads the weights from Hugging Face (17.5 GB), and starts the container with GPU access on port 8080. First boot takes about 15 minutes, and later boots take about 2 minutes.
- Writes the connection settings to
.envand opens the IAP tunnel.
Task | Command |
Stop the VM (keeps the disk) |
|
Start it again |
|
Check the tunnel |
|
Delete everything |
|
Set up the model
The SDKs
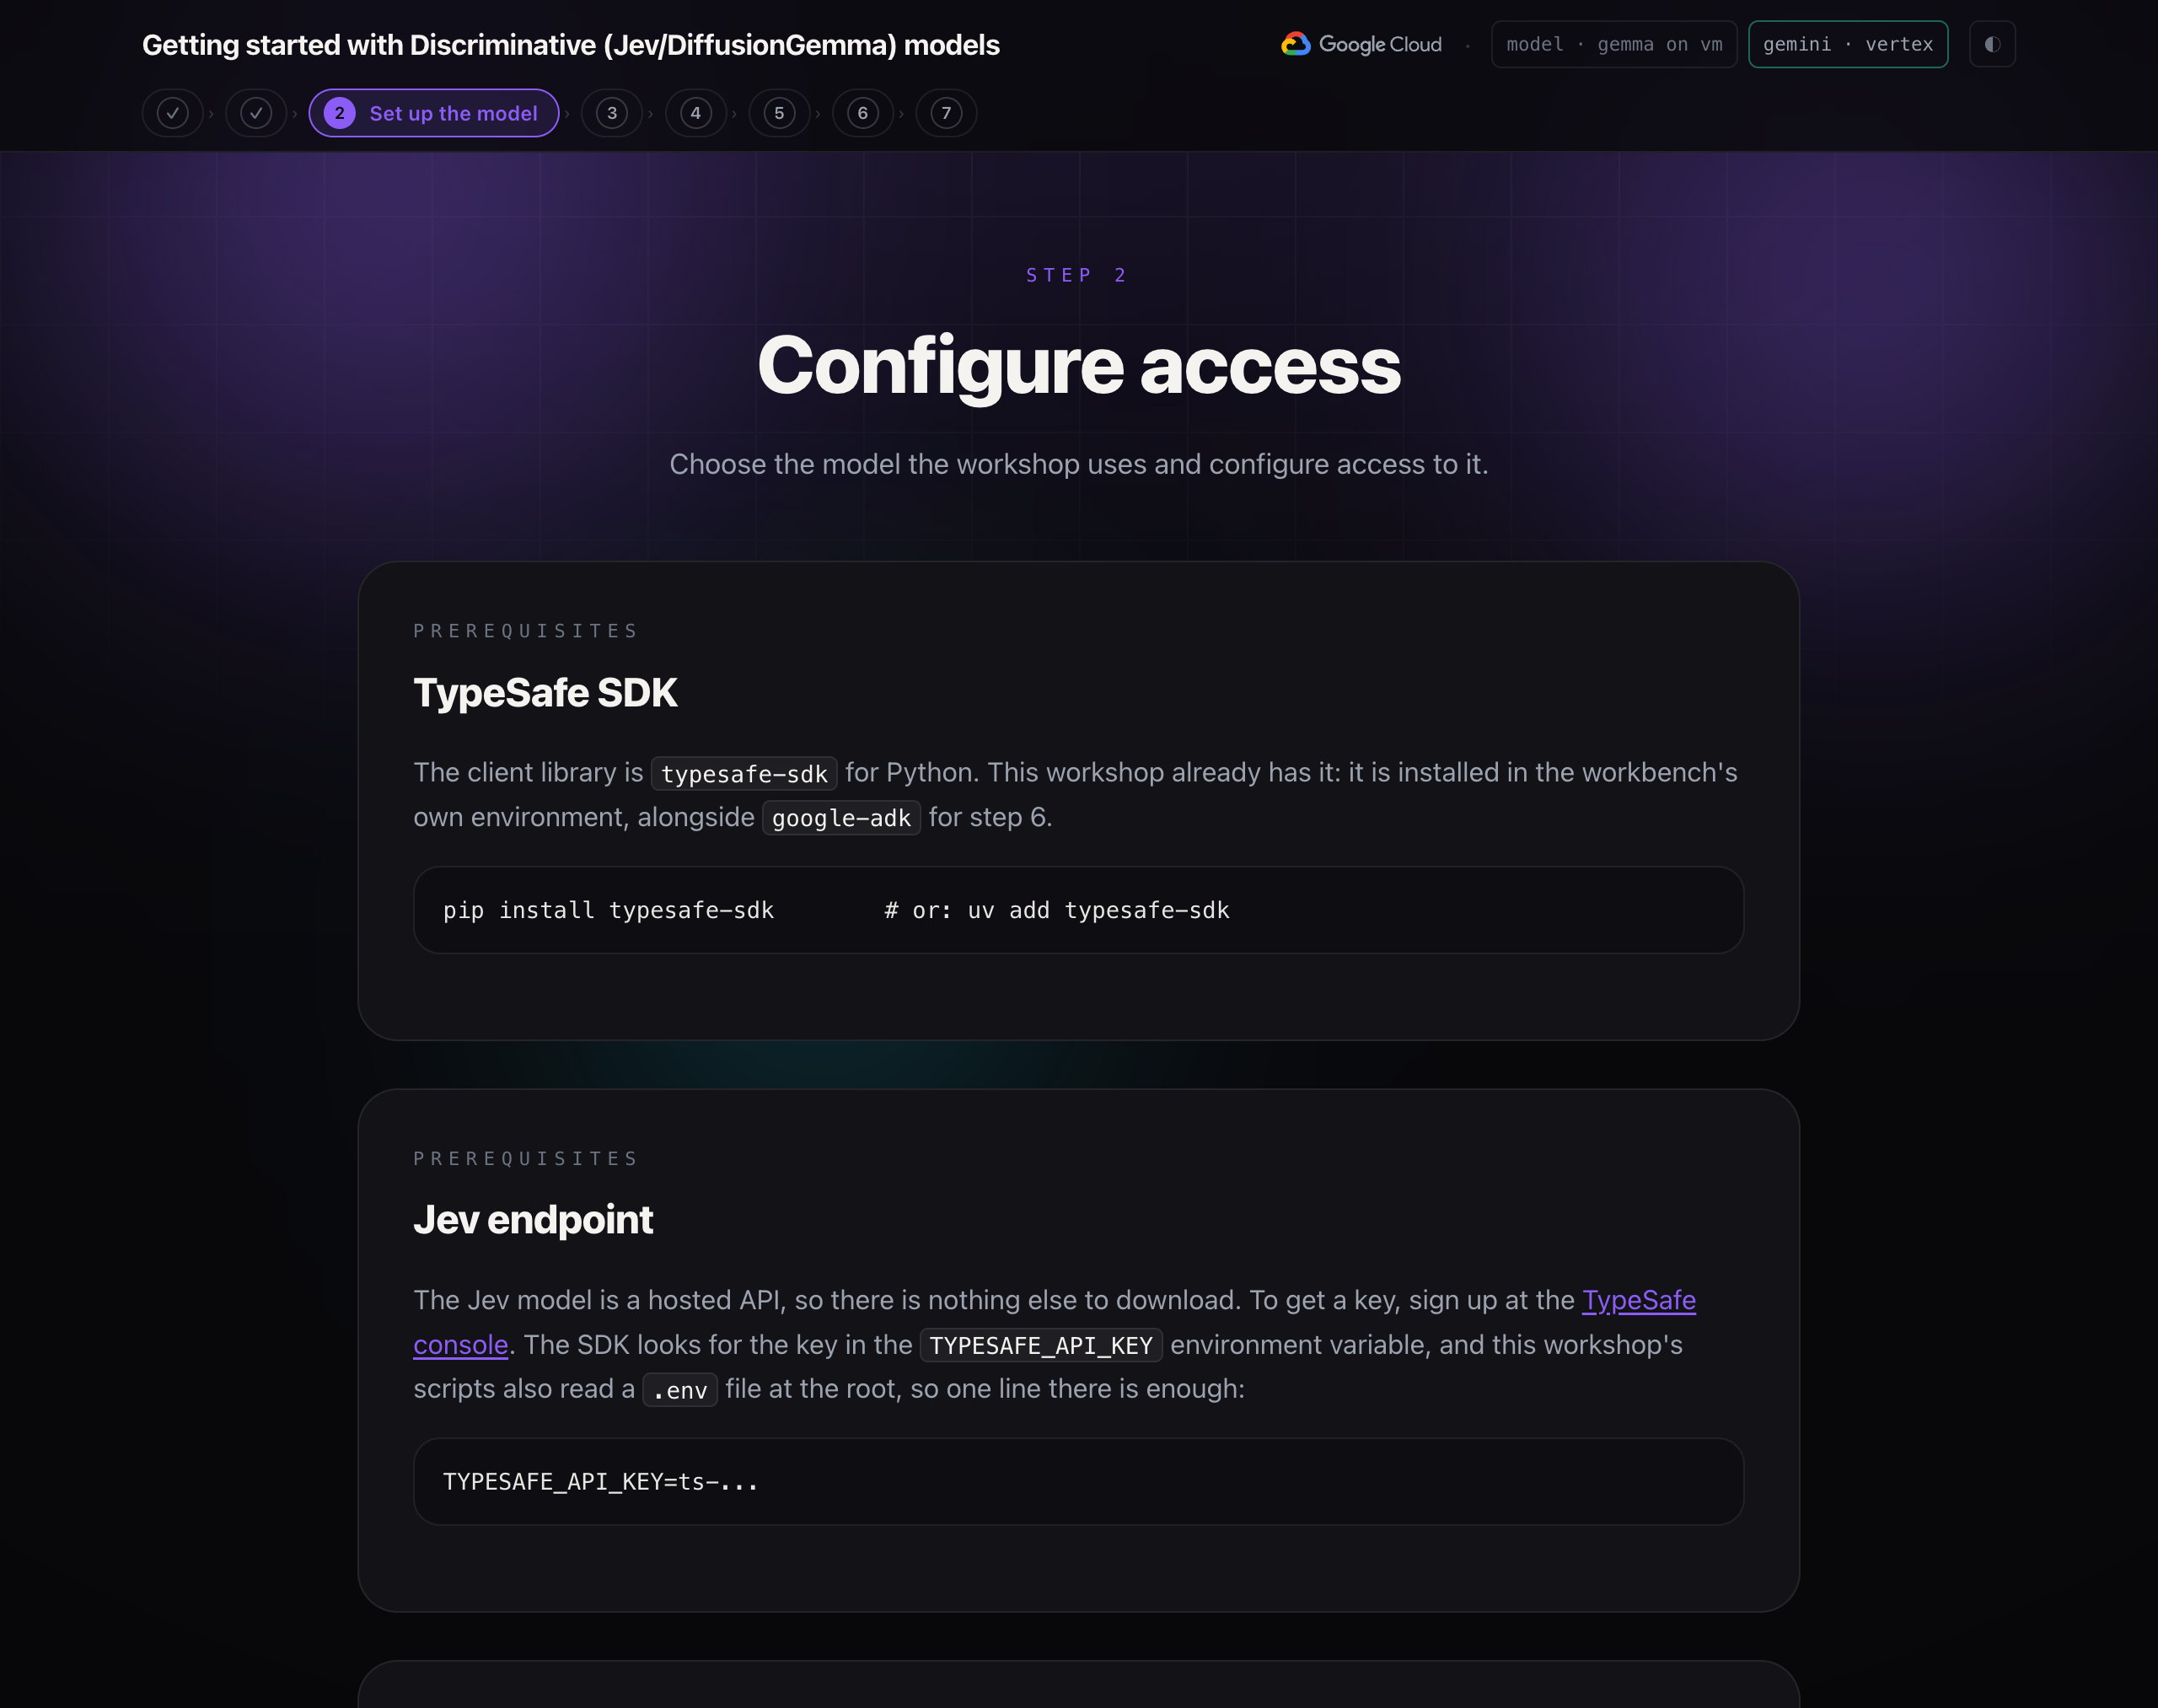
Two client libraries reach the three models: typesafe-sdk for Jev and DiffusionGemma, and google-genai for Gemini Decisions. Both are already installed in the workbench's environment alongside google-adk.
pip install typesafe-sdk        # Jev, DiffusionGemma
pip install google-genai        # Gemini Decisions
API keys
Jev and Gemini Decisions are hosted APIs, so nothing needs to be downloaded. Each SDK reads its key from an environment variable, and the workshop scripts also load .env from the repository root:
Key | Where to get it | Used for |
| Created by | Gemini Decisions, and step 6 for every model choice |
| Jev, if you choose it |
GEMINI_API_KEY=AIza...
TYPESAFE_API_KEY=apikey_...
In step 2 of the workbench, you confirm or paste your Gemini API key first, then pick one of the three decision model cards (Jev, DiffusionGemma, or Gemini Decisions). Setup verifies each key with a real request before saving it to .env.
Use DiffusionGemma
djev-run reimplements Jev's API, serving POST /v1/systemone with the same noul, choice, and score questions backed by DiffusionGemma, Google DeepMind's open diffusion model (26B total parameters, about 4B active, Apache 2.0). Because the wire format is identical, typesafe-sdk talks to it unchanged. When selected, the status pill at the top right of the workbench reads gemma on vm.
Why a diffusion model works here: It fills a whole block of positions at once, with every position seeing the full input, so the probability of each allowed option can be read in a single step. A standard autoregressive language model produces one token at a time and would have to be sampled repeatedly.
Use Gemini Decisions
Gemini Decisions is Google's hosted decision model (gemini-decision-1) on the Gemini Developer API. Nothing needs to be deployed. The Google Gen AI SDK sends requests to POST /v1beta/decisions with GEMINI_API_KEY, and answers come back in the same shape as Jev's. When selected, the status pill at the top right reads gemini decisions. Because gemini-decision-1 also reads images, step 6 uses it to read the spell card regardless of which model fights.
Play the game manually
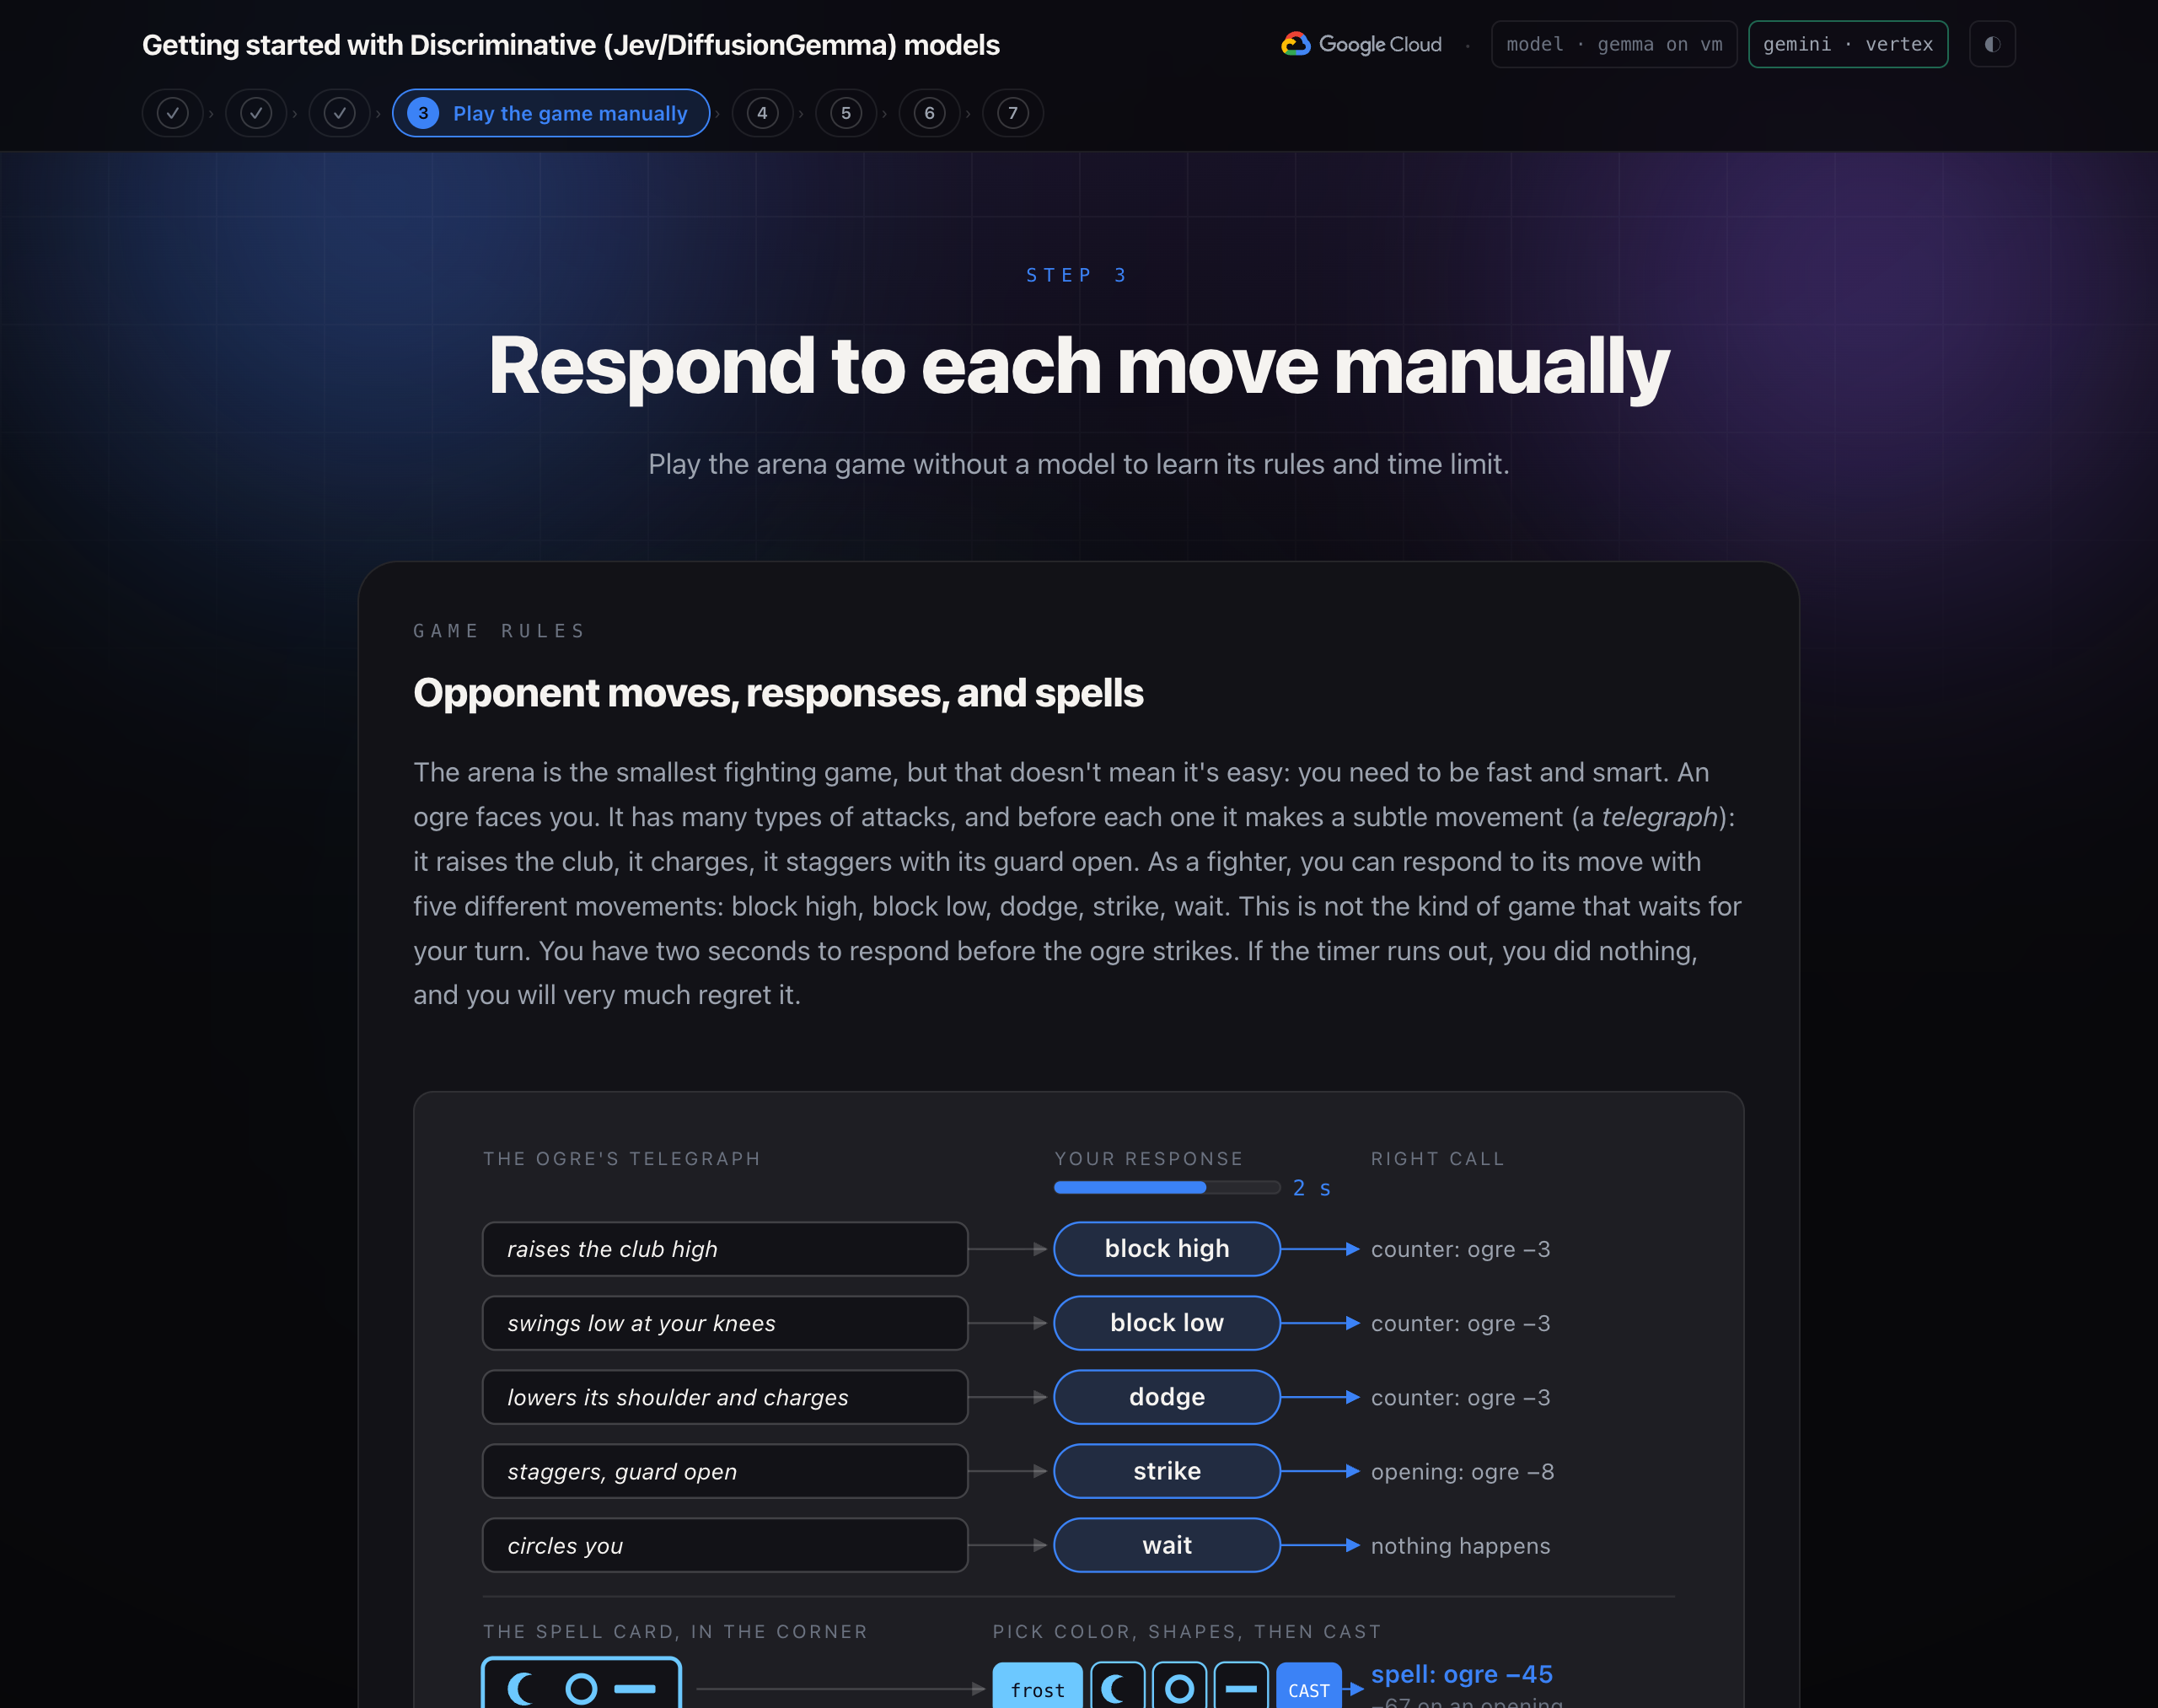
In step 3, you start the arena server from the workbench terminal with cd app and python3 main.py (which listens on port 8090 and appears inside the workbench's Arena panel), then play in You fight mode.
An ogre faces you with ten attack patterns. Before each move, it makes a subtle movement (a telegraph), such as raising its club, charging, or staggering with its guard open. You can respond with five actions: block high, block low, dodge, strike, or wait (buttons or keys 1 to 5). You have two seconds to respond before the ogre strikes.
In the top-left corner of the ring is a spell card: a colored border with three shapes. Only a spell that matches the card deals heavy damage. Under the ring, you pick the card's color and its three shapes from left to right, then press CAST, all while continuing to react to incoming attacks before the two-second timer expires. A wrong spell fizzles. In step 6, a model reads the spell card for you.
Key takeaway: A fight is a stream of small decisions with a deadline on each one. Most real-time software automation has the same shape.
Discriminative model concepts
Decisions in software
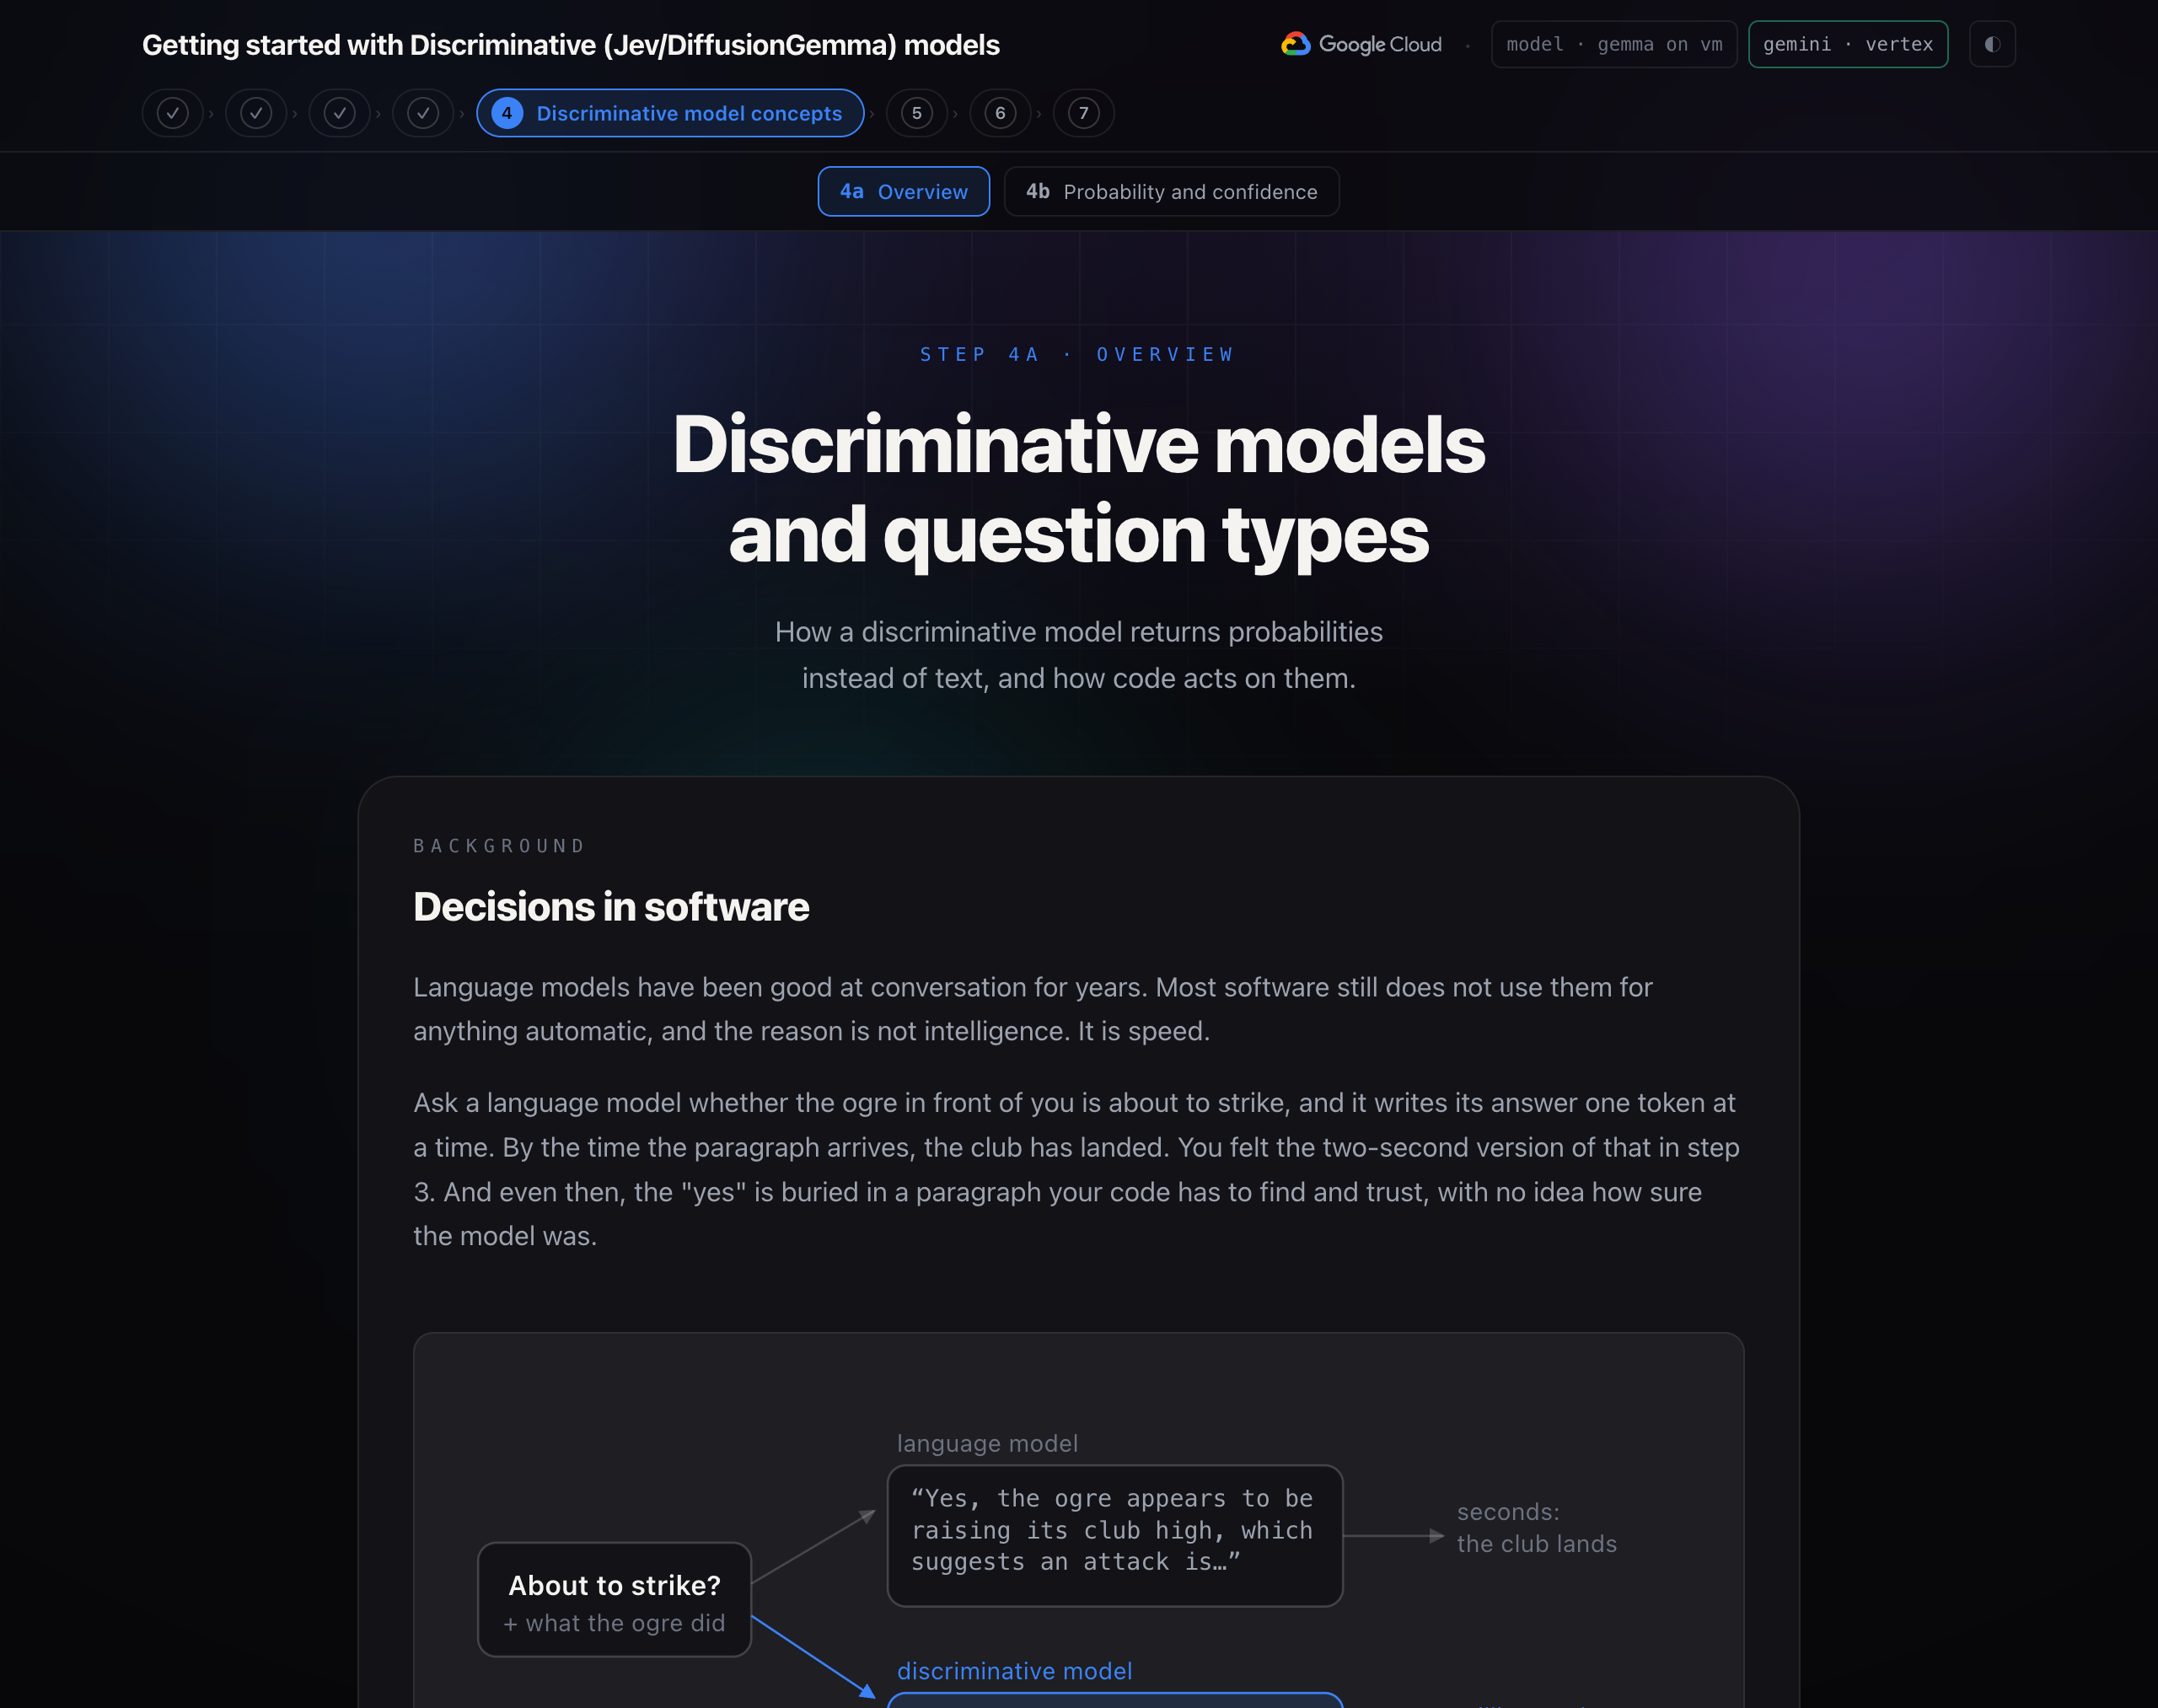
Language models have been good at conversation for years, yet most software still avoids putting them directly inside automated loops because of latency and output parsing. Ask a language model whether the ogre is about to strike, and it writes tokens one by one while the club lands, leaving your code to extract an answer without a calibrated probability.
A discriminative model reads the input and your typed questions and answers in a single pass, in milliseconds. Each answer includes probabilities and a confidence value, with no free-form text or JSON formatting to parse.
System One and System Two models
The terminology comes from Daniel Kahneman's Thinking, Fast and Slow. System Two is deliberate, step-by-step reasoning. System One is fast pattern matching.
A language model acts as a System Two engine, reasoning token by token. A discriminative model acts as a System One model: it does not reason out loud or generate prose, and it answers every question in one pass, taking roughly 70 to 500 milliseconds at a fraction of a cent per thousand decisions.
Key takeaway: A language model writes. A decision model decides. Most of what software needs from AI is a decision.
Limitations
A discriminative model will not generate text, write code, hold a conversation, do arithmetic, or follow a multi-step chain of reasoning. Jev and DiffusionGemma read text only. Gemini Decisions also reads images, audio, video, and PDFs, while still answering strictly with a choice, a score, or a yes/no probability.
- Jev is TypeSafe AI's hosted API, released in September 2026 (
jev-1.13, aliasjev-latest). There are no published weights, so it is called over HTTPS. - DiffusionGemma is Google's open-weights diffusion model. Open-source servers such as djev-run expose Jev's API in front of it, allowing existing TypeSafe SDK code to run against your own GPU VM unchanged.
- Gemini Decisions (
gemini-decision-1), announced in November 2026, is Google's hosted System One model on the Gemini Developer API. Called through the Google Gen AI SDK with a Gemini API key, it accepts the same three question types and returns probabilities and confidence with zero output tokens.
State and questions: Choice, Score, and Noul
Each call sends something to judge and one or more named questions, which are evaluated in parallel in a single pass:
- Choice picks one option from a named set of up to 255 options. It returns the top option, a probability for every option, and a confidence score. Use it when options are unordered categories, such as
block_high,block_low,dodge,strike, andwait. - Score rates the input along 2 to 10 ordered levels. It returns a probability-weighted position along the scale (for example,
1.35when probabilities arenone: 0.05,light: 0.55,heavy: 0.40), each level's probability, and a confidence score. Use it when the answer is a degree, such as incoming hit severity (choose()treats1.5or higher as a heavy hit). - Noul asks a yes/no question and returns the probability that the answer is yes, from
0(strong no) to1(strong yes), with0.5meaning uncertain.
Write focused questions
A discriminative model performs best when each question asks one specific, well-scoped thing, such as "What is the right response?", "Is the opponent exposed?", and "How much damage is about to land?". Option and level descriptions teach the rules at request time (block_high: "Raise the shield against a high swing."), and options can change dynamically per call (cast is included only when a spell is ready).
Probabilities and confidence
A Choice answer is a probability distribution over the allowed options, not just a label. In the open DiffusionGemma server, the prompt formats each question as a blank (such as response: ▢), reads the model's logits at each blank in one pass, restricts them to the allowed option labels, and applies a softmax so the probabilities sum to 1.
Confidence summarizes how sure the answer is:
- Jev computes confidence from how spread out the distribution is across the options (
1when all probability is on one option,0when evenly spread;(3 × largest − 1) / 2for three options) and trains for calibrated probabilities. - DiffusionGemma (via djev-run) reports the top probability averaged across reads.
- Gemini Decisions reports the estimated probability that the top answer is right. In this workshop's calls, that value equals the top probability, which reads slightly higher than Jev's spread-based number on the same distribution. Test your thresholds on the model you deploy.
Key takeaway: The answer tells you what. The confidence tells you whether to act.
Thresholds
Your code compares the returned confidence or probability against fixed thresholds to choose what happens next, such as acting automatically at high confidence, confirming at medium confidence, and falling back to a safe default at low confidence:
TRUST_CONFIDENCE = 0.40    # below this, the model is guessing between responses
HEAVY_DANGER = 1.5         # a danger score at or above this is a heavy hit
SPEND_ON_OPENING = 0.60    # exposed at or above this, with a spell ready, cast

def choose(answers, spell_ready):
    response = answers["response"]
    exposed = answers["exposed"].noul
    danger = answers["danger"].score

    action = response.choice
    if response.confidence < TRUST_CONFIDENCE and danger >= HEAVY_DANGER:
        action = "dodge"                   # shaky answer, heavy hit coming
    if spell_ready and action == "strike" and exposed >= SPEND_ON_OPENING:
        action = "cast"                    # a clear opening is worth the spell
    return action
Warning: A valid answer is not always a correct one. A discriminative model never invents an unoffered option, yet it can still pick the wrong option with high confidence. Test your questions and thresholds against examples you have already judged.
Automate decisions with the model
Request and response
A request has two parts: what to judge, and named questions about it.
With the TypeSafe SDK, for Jev and DiffusionGemma:
from typesafe_sdk import Choice, Noul, TypeSafeClient

with TypeSafeClient() as client:
    response = client.system_one(
        state={"opponent": OPPONENT, "telegraph": telegraph},
        questions={
            "response": Choice(instructions="What is the right response?", criteria=RESPONSES),
            "exposed": Noul(instructions="Is the opponent exposed to a counter-attack right now?"),
        },
    )

response.answers["response"].choice     # "strike"
response.answers["exposed"].noul        # 0.97
With the Google Gen AI SDK, for Gemini Decisions:
import json
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})
result = client.decisions.create(
    model="gemini-decision-1",
    input=json.dumps({"opponent": OPPONENT, "telegraph": telegraph}),
    questions={
        "response": {"type": "choice", "instructions": "What is the right response?", "criteria": RESPONSES},
        "exposed": {"type": "noul", "instructions": "Is the opponent exposed to a counter-attack right now?"},
    },
)

result.answers["response"].choice       # "strike"
result.answers["exposed"].noul          # 0.98
One function for both SDKs
In the workshop, questions are written once as plain dicts and passed to ask(about, questions) in scripts/decisions.py. about is sent as state with typesafe-sdk or as input with google-genai, returning answers with the same .choice, .noul, .score, and .confidence attributes:
from decisions import ask

answered = ask(
    about={"opponent": OPPONENT, "telegraph": telegraph},
    questions={
        "response": {"type": "choice", "instructions": "What is the right response?", "criteria": RESPONSES},
        "exposed": {"type": "noul", "instructions": "Is the opponent exposed to a counter-attack right now?"},
    },
)

answered.answers["response"].choice
answered.model, answered.sdk            # which model and SDK answered
In step 5a, you assemble QUESTIONS first and then TELEGRAPH in scripts/first_call.py, and run python3 scripts/first_call.py (adding --curl prints the raw HTTP request for your active model).
One request per tick
In step 5b, updating the game adds app/reflex.py and app/mode_model.py, enabling the Discriminative model fights mode in the arena. On each tick, mode_model.py calls decisions.ask() with three questions in a single request:
def reflex_questions(spell_ready):
    options = dict(RESPONSES)
    if spell_ready:
        options["cast"] = CAST                # only offered when there is a spell
    return {
        "response": {"type": "choice", "criteria": options,
                     "instructions": "The opponent has just done this. What is the right response?"},
        "exposed": {"type": "noul",
                    "instructions": "Is the opponent exposed to a counter-attack right now?"},
        "danger": {"type": "score", "criteria": ["None: this is not an attack.", "A light hit.", "A heavy hit."],
                   "instructions": "How much damage is about to land if the fighter does nothing?"},
    }
The choose() function
choose() reads the typed answers and applies the arena's threshold policy in plain Python before handing the chosen action to the game engine:
TRUST_CONFIDENCE = 0.40
HEAVY_DANGER = 1.5
SPEND_ON_OPENING = 0.60

def choose(answers, spell_ready):
    action = answers["response"].choice
    if answers["response"].confidence < TRUST_CONFIDENCE and answers["danger"].score >= HEAVY_DANGER:
        action = "dodge"                      # shaky call, heavy hit coming: play it safe
    if spell_ready and action == "strike" and answers["exposed"].noul >= SPEND_ON_OPENING:
        action = "cast"                       # opening spotted and spell ready: spend the spell
    ...
Key takeaway: Keep the questions and the thresholds together in one file. They are the part of a System One integration you will tune most.
Response time, input-based pricing, and decision logic
- Response time per decision. Each tick returns inside the 70 to 500 ms window: Jev answers in roughly 100 ms, Gemini Decisions in roughly 300 ms (about 0.3 s per tick), and DiffusionGemma on a single L4 GPU in roughly 450 ms. All three are fast enough for a real-time loop or an inline request check.
- Input-based pricing. Output tokens are zero because nothing is generated. Jev costs $0.042 per million input tokens and Gemini Decisions costs $0.10 per million input tokens (about $0.002 for a full 60-tick fight, with a no-cost tier available). Because extra questions add very few input tokens, the arena asks
exposedon every tick even when neitherstrikenorcastis chosen, a pattern TypeSafe calls speculative fan-out. - Combine confidence and danger. When response confidence is below
0.40anddangeris1.5or higher,choose()overrides the choice withdodge. If a decision keeps misfiring, tighten the question wording and option descriptions before moving the threshold.
Combine models in an ADK workflow
Limits of per-tick decisions
Step 5 ends in a draw. Your fighter avoids damage and counters cleanly, yet the ogre still stands at tick 60. The ogre starts with 300 hit points, while a right counter deals 3 damage and a strike into an opening deals 8. Sixty ticks of melee counters cannot reach 300 HP.
Winning requires the spell card in the corner of the ring: a valid spell deals 45 damage, 67 on an opening, or 25 when two of the three shapes match.
Assign each task to the right model
The spell card shows one of four border colors and three shapes chosen from eight options. Because both the color and each shape come from a known, bounded set, reading the spell card is also a discriminative decision problem for a model that accepts images.
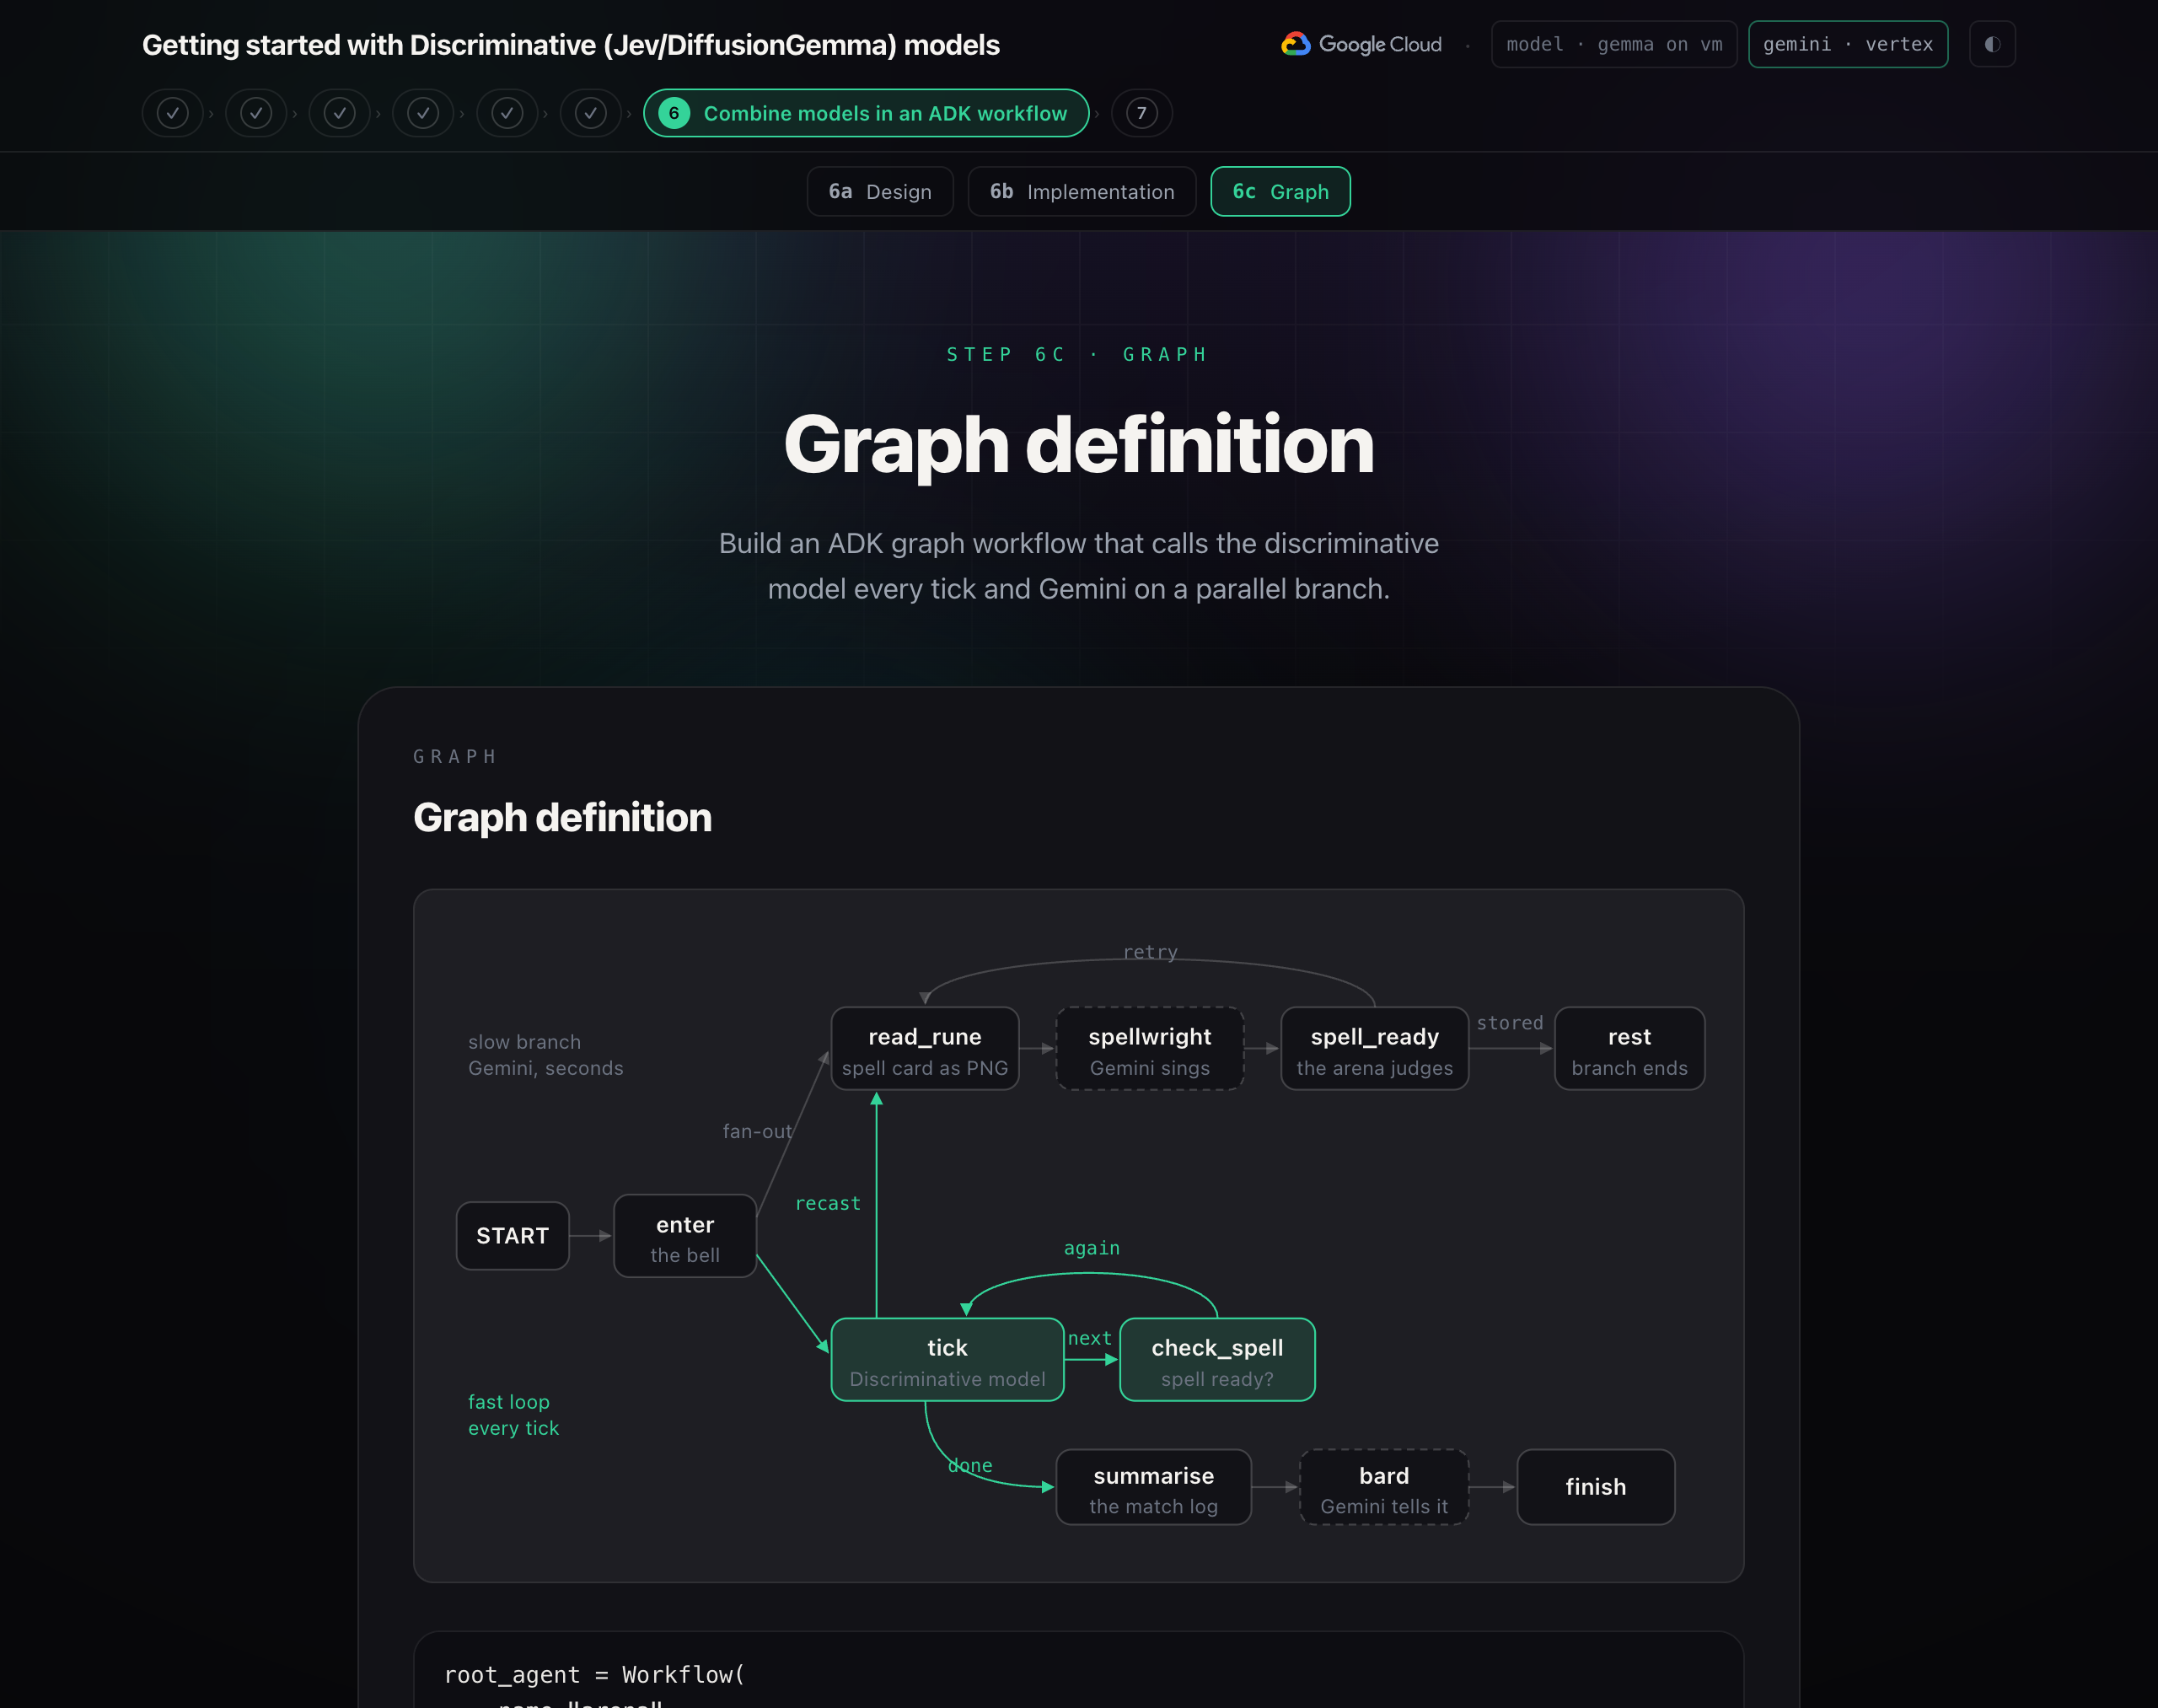
The ADK workflow in agents/arena/agent.py assigns each job to the tool that fits it:
- Your chosen decision model fights (
tick). Every tick makes onedecisions.ask_asynccall using the model from step 2 and never waits for the spell card. - Gemini Decisions reads the spell card (
read_card). Started on its own branch at the opening bell and again after each cast,read_cardfetches the PNG from the arena and asksgemini-decision-1four choice questions (element,first,second, andthird). The arena judges the reading against the card's hidden answer; a misread burns the card and routes"again". - Deterministic code holds the rules (
choose()).choose()spends a ready spell as soon as an opening appears, using a fixed incantation line per element. - Gemini writes the tale (
bard). Once the fight ends,bard(anLlmAgentusinggemini-flash-latest, orJEV101_GEMINI_MODEL) writes a short present-tense summary of the match. That is the only language model call in the workflow.
A loop, and a branch beside it
An ADK Workflow is a graph of function nodes and LLM agents connected by edges. An edge targeting a tuple (read_card, tick) fans out so both nodes start together on the same Python event loop. While tick awaits its model, read_card runs, and vice versa. The two branches never call each other directly; read_card writes the judged spell into ctx.state["spell"] with no terminal output, and tick checks ctx.state.get("spell") on every exchange:
Route from | When | Goes to |
| The fight continues |
|
| A spell was just cast and a new card is on screen |
|
| Either fighter reaches 0 HP, or tick 60 |
|
Key takeaway: Put the policy in code and give each model a narrow job.
Read the spell card with Gemini Decisions
read_card sends the PNG bytes and four choice questions (element, first, second, and third) to gemini-decision-1 in a single request:
ELEMENTS = {
    "fire": "The card is red-orange.", "frost": "The card is light blue.",
    "earth": "The card is green.", "storm": "The card is purple.",
}
SHAPES = {"circle": "A solid filled circle.", "ring": "A hollow circle.", ...}

QUESTIONS = {
    "element": {
        "type": "choice",
        "instructions": "What color is this spell card? The color is its element.",
        "criteria": ELEMENTS,
    },
    "first": {
        "type": "choice",
        "instructions": "Which shape is the first one, on the left?",
        "criteria": SHAPES,
    },
    ...                        # "second" and "third": the middle and the right
}

async def read_card(ctx: Context, node_input) -> Event:
    png = _arena(ctx).rune_png()                  # what the arena screen shows
    client = genai.Client(api_key=os.environ["GEMINI_API_KEY"],
                          http_options={"api_version": "v1beta"})
    result = await client.aio.decisions.create(
        model="gemini-decision-1",
        input=[{"type": "image", "mime_type": "image/png",
                "data": base64.b64encode(png).decode()}],
        questions=QUESTIONS,
    )
    read = result.answers
    element = read["element"].choice
    shapes = [read[p].choice for p in ("first", "second", "third")]
    spell = _arena(ctx).sung({"element": element, "glyphs": shapes,
                              "incantation": INCANTATIONS[element]})
    fizzled = spell["damage"] <= 0                # a misread burns the card
    return Event(route="again" if fizzled else "stored",
                 state={"spell": None if fizzled else spell})
In step 6b, you complete the standalone card-reading exercise in branches/read_card.py (adding the "element" choice question and the base64 PNG image block) and test different cards with python3 branches/read_card.py.
The fight loop
tick plays one exchange with your chosen decision model and returns the next route (or ["read", "next"] together right after casting a spell):
async def tick(ctx: Context, node_input) -> Event:
    arena = _arena(ctx)
    spell = ctx.state.get("spell")                # what read_card left in state, if ready
    move = await asyncio.to_thread(arena.telegraph)

    answered = await decisions.ask_async(         # the model you chose in step 2
        about={"opponent": engine.OPPONENT["description"], "telegraph": move["telegraph"]},
        questions=reflex.reflex_questions(spell_ready=spell is not None),
    )

    decision = reflex.choose(answered.answers, spell_ready=spell is not None)
    entry = await asyncio.to_thread(arena.respond, decision["action"], decision, ...)
    over = entry["you"] <= 0 or entry["foe"] <= 0 or entry["tick"] >= engine.MAX_TICKS

    routes = []
    if entry["spell_used"] and not over:
        routes.append("read")                     # read the new spell card on its own branch
    routes.append("done" if over else "next")
    return Event(output="fight", route=routes, state={"tick": ..., ...})
In the second part of step 6b, you assemble tick inside branches/fight_loop.py and run python3 branches/fight_loop.py to play through five moves.
Graph definition
root_agent = Workflow(
    name="arena",
    edges=[
        ("START", enter),
        (enter, (read_card, tick)),                   # read the card and fight, together
        (read_card, {"again": read_card, "stored": rest}),
        (tick, {"next": tick, "read": read_card, "done": summarize}),
        (summarize, bard, finish),
    ],
)
In step 6c, you update the game to workflow mode (app/mode_workflow.py and app/static/modes/workflow.js), verify your keys with python3 scripts/check_setup.py, and press Start in Workflow fights. Under the ring, the SPELL CARD panel displays the four answers and confidence scores from Gemini Decisions, the REFLEX panel displays each tick's decision, and THE TALE panel displays Gemini's retelling once the ogre falls. You can also run adk web agents from the workshop root to inspect the workflow graph and events in the ADK developer UI.
Summary and next steps
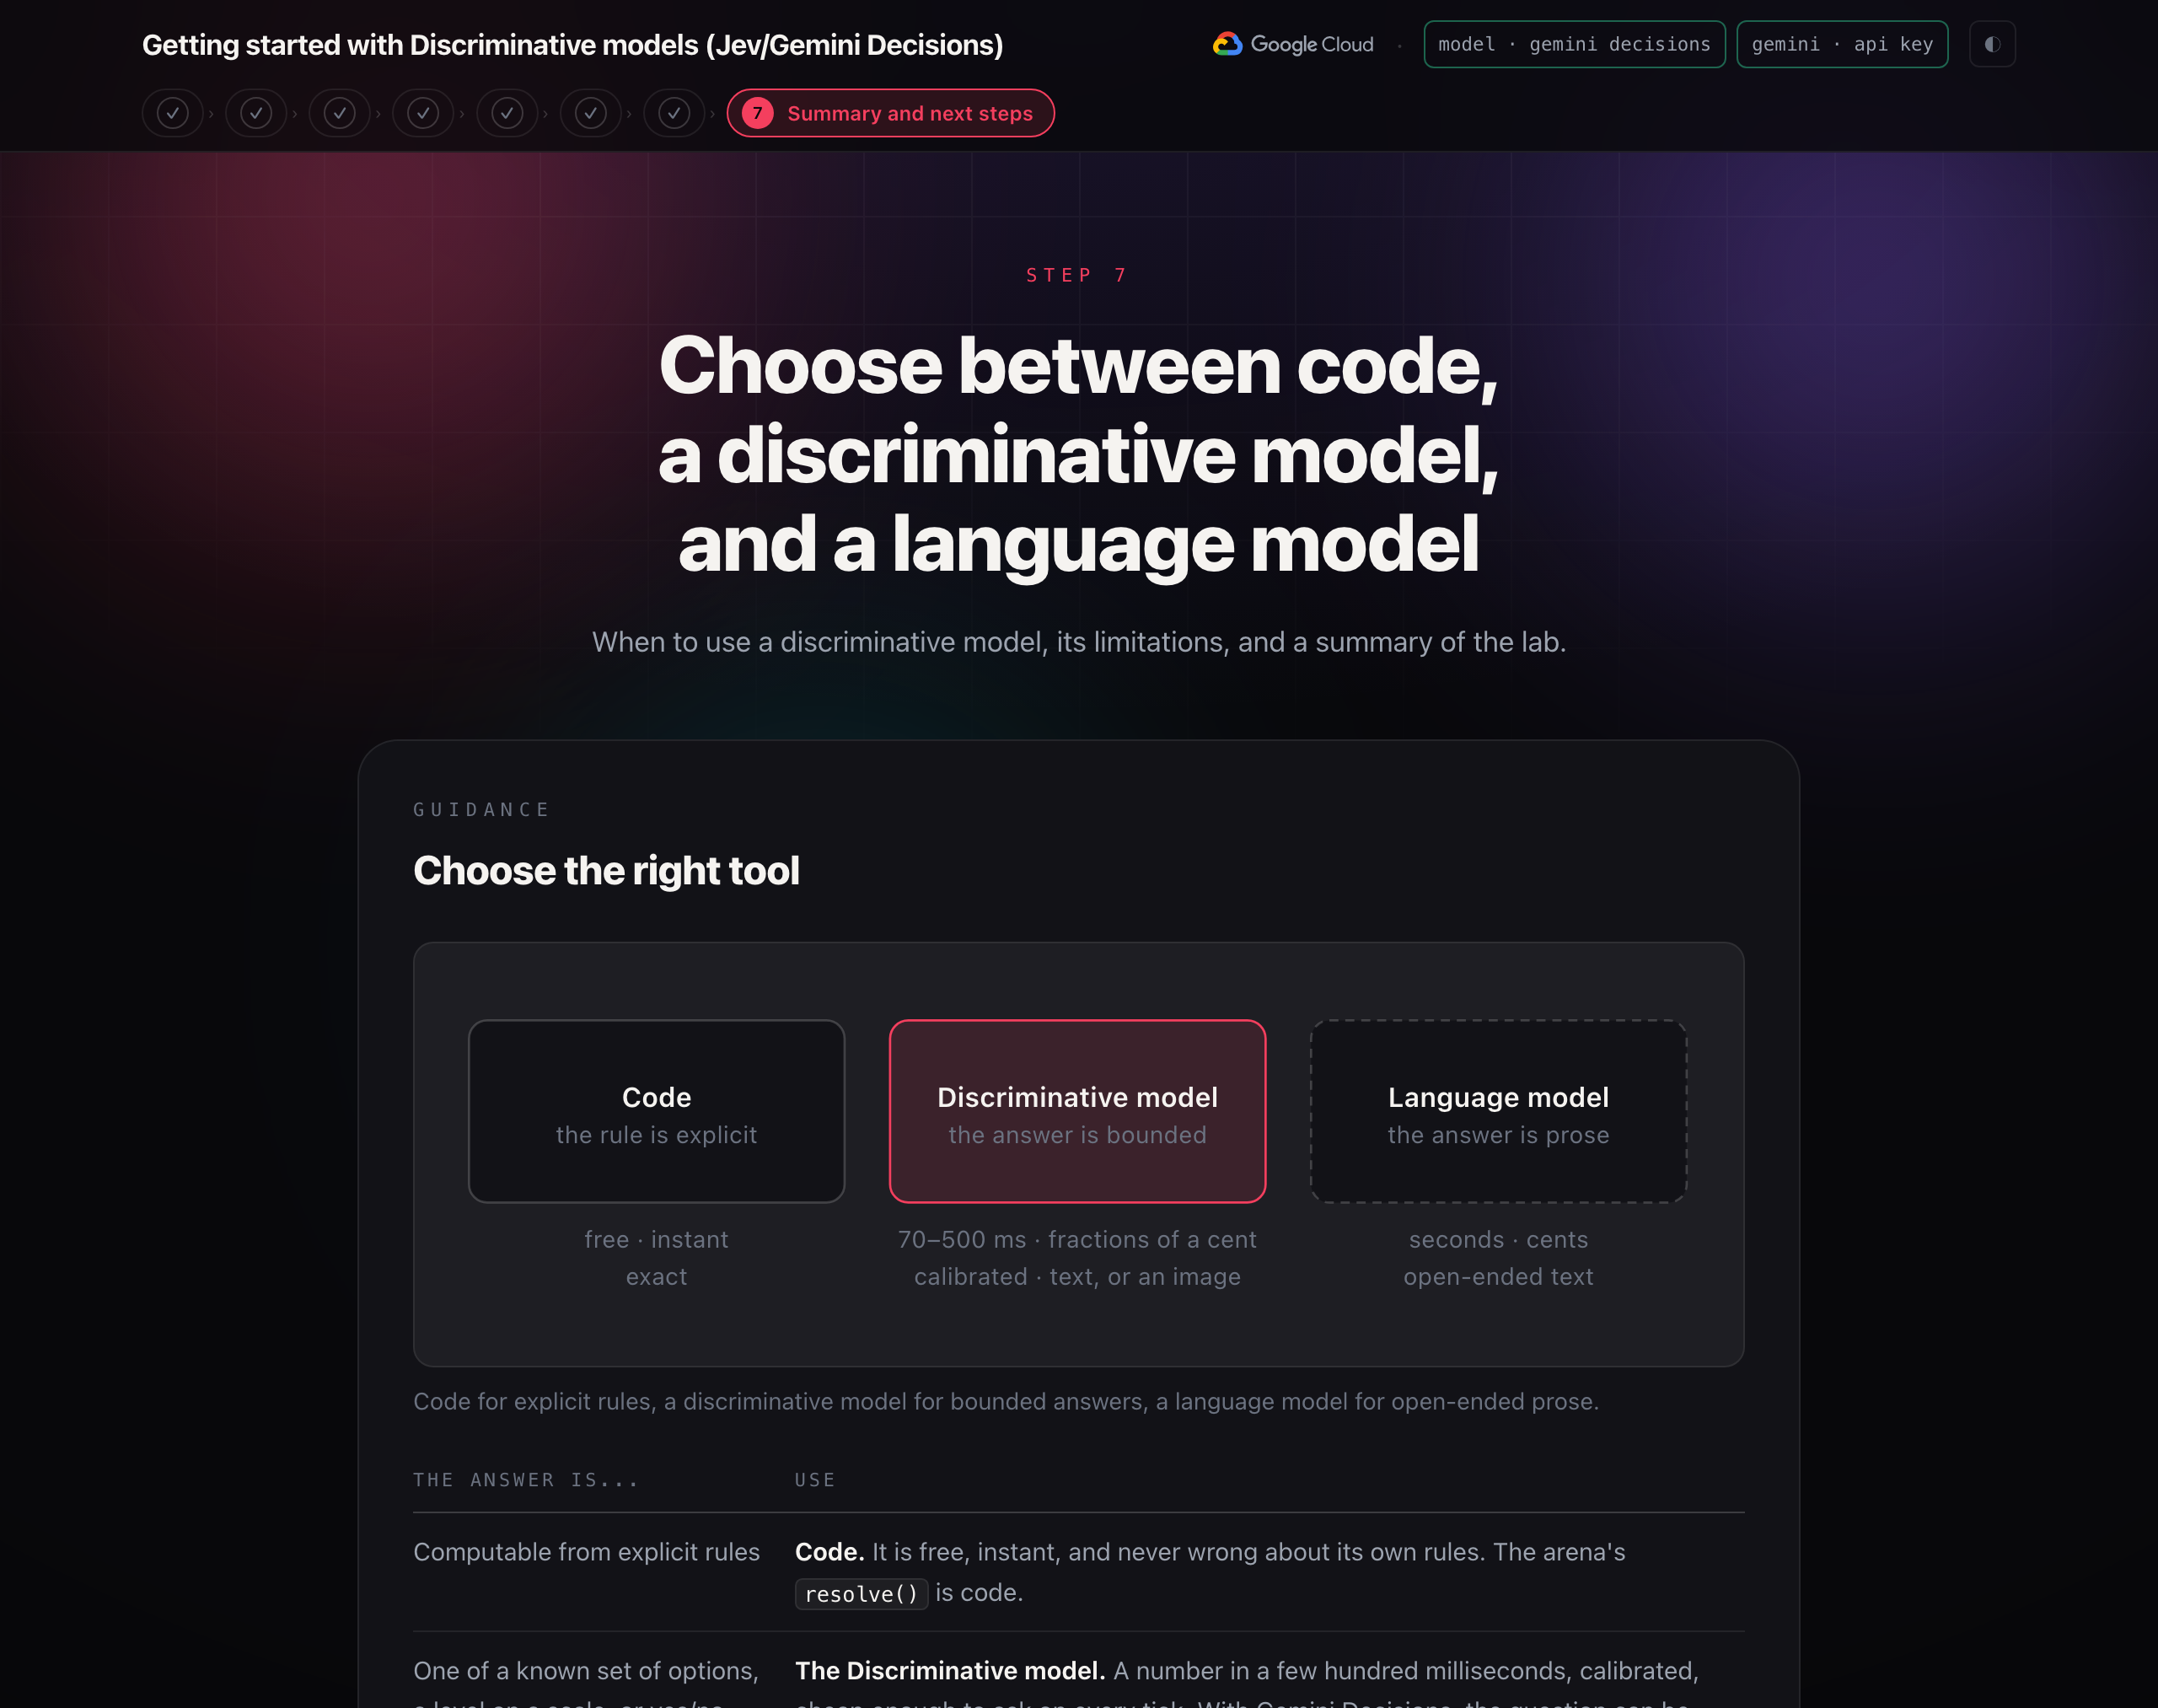
Choose the right tool
The answer is... | Use |
Computable from explicit rules | Code. Free, instant, and exact about its own rules, such as |
One of a known set of options, a level on a scale, or yes/no | A discriminative model. Returns calibrated numbers in milliseconds, cheap enough to ask on every event, including image questions with Gemini Decisions. |
Open-ended prose or a conversation | A language model. Gemini writes the tale once at the end of the fight. |
Considerations
- Input modalities depend on the model. Jev and DiffusionGemma accept text only. Gemini Decisions accepts text, images, audio, video, and PDFs. English is strongest across models.
- Arithmetic and multi-step chains belong in code. Compute counts or totals in Python and pass the result in the state.
- Keep option sets focused. Questions with 50 or more options lose accuracy; clear option descriptions and hierarchical splits help.
- Treat untrusted text as data. Ask questions about user input rather than letting instructions inside the state steer the decision.
- Request limits. Jev accepts up to 64k tokens per request. Gemini Decisions accepts up to 262k tokens and up to 1,000 questions per request. Both accept up to 255 options per
Choiceand work best with 2 to 10 levels perScore.