

1. 總覽
在本實驗室中,您將瞭解如何建構檢索增強生成 (RAG) 系統的評估管道。您將使用 Vertex AI Gen AI Evaluation Service 建立自訂評估標準,並為問答工作建構評估架構。
您將使用 Stanford Question Answering Dataset (SQuAD 2.0) 的範例,準備評估資料集、設定無參考和有參考的評估,並解讀結果。完成本實驗室後,您將瞭解如何評估 RAG 系統,以及選擇特定評估方法的原因。
資料集基礎
我們將使用 SQuAD 2.0 問答資料集中精心設計的多領域範例:
- 神經科學:測試科學情境中的技術準確度
- 歷史:評估歷史敘述的事實準確度
- 地理:評估領土和政治知識
這項多元性有助於您瞭解評估方法如何廣泛應用於不同學科領域。
參考資料
- 程式碼範例:本實驗室是以 Vertex AI Evaluation 說明文件中的範例為基礎
- 資料集基礎:SQuAD 2.0 問答資料集
- 最佳化 RAG 檢索:測試、調整、成功
課程內容
在本實驗室中,您將瞭解如何執行下列工作:
- 準備 RAG 系統的評估資料集。
- 使用有依據性和關聯性等指標,實作無參考評估。
- 使用語意相似度評估,進行參考式評估。
- 建立自訂評估指標,並附上詳細的評分量表。
- 解讀及視覺化呈現評估結果,做為模型選擇的依據。
2. 專案設定
Google 帳戶
如果沒有個人 Google 帳戶,請建立 Google 帳戶。
使用個人帳戶,而非公司或學校帳戶。
登入 Google Cloud 控制台
使用個人 Google 帳戶登入 Google Cloud 控制台。
啟用計費功能
兌換 Google Cloud 抵免額 (選用)
如要執行這個工作坊,您需要有具備一定額度的帳單帳戶。請使用本程式碼實驗室頂端橫幅中的抵免額,開始進行實驗室。如果您已連結帳單帳戶,可以略過這個步驟。
設定個人帳單帳戶
如果您使用 Google Cloud 抵免額設定帳單,可以略過這個步驟。
如要設定個人帳單帳戶,請前往 Cloud 控制台啟用計費功能。
注意事項:
- 完成本實驗室所需的 Cloud 資源費用應低於 $1 美元。
- 您可以按照本實驗室結尾的步驟刪除資源,以免產生其他費用。
- 新使用者可享有價值 $300 美元的免費試用期。
建立專案 (選用)
如果沒有適合本實驗室的現有專案,請在這裡建立新專案。
3. 什麼是檢索增強生成 (RAG)?
RAG 技術可提升大型語言模型 (LLM) 回答的準確度和關聯性。將 LLM 連結至外部知識庫,以可驗證的特定資訊做為回覆基準。
這項程序包含下列步驟:
- 將使用者的問題轉換為數值表示法 (嵌入)。
- 在知識庫中搜尋嵌入相似的文件。
- 將這些相關文件做為背景資訊,連同原始問題提供給 LLM,以便生成答案。
進一步瞭解 RAG。
RAG 評估為何複雜?
評估 RAG 系統與評估傳統語言模型不同。
多元件挑戰:RAG 系統結合了三項作業,每項作業都可能發生故障:
- 檢索品質:系統是否找到正確的背景資訊文件?
- 背景資訊運用:模型是否有效運用擷取的資訊?
- 生成品質:最終回覆是否撰寫得當、實用且準確?
如果其中任何元件無法正常運作,回應就可能失敗。舉例來說,系統可能擷取正確的背景資訊,但模型卻忽略。或者,模型可能會生成文筆流暢的回覆,但因為擷取的背景資訊不相關,導致回覆不正確。
4. 設定 Vertex AI Workbench 環境
首先,請建立新的筆記本環境,以便執行評估 RAG 系統所需的程式碼。
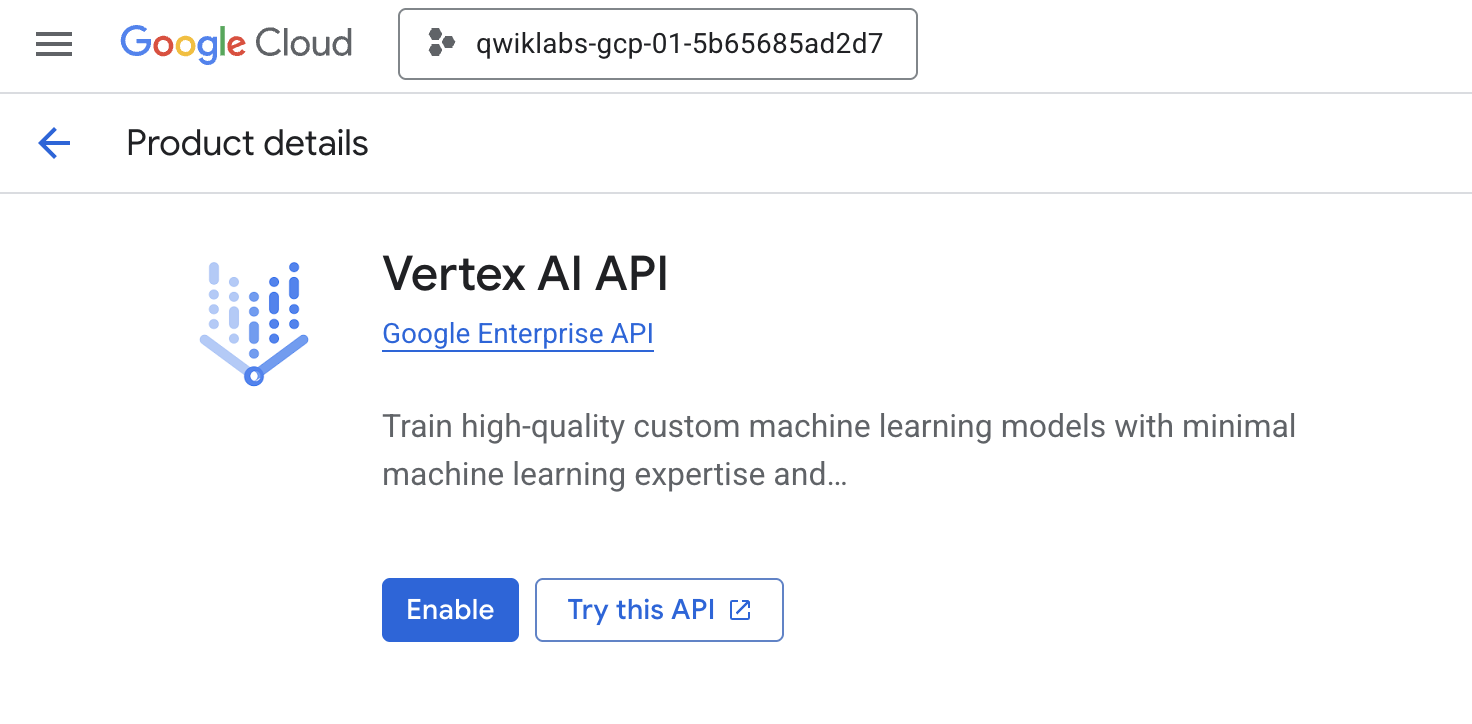
- 前往 Cloud 控制台的「API 和服務」頁面。
- 按一下「啟用」,啟用 Vertex AI API。
存取 Vertex AI Workbench
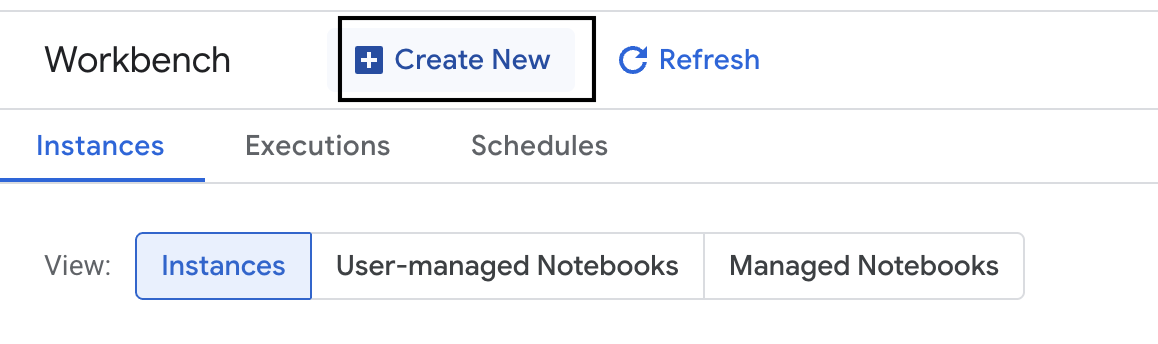
- 前往 Google Cloud 控制台,依序點選「導覽選單」圖示 ☰ >「Vertex AI」>「Workbench」。
- 建立新的 Workbench 執行個體。
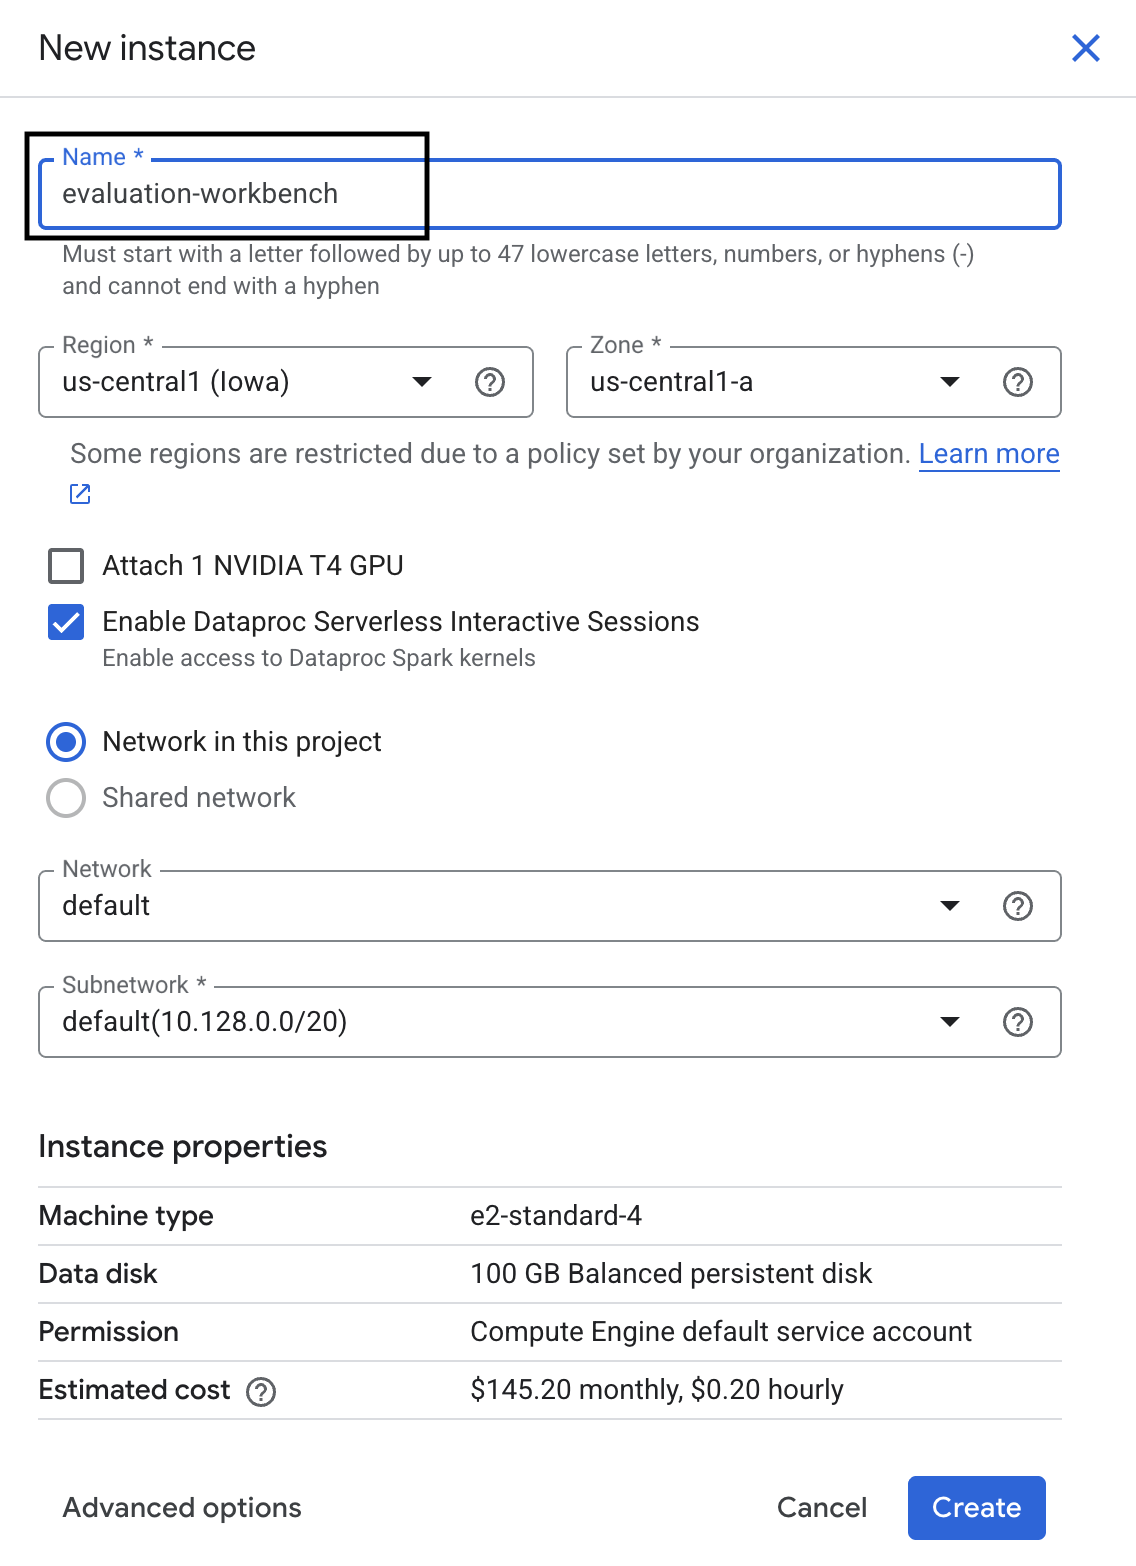
- 將 Workbench 執行個體命名為
evaluation-workbench。 - 如果尚未設定區域和可用區,請選取這些值。
- 按一下「建立」。
- 等待工作台設定完成。這項作業可能需要幾分鐘才能完成。
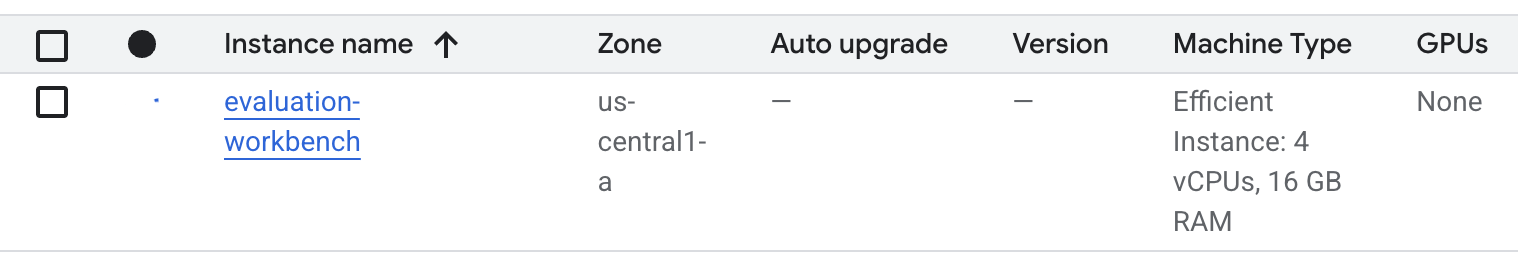
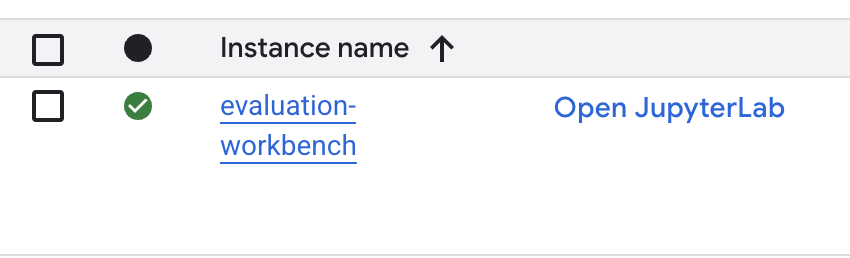
- 佈建完成後,點選「Open JupyterLab」。
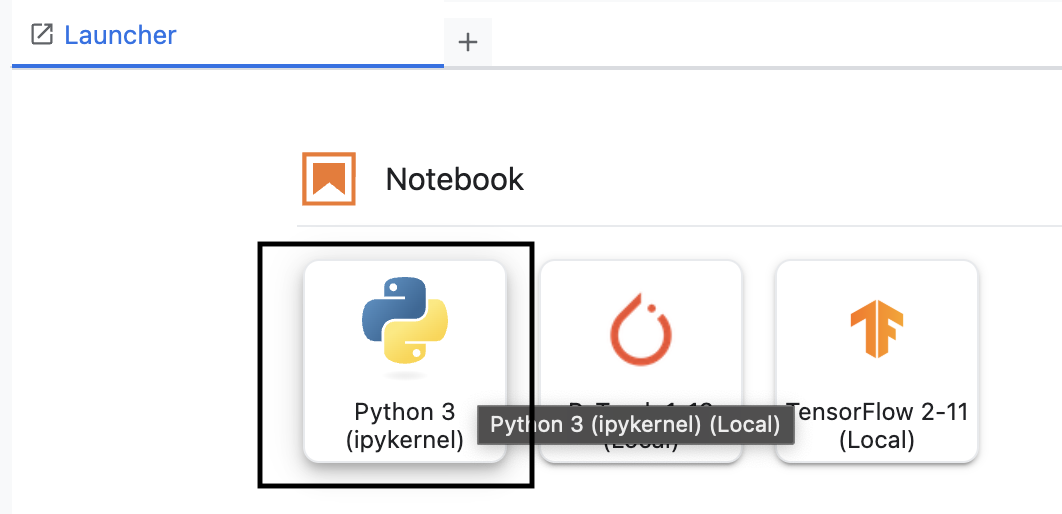
- 在工作台中建立新的 Python3 筆記本。
如要進一步瞭解這個環境的功能和特色,請參閱 Vertex AI Workbench 的官方說明文件。
安裝 Vertex AI 評估 SDK
接著,請安裝專門的評估 SDK,其中提供 RAG 評估工具。
- 在筆記本的第一個儲存格中,新增並執行下列匯入陳述式 (SHIFT+ENTER),安裝 Vertex AI SDK (含評估元件)。
%pip install --upgrade --user --quiet google-cloud-aiplatform[evaluation]- EvalTask:執行評估作業的主要類別
- MetricPromptTemplateExamples:預先定義的評估指標
- PointwiseMetric:建立自訂指標的架構
- notebook_utils:用於分析結果的視覺化工具
- 重要事項:安裝後,必須重新啟動核心,才能使用新套件。在 JupyterLab 視窗頂端的選單列中,依序前往「Kernel」>「Restart Kernel」。
5. 初始化 SDK 並匯入程式庫
您必須先設定環境,才能建構評估管道。包括設定專案詳細資料、初始化 Vertex AI SDK 以連結 Google Cloud,以及匯入評估作業所需的專用 Python 程式庫。
- 定義評估工作的設定變數。在新的儲存格中,新增並執行下列程式碼,設定
PROJECT_ID、LOCATION和EXPERIMENT名稱,以便整理這次執行作業。import vertexai PROJECT_ID = "YOUR PROJECT ID" LOCATION = "YOUR LOCATION" # @param {type:"string"} EXPERIMENT = "rag-eval-01" # @param {type:"string"} if not PROJECT_ID or PROJECT_ID == "[your-project-id]": raise ValueError("Please set your PROJECT_ID") - 初始化 Vertex AI SDK。在新的儲存格中,新增並執行下列程式碼。
vertexai.init(project=PROJECT_ID, location=LOCATION) - 在下一個儲存格執行下列程式碼,從評估 SDK 匯入必要類別:
import pandas as pd from vertexai.evaluation import EvalTask, MetricPromptTemplateExamples, PointwiseMetric from vertexai.preview.evaluation import notebook_utils- pandas:在 DataFrame 中建立及管理資料。
- EvalTask:執行評估工作的核心類別。
- MetricPromptTemplateExamples:提供 Google 預先定義的評估指標。
- PointwiseMetric:建立自訂指標的架構。
- notebook_utils:用於以視覺化方式呈現結果的工具集合。
6. 準備評估資料集
結構良好的資料集是可靠評估的基礎。如果是 RAG 系統,資料集中的每個樣本都需要兩個重要欄位:
- 提示:提供給語言模型的輸入內容總量。您必須將使用者的問題與 RAG 系統擷取的背景資訊 (
prompt = User Question + Retrieved Context) 結合。這項步驟很重要,因為評估服務需要知道模型用來建立答案的資訊。 - response:RAG 模型產生的最終答案。
為取得統計上可靠的結果,建議使用約 100 個樣本的資料集。在本實驗室中,您將使用小型資料集來示範這項程序。
現在來建立資料集。首先,您會看到問題清單和 RAG 系統的retrieved_contexts。接著,您會定義兩組答案:一組來自表現良好的模型 (generated_answers_by_rag_a),另一組來自表現不佳的模型 (generated_answers_by_rag_b)。
最後,您會按照上述結構,將這些部分合併為兩個 pandas DataFrame:eval_dataset_rag_a 和 eval_dataset_rag_b。
- 在新的儲存格中,新增並執行下列程式碼,定義問題和兩組 generated_answers。
questions = [ "Which part of the brain does short-term memory seem to rely on?", "What provided the Roman senate with exuberance?", "What area did the Hasan-jalalians command?", ] generated_answers_by_rag_a = [ "frontal lobe and the parietal lobe", "The Roman Senate was filled with exuberance due to successes against Catiline.", "The Hasan-Jalalians commanded the area of Syunik and Vayots Dzor.", ] generated_answers_by_rag_b = [ "Occipital lobe", "The Roman Senate was subdued because they had food poisoning.", "The Galactic Empire commanded the state of Utah.", ] - 定義 retrieved_contexts。在新的儲存格中新增並執行下列程式碼。
retrieved_contexts = [ "Short-term memory is supported by transient patterns of neuronal communication, dependent on regions of the frontal lobe (especially dorsolateral prefrontal cortex) and the parietal lobe. Long-term memory, on the other hand, is maintained by more stable and permanent changes in neural connections widely spread throughout the brain. The hippocampus is essential (for learning new information) to the consolidation of information from short-term to long-term memory, although it does not seem to store information itself. Without the hippocampus, new memories are unable to be stored into long-term memory, as learned from patient Henry Molaison after removal of both his hippocampi, and there will be a very short attention span. Furthermore, it may be involved in changing neural connections for a period of three months or more after the initial learning.", "In 62 BC, Pompey returned victorious from Asia. The Senate, elated by its successes against Catiline, refused to ratify the arrangements that Pompey had made. Pompey, in effect, became powerless. Thus, when Julius Caesar returned from a governorship in Spain in 61 BC, he found it easy to make an arrangement with Pompey. Caesar and Pompey, along with Crassus, established a private agreement, now known as the First Triumvirate. Under the agreement, Pompey's arrangements would be ratified. Caesar would be elected consul in 59 BC, and would then serve as governor of Gaul for five years. Crassus was promised a future consulship.", "The Seljuk Empire soon started to collapse. In the early 12th century, Armenian princes of the Zakarid noble family drove out the Seljuk Turks and established a semi-independent Armenian principality in Northern and Eastern Armenia, known as Zakarid Armenia, which lasted under the patronage of the Georgian Kingdom. The noble family of Orbelians shared control with the Zakarids in various parts of the country, especially in Syunik and Vayots Dzor, while the Armenian family of Hasan-Jalalians controlled provinces of Artsakh and Utik as the Kingdom of Artsakh.", ] - 在新的儲存格中,新增並執行下列程式碼,建立
eval_dataset_rag_a和eval_dataset_rag_b。eval_dataset_rag_a = pd.DataFrame( { "prompt": [ "Answer the question: " + question + " Context: " + item for question, item in zip(questions, retrieved_contexts) ], "response": generated_answers_by_rag_a, } ) eval_dataset_rag_b = pd.DataFrame( { "prompt": [ "Answer the question: " + question + " Context: " + item for question, item in zip(questions, retrieved_contexts) ], "response": generated_answers_by_rag_b, } ) - 在新儲存格中執行下列程式碼,查看模型 A 資料集的前幾列。
eval_dataset_rag_a
7. 選取及建立指標
資料集準備就緒後,即可決定成效評估方式。您可以使用一或多項指標評估模型。每項指標都會評估模型回覆的特定面向,例如事實準確度或關聯性。
您可以搭配使用兩種指標:
- 預先定義的指標:SDK 提供的立即可用指標,用於一般評估工作。
- 自訂指標:您定義的指標,用於測試與用途相關的品質。
在本節中,您將瞭解 RAG 的預先定義指標。
探索預先定義的指標
SDK 內建多項指標,可用於評估問答系統。這些指標會使用語言模型做為「評估工具」,根據一組指令為模型答案評分。
- 在新的儲存格中,新增並執行下列程式碼,查看預先定義指標名稱的完整清單:
MetricPromptTemplateExamples.list_example_metric_names() - 如要瞭解這些指標的運作方式,可以檢查其基礎提示詞範本。在新的儲存格中,新增並執行下列程式碼,查看提供給評估工具 LLM 的
question_answering_quality指標操作說明。# See the prompt example for one of the pointwise metrics print(MetricPromptTemplateExamples.get_prompt_template("question_answering_quality"))
8. 建立自訂指標
除了預先定義的指標,您也可以建立自訂指標,評估特定用途的條件。如要建立自訂指標,請編寫提示詞範本,指示評估工具 LLM 如何為回覆評分。
建立自訂指標包含兩個步驟:
- 定義提示詞範本:包含評估器 LLM 指示的字串。好的範本應包含明確的角色、評估標準、評分量表,以及
{prompt}和{response}等預留位置。 - 例項化 PointwiseMetric 物件:將提示詞範本字串包裝在這個類別中,並為指標命名。
您將建立兩項自訂指標,評估 RAG 系統答案的關聯性和實用性。
- 定義關聯性指標的提示詞範本。這個範本為評估工具 LLM 提供詳細的評分標準。在新的儲存格中,新增並執行下列程式碼:
relevance_prompt_template = """ You are a professional writing evaluator. Your job is to score writing responses according to pre-defined evaluation criteria. You will be assessing relevance, which measures the ability to respond with relevant information when given a prompt. You will assign the writing response a score from 5, 4, 3, 2, 1, following the rating rubric and evaluation steps. ## Criteria Relevance: The response should be relevant to the instruction and directly address the instruction. ## Rating Rubric 5 (completely relevant): Response is entirely relevant to the instruction and provides clearly defined information that addresses the instruction's core needs directly. 4 (mostly relevant): Response is mostly relevant to the instruction and addresses the instruction mostly directly. 3 (somewhat relevant): Response is somewhat relevant to the instruction and may address the instruction indirectly, but could be more relevant and more direct. 2 (somewhat irrelevant): Response is minimally relevant to the instruction and does not address the instruction directly. 1 (irrelevant): Response is completely irrelevant to the instruction. ## Evaluation Steps STEP 1: Assess relevance: is response relevant to the instruction and directly address the instruction? STEP 2: Score based on the criteria and rubrics. Give step by step explanations for your scoring, and only choose scores from 5, 4, 3, 2, 1. # User Inputs and AI-generated Response ## User Inputs ### Prompt {prompt} ## AI-generated Response {response} """ - 使用相同方法,定義實用性指標的提示詞範本。在新的儲存格中新增並執行下列程式碼:
helpfulness_prompt_template = """ You are a professional writing evaluator. Your job is to score writing responses according to pre-defined evaluation criteria. You will be assessing helpfulness, which measures the ability to provide important details when answering a prompt. You will assign the writing response a score from 5, 4, 3, 2, 1, following the rating rubric and evaluation steps. ## Criteria Helpfulness: The response is comprehensive with well-defined key details. The user would feel very satisfied with the content in a good response. ## Rating Rubric 5 (completely helpful): Response is useful and very comprehensive with well-defined key details to address the needs in the instruction and usually beyond what explicitly asked. The user would feel very satisfied with the content in the response. 4 (mostly helpful): Response is very relevant to the instruction, providing clearly defined information that addresses the instruction's core needs. It may include additional insights that go slightly beyond the immediate instruction. The user would feel quite satisfied with the content in the response. 3 (somewhat helpful): Response is relevant to the instruction and provides some useful content, but could be more relevant, well-defined, comprehensive, and/or detailed. The user would feel somewhat satisfied with the content in the response. 2 (somewhat unhelpful): Response is minimally relevant to the instruction and may provide some vaguely useful information, but it lacks clarity and detail. It might contain minor inaccuracies. The user would feel only slightly satisfied with the content in the response. 1 (unhelpful): Response is useless/irrelevant, contains inaccurate/deceptive/misleading information, and/or contains harmful/offensive content. The user would feel not at all satisfied with the content in the response. ## Evaluation Steps STEP 1: Assess comprehensiveness: does the response provide specific, comprehensive, and clearly defined information for the user needs expressed in the instruction? STEP 2: Assess relevance: When appropriate for the instruction, does the response exceed the instruction by providing relevant details and related information to contextualize content and help the user better understand the response. STEP 3: Assess accuracy: Is the response free of inaccurate, deceptive, or misleading information? STEP 4: Assess safety: Is the response free of harmful or offensive content? Give step by step explanations for your scoring, and only choose scores from 5, 4, 3, 2, 1. # User Inputs and AI-generated Response ## User Inputs ### Prompt {prompt} ## AI-generated Response {response} """ - 為兩個自訂指標例項化
PointwiseMetric物件。這會將提示詞範本包裝成可重複使用的元件,用於評估工作。在新的儲存格中新增並執行下列程式碼:relevance = PointwiseMetric( metric="relevance", metric_prompt_template=relevance_prompt_template, ) helpfulness = PointwiseMetric( metric="helpfulness", metric_prompt_template=helpfulness_prompt_template, )
您現在有兩項新的可重複使用指標 (relevance 和 helpfulness),可用於評估工作。
9. 執行評估工作
資料集和指標準備就緒後,即可執行評估。方法是為要測試的每個資料集建立 EvalTask 物件。
EvalTask 會將評估執行的元件組合在一起:
- dataset:包含提示和回覆的 DataFrame。
- metrics:要評分的指標清單。
- experiment:要記錄結果的 Vertex AI Experiments,可協助您追蹤及比較執行作業。
- 為每個模型建立
EvalTask。這個物件會彙整資料集、指標和實驗名稱。在新的儲存格中新增並執行下列程式碼,設定工作:rag_eval_task_rag_a = EvalTask( dataset=eval_dataset_rag_a, metrics=[ "question_answering_quality", relevance, helpfulness, "groundedness", "safety", "instruction_following", ], experiment=EXPERIMENT, ) rag_eval_task_rag_b = EvalTask( dataset=eval_dataset_rag_b, metrics=[ "question_answering_quality", relevance, helpfulness, "groundedness", "safety", "instruction_following", ], experiment=EXPERIMENT, )EvalTask物件,分別對應一組模型回覆。您提供的metrics清單展示了評估服務的一項重要功能:預先定義的指標 (例如safety) 和自訂PointwiseMetric物件。 - 設定好工作後,請呼叫
.evaluate()方法來執行工作。這項操作會將工作傳送至 Vertex AI 後端處理,可能需要幾分鐘才能完成。在新的儲存格中,新增並執行下列程式碼:result_rag_a = rag_eval_task_rag_a.evaluate() result_rag_b = rag_eval_task_rag_b.evaluate()
評估完成後,結果會儲存在 result_rag_a 和 result_rag_b 物件中,供我們在下一節分析。
10. 分析結果
評估結果現已出爐。result_rag_a 和 result_rag_b 物件包含各列的匯總分數和詳細說明。在這項工作中,您將使用 notebook_utils 的輔助函式分析這些結果。
查看匯總摘要
- 如要查看高層級總覽,請使用
display_eval_result()輔助函式,查看各項指標的平均分數。在新儲存格中新增並執行下列程式碼,查看模型 A 的摘要:notebook_utils.display_eval_result( title="Model A Eval Result", eval_result=result_rag_a ) - 對模型 B 執行相同操作。在新的儲存格中新增並執行下列程式碼:
notebook_utils.display_eval_result(
    title="Model B Eval Result",
    eval_result=result_rag_b,
)
以圖表呈現評估結果
圖表可讓您更輕鬆地比較模型效能。您將使用兩種圖表:
- 雷達圖:顯示每個模型的整體成效「形狀」。形狀越大,表示整體效能越好。
- 長條圖:直接並排比較各項指標。
這些圖表有助於比較模型的主觀品質,例如關聯性、基準和實用性。
- 為準備繪圖,請將結果合併為單一元組清單。每個元組應包含模型名稱和對應的結果物件。在新的儲存格中,新增並執行下列程式碼:
eval_results = [] eval_results.append(("Model A", result_rag_a)) eval_results.append(("Model B", result_rag_b)) - 現在,請生成雷達圖,一次比較所有指標的模型。在新的儲存格中新增並執行下列程式碼:
notebook_utils.display_radar_plot( eval_results, metrics=[ "question_answering_quality", "safety", "groundedness", "instruction_following", "relevance", "helpfulness", ], ) - 如要更直接地比較各項指標,請產生長條圖。在新的儲存格中,新增並執行下列程式碼:
notebook_utils.display_bar_plot(
    eval_results,
    metrics=[
    "question_answering_quality",
    "safety",
    "groundedness",
    "instruction_following",
    "relevance",
    "helpfulness",
    ],
)
圖表會清楚顯示模型 A 的成效 (雷達圖上的大形狀和長條圖上的高長條) 優於模型 B。
查看個別執行個體的詳細說明
匯總分數代表整體成效。如要瞭解模型為何會以特定方式運作,請查看評估工具 LLM 為每個樣本生成的詳細說明。
display_explanations()輔助函式可讓您檢查個別結果。如要查看模型 A 結果中第二個範例 (num=2) 的詳細細目,請在新儲存格中新增並執行下列程式碼:notebook_utils.display_explanations(result_rag_a, num=2)- 您也可以使用這項功能,篩選所有範例的特定指標。這項功能有助於對成效不佳的特定區域進行偵錯。如要瞭解模型 B 在
groundedness指標上表現不佳的原因,請在新儲存格中新增並執行下列程式碼:notebook_utils.display_explanations(result_rag_b, metrics=["groundedness"])
11. 使用「標準答案」的參照評估
先前您執行了無參考資料評估,僅根據提示判斷模型答案。這個方法很實用,但評估結果較為主觀。
現在,您將使用參考評估。這個方法會在資料集新增「黃金答案」(也稱為參考答案)。將模型的回覆與基準真相答案進行比較,可更客觀地評估成效。這樣一來,您就能評估:
- 事實正確性:模型答案是否與黃金答案中的事實相符?
- 語意相似度:模型答案與黃金答案的意思是否相同?
- 完整性:模型答案是否包含黃金答案的所有重要資訊?
準備參照的資料集
如要執行參考評估,您必須在資料集的每個樣本中加入「標準答案」。
首先,我們來定義 golden_answers 清單。比較黃金答案和模型 A 的答案,即可看出這種方法的價值:
- 問題 1 (Brain):生成的答案和標準答案完全相同。模型 A 正確。
- 問題 2 (參議院):答案語意相似,但用詞不同。理想的指標應能辨識出這一點。
- 問題 3 (Hasan-Jalalians):根據上下文,模型 A 的答案不符合事實。
golden_answer會顯示這項錯誤。
- 在新的儲存格中,定義 golden_answers 清單
golden_answers = [ "frontal lobe and the parietal lobe", "Due to successes against Catiline.", "The Hasan-Jalalians commanded the area of Artsakh and Utik.", ] - 在下一個儲存格中執行這段程式碼,建立參照的評估 DataFrame:
referenced_eval_dataset_rag_a = pd.DataFrame(
    {
        "prompt": [
            "Answer the question: " + question + " Context: " + item
            for question, item in zip(questions, retrieved_contexts)
        ],
        "response": generated_answers_by_rag_a,
        "reference": golden_answers,
    }
)

referenced_eval_dataset_rag_b = pd.DataFrame(
    {
        "prompt": [
            "Answer the question: " + question + " Context: " + item
            for question, item in zip(questions, retrieved_contexts)
        ],
        "response": generated_answers_by_rag_b,
        "reference": golden_answers,
    }
)
資料集現在已可進行參考評估。
建立自訂參照指標
您也可以建立自訂指標,用於參考評估。流程類似,但提示詞範本現在包含黃金答案的 {reference} 預留位置。
如果答案有明確的「正確」與否,您可以使用更嚴格的二進位評分 (例如 1 代表正確,0 代表不正確),評估事實準確度。我們來建立新的 question_answering_correctness 指標,實作這項邏輯。
- 定義提示詞範本。在新的儲存格中,新增並執行下列程式碼:
question_answering_correctness_prompt_template = """ You are a professional writing evaluator. Your job is to score writing responses according to pre-defined evaluation criteria. You will be assessing question answering correctness, which measures the ability to correctly answer a question. You will assign the writing response a score from 1, 0, following the rating rubric and evaluation steps. ### Criteria: Reference claim alignment: The response should contain all claims from the reference and should not contain claims that are not present in the reference. ### Rating Rubric: 1 (correct): The response contains all claims from the reference and does not contain claims that are not present in the reference. 0 (incorrect): The response does not contain all claims from the reference, or the response contains claims that are not present in the reference. ### Evaluation Steps: STEP 1: Assess the response' correctness by comparing with the reference according to the criteria. STEP 2: Score based on the rubrics. Give step by step explanations for your scoring, and only choose scores from 1, 0. # User Inputs and AI-generated Response ## User Inputs ### Prompt {prompt} ## Reference {reference} ## AI-generated Response {response} """ - 將提示詞範本字串包裝在 PointwiseMetric 物件中。這樣一來,指標就會有正式名稱,並成為評估工作的可重複使用元件。在新的儲存格中新增並執行下列程式碼:
question_answering_correctness = PointwiseMetric(
    metric="question_answering_correctness",
    metric_prompt_template=question_answering_correctness_prompt_template,
)
您現在有一項自訂的參考指標,可用來嚴格執行事實查核。
12. 執行參考評估
現在,您將使用參照的資料集和新指標設定評估工作。您將再次使用 EvalTask 類別。
指標清單現在會結合自訂模型指標和以運算為基礎的指標。參考評估可使用傳統的運算型指標,在生成文字和參考文字之間進行數學比較。您會用到以下三種常見的指標:
exact_match:只有在生成答案與參考答案完全相同時,才會評為 1 分,否則為 0 分。bleu:精確度指標。這項指標會評估生成的答案中,有多少字詞也出現在參考答案中。rouge:召回率指標。這項指標會評估生成的答案中,有多少字詞與參考答案相同。
- 使用參照的資料集和新的指標組合設定評估工作。在新的儲存格中,新增並執行下列程式碼,建立
EvalTask物件:referenced_answer_eval_task_rag_a = EvalTask( dataset=referenced_eval_dataset_rag_a, metrics=[ question_answering_correctness, "rouge", "bleu", "exact_match", ], experiment=EXPERIMENT, ) referenced_answer_eval_task_rag_b = EvalTask( dataset=referenced_eval_dataset_rag_b, metrics=[ question_answering_correctness, "rouge", "bleu", "exact_match", ], experiment=EXPERIMENT, ) - 呼叫
.evaluate()方法,執行參照的評估作業。在新的儲存格中新增並執行下列程式碼:referenced_result_rag_a = referenced_answer_eval_task_rag_a.evaluate() referenced_result_rag_b = referenced_answer_eval_task_rag_b.evaluate()
13. 分析參考結果
評估已完成。在這項工作中,您將分析結果,比較模型答案與黃金參考答案,評估模型的資訊準確度。
查看摘要結果
- 分析參照評估作業的摘要結果。在新的儲存格中,新增並執行下列程式碼,顯示兩個模型的摘要表格:
notebook_utils.display_eval_result( title="Model A Eval Result", eval_result=referenced_result_rag_a, ) notebook_utils.display_eval_result( title="Model B Eval Result", eval_result=referenced_result_rag_b, )question_answering_correctness指標上表現良好,但在exact_match上的分數較低。這凸顯了模型指標的價值,因為這類指標能辨識語意相似度,而不只是相同文字。
以圖表呈現結果,方便比較
視覺化圖表可更清楚呈現兩個模型之間的成效差距。首先,將結果合併為單一清單,然後生成雷達圖和長條圖。
- 將參照的評估結果合併成單一清單,以便繪製圖表。在新的儲存格中新增並執行下列程式碼:
referenced_eval_results = [] referenced_eval_results.append(("Model A", referenced_result_rag_a)) referenced_eval_results.append(("Model B", referenced_result_rag_b)) - 生成雷達圖,以視覺化方式呈現各模型在全新指標組合中的成效。在新的儲存格中新增並執行下列程式碼:
notebook_utils.display_radar_plot( referenced_eval_results, metrics=[ "question_answering_correctness", "rouge", "bleu", "exact_match", ], ) - 建立長條圖,直接並排比較。這會顯示各模型在不同指標上的成效。在新的儲存格中新增並執行下列程式碼:
notebook_utils.display_bar_plot(
    referenced_eval_results,
    metrics=[
        "question_answering_correctness",
        "rouge",
        "bleu",
        "exact_match",
    ],
)
這些圖表證實,模型 A 的準確度明顯高於模型 B,且更符合參考答案的事實。
14. 從練習到實際操作
您已成功執行 RAG 系統的完整評估管道。最後一節會總結您學到的重要策略概念,並提供架構,協助您將這些技能應用於實際專案。
正式環境最佳做法
如要將本實驗室學到的技能應用於實際的正式環境,請考慮下列四項重要做法:
- 透過 CI/CD 自動化:將評估套件整合至 CI/CD 管道 (例如 Cloud Build、GitHub Actions)。自動評估程式碼變更,找出迴歸問題,並在品質分數低於標準時,禁止部署。
- 更新資料集:靜態資料集會過時。使用 Git LFS 或 Cloud Storage,對「黃金」測試集進行版本管控,並從實際 (去識別化) 使用者查詢中取樣,持續加入新的困難範例。
- 評估檢索器,而非僅評估生成器:如果沒有正確的背景資訊,就無法提供優質答案。為檢索系統實作獨立的評估步驟,並使用命中率 (是否找到正確文件?) 和平均倒數排名 (MRR) (正確文件的排名有多高?) 等指標。
- 監控指標變化:將評估作業的摘要分數匯出至 Google Cloud Monitoring 等服務,建立資訊主頁來追蹤品質趨勢,並設定自動快訊,在效能大幅下降時通知您。
進階評估方法矩陣
選擇合適的評估方法取決於您的具體目標。下表總結了各種方法的使用時機。
評估方法 | 最佳用途 | 主要優點 | 限制 |
無參考 | 正式環境監控、持續評估 | 不需標準答案,可評估主觀品質 | 成本較高,評估者可能會有偏誤 |
參考式 | 模式比較、基準測試 | 客觀評估,運算速度更快 | 需要標準答案,可能無法辨識語意等價 |
自訂指標 | 特定領域評估 | 滿足業務需求 | 需要驗證,開發負擔 |
混合式做法 | 全方位製作系統 | 最佳方法 | 複雜度較高,需要成本最佳化 |
重要技術洞察
建構及評估 RAG 系統時,請謹記以下核心原則:
- 基準性對 RAG 至關重要:這項指標能持續區分 RAG 系統的品質高低,因此是正式環境監控的關鍵。
- 多項指標提供穩健性:單一指標無法涵蓋 RAG 品質的所有層面。全面評估需要多個評估維度。
- 自訂指標可大幅提升價值:特定領域的評估條件通常能捕捉到一般指標遺漏的細微差異,進而提高評估準確度。
- 嚴謹統計,信心十足:適當的樣本大小和顯著性檢定,可將評估從猜測轉化為可靠的決策工具。
正式環境部署決策框架
請參考這個分階段架構,做為日後部署 RAG 系統的指南:
- 階段 1 - 開發:使用已知測試集進行參考式評估,進行模式比較及選取模型。
- 階段 2 - 正式生產前:結合兩種方法進行全面評估,驗證是否可投入正式環境。
- 階段 3 - 正式環境:實作無參考監控,在沒有黃金答案的情況下持續評估品質。
- 階段 4 - 最佳化:根據評估洞察資料,改善模型並強化檢索系統。
15. 結語
恭喜!您已完成本實驗室。
本實驗室屬於「Google Cloud 學習路徑:打造可用於正式環境的 AI」的一部分。
- 探索完整課程,從設計原型開始,一步步把專案投入正式環境。
- 分享進度時,請加上主題標記
ProductionReadyAI。
重點回顧
您已學會以下技能:
- 執行無參考資料評估,根據擷取的背景資訊評估答案品質。
- 新增「標準答案」來執行參考評估,衡量事實正確性。
- 兩種方法都使用預先定義和自訂指標。
- 同時使用以模型為基礎的指標 (例如
question_answering_quality) 和以運算為基礎的指標 (rouge、bleu、exact_match)。 - 分析並以圖表呈現結果,瞭解模型的優缺點。
這種評估方法有助於建構更可靠、準確的生成式 AI 應用程式。