

১. ভূমিকা
ধরুন, আপনি সাইম্বাল ফিনান্সিয়াল (Cymbal Financial)- এর একজন ডেটা সায়েন্টিস্ট , যা একটি বিপুল পরিমাণ লেনদেন প্রক্রিয়াকারী প্রতিষ্ঠান। সম্প্রতি লেনদেন নিষ্পত্তিতে বিলম্বের একটি ঢেউ দেখা দিয়েছে এবং কমপ্লায়েন্স টিম সমন্বিত জালিয়াতির সন্দেহ করছে। আপনাকে এমন একটি পাইপলাইন তৈরি করতে হবে যা ক্লিয়ারিংহাউসের সরাসরি ট্রানজ্যাকশন লগ গ্রহণ করবে, ডেটা পরিষ্করণ করবে, একটি মেশিন লার্নিং মডেলকে প্রশিক্ষণ দেবে, ব্যাচ ইনফারেন্স চালাবে এবং উচ্চ-ঝুঁকিপূর্ণ ট্রানজ্যাকশনগুলোকে ম্যানুয়াল অডিটিংয়ের জন্য একটি ক্লাউড স্প্যানার (Cloud Spanner) রিভিউ কিউতে অন্তর্ভুক্ত করবে।
সাধারণত, এর জন্য দিনের পর দিন ধরে পুনরাবৃত্তিমূলক সেটআপ কোড (স্পার্ক নোটবুক, ডিবিটি কনফিগারেশন, ট্রেনিং স্ক্রিপ্ট, এয়ারফ্লো ডিএজি) লিখতে হয় এবং কনসোল ইন্টারফেস ও এডিটরের মধ্যে ক্রমাগত কাজ পরিবর্তন করতে হয়।
এই কোডল্যাবে, আপনি Antigravity IDE-এর ভিতরে Google Cloud Data Agent Kit (DAK) ব্যবহার করে একটি এজেন্টের সাথে পেয়ার-প্রোগ্রামিং করবেন। কথোপকথনমূলক স্বাভাবিক ভাষা ব্যবহার করে, এজেন্টটি আপনাকে Spark নোটবুক তৈরি করতে, একটি dbt প্রজেক্ট কম্পাইল করতে, একটি ইনফারেন্স লুপ তৈরি করতে এবং Apache Airflow-এর ম্যানেজড সার্ভিস ব্যবহার করে ওয়ার্কফ্লো অর্কেস্ট্রেট করতে সাহায্য করবে।
আপনি যা করবেন
- অ্যাপাচি স্পার্কের জন্য পরিচালিত পরিষেবা (স্পার্ক সার্ভারলেস) ব্যবহার করে ক্লাউড স্টোরেজ থেকে ক্লিয়ারিংহাউস লগগুলিকে একটি বিগকোয়েরি টেবিলে অন্তর্ভুক্ত করুন।
- dbt ব্যবহার করে ট্রানজ্যাকশনগুলো থেকে ডুপ্লিকেট বাদ দিন এবং সেগুলোকে স্বাভাবিক করুন, যাতে স্বচ্ছ ডেটা লেয়ার (র, স্টেজিং, এনরিচড) তৈরি হয়।
- স্পার্ক সার্ভারলেস-এ একটি ডিস্ট্রিবিউটেড র্যান্ডম ফরেস্ট ক্লাসিফিকেশন মডেল (
RandomForestClassifier) প্রশিক্ষণ দিন। - নতুন ট্রানজ্যাকশনগুলোর ওপর ব্যাচ ইনফারেন্স চালান এবং উচ্চ-ঝুঁকিপূর্ণ অ্যালার্টগুলো সরাসরি ক্লাউড স্প্যানারে লিখুন।
- IDE-এর ভিতরে Apache Airflow-এর ম্যানেজড সার্ভিস এবং ইন্টারেক্টিভ DAG মনিটরিং ব্যবহার করে সম্পূর্ণ পাইপলাইনটি অর্কেস্ট্রেট, ভিজ্যুয়ালি কনফিগার এবং ডিপ্লয় করুন ।
আপনার যা যা লাগবে
- ক্রোমের মতো একটি ওয়েব ব্রাউজার
- বিলিং সক্ষম একটি গুগল ক্লাউড প্রজেক্ট (হ্যান্ডস-অন ল্যাবের জন্য আমরা একটি নতুন, ডেডিকেটেড প্রজেক্ট ব্যবহারের পরামর্শ দিই)।
- SQL, Python, এবং PySpark সম্পর্কে প্রাথমিক ধারণা।
- গুগল এআই প্রো সাবস্ক্রিপশন সহ অ্যান্টিগ্র্যাভিটি আইডিই (প্রস্তাবিত)
এই কোডল্যাবে তৈরি করা রিসোর্সগুলোর খরচ $5-এর কম হওয়া উচিত। প্রোভিশন করা রিসোর্সগুলো মুছে ফেলার জন্য ল্যাবের শেষে দেওয়া ক্লিন আপ নির্দেশাবলী অবশ্যই অনুসরণ করুন।
২. পরিবেশ সেটআপ
ল্যাবটি শুরু করার জন্য, আপনাকে একটি বুটস্ট্র্যাপ স্ক্রিপ্ট চালাতে হবে। এই স্ক্রিপ্টটি স্বয়ংক্রিয়ভাবে প্রয়োজনীয় GCP API-গুলো সক্রিয় করে, একটি ইনজেশন ক্লাউড স্টোরেজ বাকেট তৈরি করে, মক ট্রানজ্যাকশন ও ডিরেক্টরি ডেটাসেট তৈরি করে, রেফারেন্স ডিরেক্টরিগুলোকে BigQuery-তে লোড করে এবং ক্লাউড স্প্যানার ও অ্যাপাচি এয়ারফ্লো-এর জন্য ম্যানেজড সার্ভিস (যা পূর্বে ক্লাউড কম্পোজার নামে পরিচিত ছিল)-এর ব্যাকগ্রাউন্ড প্রভিশনিং শুরু করে।
একটি প্রকল্প নির্বাচন করুন বা তৈরি করুন
গুগল ক্লাউড কনসোলে একটি বিদ্যমান প্রজেক্ট বেছে নিন অথবা একটি নতুন প্রজেক্ট তৈরি করুন ।
বিলিং যাচাই করুন
আপনার গুগল ক্লাউড প্রোজেক্টের জন্য বিলিং চালু আছে কিনা তা নিশ্চিত করুন। কীভাবে এটি করতে হয়, তা জানতে এই নির্দেশিকাটি অনুসরণ করতে পারেন।
সেটআপ স্ক্রিপ্টটি চালান
এনভায়রনমেন্ট সেটআপ চালু করার জন্য আপনি গুগল ক্লাউড শেল (অথবা গুগল ক্লাউড সিএলআই দিয়ে কনফিগার করা আপনার লোকাল শেল) ব্যবহার করবেন।
- গুগল ক্লাউড কনসোল খুলুন।
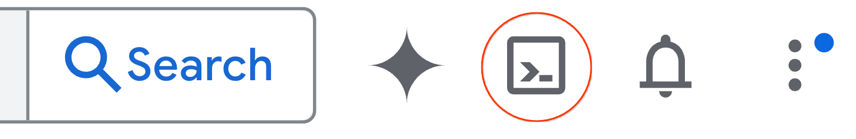
- উপরের ডানদিকের টুলবারে থাকা ‘Activate Cloud Shell’- এ ক্লিক করুন।
- ক্লাউড শেল টার্মিনালে আপনার সক্রিয় প্রজেক্টটি কনফিগার করুন:
gcloud config set project <<YOUR_PROJECT_ID>>
export PROJECT_ID=$(gcloud config get-value project)
- কোডল্যাব রিপোজিটরিটি ক্লোন করুন এবং স্ক্রিপ্টস ফোল্ডারে যান:
cd ~/
git clone --filter=blob:none --no-checkout https://github.com/GoogleCloudPlatform/devrel-demos.git
cd ~/devrel-demos
git sparse-checkout init --cone
git sparse-checkout set codelabs/agentic-data-labs/data-science
git checkout main
cd codelabs/agentic-data-labs/data-science/scripts
-
us-central1এ সমস্ত রিসোর্স ডেপ্লয় করতে বুটস্ট্র্যাপ সেটআপ স্ক্রিপ্টটি চালান:
chmod +x setup.sh setup_spanner.sh setup_composer.sh
export REGION=us-central1
./setup.sh
- স্ক্রিপ্টটি শেষ হলে, আপনি একটি সারসংক্ষেপ আউটপুট দেখতে পাবেন যা নির্দেশ করবে যে আপনার BigQuery ডেটাসেট এবং ক্লাউড স্টোরেজ বাকেট প্রস্তুত। ব্যাকগ্রাউন্ডে, ক্লাউড স্প্যানার (প্রায় ২ মিনিট সময় নেয়) এবং ম্যানেজড এয়ারফ্লো (প্রায় ২০ মিনিট সময় নেয়) প্রোভিশনিং চালিয়ে যাবে। আপনি যেকোনো সময় নিম্নলিখিত কমান্ডটি চালিয়ে তাদের অগ্রগতি পর্যবেক্ষণ করতে পারেন:
tail -f /tmp/spanner_setup.log
tail -f /tmp/composer_setup.log
Antigravity IDE খুলুন
- গুগল অ্যান্টিগ্র্যাভিটি ডাউনলোড পেজ থেকে অ্যান্টিগ্র্যাভিটি আইডিই (IDE) ডাউনলোড ও ইনস্টল করুন।
- Antigravity IDE চালু করুন।
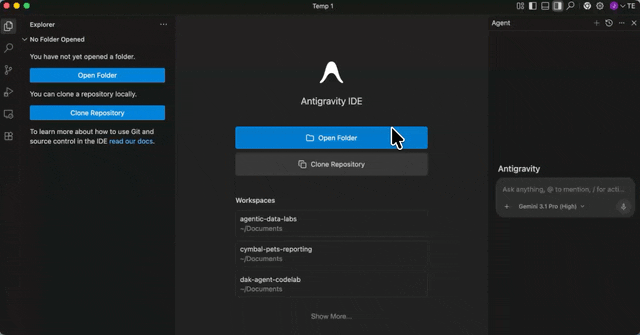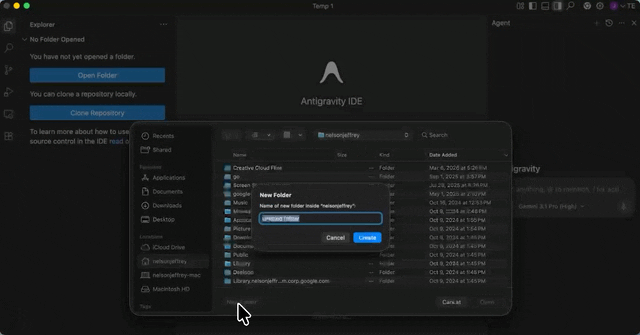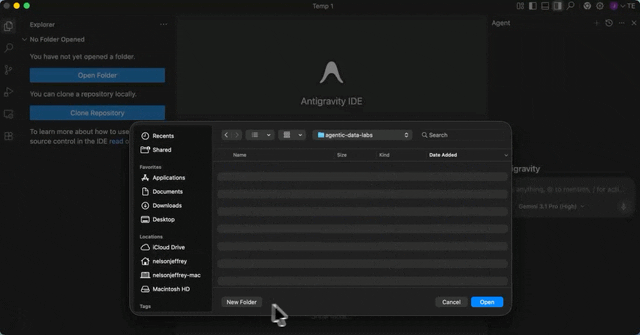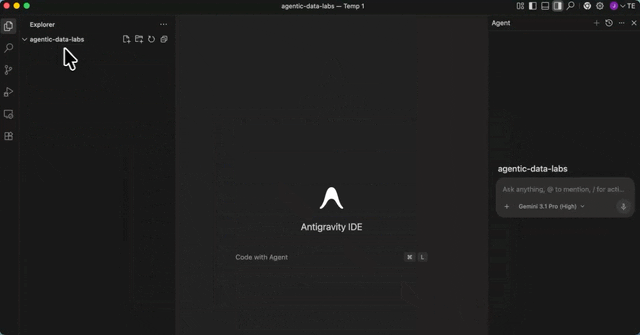
- আপনার লোকাল মেশিনে একটি নতুন, খালি ফোল্ডার তৈরি করুন (যেমন
agentic-data-labsনামে), এবং IDE-তে 'Open Folder' নির্বাচন করে এটি খুলুন। এটি আপনার কোডল্যাবের জন্য লোকাল ওয়ার্কস্পেস হিসেবে কাজ করবে।
ডেটা এজেন্ট কিট এক্সটেনশনটি ইনস্টল করুন
Google Cloud Data Agent Kit এক্সটেনশনটি আপনার এডিটরের মধ্যেই সরাসরি Google Cloud ডেটা পরিষেবাগুলির সাথে গভীর ইন্টিগ্রেশন প্রদান করে, যার ফলে আপনি কনটেক্সট পরিবর্তন না করেই BigQuery, Cloud SQL, Cloud Storage এবং আরও অনেক কিছুর সাথে ইন্টারঅ্যাক্ট করতে পারেন।
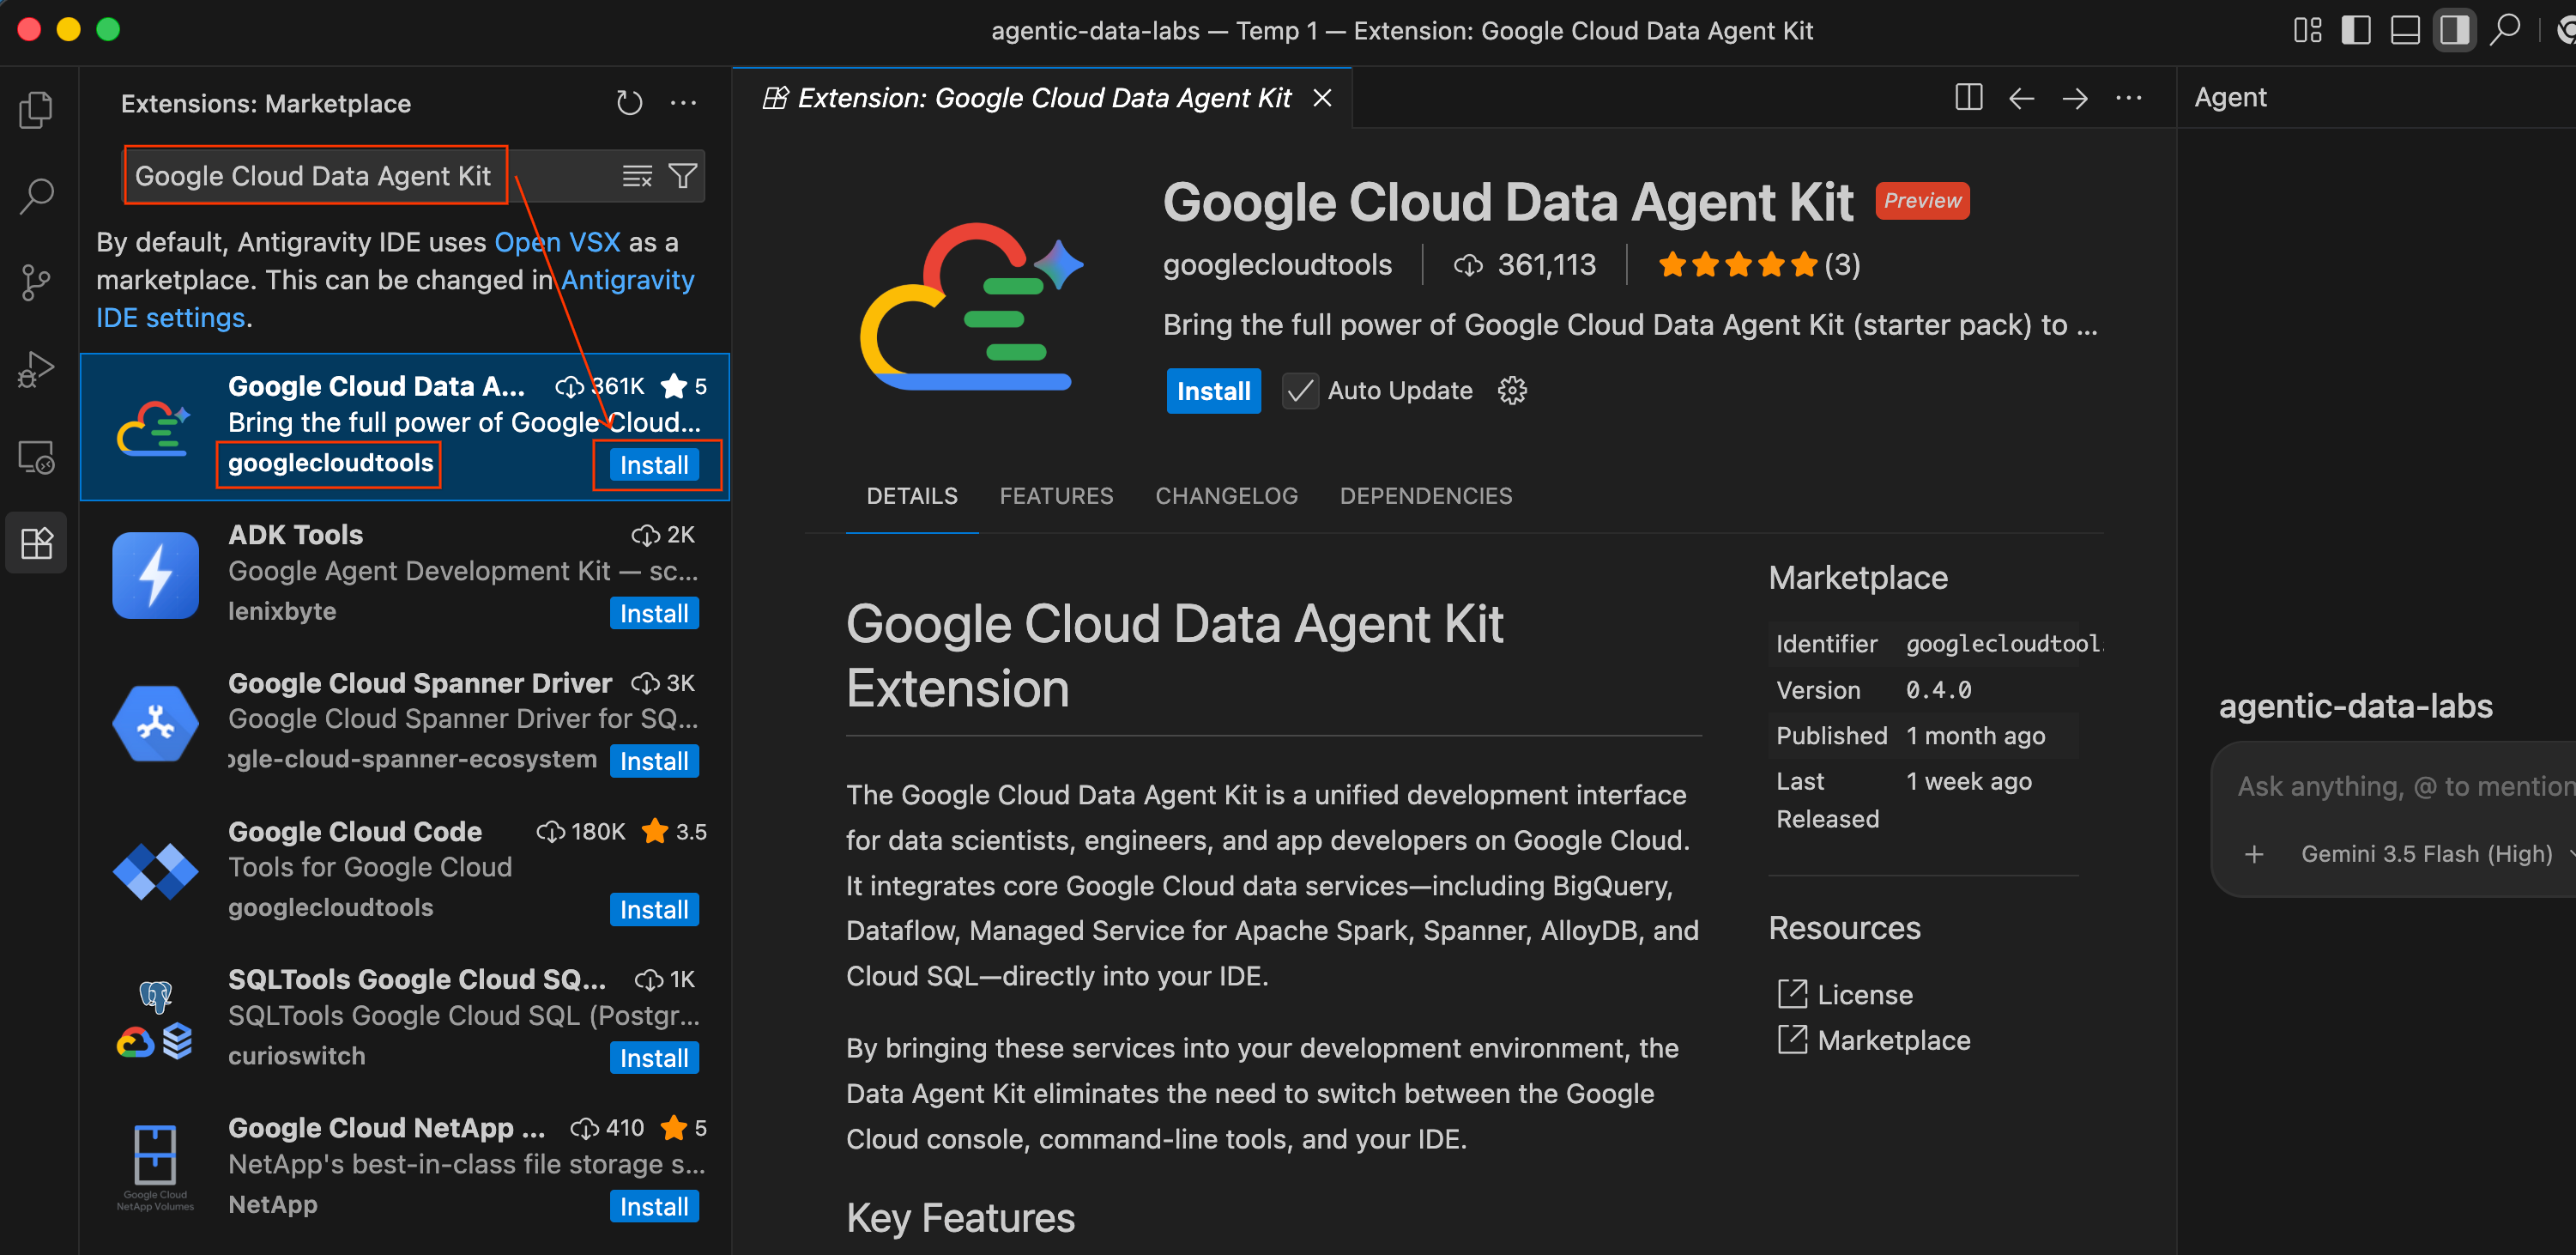
- Antigravity IDE-তে, স্ক্রিনের একেবারে বাম দিকে অ্যাক্টিভিটি বারে থাকা এক্সটেনশন আইকনটিতে ক্লিক করুন (এটি দেখতে চারটি বর্গক্ষেত্রের মতো)।
- এক্সটেনশন প্যানেলের উপরের সার্চ বারে
Google Cloud Data Agent Kitটাইপ করুন। -
googlecloudtoolsদ্বারা প্রকাশিত Google Cloud Data Agent Kit নামের এক্সটেনশনটি খুঁজুন। - ইনস্টল বোতামে ক্লিক করুন।
- একটি প্রম্পট আসতে পারে যেখানে জিজ্ঞাসা করা হবে, "আপনি কি প্রকাশক 'googlecloudtools' এবং তাদের এক্সটেনশনগুলিকে বিশ্বাস করেন?"। এগিয়ে যেতে 'Trust Publishers & Install'-এ ক্লিক করুন।
ইনস্টল হয়ে গেলে, আপনি Antigravity IDE-র একেবারে বাম দিকের অ্যাক্টিভিটি বারে একটি নতুন Google Cloud Data Agent Kit আইকন দেখতে পাবেন।
- 'Welcome to Google Cloud Data Agent Kit' শিরোনামের একটি অনবোর্ডিং পেজ স্বয়ংক্রিয়ভাবে খুলে যাবে। আপনি যদি আপনার ক্লাউড অ্যাকাউন্টে সাইন ইন না করে থাকেন, তবে অ্যাক্সেস দেওয়ার জন্য নির্দেশাবলী অনুসরণ করুন।
- কনফিগারেশন সামারি সেকশনে, প্রজেক্ট ফিল্ডটি খুঁজুন। ড্রপডাউনে ক্লিক করে আপনার গুগল ক্লাউড প্রজেক্টটি সিলেক্ট করুন। আপনার রিজিয়ন
us-central1হিসেবে সেট করুন। এরপর কনফিগার এমসিপি সার্ভারস সিলেক্ট করুন।
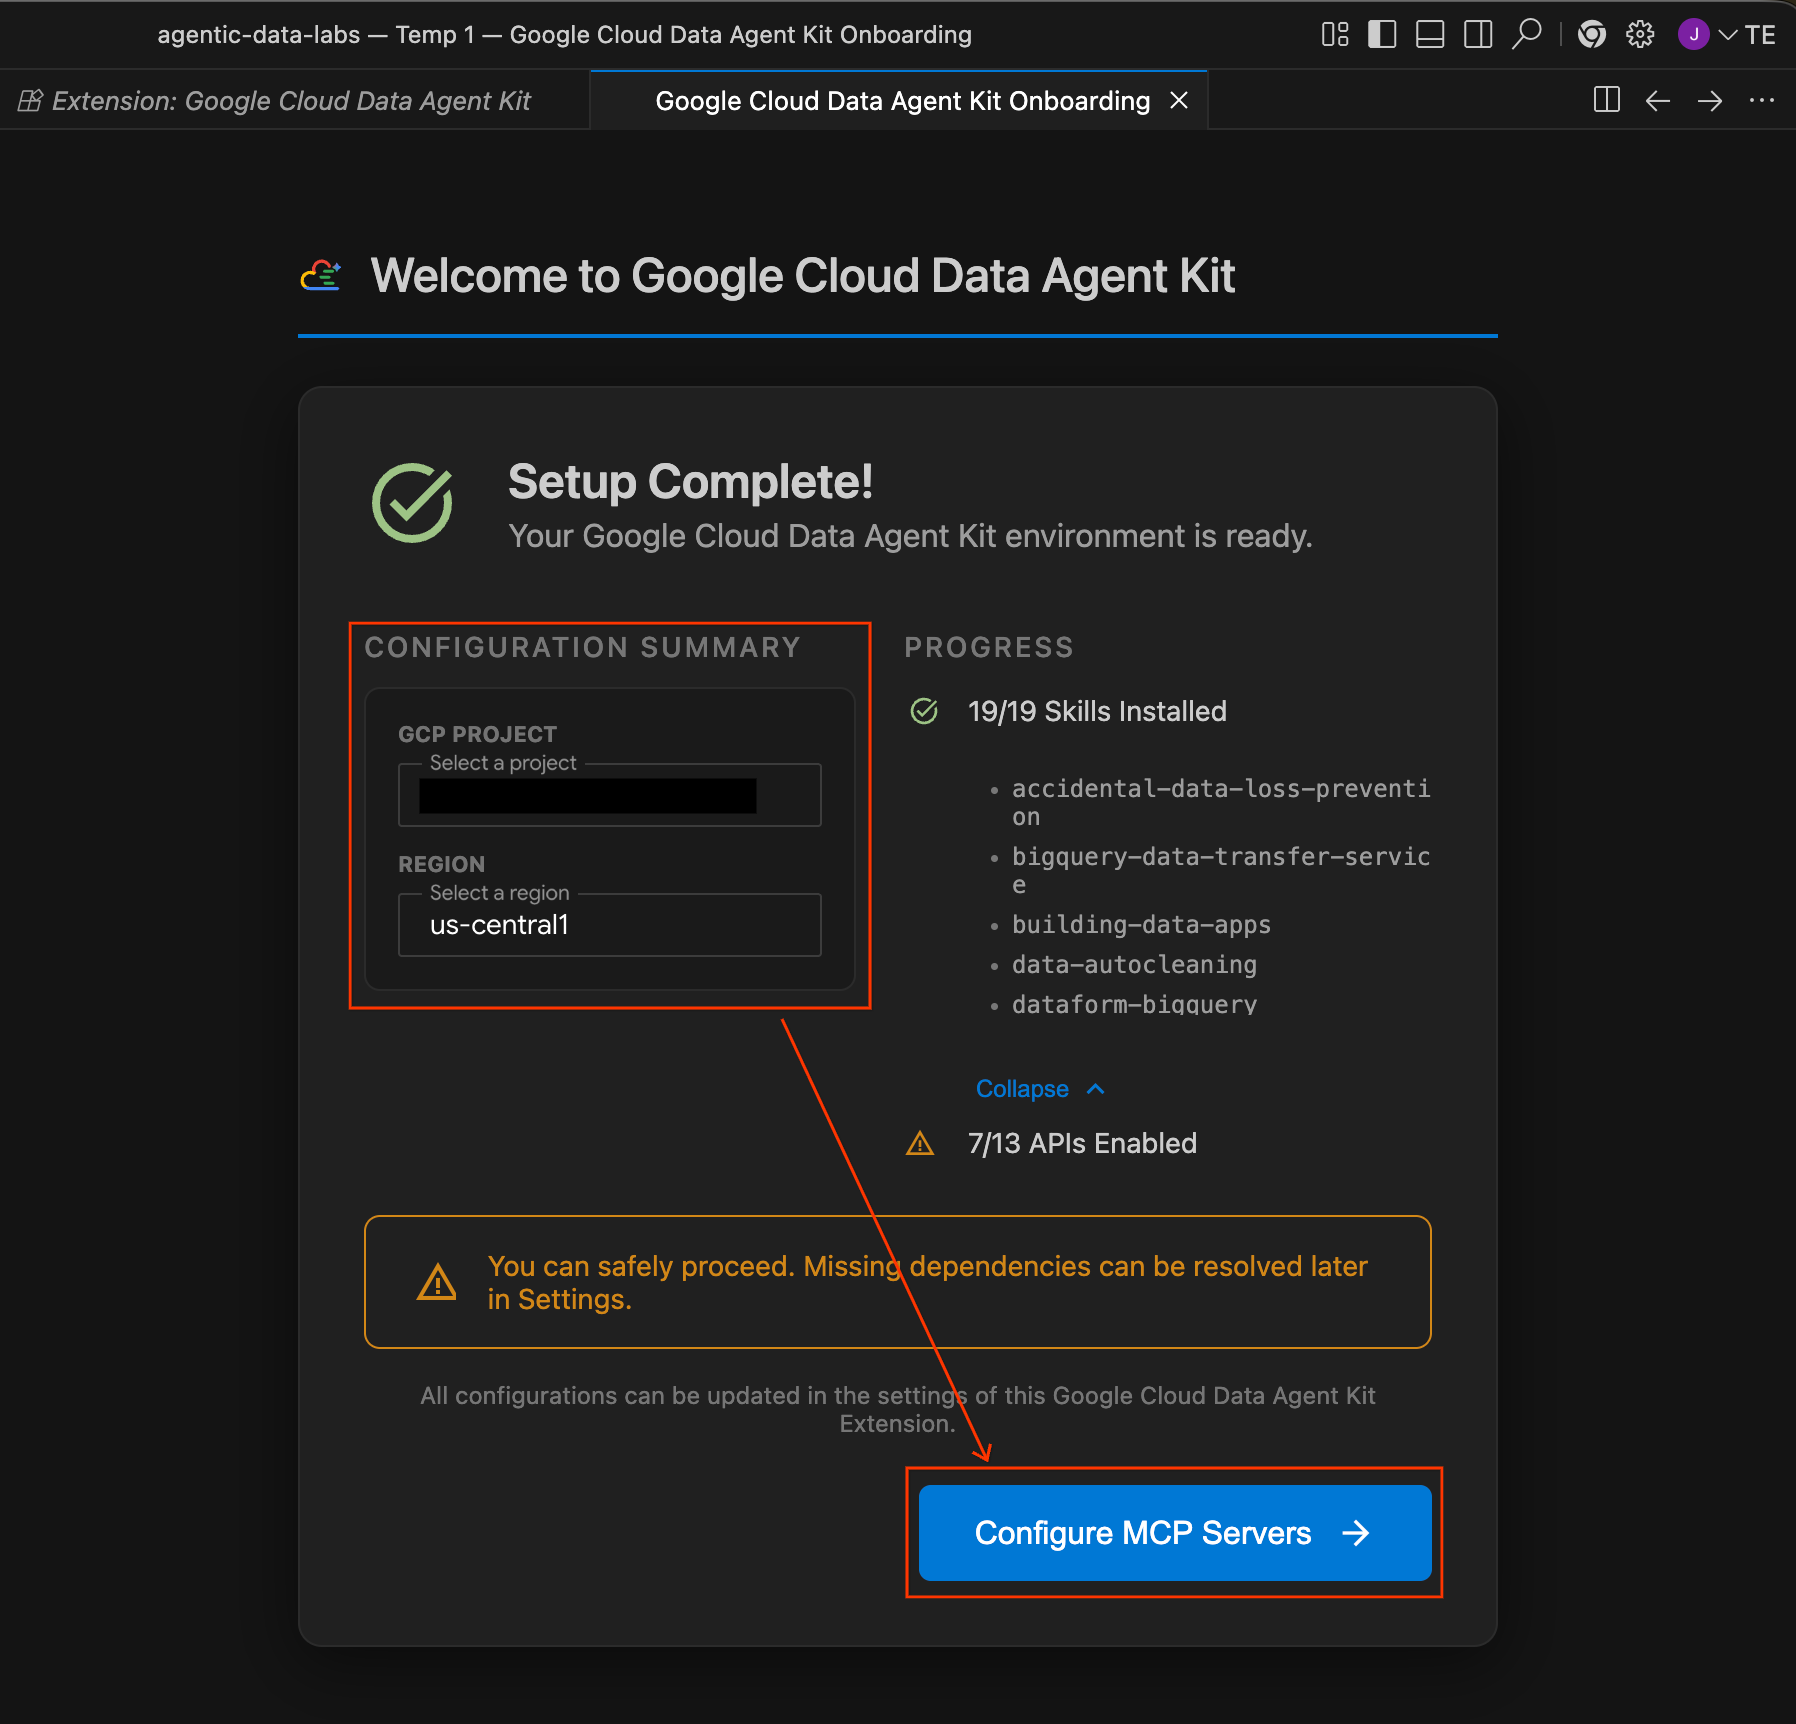
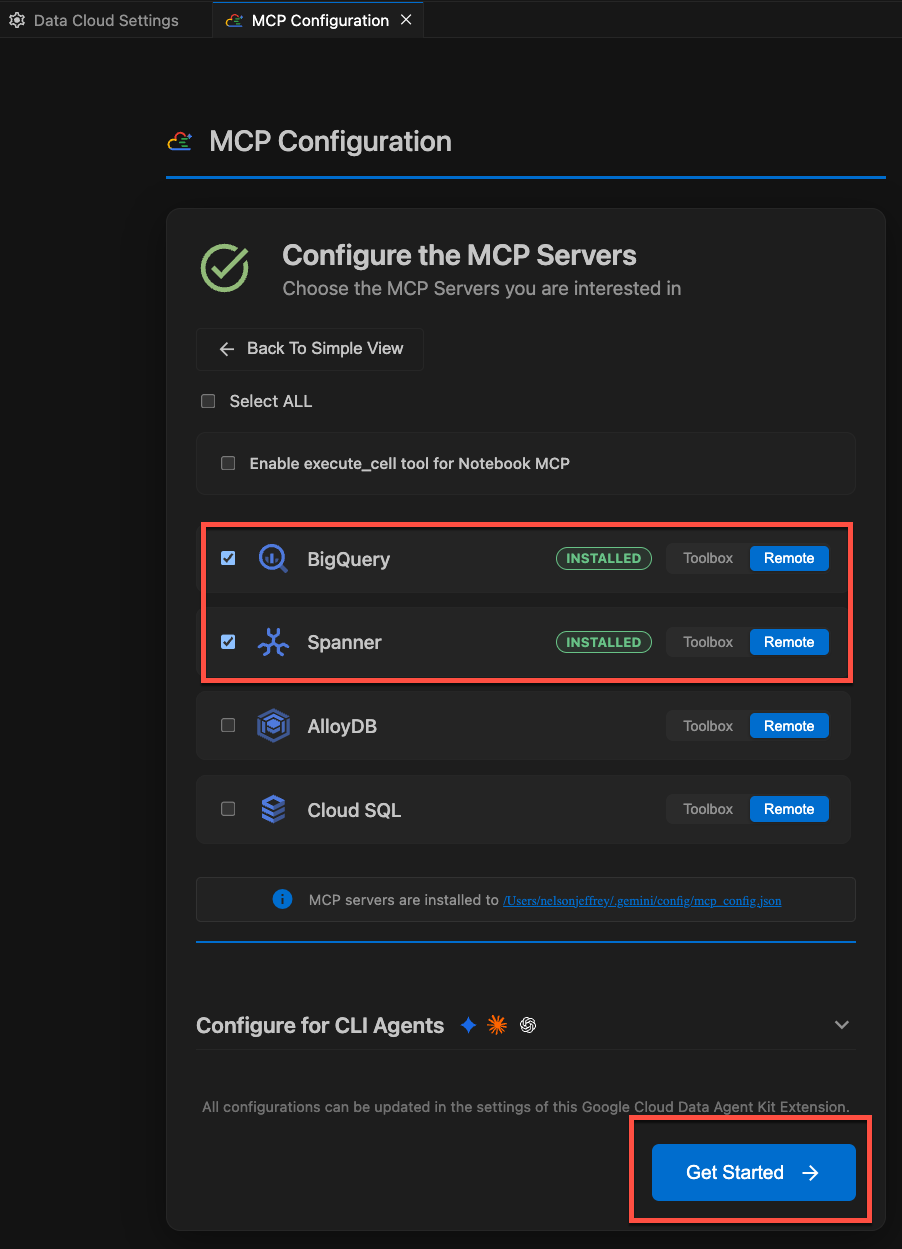
- ‘Configure MCP Servers’ নির্বাচন করুন। ‘MCP Configuration’ প্যানেলের অধীনে, নিম্নলিখিত রিমোট MCP সার্ভারগুলি সক্রিয় করা নিশ্চিত করুন:
- বিগকোয়েরি
- স্প্যানার
- নোটবুক
তারপর Get Started-এ ক্লিক করুন।
কনফিগারেশন বিকল্পগুলি অন্বেষণ করুন
সেটআপ সম্পন্ন হলে, আপনি 'Get started with Google Cloud Data Agent Kit' পেজটিতে চলে আসবেন।
- "সেটআপ ও কনফিগারেশন"-এর অধীনে, "শুরু করুন "-এ ক্লিক করুন।
- এটি ডেটা এজেন্ট কিট কনফিগারেশন প্যানেলটি খোলে। ট্যাবগুলো ঘুরে দেখুন:
- প্রজেক্ট এবং অঞ্চল: আপনার নির্বাচিত প্রজেক্ট আইডি যাচাই করুন এবং নিশ্চিত করুন যে সেটআপ স্ক্রিপ্টটি সমস্ত প্রয়োজনীয় এপিআই (কম্পিউট ইঞ্জিন, ক্লাউড স্টোরেজ, বিগকোয়েরি, স্প্যানার, ইত্যাদি) সক্রিয় করেছে।
- BigQuery: আপনার BigQuery কোয়েরিগুলোর জন্য ডিফল্ট অবস্থান কনফিগার করুন।
us-central1অঞ্চলটি ব্যবহার করুন। - এমসিপি সার্ভার কনফিগার করুন: সক্রিয় এমসিপি সার্ভারগুলো (বিগকোয়েরি, নোটবুক, স্প্যানার, ইত্যাদি) দেখুন, যেগুলো এআই এজেন্টদের আপনার ডেটার সাথে নিরাপদে ইন্টারঅ্যাক্ট করতে দেয়।
- দক্ষতা: আগে থেকে তৈরি দক্ষতাগুলো অন্বেষণ করুন যা এজেন্টদের জটিল ডেটা সংক্রান্ত কাজের জন্য বিশেষায়িত সক্ষমতা প্রদান করে।
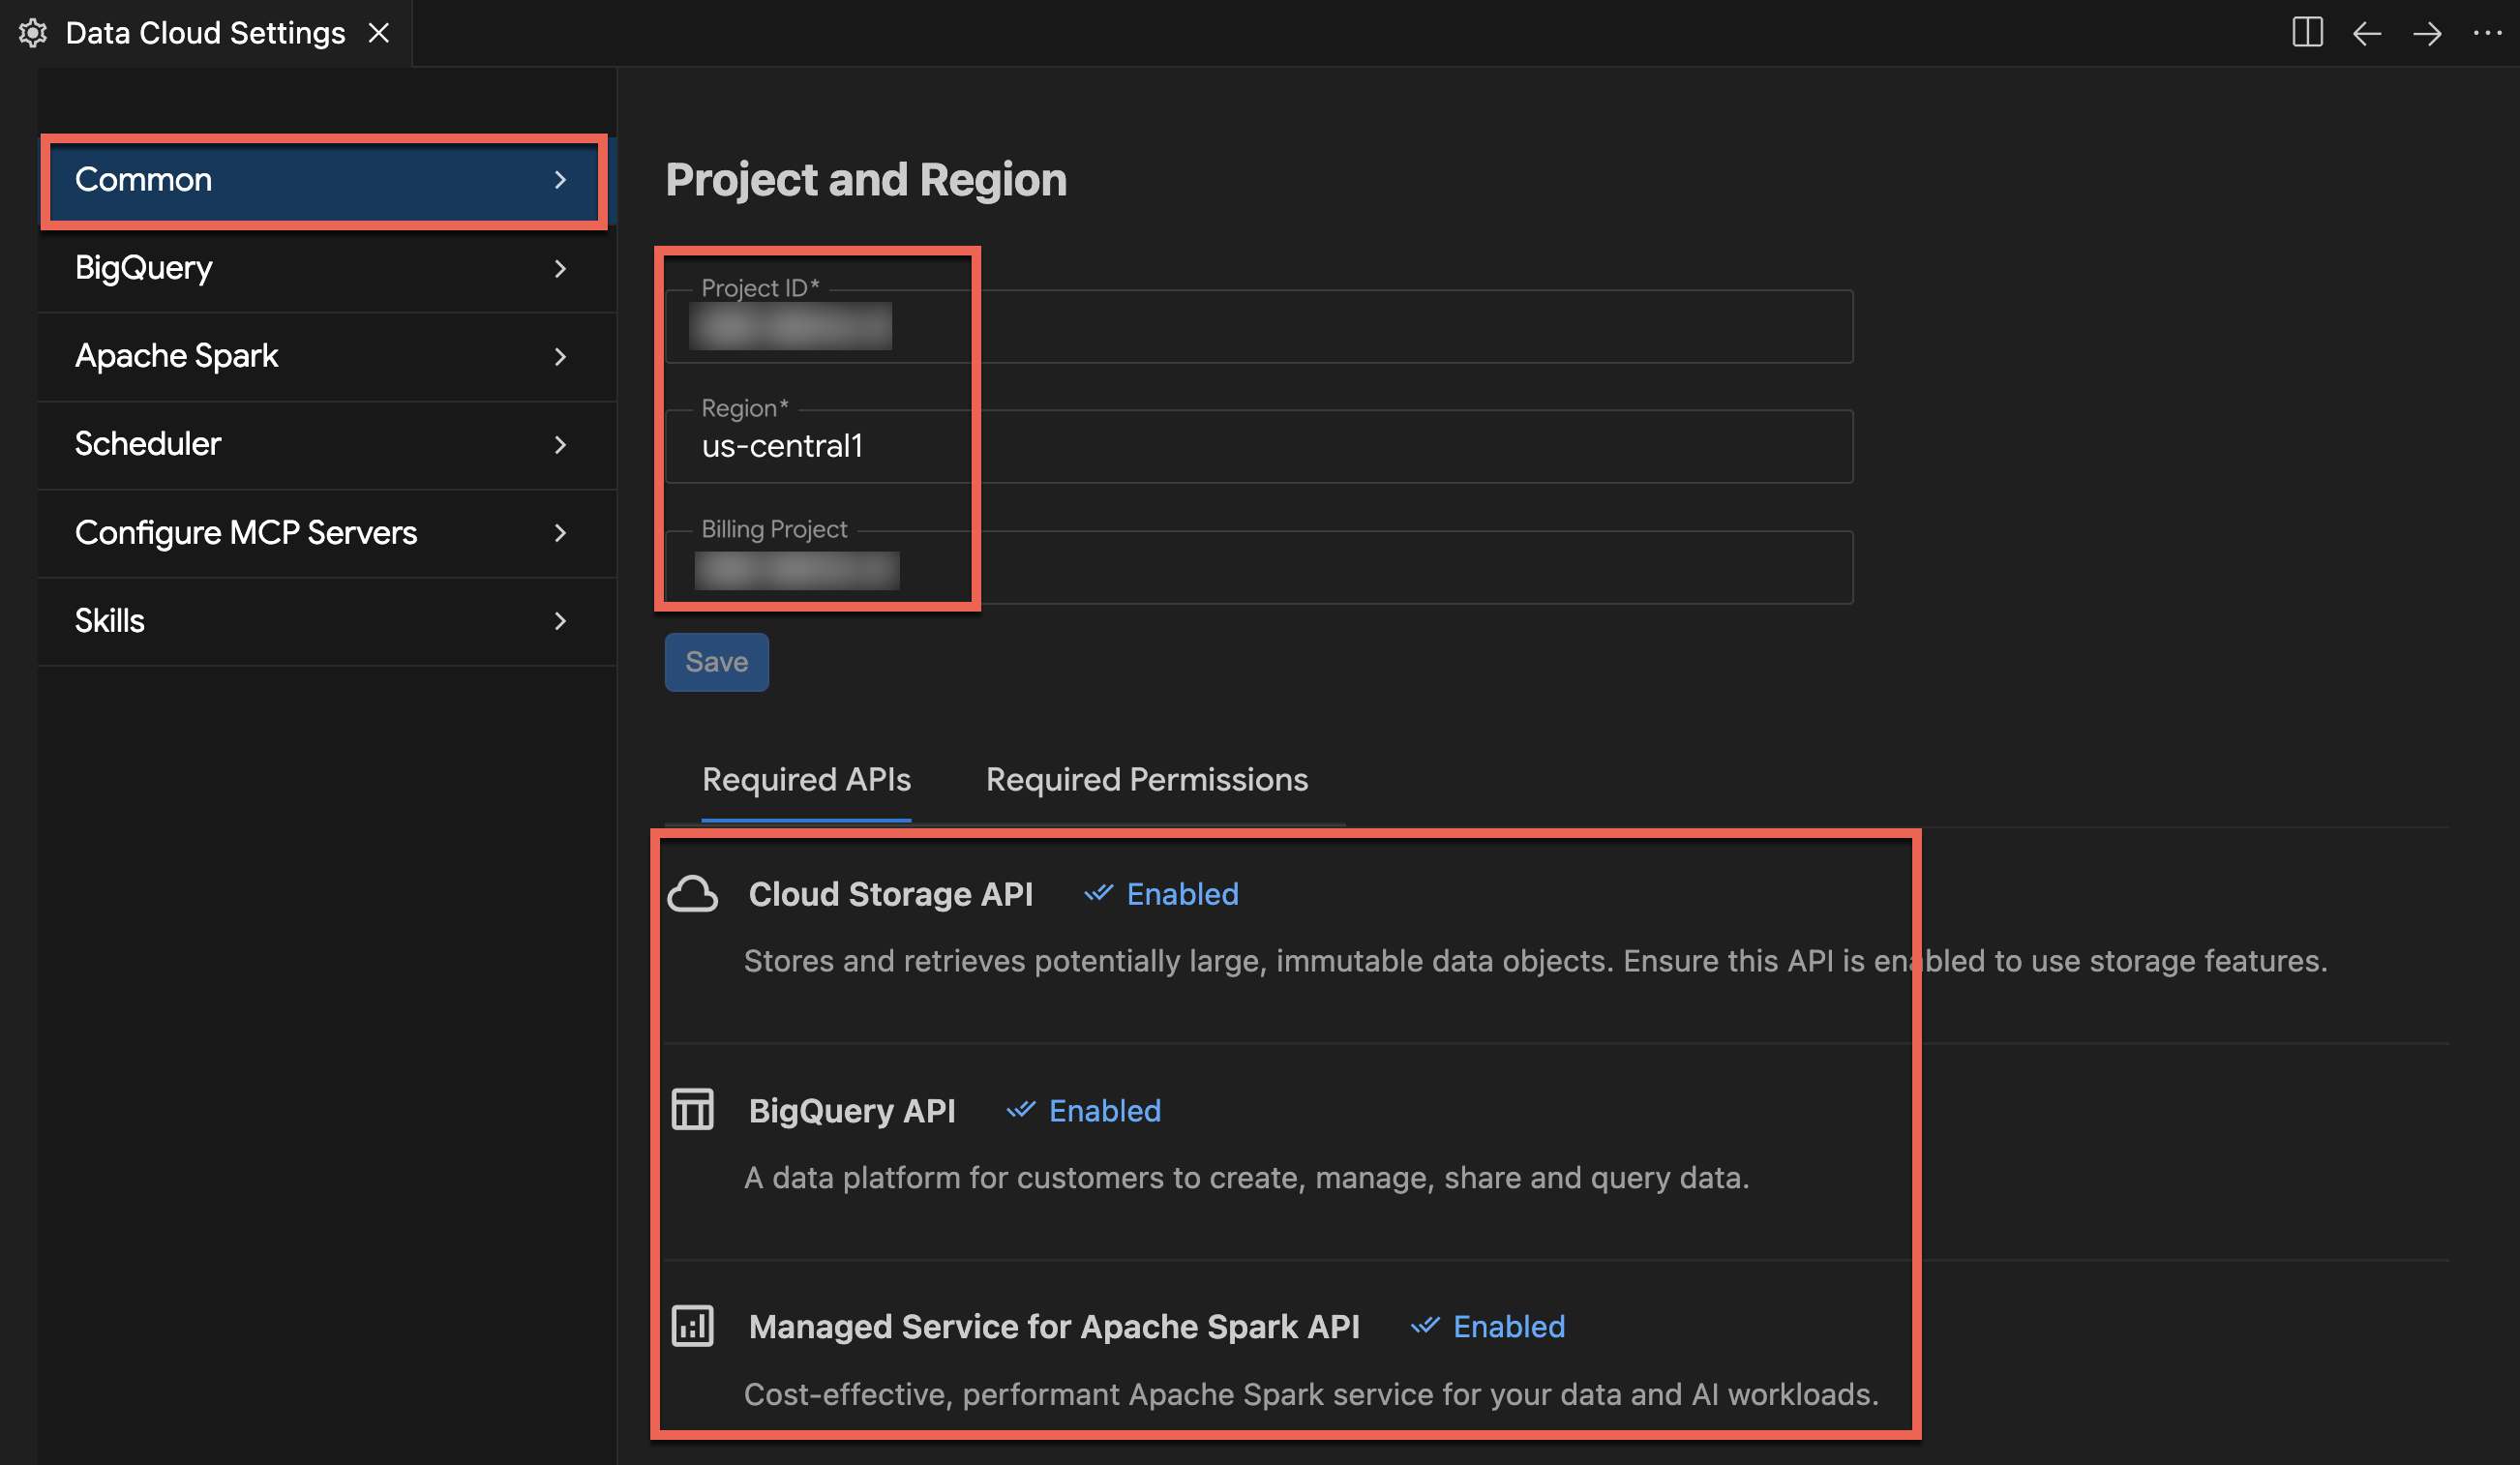
অধ্যায়ের পুনরালোচনা: স্প্যানার এবং এয়ারফ্লো ব্যাকগ্রাউন্ডে বিল্ড হওয়ার সময়ে আপনি GCS এবং BigQuery অ্যাসেট তৈরি করার জন্য বুটস্ট্র্যাপ স্ক্রিপ্টটি চালিয়েছিলেন। এরপর আপনি অ্যান্টিগ্র্যাভিটি আইডিই-তে প্রজেক্টটি খুলেছেন এবং গুগল ক্লাউড ডেটা এজেন্ট কিট এক্সটেনশনটি সক্রিয় করেছেন। আপনি এখন আপনার প্রথম নোটবুকটি লেখার জন্য প্রস্তুত।
৩. স্পার্ক সার্ভারলেস ব্যবহার করে কাঁচা লগ গ্রহণ করুন
এই অংশে, আপনি ডেটা লেকে সরাসরি JSON ট্রানজ্যাকশন লগ অন্তর্ভুক্ত করবেন। অ্যাপাচি স্পার্কের জন্য পরিচালিত পরিষেবা (স্পার্ক সার্ভারলেস) সরাসরি BigQuery- এর নেটিভ স্টোরেজের সাথে সংযুক্ত হয়। আপনি টেবুলার ডেটা পরিচালনা করতে এবং সরাসরি কোয়েরি ও অ্যানালিটিক্স সক্ষম করতে স্ট্যান্ডার্ড BigQuery কানেক্টর ব্যবহার করবেন।
পূর্ব-কনফিগার করা স্পার্ক সার্ভারলেস রানটাইম অন্বেষণ করুন
স্পার্ক কোড এক্সিকিউট করার আগে, সেটআপ স্ক্রিপ্ট দ্বারা আগে থেকে কনফিগার করা সার্ভারলেস রানটাইম টেমপ্লেটটি পরীক্ষা করুন। এই টেমপ্লেটটি টার্গেট এক্সিকিউশন এনভায়রনমেন্ট ব্যাকএন্ড নির্ধারণ করে এবং প্রয়োজনীয় কানেক্টর ডিপেন্ডেন্সিগুলো বান্ডল করে।
- IDE অ্যাক্টিভিটি বারে, Google Cloud Data Agent Kit প্যানেলটি খুলুন।
- Apache Spark ড্রপ-ডাউন মেনুটি প্রসারিত করুন, তারপর Serverless প্রসারিত করুন।
-
fraud-pipeline-runtimeউপর রাইট-ক্লিক করে প্রোফাইল (Profile) নির্বাচন করলে এডিটরে এর কনফিগারেশন ভিউটি খুলবে। - প্রোফাইল ট্যাবে, নিচে স্ক্রল করুন এবং এনভায়রনমেন্টের সাথে সংযুক্ত কাস্টম ডিপেন্ডেন্সিগুলো পরীক্ষা করার জন্য প্রোপার্টিজ প্রসারিত করুন:
-
spark.jars: এর মধ্যেgs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jarরয়েছে, যা Spark Spanner কানেক্টর ব্যবহার করে Spark জবগুলোকে ল্যাবের পরবর্তী পর্যায়ে ইনফারেন্সের ফলাফল সরাসরি Cloud Spanner-এ লিখতে দেয়। (দ্রষ্টব্য: Dataproc Serverless-এ ডিফল্টরূপে Google Cloud-এর Spark BigQuery কানেক্টর অন্তর্ভুক্ত থাকে, ফলে BigQuery টেবিল পড়া ও লেখার জন্য কোনো অতিরিক্ত jar কনফিগারেশনের প্রয়োজন হয় না)।
-
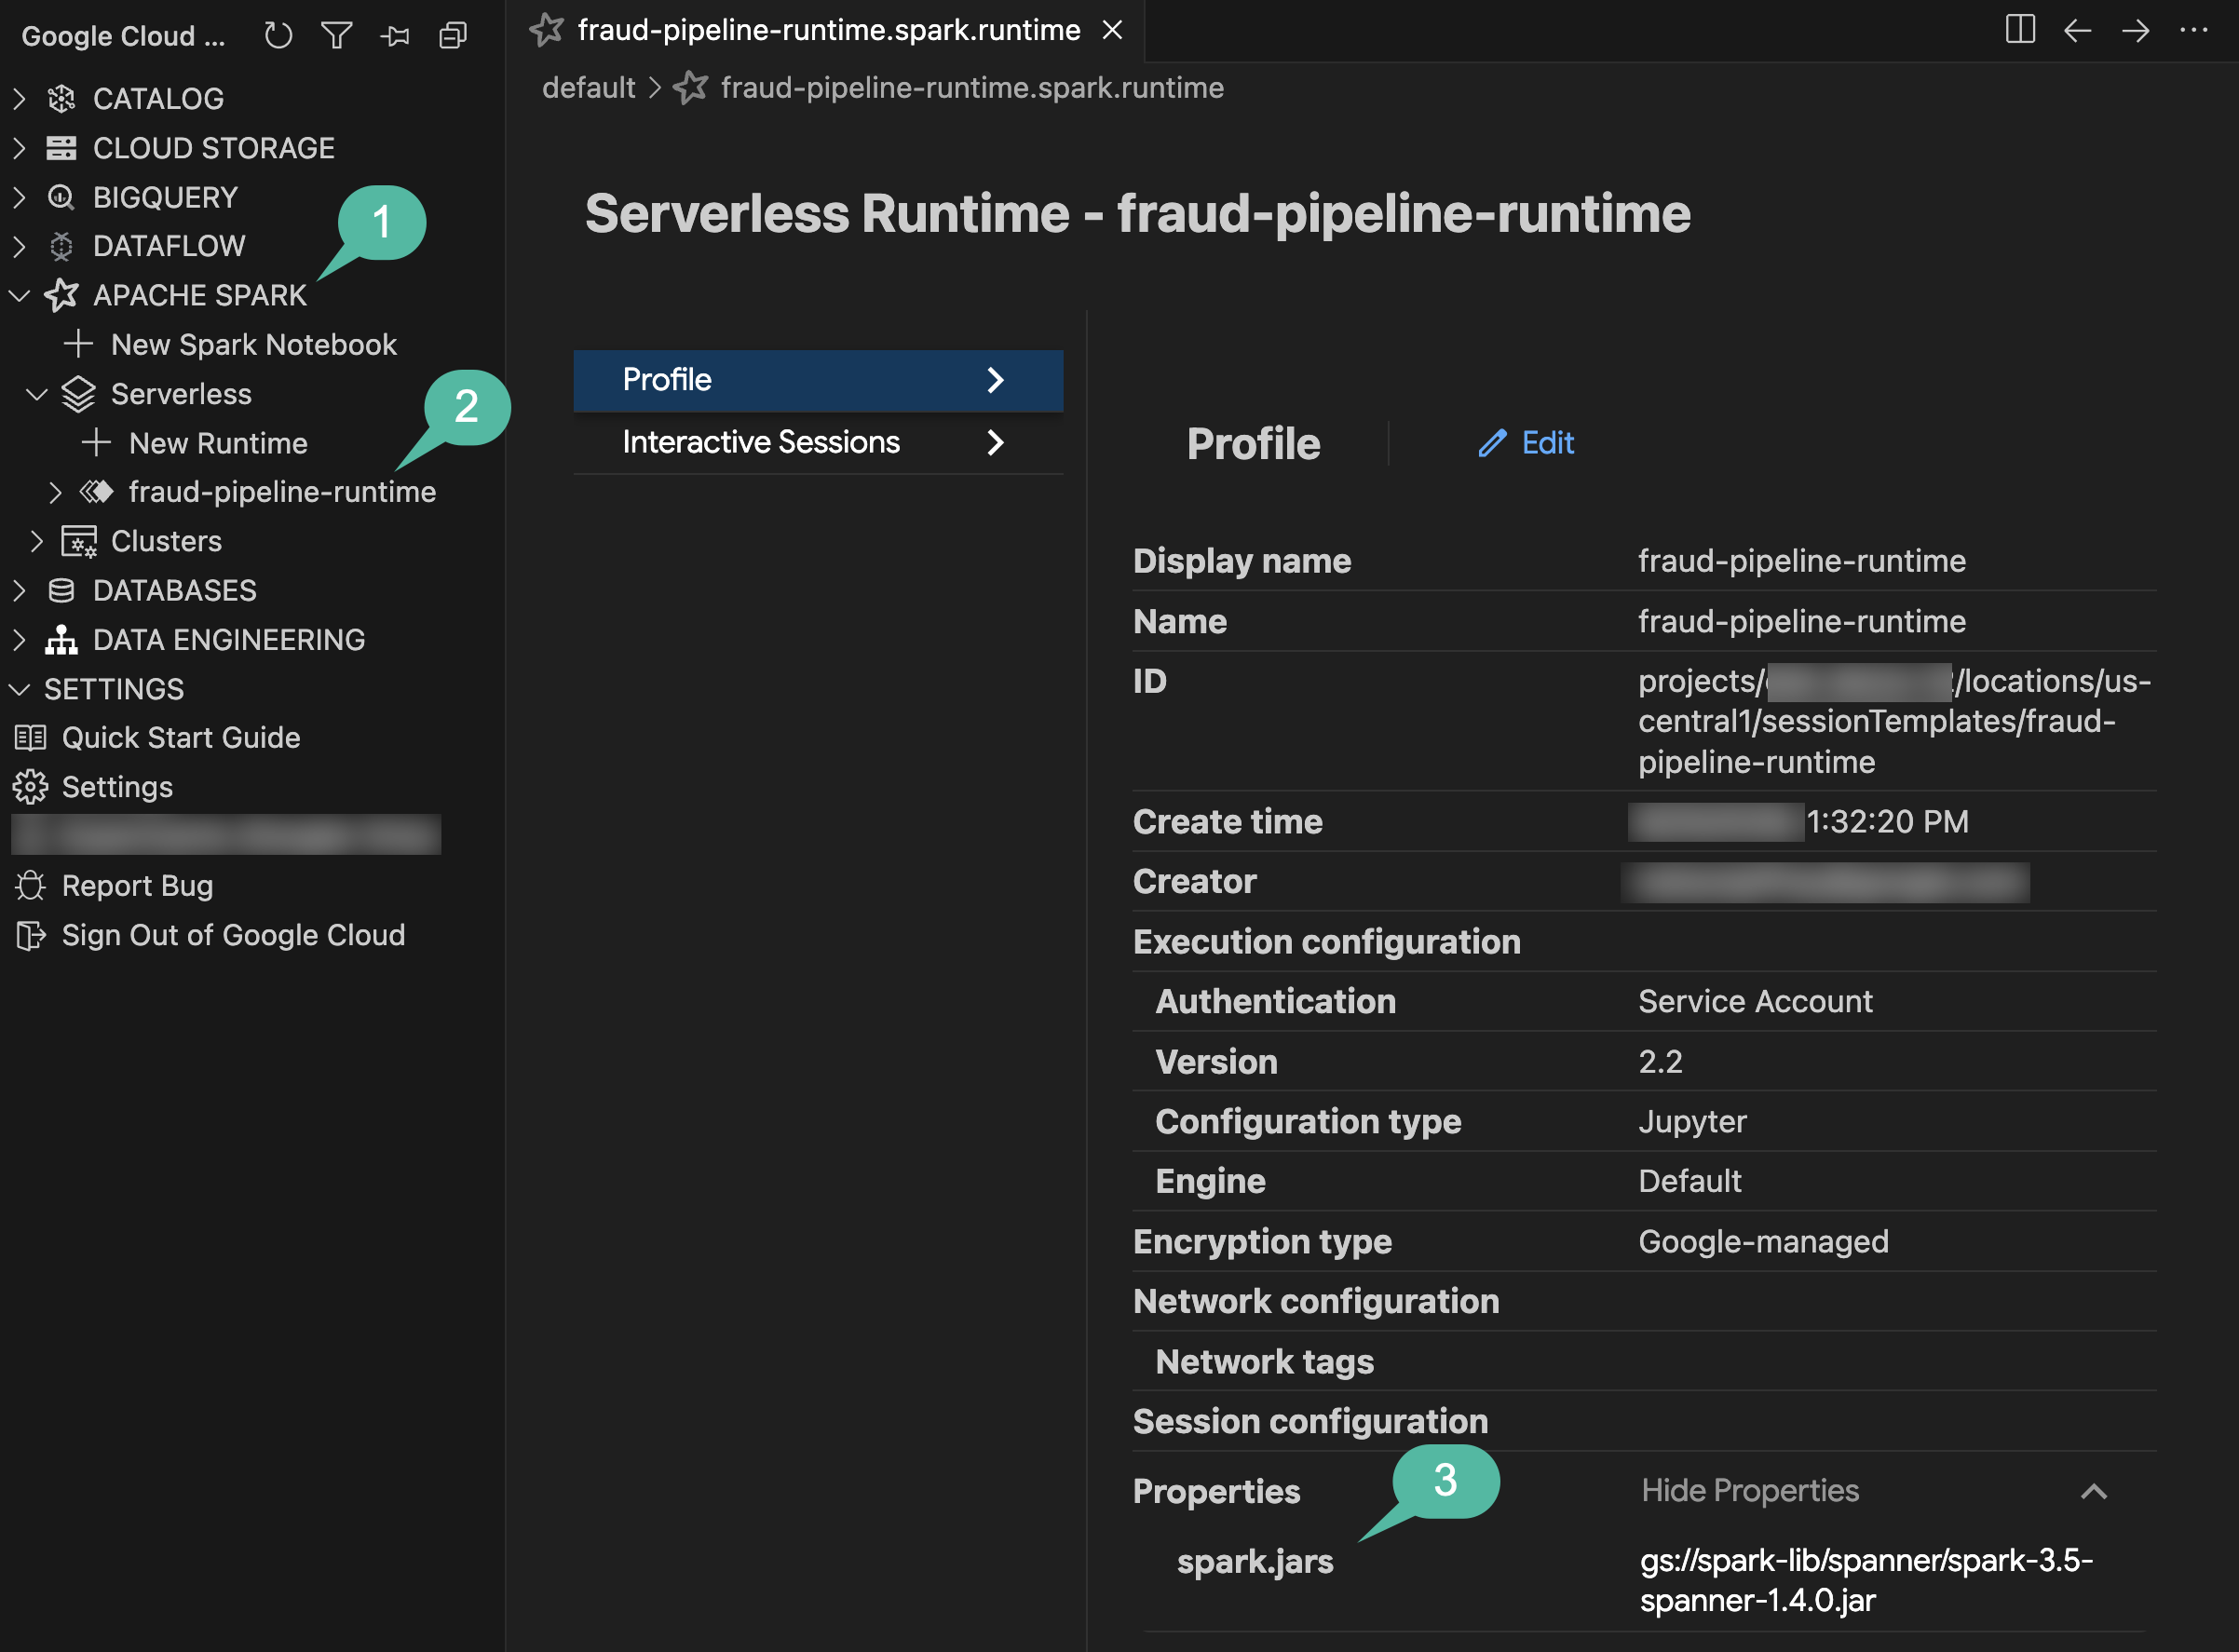
- বাম দিকে থাকা ‘ইন্টারেক্টিভ সেশনস’ ট্যাবটি লক্ষ্য করুন। এটি বর্তমানে খালি, কারণ আপনি এখনও কোনো কোড চালাননি। পরবর্তী ধাপে নোটবুকটি রান করার সাথে সাথেই, একটি লাইভ সার্ভারলেস কম্পিউট সেশন স্বয়ংক্রিয়ভাবে প্রস্তুত হয়ে এখানে প্রদর্শিত হবে!
ডেটা এজেন্ট কিট ব্যবহার করে ডেটা গ্রহণ করুন
ম্যানুয়ালি একটি স্পার্ক সেশন কনফিগার করা বা প্রথম থেকে পাইস্পার্ক লোডিং স্ক্রিপ্ট লেখার পরিবর্তে, আপনি ডেটা এজেন্ট কিট ব্যবহার করে একটি এজেন্টের সাথে পেয়ার-প্রোগ্রামিং করবেন।
- উপরের ডানদিকের টুলবারে থাকা টগল এজেন্ট আইকনে ক্লিক করে এজেন্ট চ্যাট প্যানেটি খুলুন।
- নিচের প্রম্পটটি চ্যাটে পেস্ট করুন (অবশ্যই
${PROJECT_ID}এর জায়গায় আপনার আসল গুগল ক্লাউড প্রজেক্ট আইডি বসাবেন):
Create a PySpark notebook (01_ingestion.ipynb) to ingest JSON transaction logs
from gs://${PROJECT_ID}-fin-clearing-raw/ into a BigQuery table
`${PROJECT_ID}.transactions_dataset_evals.raw_transactions`
using the Spark BigQuery connector (`format("bigquery")`) with overwrite mode.
- যদি এজেন্ট ব্যাকগ্রাউন্ড ভেরিফিকেশন কমান্ড চালানোর অনুমতি চায় (যেমন "এই কমান্ডটি চালানোর অনুমতি দিন?" ), তাহলে প্রস্তাবিত কমান্ডটি পর্যালোচনা করুন এবং 'হ্যাঁ, এইবারের জন্য অনুমতি দিন ' (অথবা 'হ্যাঁ, এবং সর্বদা অনুমতি দিন ') নির্বাচন করুন।
- এজেন্ট ফাইলটি তৈরি করা শেষ করলে, আপনার ওয়ার্কস্পেসে
notebooks/01_ingestion.ipynbসংরক্ষণ করতে চ্যাট পেনের নীচে থাকা নীল রঙের ' Accept all' বোতামে (বা টিক চিহ্ন আইকনে) ক্লিক করুন।
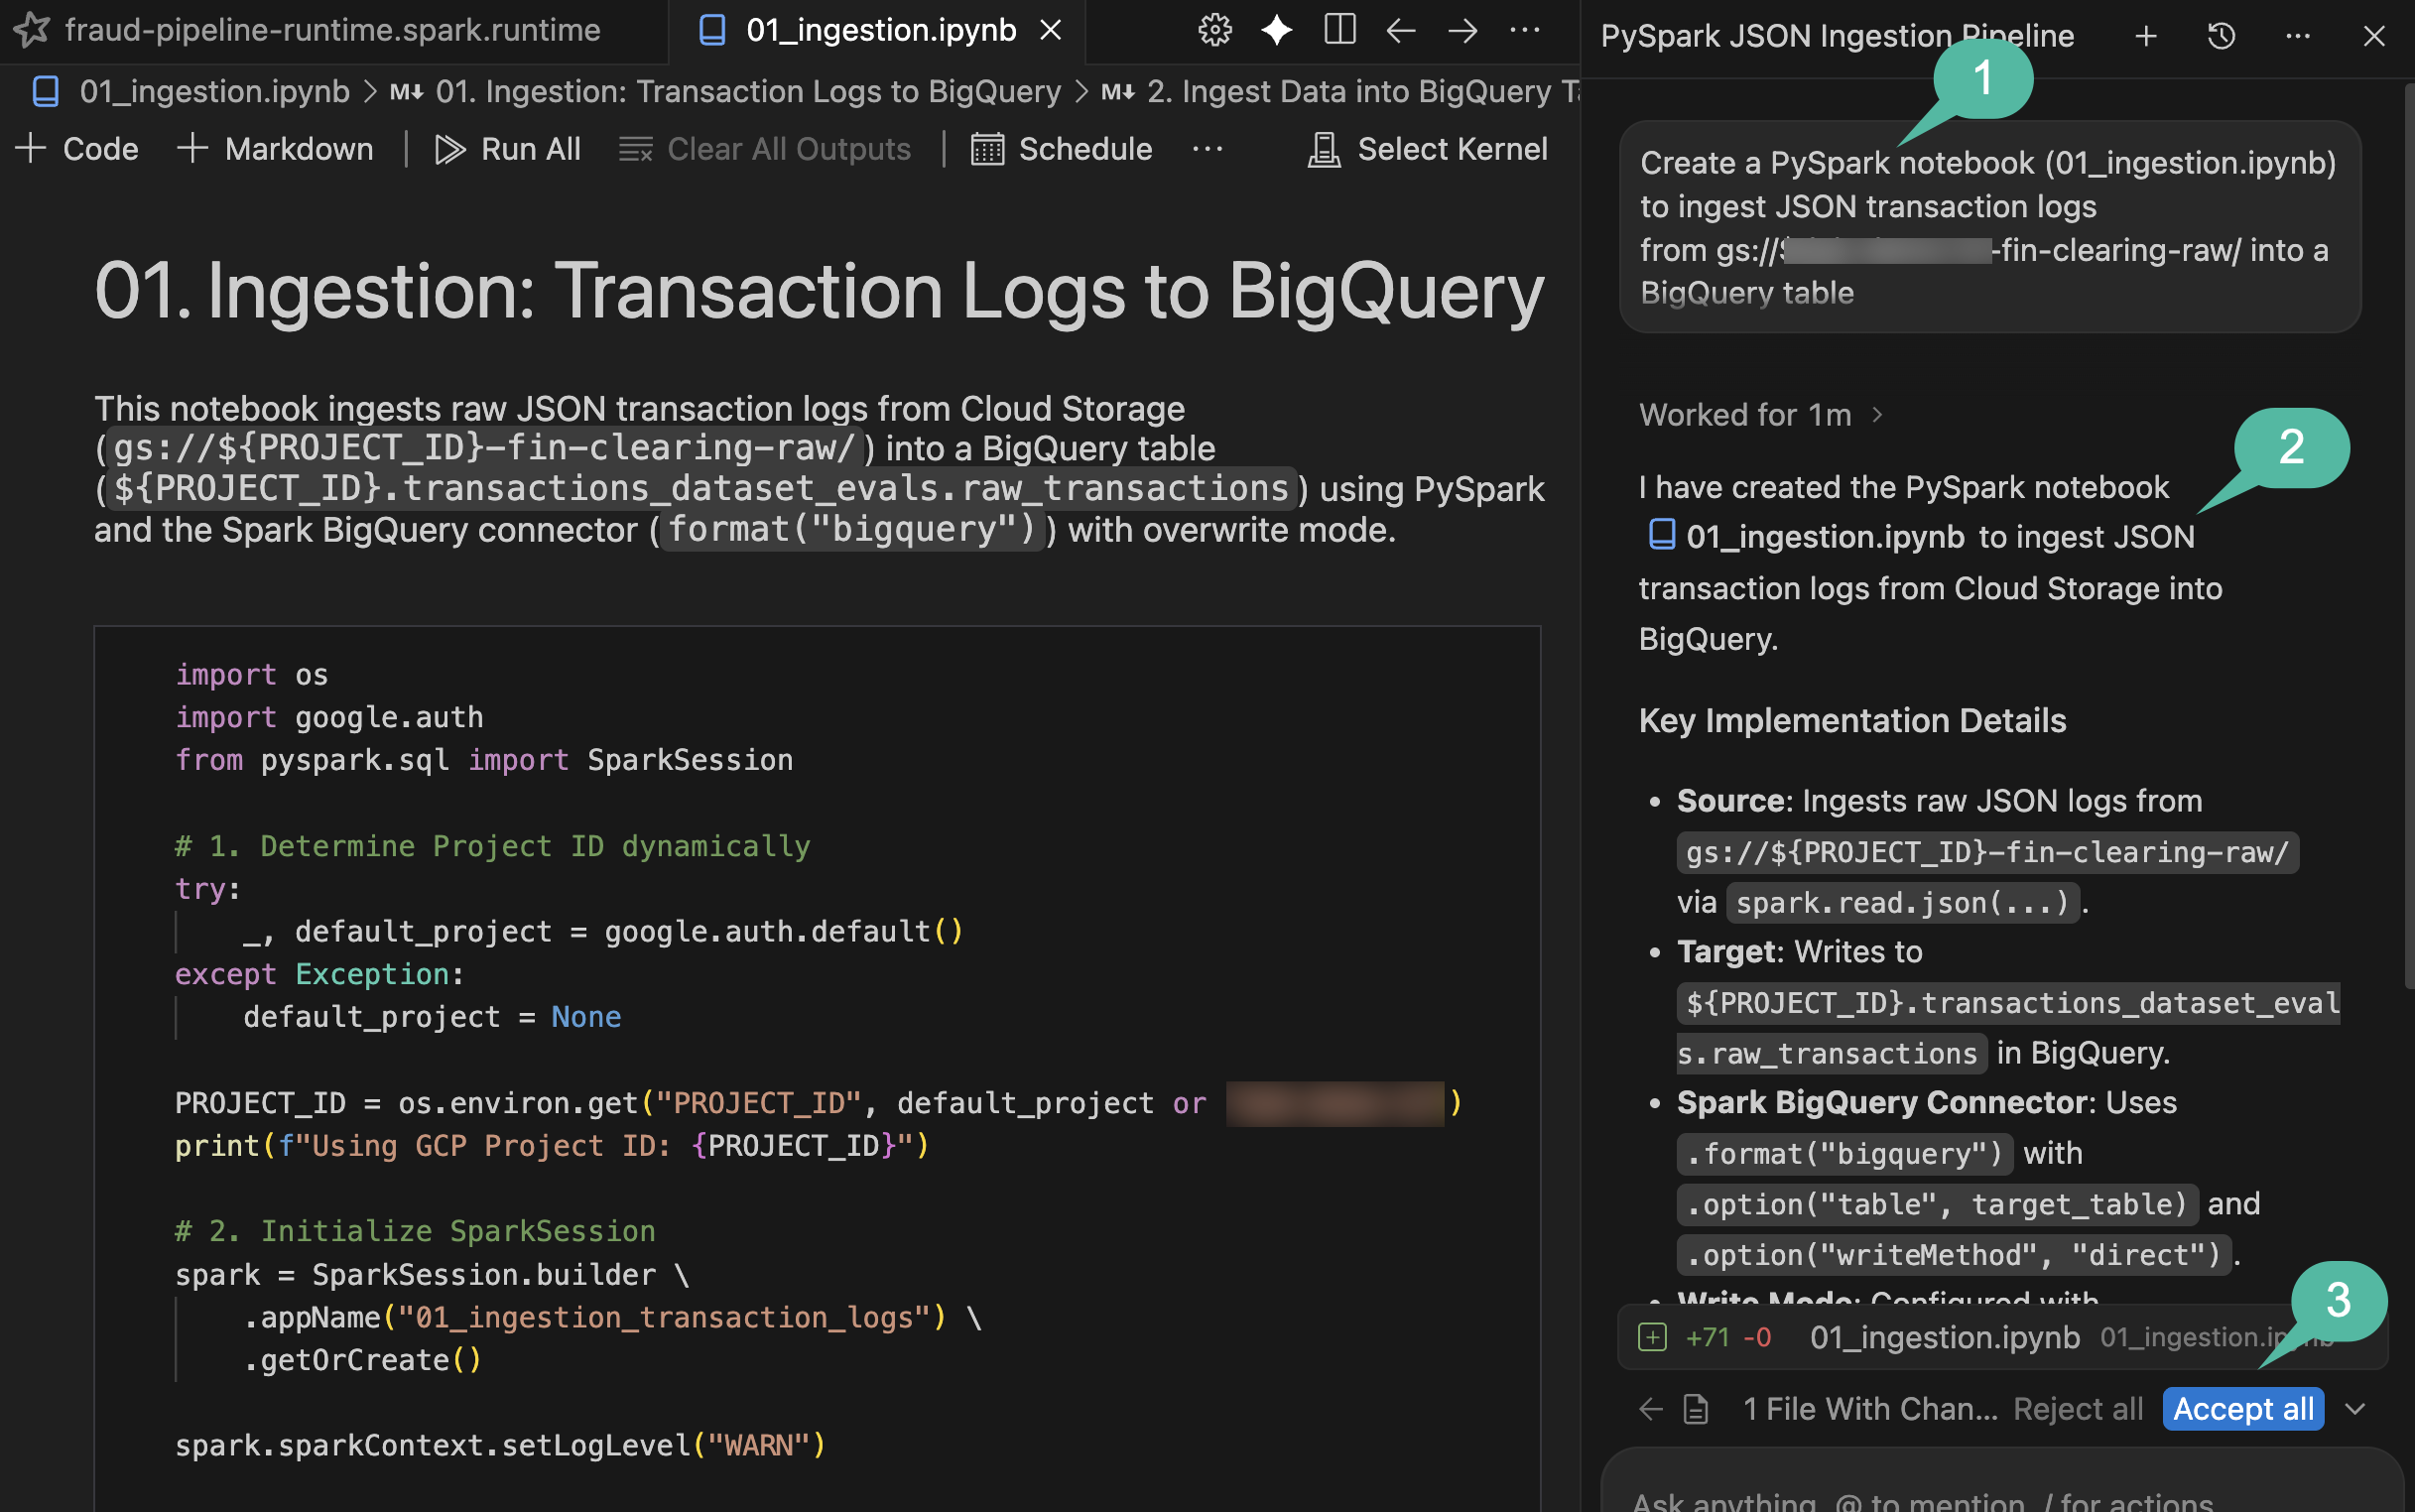
নোটবুকটি পর্যালোচনা করুন এবং কার্যকর করুন।
- IDE-তে নতুন তৈরি হওয়া
notebooks/01_ingestion.ipynbফাইলটি খুলুন। - BigQuery কানেক্টরের রাইট লজিকের জন্য PySpark কোডটি পর্যালোচনা করুন।
- IDE-এর নোটবুক টুলবারে থাকা 'Run All'- এ ক্লিক করুন।
- আপনি যদি প্রথমবারের মতো কোনো রিমোট স্পার্ক নোটবুক চালান, তাহলে IDE আপনাকে লোকাল ডিপেন্ডেন্সি ইনস্টল করার জন্য অনুরোধ করতে পারে। অনুরোধ করা হলে, ‘Install dependencies for Remote Spark Kernels’-এ ক্লিক করুন এবং ইনস্টলেশন ডায়ালগগুলো নিশ্চিত করুন, তারপর আবার ‘Run All’-এ ক্লিক করুন।
- 'Select Kernel' ড্রপডাউন মেনু থেকে, 'Remote Spark Kernels ' -> 'fraud-pipeline-runtime on Serverless Spark' নির্বাচন করুন। (টিপ: যদি আপনি আপনার আগে থেকে কনফিগার করা রানটাইম টেমপ্লেটটি তালিকায় দেখতে না পান, তাহলে উপলব্ধ রিমোট কার্নেলগুলো পুনরায় লোড করতে কার্নেল পিকার ড্রপডাউনের উপরের ডানদিকে থাকা রিফ্রেশ আইকনে ক্লিক করুন )।
- এডিটরের নিচের বাম দিকের স্ট্যাটাস বারটি দেখুন। আপনি দেখতে পাবেন
Connecting to kernel: fraud-pipeline-runtime on Serverless Spark...’। যেহেতু এটি Spark Serverless রানটাইম কার্নেল ব্যাকএন্ডের প্রাথমিক লঞ্চ, তাই এটি প্রোভিশন এবং বুট আপ হতে কয়েক মিনিট সময় লাগবে। - কার্নেল সংযোগ স্থাপন সম্পন্ন করলেই, নোটবুকটি স্বয়ংক্রিয়ভাবে ক্রমানুসারে সমস্ত সেল চালানো শুরু করবে, যাতে কাঁচা ট্রানজ্যাকশন লগগুলোকে আপনার BigQuery ডেটাসেটে প্রসেস করা যায়।
যাচাইকরণ
এক্সিকিউশন সম্পন্ন হলে, টেবিল তৈরি হয়েছে কিনা তা যাচাই করতে ডেটা এজেন্ট কিট ক্যাটালগটি দেখুন:
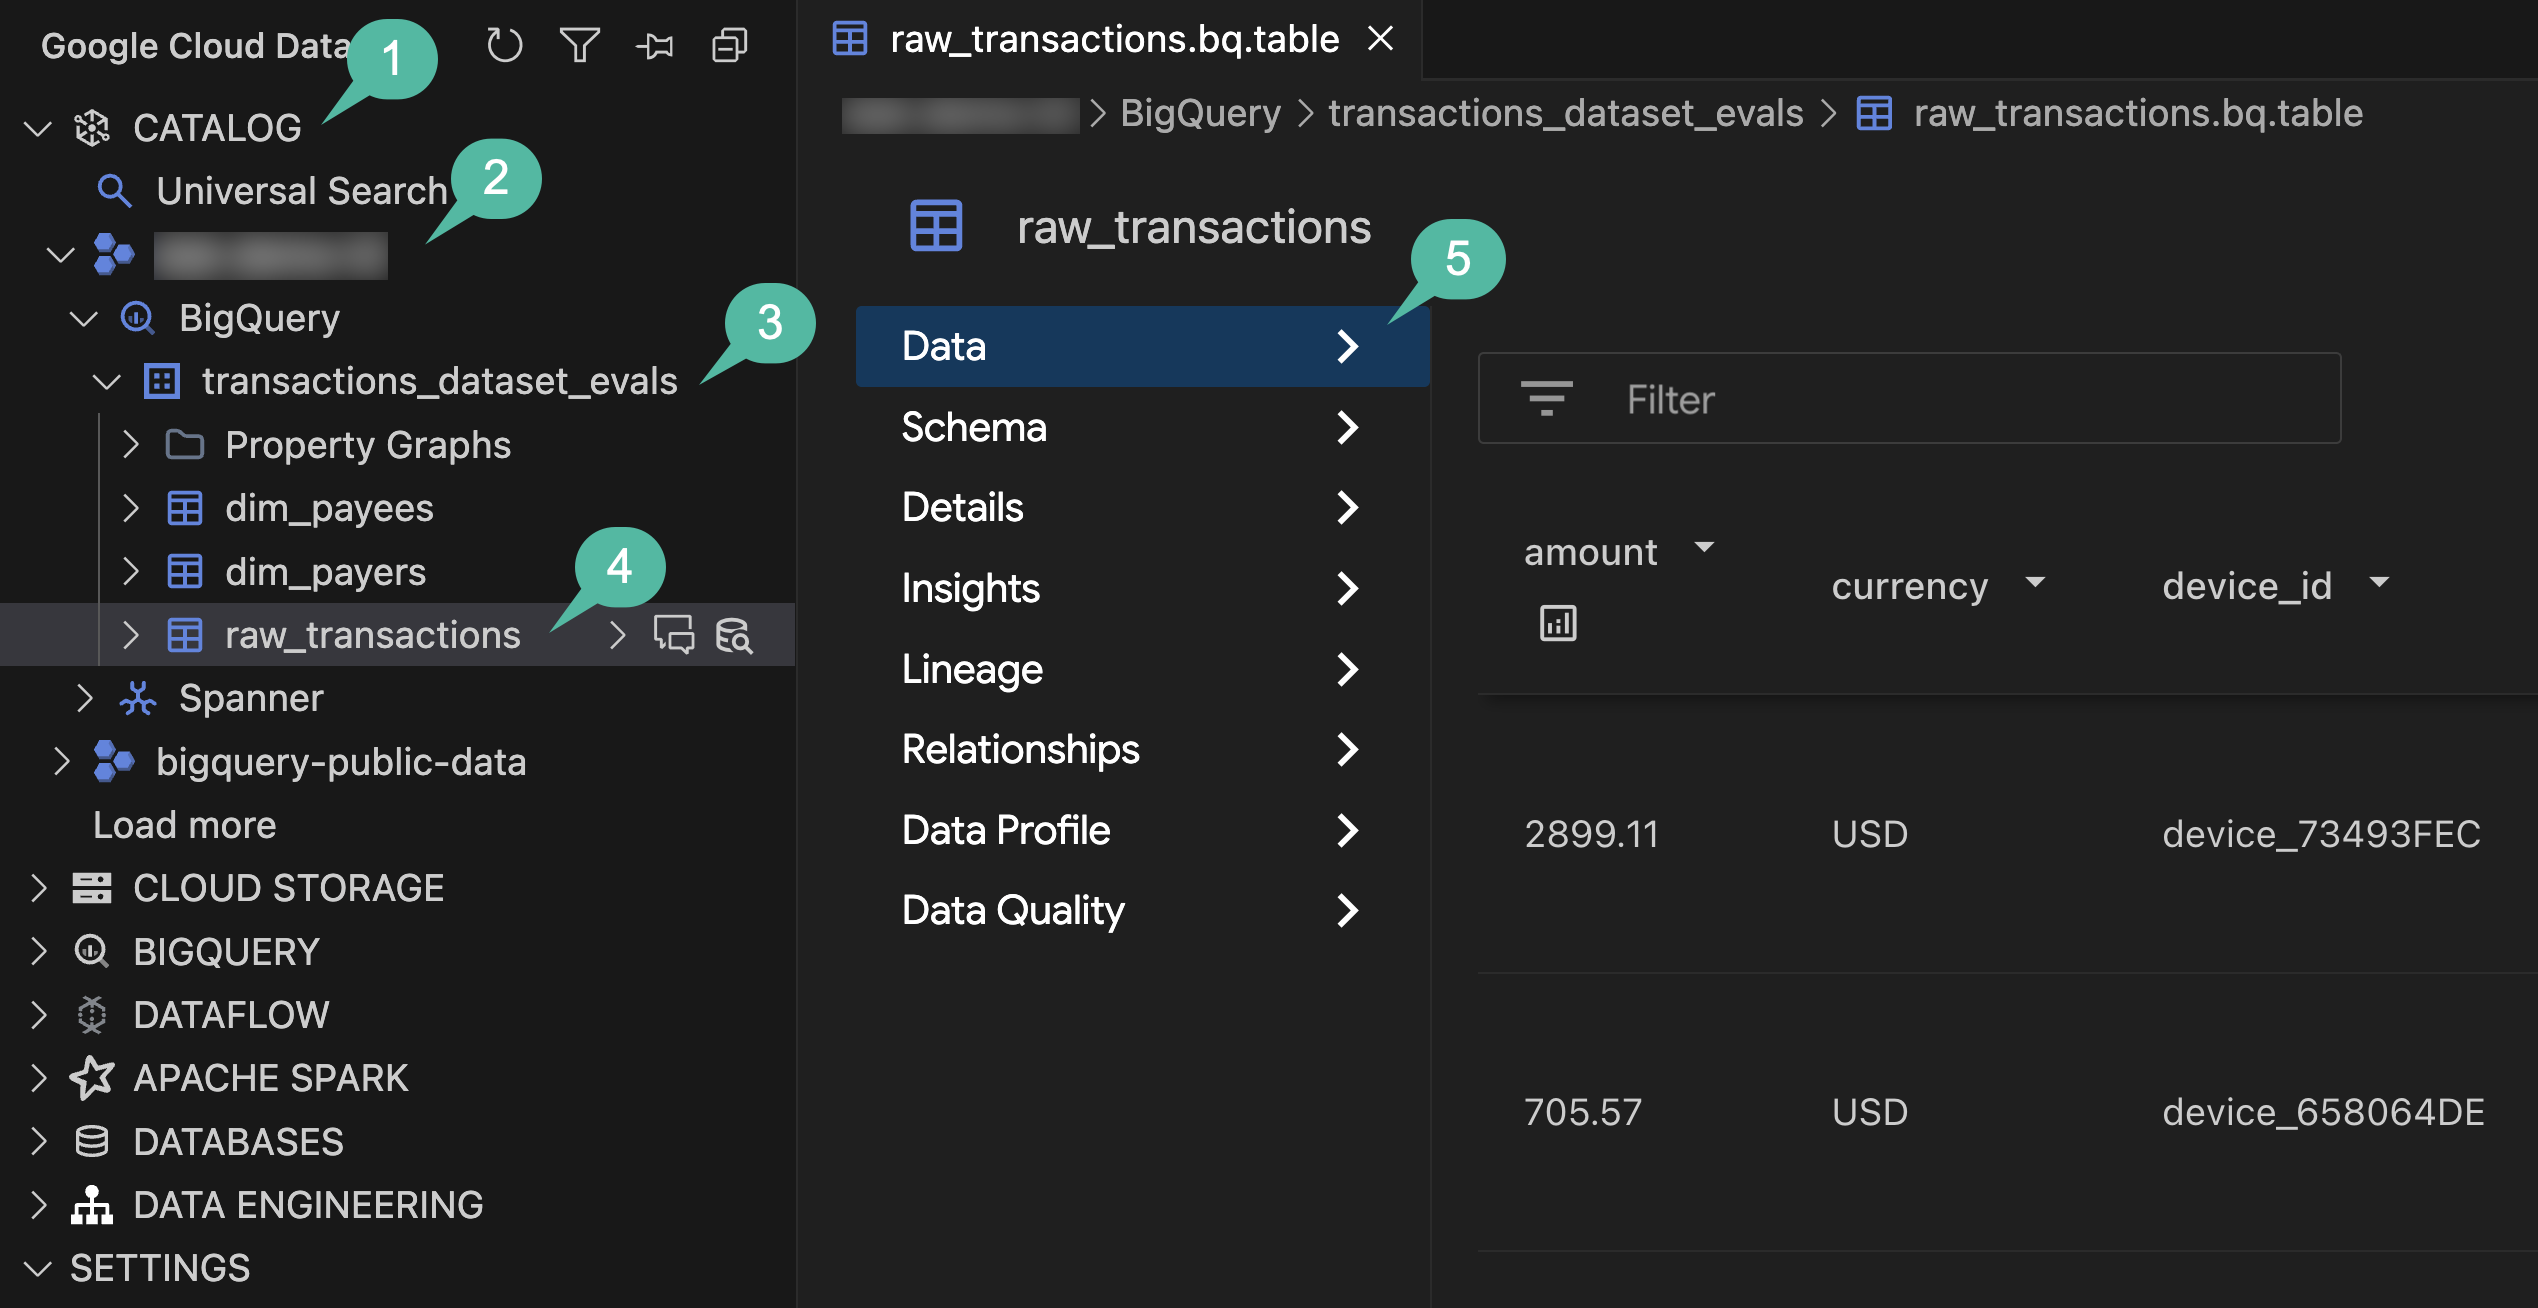
- IDE অ্যাক্টিভিটি বারে, Google Cloud Data Agent Kit প্যানেলটি খুলুন।
- ক্যাটালগ বিভাগটি প্রসারিত করুন।
- আপনার প্রজেক্ট আইডিটি প্রসারিত করুন।
- BigQuery প্রসারিত করুন।
-
transactions_dataset_evalsডেটাসেটটি প্রসারিত করুন। - মূল এডিটরে
raw_transactionsটেবিলের বিস্তারিত ভিউ খুলতে সেটিতে ক্লিক করুন। - বাম দিকের নেভিগেশনে, গৃহীত রেকর্ড এবং মেটাডেটা পরীক্ষা করার জন্য ডেটা , স্কিমা এবং ডিটেইলস ট্যাবগুলো দেখুন।
অধ্যায়ের সারসংক্ষেপ: আপনি এজেন্ট চ্যাটে স্বাভাবিক ভাষা ব্যবহার করে একটি সম্পূর্ণ স্পার্ক সার্ভারলেস ওয়ার্কলোড তৈরি করেছেন। এরপর আপনি অসংগঠিত JSON লগগুলোকে একটি BigQuery (raw) টেবিলে প্রসেস করার জন্য এটি এক্সিকিউট করেছেন।
৪. dbt ব্যবহার করে ডুপ্লিকেট বাদ দিন এবং স্বাভাবিক করুন।
এমএল মডেলকে প্রশিক্ষণ দেওয়ার আগে, আপনি ডুপ্লিকেট স্ট্রিমিং লগগুলি সরিয়ে, ত্রুটিপূর্ণ রেকর্ডগুলি (যেমন খালি ট্রানজ্যাকশন আইডি) আলাদা করে এবং ডাইমেনশনাল ডেটা (প্রদানকারী ও প্রাপক) যুক্ত করার মাধ্যমে ডেটার গুণমান নিশ্চিত করবেন। এই প্রক্রিয়ার জন্য আইডম্পোটেন্ট ও নির্ভরযোগ্য SQL ট্রান্সফরমেশন প্রয়োজন, যার জন্য dbt (ডেটা বিল্ড টুল) একটি চমৎকার সমাধান।
ডিবিটি পাইপলাইনকে কাঠামোবদ্ধ করুন
BigQuery ডেটাসেটের উপর একটি dbt প্রজেক্ট তৈরি করতে এজেন্টটি ব্যবহার করুন:
- এজেন্ট চ্যাট প্যানে ফিরে যান।
- dbt প্রজেক্টটি তৈরি করার জন্য নিম্নলিখিত নির্দেশনা প্রদান করুন:
Scaffold a us-central1 dbt project in dbt_project/ that maps raw_transactions
through to an enriched_transactions model in dataset transactions_dataset_evals.

Deduplicate by transaction_id in staging. Quarantine null IDs to an invalid_transactions model.
Join the valid staging records with dim_payers and dim_payees for the enriched_transactions model,
preserving the historical `is_fraud` label column, and finally add a transaction uniqueness test.

Create an implementation plan first.
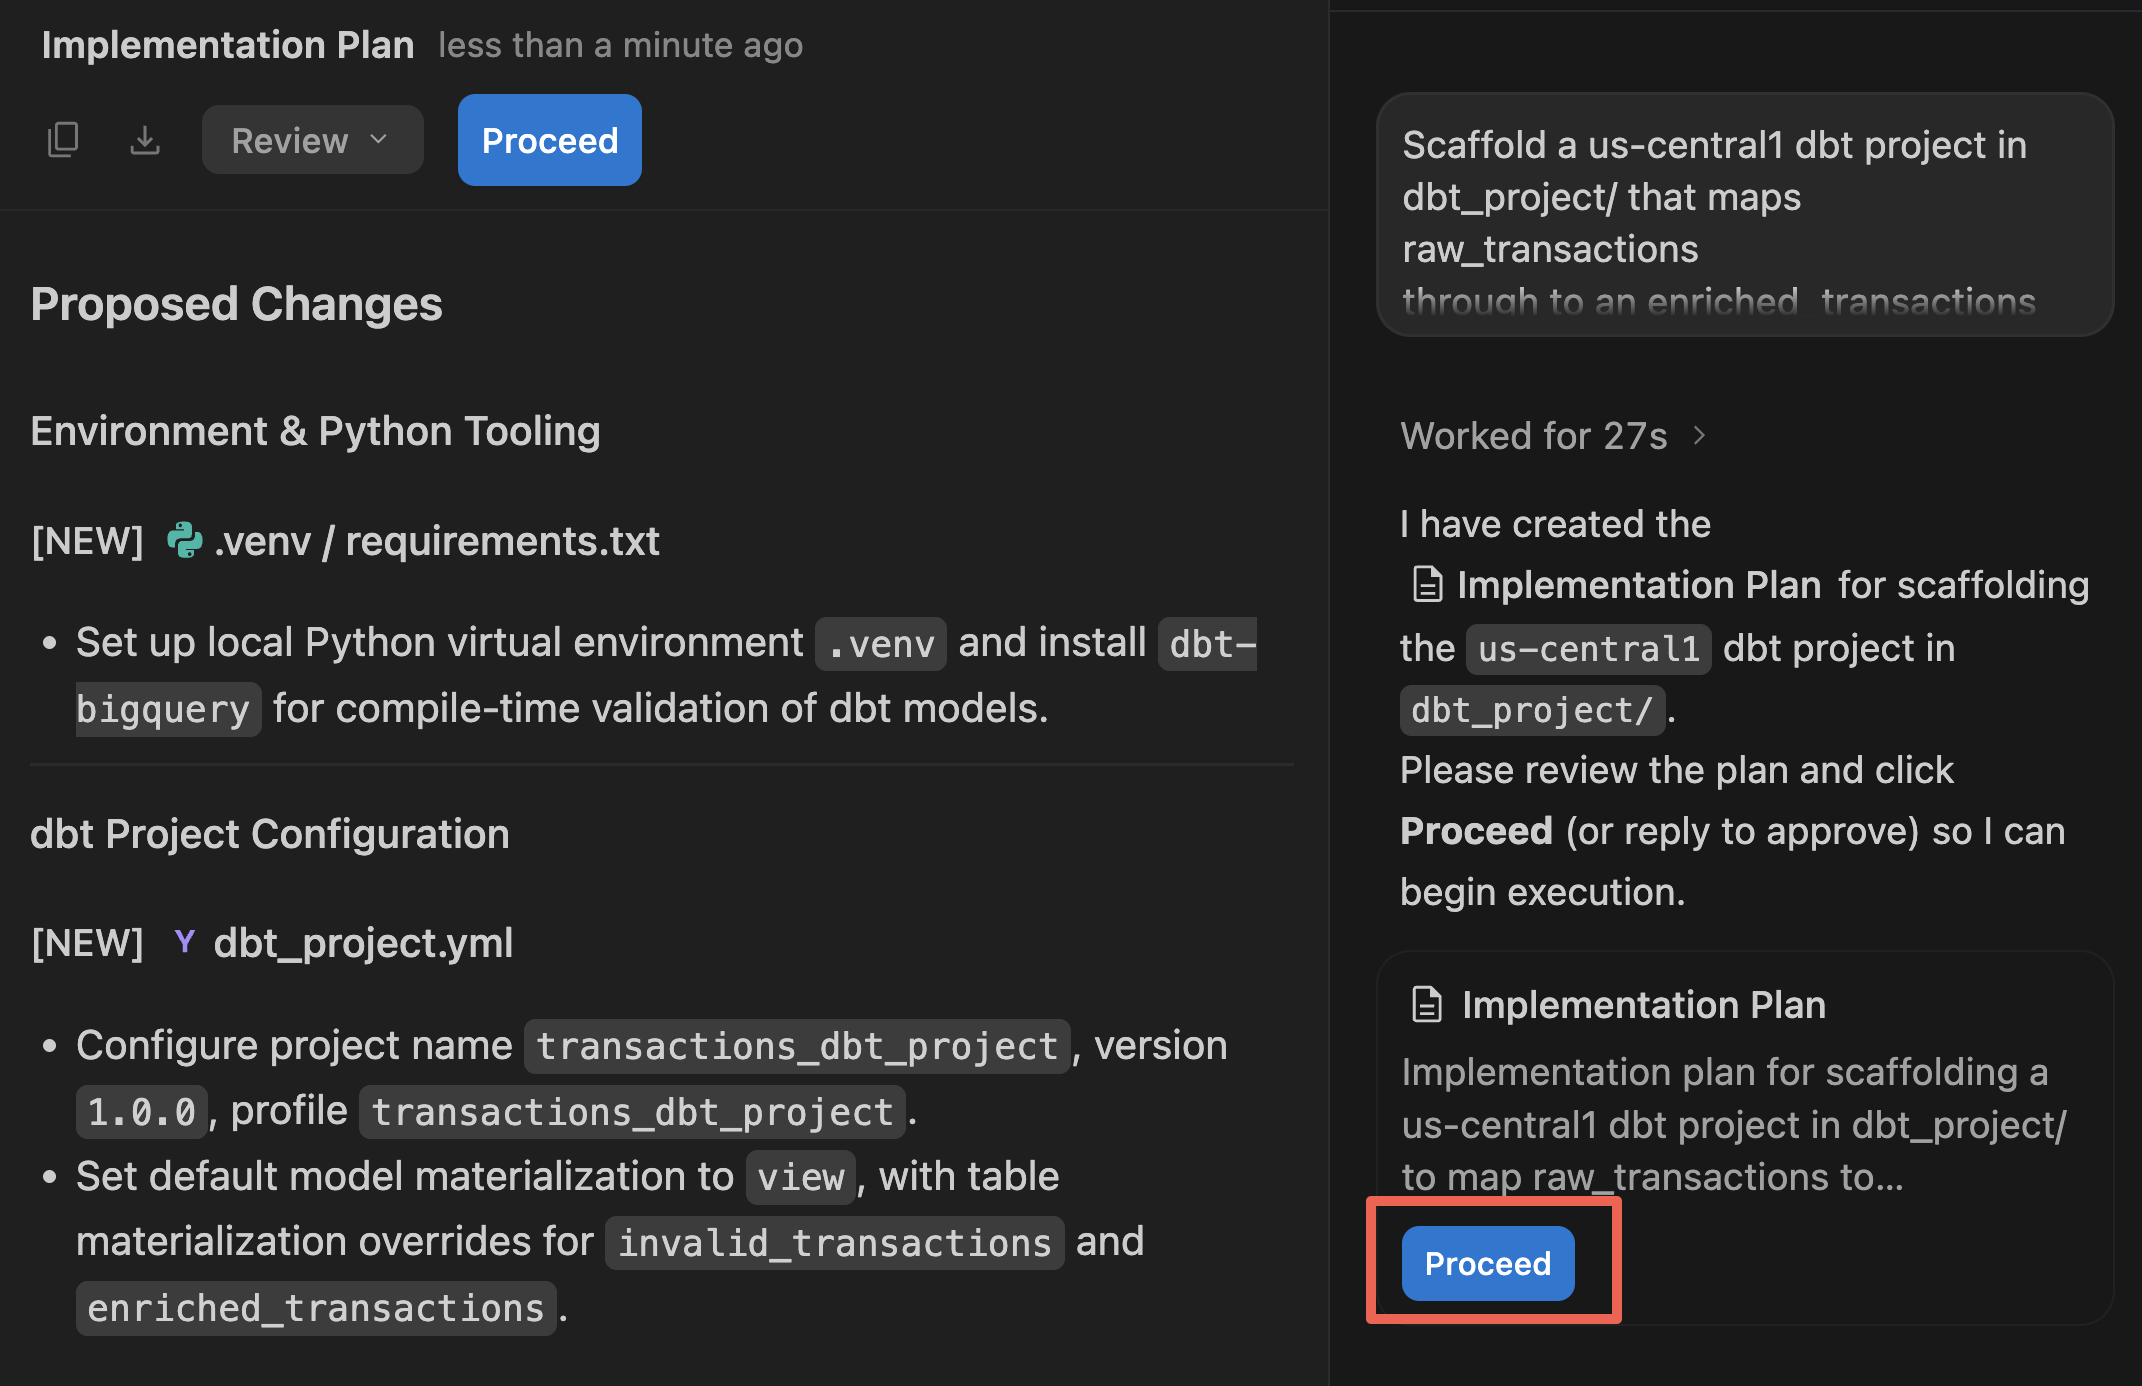
- এজেন্ট মূল এডিটর প্যানে একটি ইমপ্লিমেন্টেশন প্ল্যান আর্টিফ্যাক্ট উপস্থাপন করবে। প্রস্তাবিত ফাইল কাঠামো এবং SQL লজিক পর্যালোচনা করুন।
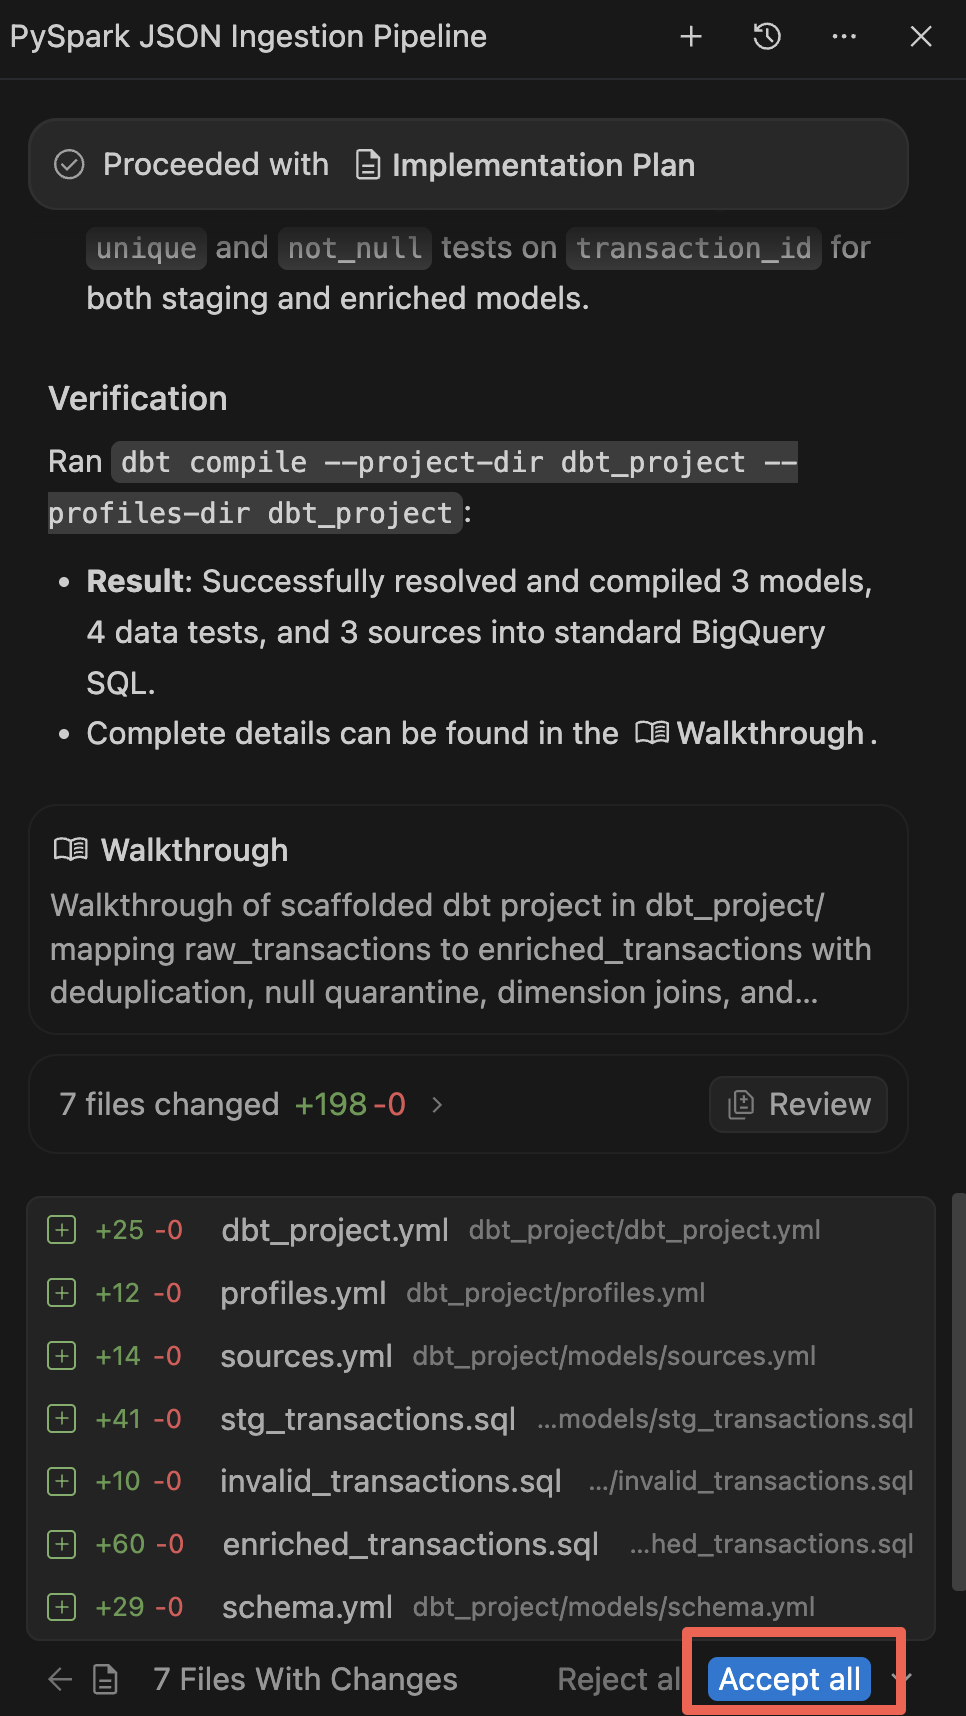
- এজেন্টকে আপনার ওয়ার্কস্পেসে ফাইলগুলো তৈরি করার অনুমতি দিতে 'Proceed' (এবং তারপর 'Accept all ')-এ ক্লিক করুন।
- একবার তৈরি হয়ে গেলে, এজেন্ট নতুন উপাদানগুলোর সারসংক্ষেপসহ একটি ওয়াকথ্রু প্রদর্শন করে। অনুরোধ করা হলে সমস্ত পরিবর্তন গ্রহণ করুন।
তৈরি করুন এবং পরীক্ষা করুন
যদিও এজেন্ট তৈরি হওয়া SQL-টি সিনট্যাক্টিকভাবে বৈধ কিনা তা নিশ্চিত করার জন্য স্বয়ংক্রিয়ভাবে dbt compile চালিয়েছিল, এখন আপনি এই ভিউ এবং টেবিলগুলোকে BigQuery-তে ম্যাটেরিয়ালাইজ করবেন এবং স্থানীয়ভাবে যাচাই করার জন্য ডেটার গুণমান পরীক্ষাগুলো চালাবেন। (দ্রষ্টব্য: ল্যাবের পরবর্তী অংশে, আপনি একটি এন্ড-টু-এন্ড Airflow DAG-এর অংশ হিসেবে এই dbt ধাপটি স্বয়ংক্রিয় করবেন)।
- একেবারে বাম দিকের অ্যাক্টিভিটি বারে, এক্সপ্লোরার আইকনে ক্লিক করুন (অথবা
Cmd/Ctrl+Shift+Eচাপুন)। - তৈরি হওয়া SQL মডেলগুলো দেখতে
dbt_project->modelsপ্রসারিত করুন।enriched_transactions.sqlফাইলটিতে ক্লিক করে এটি খুলুন এবং এডিটরে এর ট্রান্সফরমেশন ও ফ্রড ফিচার লজিক পর্যালোচনা করুন। - ফাইল এক্সপ্লোরারে,
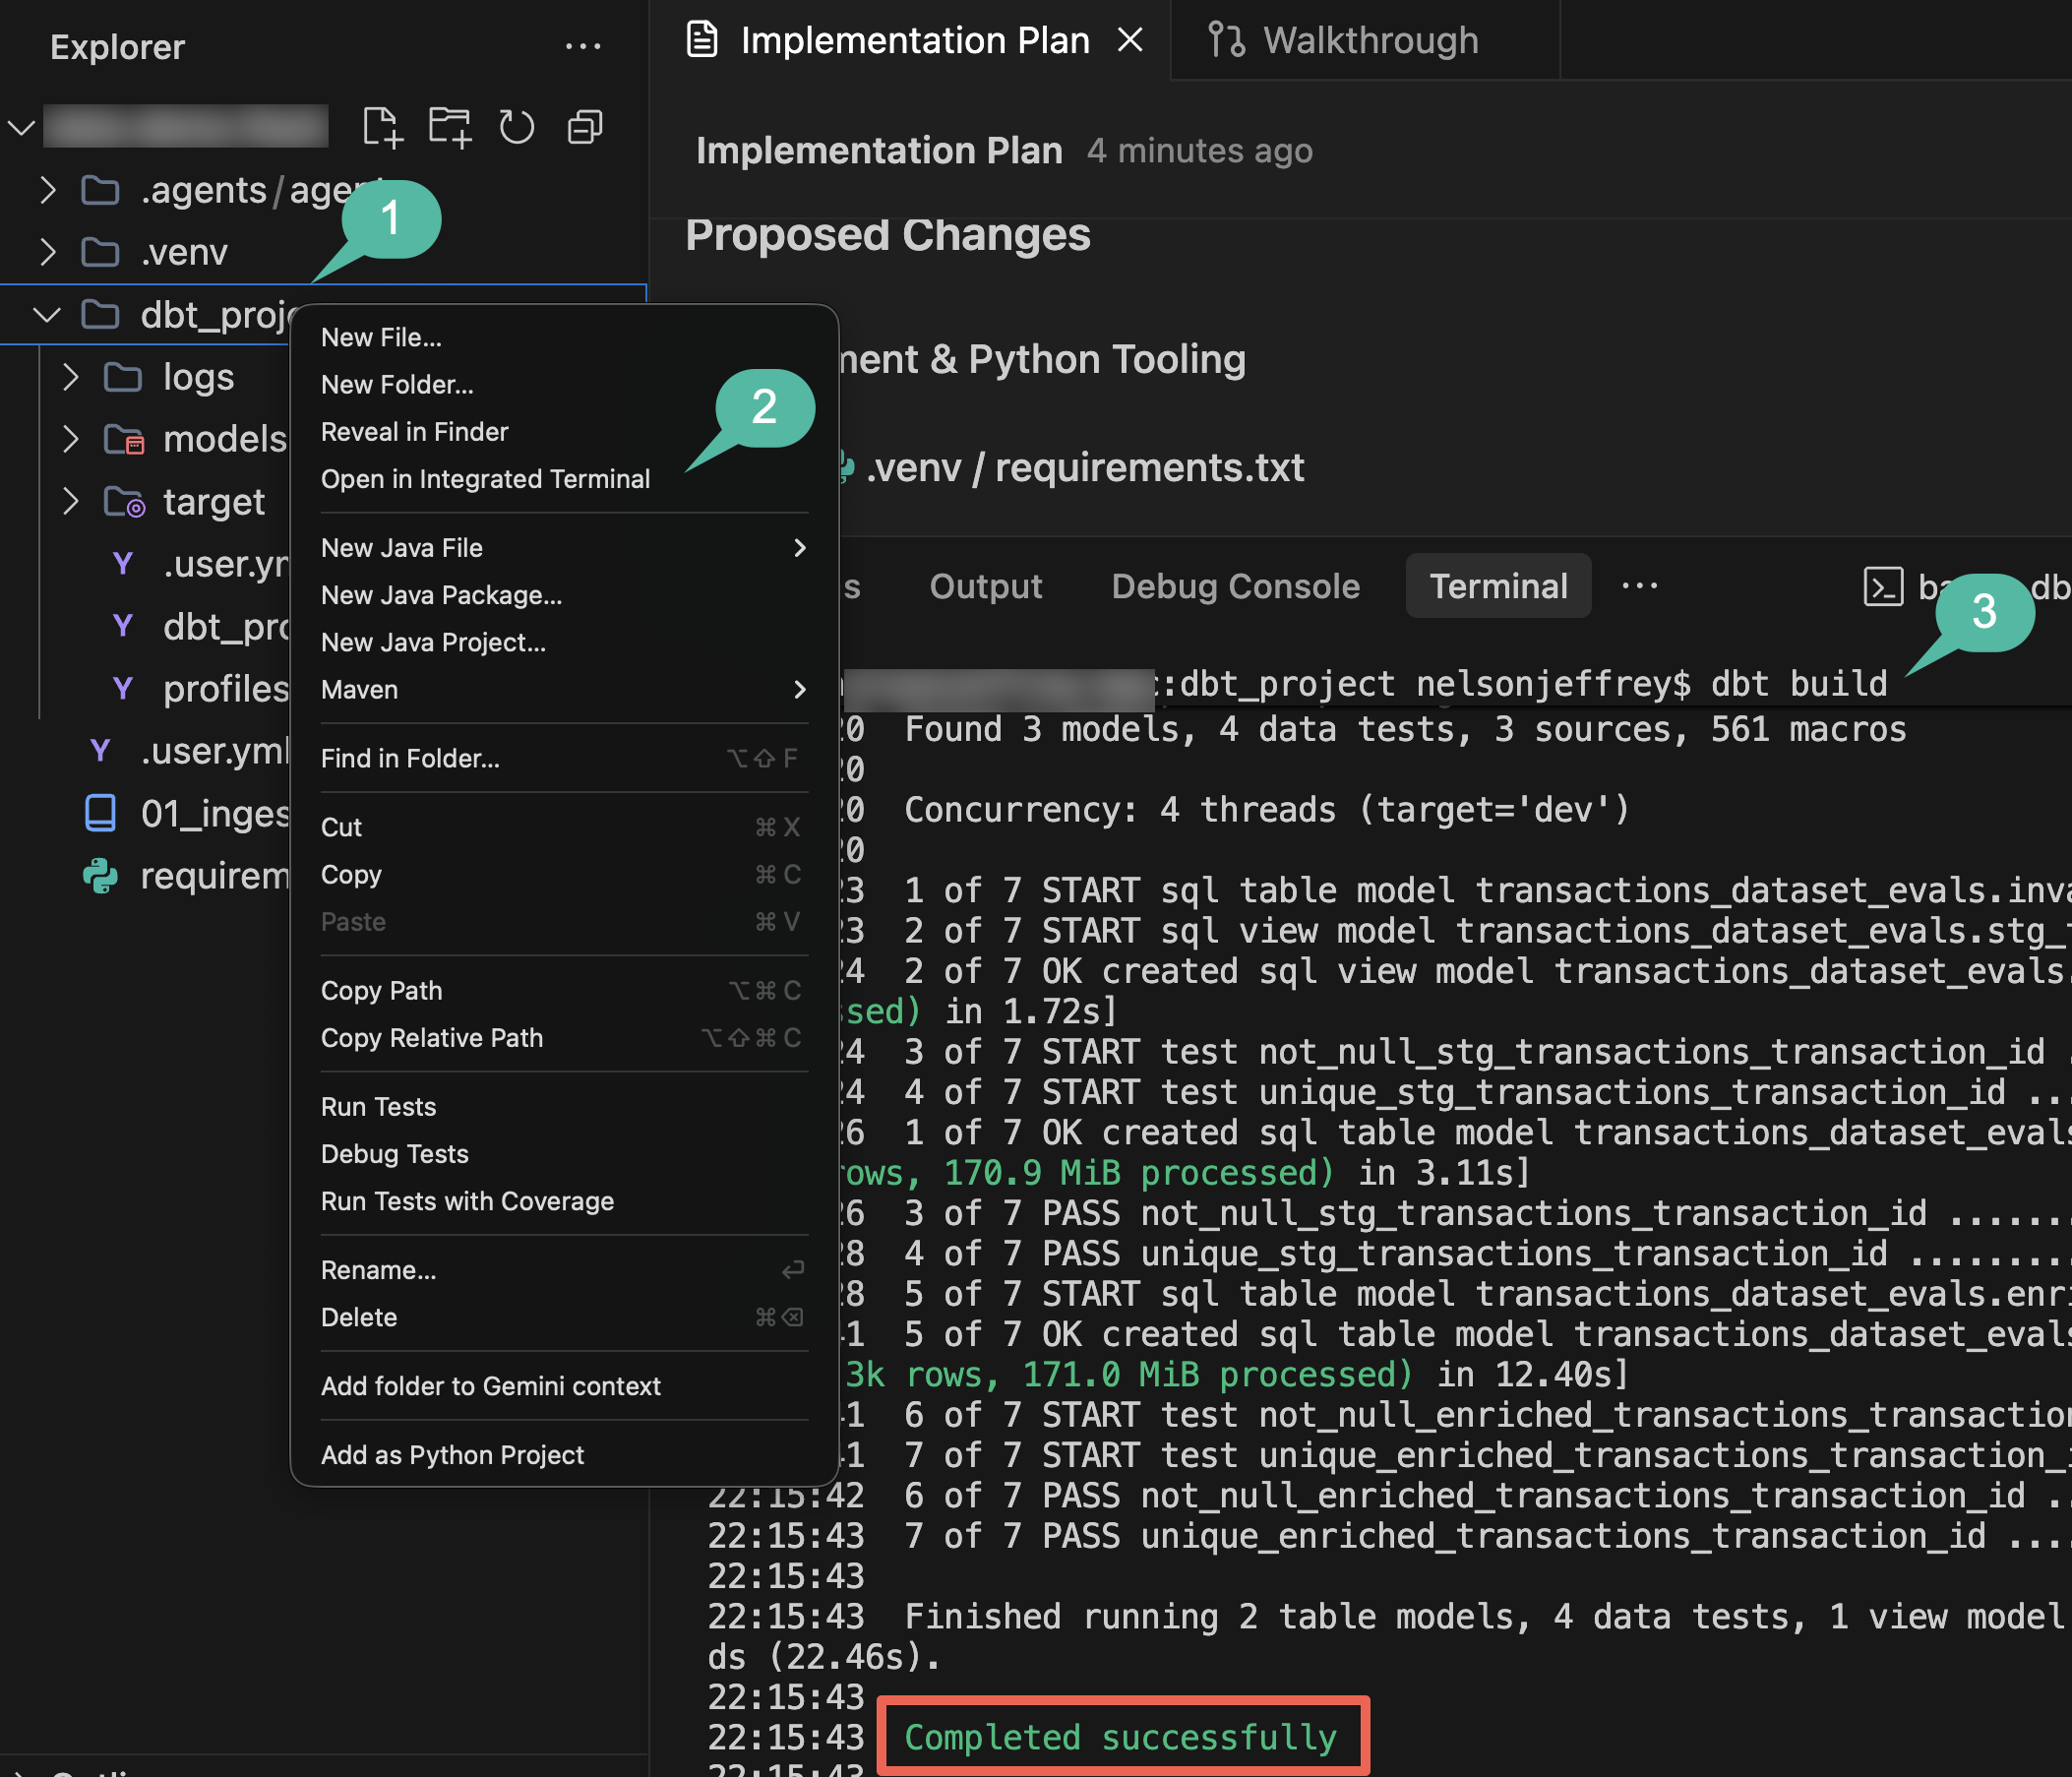
dbt_projectফোল্ডারটির উপর রাইট-ক্লিক করুন এবং ‘Open in Integrated Terminal’ নির্বাচন করুন। এটি স্বয়ংক্রিয়ভাবে একটি টার্মিনাল পেইন খুলে দেবে, যা সরাসরি প্রয়োজনীয়dbt_projectওয়ার্কিং ডিরেক্টরিতে সেট করা থাকবে। - যদি আপনার
dbtআগে থেকে ইনস্টল করা না থাকে, তাহলেdbt_project/বাইরে (আপনার হোম বা ওয়ার্কস্পেস রুটে) একটি ভার্চুয়াল এনভায়রনমেন্ট তৈরি করুন এবং BigQuery অ্যাডাপ্টারটি ইনস্টল করুন:
python3 -m venv ~/.venv/dbt
source ~/.venv/dbt/bin/activate
pip install dbt-bigquery
- dbt মডেলগুলো এবং সেগুলোর সাথে সম্পর্কিত ডেটার গুণমান পরীক্ষাগুলো চালান:
dbt build
- টার্মিনাল আউটপুটটি লক্ষ্য করুন। dbt SQL কম্পাইল করবে, BigQuery-তে স্টেজিং ও এনরিচড টেবিলগুলোকে ম্যাটেরিয়ালাইজ করবে এবং ডেটা টেস্টগুলো সম্পাদন করবে।
- বিল্ড শেষ হয়ে গেলে, বাকি ধাপগুলোর জন্য স্ক্রিনে জায়গা খালি করতে টার্মিনাল পেইনটি বন্ধ করে দিন।
অধ্যায়ের পুনরালোচনা: আপনি এজেন্টের সাহায্যে একটি dbt প্রজেক্ট তৈরি করেছেন, ডেটার গুণমান পরীক্ষা চালিয়েছেন এবং কাঁচা রেকর্ডগুলোকে স্টেজিং ও এনরিচড BigQuery টেবিলে রূপান্তর করেছেন।
৫. র্যান্ডম ফরেস্ট ব্যবহার করে ডিস্ট্রিবিউটেড জালিয়াতি সনাক্তকরণ মডেলকে প্রশিক্ষণ দিন।
BigQuery-তে প্রাপ্ত সমৃদ্ধ লেনদেনগুলো ব্যবহার করে, আপনি জালিয়াতিপূর্ণ ঘটনাগুলোকে শ্রেণীবদ্ধ করার জন্য একটি মেশিন লার্নিং মডেল তৈরি করবেন। Random Forest হলো একটি এনসেম্বল লার্নিং পদ্ধতি যা সারণিভিত্তিক শ্রেণীবিন্যাস ডেটার জন্য বিশেষভাবে উপযুক্ত। Spark Serverless-এ RandomForestClassifier চালালে, আপনাকে পরিকাঠামো পরিচালনা করার প্রয়োজন ছাড়াই ওয়ার্কার নোডগুলোর মধ্যে মডেল প্রশিক্ষণ বন্টন করা হয়।
এই ধাপে, আপনি এজেন্টটি ব্যবহার করে স্পার্ক এমএল ট্রেনিং পাইপলাইন তৈরি করবেন।
এমএল প্রশিক্ষণ নোটবুকটি তৈরি করুন
- এজেন্ট চ্যাট প্যানেটি খুলুন।
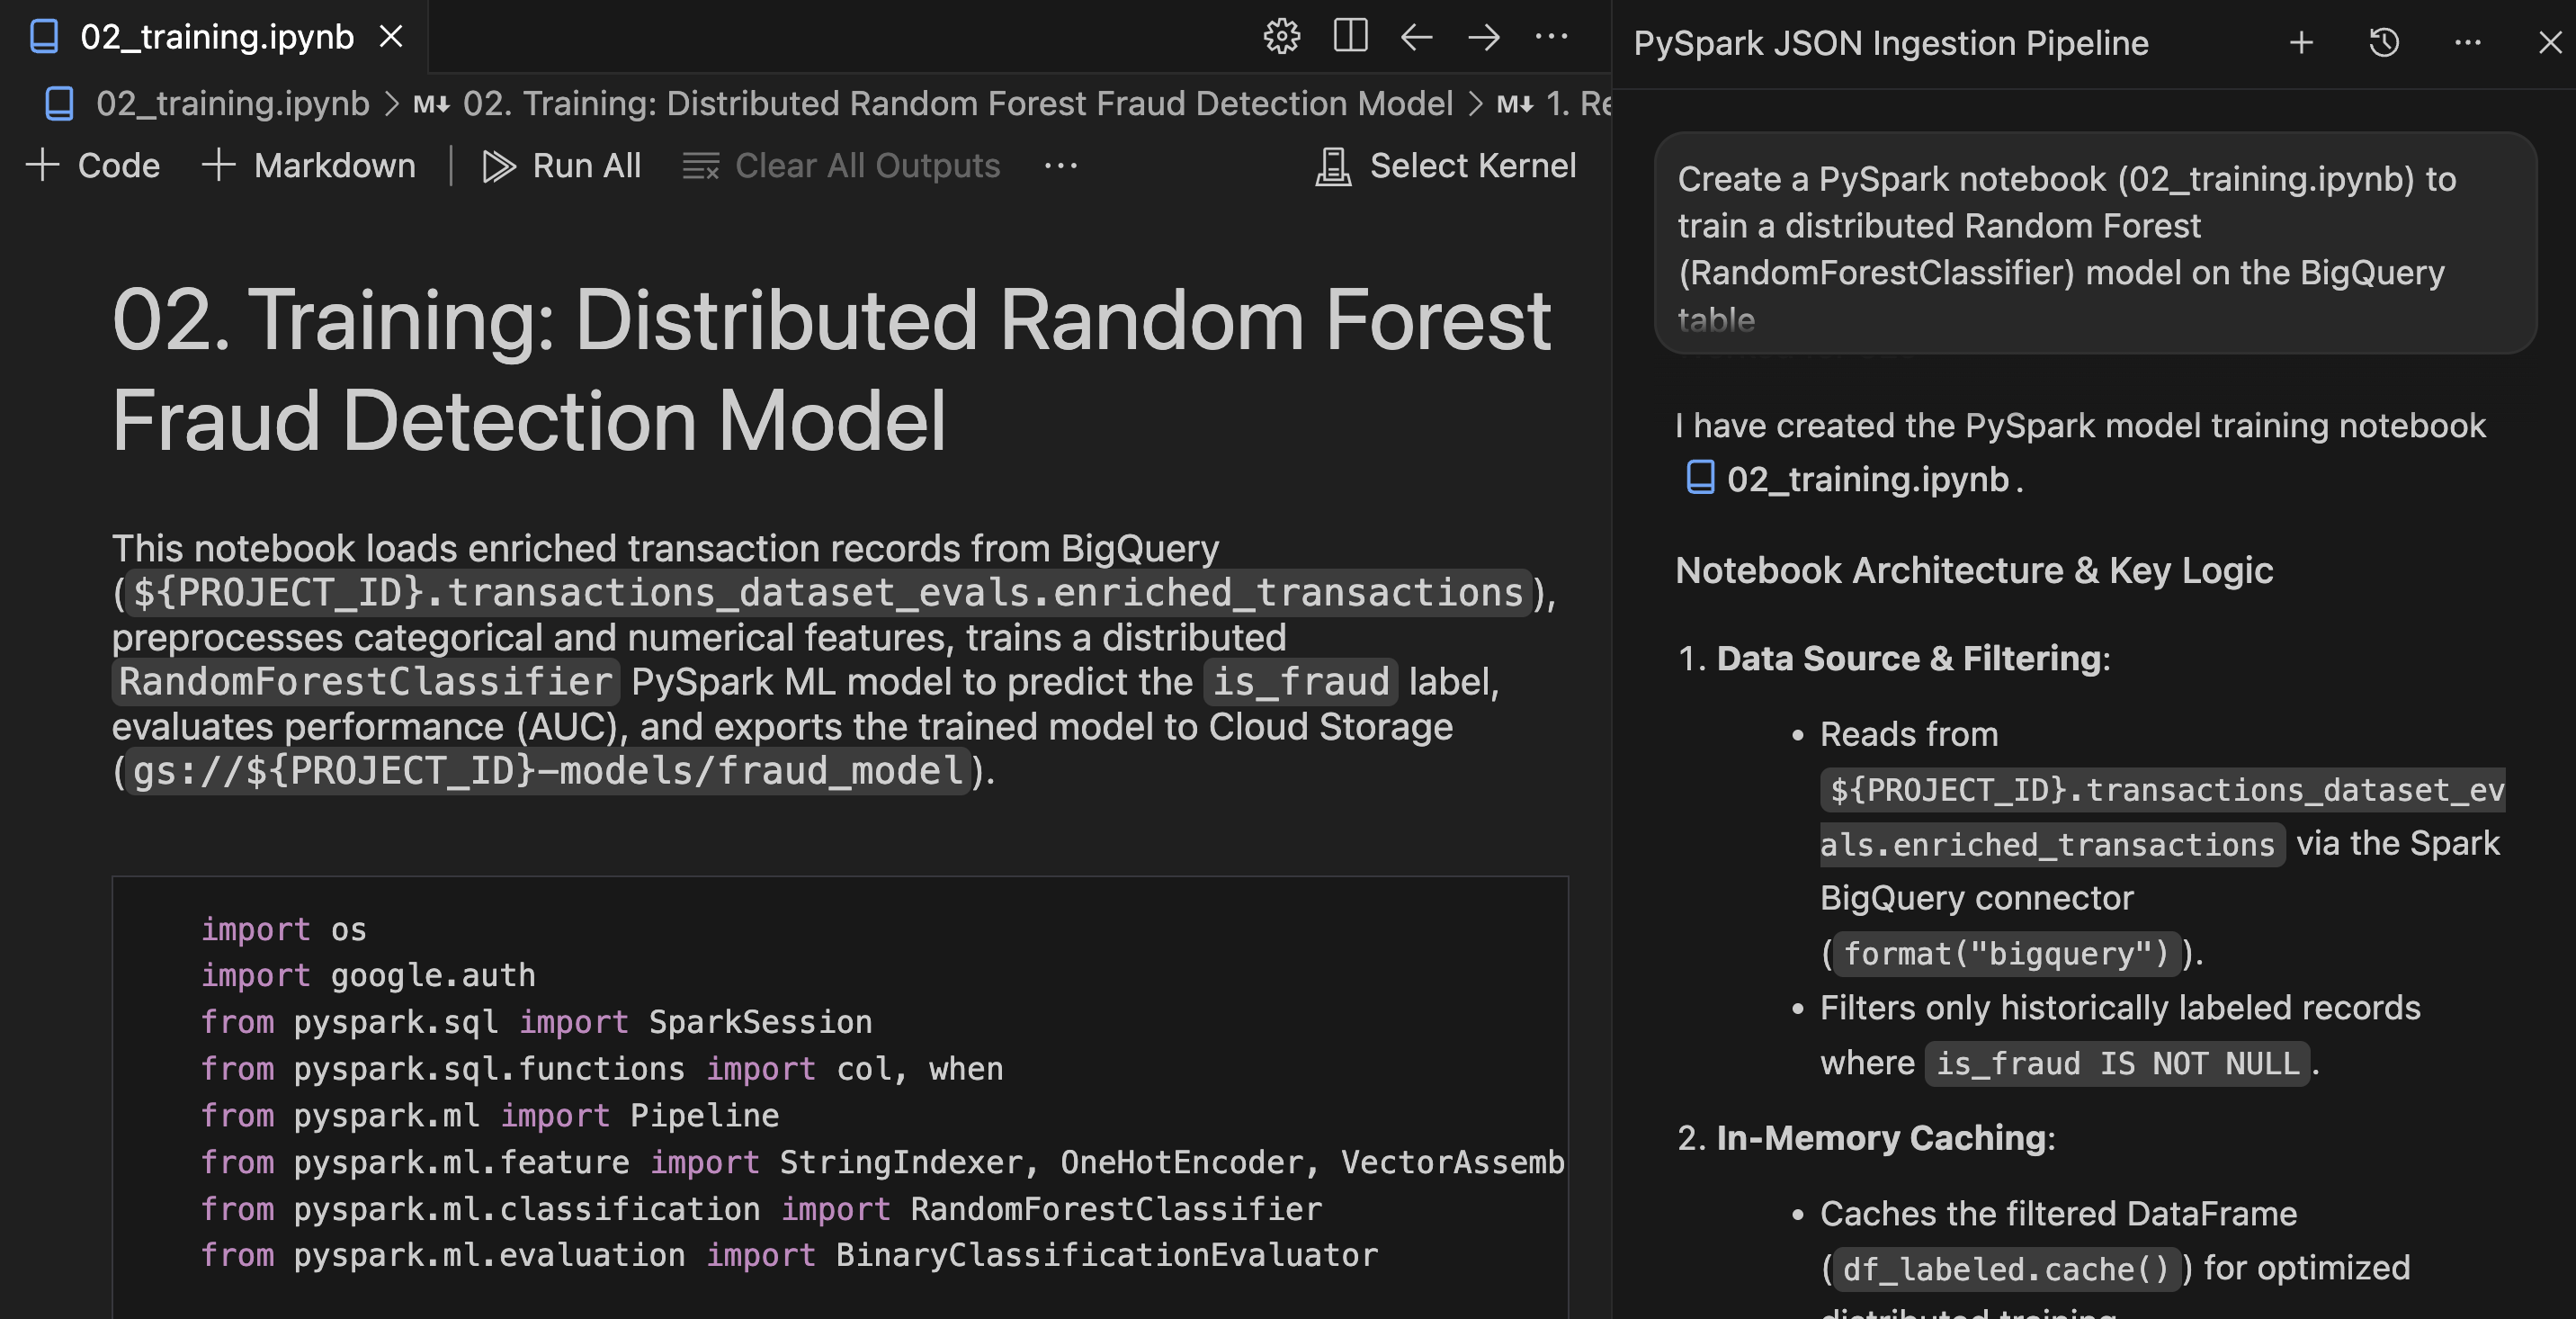
- মডেল প্রশিক্ষণ ক্রম ডিজাইন করার জন্য নিম্নলিখিত প্রম্পটটি প্রদান করুন (মনে রাখবেন,
${PROJECT_ID}এর জায়গায় আপনার সক্রিয় প্রজেক্ট আইডি বসাতে হবে):
Create a PySpark notebook (02_training.ipynb) to train a distributed Random Forest
(RandomForestClassifier) model on the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`, predicting the `is_fraud` label.
Train only on historically labeled records where `is_fraud` is not null.

One-hot encode categorical strings, scale amounts, cache the dataset in memory,
evaluate AUC, and save the evaluated model to gs://${PROJECT_ID}-models/fraud_model.
- এজেন্টের পরিকল্পনা বা তৈরি করা কোড পর্যালোচনা করুন এবং আপনার ওয়ার্কস্পেসে
notebooks/02_training.ipynbসংরক্ষণ করতে Proceed / Accept all-এ ক্লিক করুন।
নোটবুকটি পর্যালোচনা করুন এবং কার্যকর করুন।
- এডিটরে
notebooks/02_training.ipynbখুলুন। - ফিচার এনকোডিং, ভেক্টর অ্যাসেম্বলি এবং র্যান্ডম ফরেস্ট ক্লাসিফিকেশন লজিকের জন্য পাইস্পার্ক এমএল পাইপলাইনের পর্যায়গুলো পর্যালোচনা করুন।
- IDE-এর নোটবুক টুলবারে থাকা 'Run All'- এ ক্লিক করুন।
- যখন সিলেক্ট কার্নেল ড্রপডাউন পিকারটি খুলবে, তখন সার্ভারলেস স্পার্ক-এ ফ্রড-পাইপলাইন-রানটাইম নির্বাচন করুন।
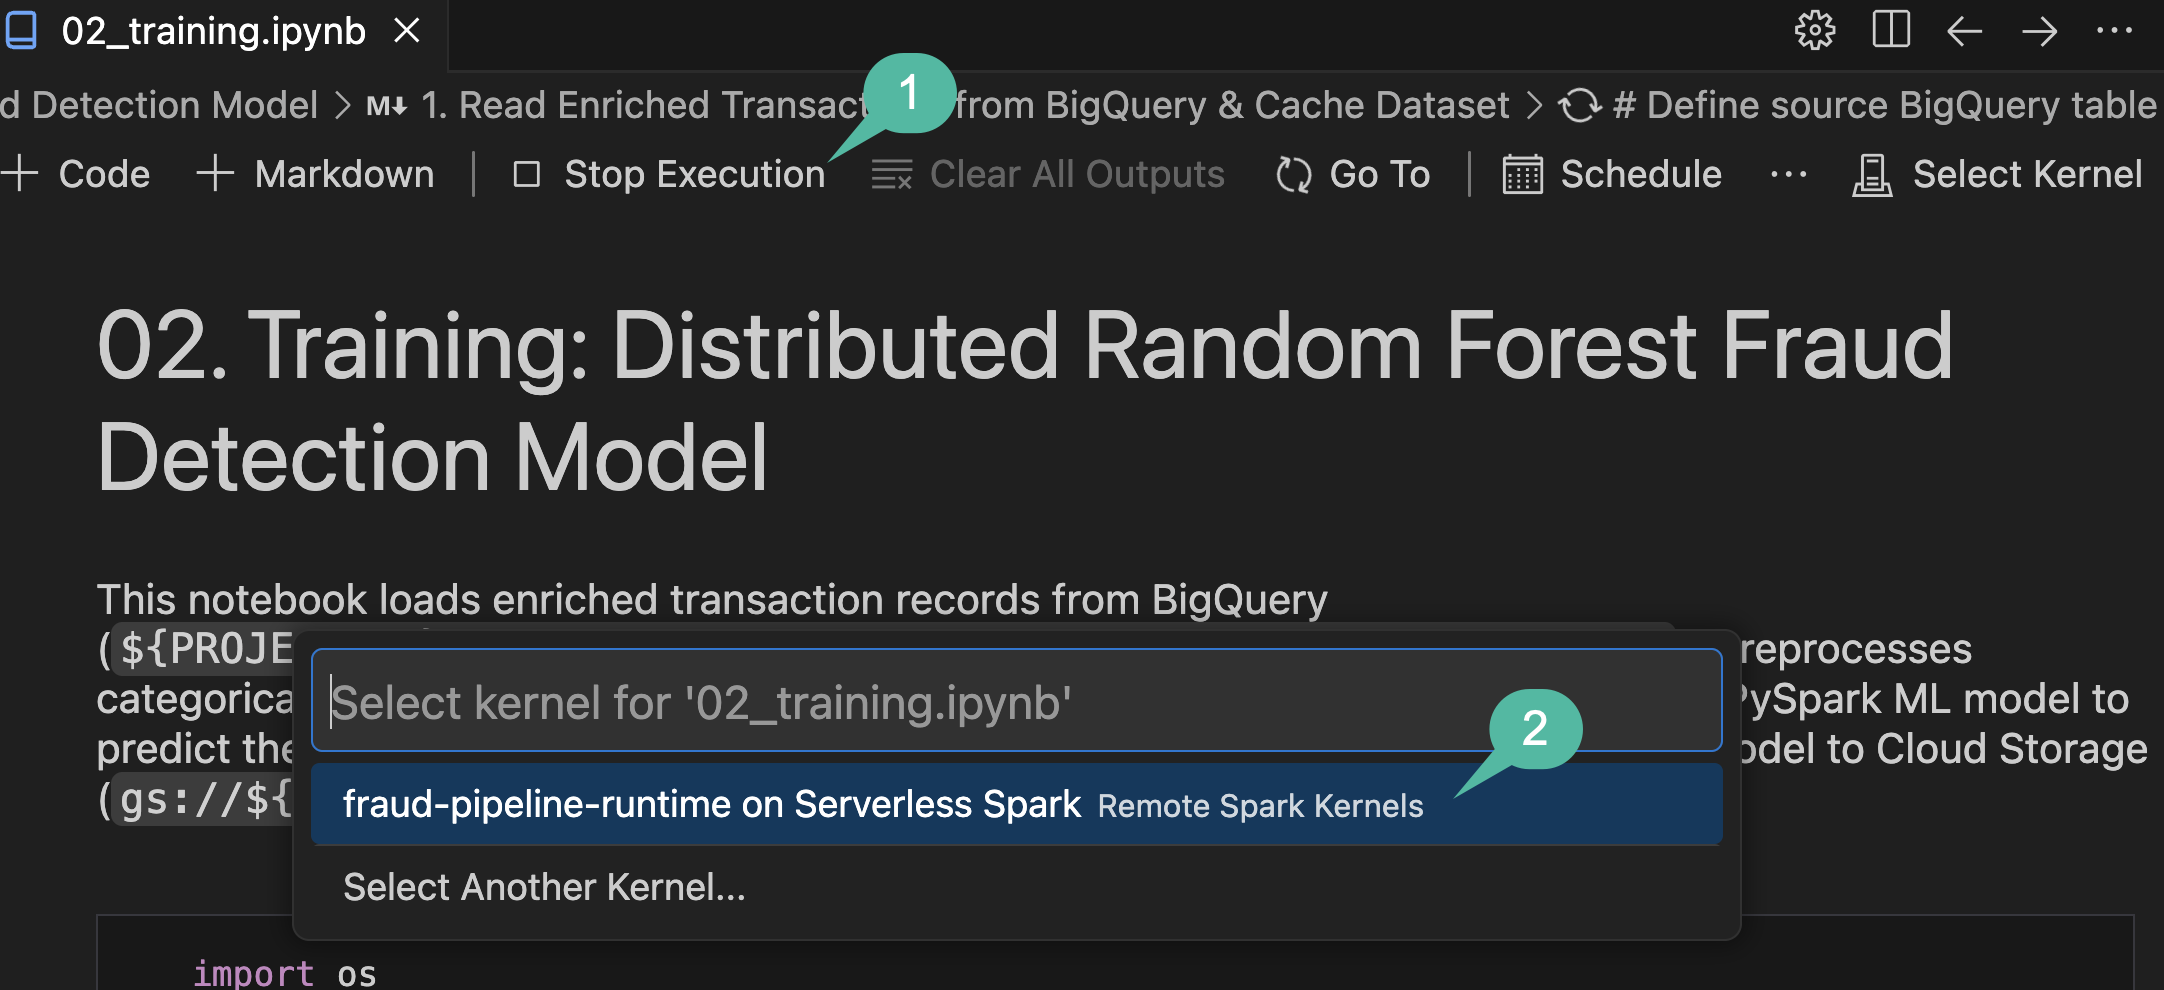
যাচাইকরণ
এক্সিকিউশন সম্পন্ন হলে, মডেলটি সঠিকভাবে প্রশিক্ষিত এবং এক্সপোর্ট করা হয়েছে কিনা তা নিশ্চিত করুন:
- রিপোর্ট করা Area Under ROC (AUC) স্কোর যাচাই করার জন্য নোটবুকের নিচের দিকের মূল্যায়ন সেলের আউটপুটগুলো পর্যালোচনা করুন।
- মডেল আর্টিফ্যাক্টগুলো GCS-এ সফলভাবে সেভ হয়েছে কিনা তা নিশ্চিত করতে, ডেটা এজেন্ট কিট সাইডবারে থাকা স্টোরেজ এক্সপ্লোরার প্যানেটি এক্সপ্যান্ড করুন।
-
-modelsদিয়ে শেষ হওয়া (আপনার সক্রিয় প্রজেক্ট আইডির সাথে যুক্ত) বাকেটটি খুঁজুন, সেটিকে এক্সপ্যান্ড করুন এবং এর ভেতরে গিয়েfraud_modelডিরেক্টরি ও তার পাইপলাইন স্টেজগুলোর অস্তিত্ব যাচাই করুন।
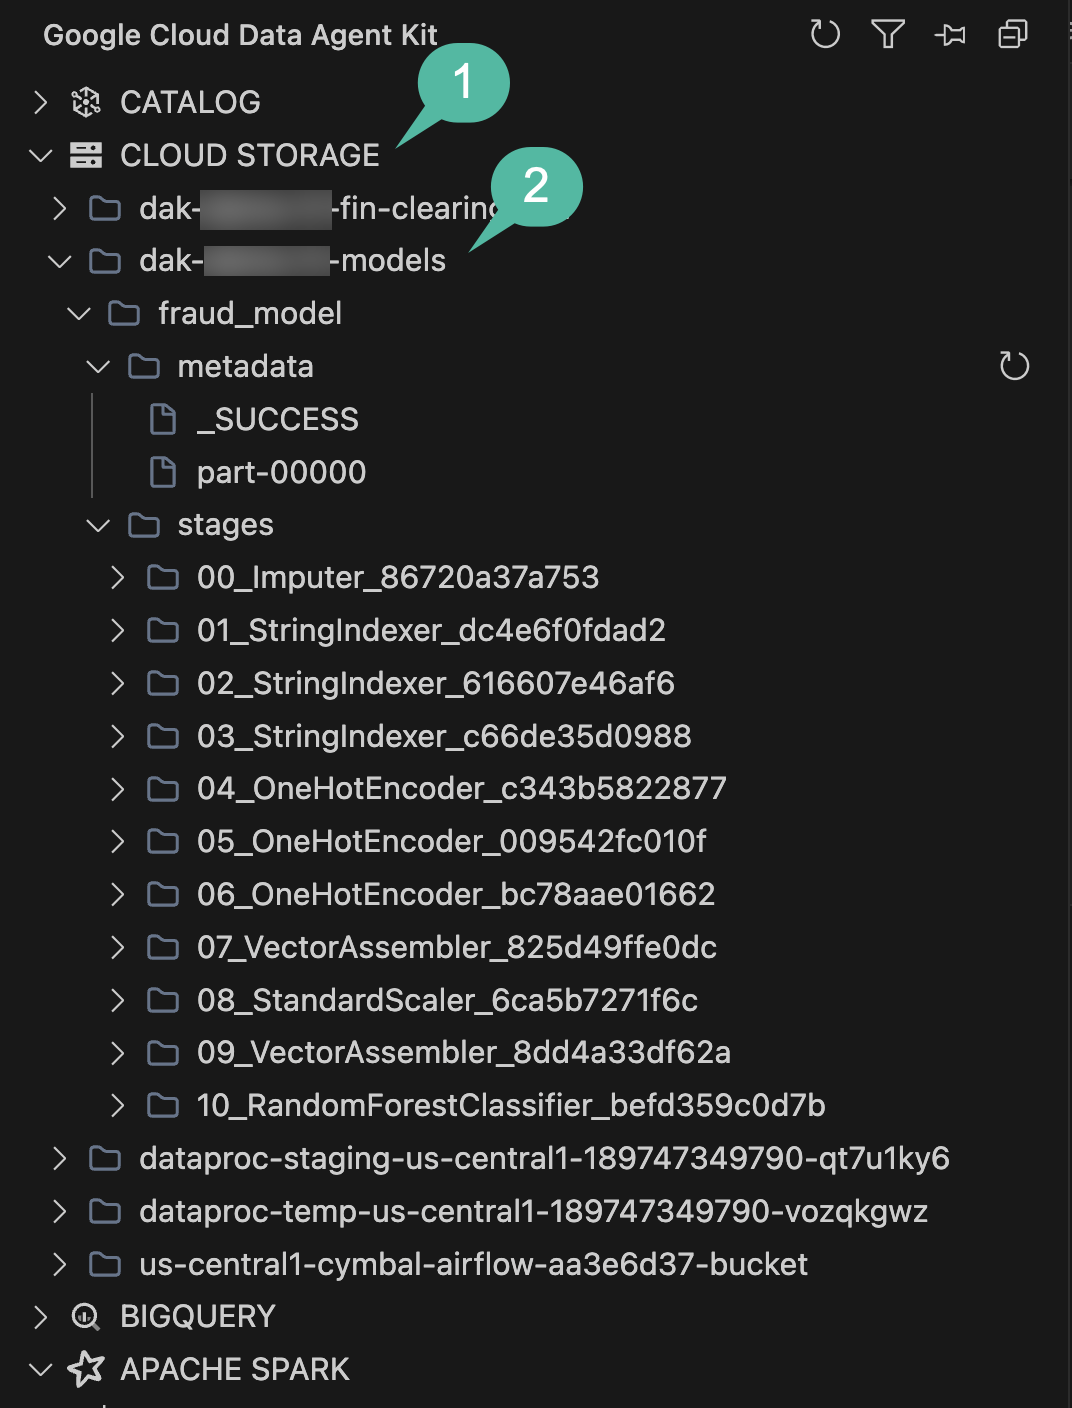
অধ্যায়ের পুনরালোচনা: আপনি এজেন্ট ব্যবহার করে একটি PySpark ML ট্রেনিং পাইপলাইন তৈরি করেছেন, আপনার এনরিচড BigQuery টেবিলের উপর একটি Random Forest মডেলকে ট্রেইন করেছেন এবং মডেলটিকে ক্লাউড স্টোরেজে এক্সপোর্ট করেছেন।
৬. ব্যাচ ইনফারেন্স এবং ক্লাউড স্প্যানার রাইট
ক্লাউড স্টোরেজে সংরক্ষিত একটি প্রশিক্ষিত ভবিষ্যদ্বাণীমূলক মডেলের সাহায্যে, আপনি BigQuery-এর মাধ্যমে প্রবাহিত নতুন লেনদেনগুলিতে ব্যাচ ইনফারেন্স চালাবেন। উচ্চ-ঝুঁকিপূর্ণ লেনদেনগুলিকে একটি অপারেশনাল সিস্টেমে পাঠানো প্রয়োজন, যাতে একটি কমপ্লায়েন্স টিম সেগুলি পর্যালোচনা করতে পারে। ক্লাউড স্প্যানার এই পর্যালোচনা সারির জন্য একটি স্কেলেবল ট্রানজ্যাকশনাল ডেটাবেস সরবরাহ করে।
ব্যাচ ইনফারেন্স নোটবুক তৈরি করুন
BigQuery, Cloud Storage, এবং Cloud Spanner সংযোগ করে একটি ইনফারেন্স নোটবুক তৈরি করতে এজেন্টটি ব্যবহার করুন:
- এজেন্ট চ্যাট প্যানেটি খুলুন।
- নিম্নলিখিত নির্দেশটি প্রদান করুন:
Create an inference notebook (03_inference.ipynb) that loads the RandomForestClassifier
model to score unlabeled records (where `is_fraud` is null) from the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`.

Filter for high-risk transactions with a 50%+ fraud probability score (probability >= 0.50)
and write them to the Cloud Spanner table SparkEvalFraudReviewQueue in the cymbal-fraud instance
under fraud-db.
- আপনার ওয়ার্কস্পেসে
notebooks/03_inference.ipynbসংরক্ষণ করতে তৈরি হওয়া নোটবুকটি গ্রহণ করুন।
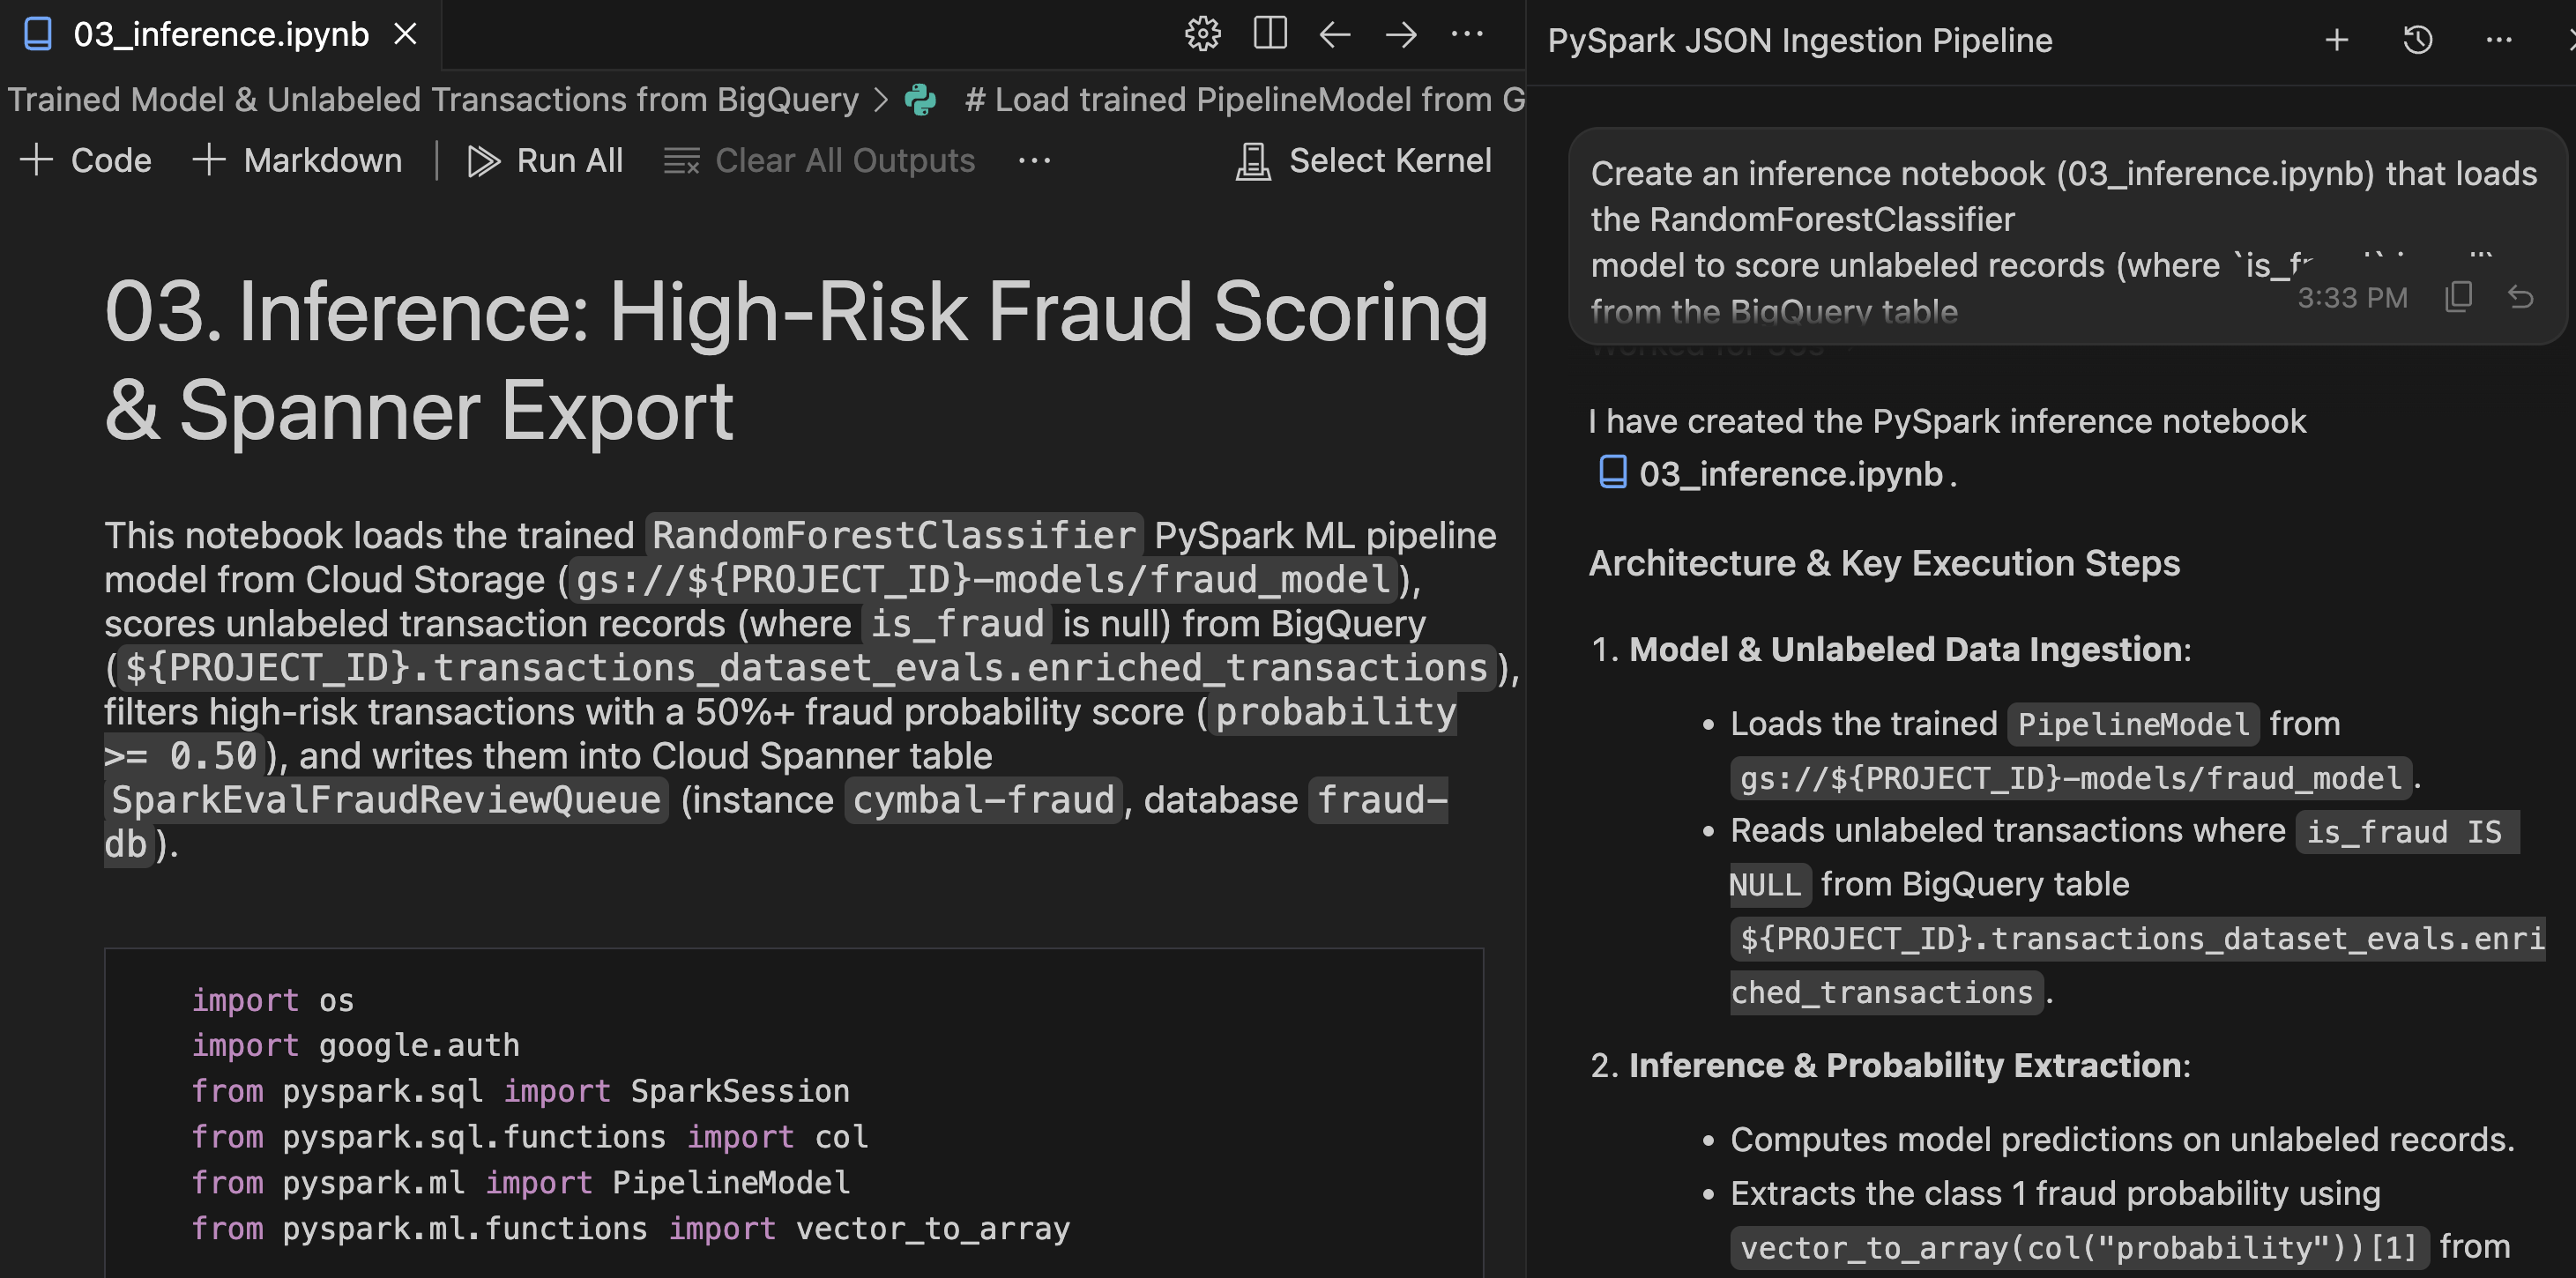
নোটবুকটি পর্যালোচনা করুন এবং কার্যকর করুন।
- এডিটরে নতুন তৈরি হওয়া
notebooks/03_inference.ipynbফাইলটি খুলুন। - PySpark ইনফারেন্স সিকোয়েন্স পর্যালোচনা করুন:
- নির্ভরতা: সার্ভারলেস রানটাইম টেমপ্লেটটি স্পার্ক এক্সিকিউশনের জন্য প্রয়োজনীয়
cloud-spannerJAR নির্ভরতা সরবরাহ করে। - ডেটা ফরম্যাটিং: স্প্যানার টেবিলের স্কিমার সাথে মেলানোর জন্য, স্ক্রিপ্টটি লেখার আগে জটিল স্পার্ক এমএল ভেক্টর কলামগুলো (যেমন র ফিচার এবং প্রোবাবিলিটি) বাদ দেয়।
- স্প্যানার কানেক্টর: এটি
.format("cloud-spanner")ব্যবহার করে ফ্ল্যাগ করা সারিগুলোকে সরাসরি রিভিউ কিউতে যুক্ত করে।
- নির্ভরতা: সার্ভারলেস রানটাইম টেমপ্লেটটি স্পার্ক এক্সিকিউশনের জন্য প্রয়োজনীয়
- IDE-এর নোটবুক টুলবারে থাকা 'Run All'- এ ক্লিক করুন।
- কার্নেল নির্বাচন করতে বলা হলে, Serverless Spark-এ fraud-pipeline-runtime নির্বাচন করুন।
যাচাইকরণ
ইনফারেন্স নোটবুকটির প্রসেসিং শেষ হয়ে গেলে, আপনি সরাসরি IDE-এর ভেতরে আপনার অপারেশনাল স্প্যানার ডাটাবেসে কোয়েরি করতে পারবেন:
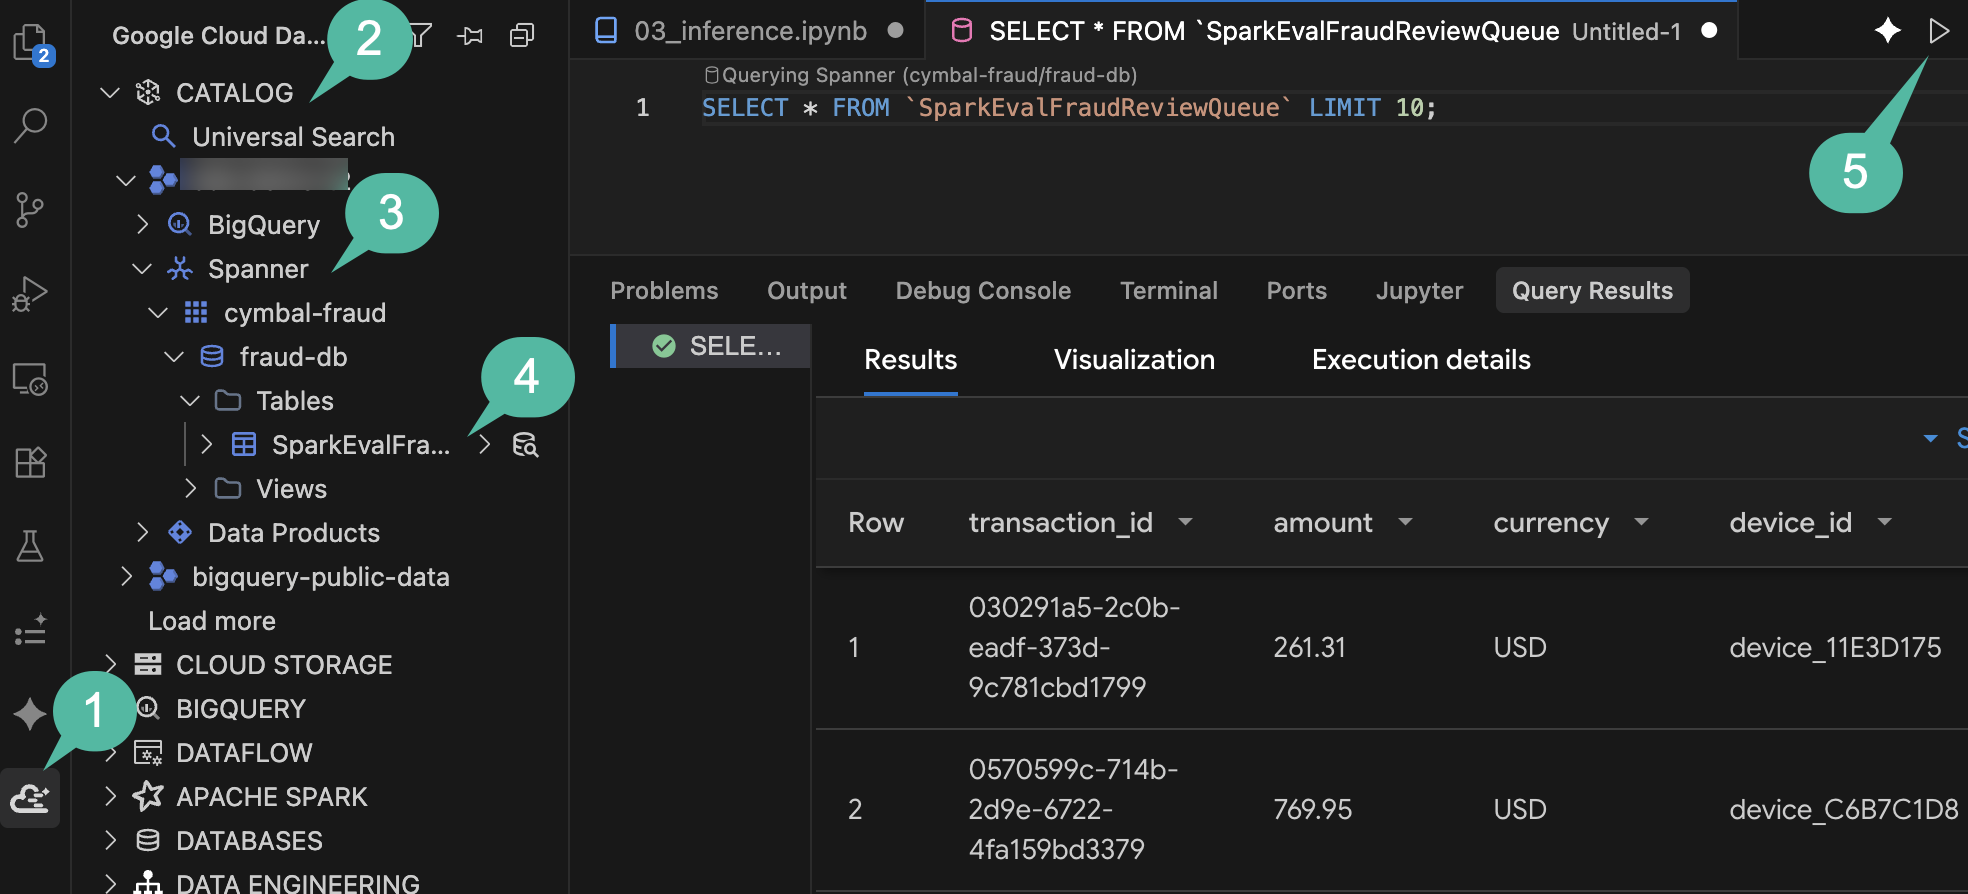
- IDE অ্যাক্টিভিটি বারে, Google Cloud Data Agent Kit প্যানেলটি খুলুন।
- ক্যাটালগ বিভাগটি প্রসারিত করুন।
- আপনার প্রজেক্ট আইডি প্রসারিত করুন, তারপর স্প্যানার প্রসারিত করুন।
-
cymbal-fraud->fraud-db->Tables->SparkEvalFraudReviewQueue-এ যান। - টেবিলটির উপর রাইট-ক্লিক করে 'Query Table' নির্বাচন করুন, তারপর কোয়েরিটি চালান:
SELECT *
FROM `SparkEvalFraudReviewQueue`
LIMIT 100;
- নিচের কোয়েরি রেজাল্টস প্যানে, আপনি নতুনভাবে সন্নিবেশিত সারিগুলো দেখতে পাবেন, যেগুলো ম্যানুয়াল পর্যালোচনার জন্য চিহ্নিত উচ্চ-ঝুঁকিপূর্ণ লেনদেনগুলোর প্রতিনিধিত্ব করে।
অধ্যায়ের সারসংক্ষেপ: আপনি এজেন্ট ব্যবহার করে একটি ব্যাচ ইনফারেন্স নোটবুক তৈরি করেছেন, আপনার প্রশিক্ষিত মডেল দিয়ে লেবেলবিহীন BigQuery রেকর্ডগুলোর স্কোরিং করেছেন, এবং উচ্চ-ঝুঁকিপূর্ণ ট্রানজ্যাকশনগুলো সরাসরি ক্লাউড স্প্যানারে লিখেছেন।
৭. নিয়ন্ত্রিত বায়ুপ্রবাহের মাধ্যমে কাঠামো তৈরি করুন এবং সমন্বয় সাধন করুন।
আপনার পাইপলাইনটি বর্তমানে কয়েকটি পৃথক ধাপ নিয়ে গঠিত: একটি ইনজেশন নোটবুক, একটি ডিবিটি ট্রান্সফরমেশন প্রজেক্ট এবং একটি ব্যাচ ইনফারেন্স নোটবুক। এটিকে প্রোডাকশনের জন্য প্রস্তুত করতে, আপনি এগুলোকে একত্রিত করে একটি শিডিউলড ডিপেন্ডেন্সি গ্রাফ তৈরি করবেন।
অ্যাপাচি এয়ারফ্লো-এর জন্য পরিচালিত পরিষেবা (পূর্বে ক্লাউড কম্পোজার নামে পরিচিত) এই ওয়ার্কফ্লোর জন্য একটি পরিচালিত অর্কেস্ট্রেশন ইঞ্জিন প্রদান করে। ডেটা এজেন্ট কিট-এ একটি অর্কেস্ট্রেশন পাইপলাইনস বৈশিষ্ট্য রয়েছে যা ডিক্লারেটিভ YAML পাইপলাইন সংজ্ঞাগুলোকে সরাসরি এয়ারফ্লো DAG-তে অনুবাদ করে।
পাইপলাইন সংজ্ঞায়িত করুন
অর্কেস্ট্রেশন পাইপলাইন কনফিগারেশন তৈরি করতে এজেন্টটি ব্যবহার করুন:
- এজেন্ট চ্যাটে , নিম্নলিখিত প্রম্পটটি প্রদান করুন (মনে রাখবেন
${PROJECT_ID}প্রতিস্থাপন করতে হবে):
Initialize and define an orchestration pipeline (fraud_analysis_pipeline) triggering
the ingestion notebook, dbt project, and inference notebook in sequential order.
For Dataproc Serverless engine configs in us-central1, use resourceProfile.inline
(defining properties with spark.jars: "gs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jar"
for inference) rather than resourceProfile.path or overrides.

Set the schedule interval to run daily at midnight, and use
gs://${PROJECT_ID}-airflow-artifacts for artifact storage.
DAG কনফিগারেশন পর্যালোচনা করুন
ডেটা এজেন্ট কিট অর্কেস্ট্রেটর অ্যাপাচি এয়ারফ্লো-তে পাইপলাইন সংজ্ঞায়িত ও স্থাপন করতে ডিক্লারেটিভ YAML কনফিগারেশন ব্যবহার করে, যা ডেফিনিশনগুলোকে ভার্সন কন্ট্রোল এবং CI/CD-এর মাধ্যমে স্থাপন করার সুযোগ দেয়।
IDE এক্সপ্লোরার প্যানে, আপনার ওয়ার্কস্পেসের রুটে এজেন্ট দ্বারা তৈরি করা দুটি পাইপলাইন ফাইল পর্যালোচনা করুন:
-
deployment.yaml: এই ফাইলটি খুলুন। এটি আপনার এনভায়রনমেন্ট রেজিস্ট্রি হিসেবে কাজ করে। এটি আপনার লজিক্যালdevপাইপলাইনকেcymbal-airflowএনভায়রনমেন্টের সাথে ম্যাপ করে, এক্সিকিউশন রিজিয়ন (us-central1) সেট করে এবংartifact_storageবাকেট নির্ধারণ করে, যেখানে কম্পাইল করা DAG ও ডিপেন্ডেন্সিগুলো স্টেজ করা হয়। -
fraud_analysis_pipeline.yaml: এই ফাইলটি খুলুন। এটি এক্সিকিউশন গ্রাফ নির্ধারণ করে। এটি ট্রিগার শিডিউল (interval: '0 0 * * *') নির্দিষ্ট করে এবংactionsব্লকের অধীনে তিনটি ধাপের ক্রম নির্ধারণ করে:- Dataproc Serverless-এ চলমান
01_ingestion.ipynbএর জন্য একটি ইনজেশনnotebookঅ্যাকশন। -
dbt_projectডিরেক্টরিকে লক্ষ্য করে একটি ট্রান্সফরমেশনpipelineঅ্যাকশন, যেখানে একটিdependsOnডিপেন্ডেন্সি ইনজেশন স্টেপটিকে নির্দেশ করে। -
03_inference.ipynbএর জন্য একটি ইনফারেন্সnotebookঅ্যাকশন, যার একটিdependsOnডিপেন্ডেন্সি dbt স্টেপটিকে নির্দেশ করে এবং যা Spanner JAR প্রপার্টিটিকে বান্ডল করে।
- Dataproc Serverless-এ চলমান
- এজেন্টটি আপনার এডিটর প্যানেলের একটি 'ওয়াকথ্রু' ট্যাবে এই তৈরি হওয়া আর্টিফ্যাক্টগুলোর সারসংক্ষেপও প্রকাশ করবে, যেখানে সম্পাদিত কনফিগারেশন এবং ভ্যালিডেশনগুলোর রূপরেখা দেওয়া থাকবে।
ইন্টারেক্টিভ ডিএজি কনফিগারেশন
ডেটা এজেন্ট কিট আপনার পাইপলাইন কনফিগারেশনকে একটি ইন্টারেক্টিভ ভিজ্যুয়াল গ্রাফ হিসাবে উপস্থাপন করে, যার মাধ্যমে এয়ারফ্লো ডিএজি প্রোপার্টিগুলো পরিদর্শন ও সম্পাদনা করা যায়।
- IDE অ্যাক্টিভিটি বারে, Google Cloud Data Agent Kit প্যানেলটি খুলুন।
-
DATA ENGINEERINGএর অধীনে,Orchestration Pipelinesপ্রসারিত করুন। - মূল এডিটরে ভিজ্যুয়াল DAG ক্যানভাসটি খুলতে
fraud_analysis_pipeline.yamlএ ক্লিক করুন।
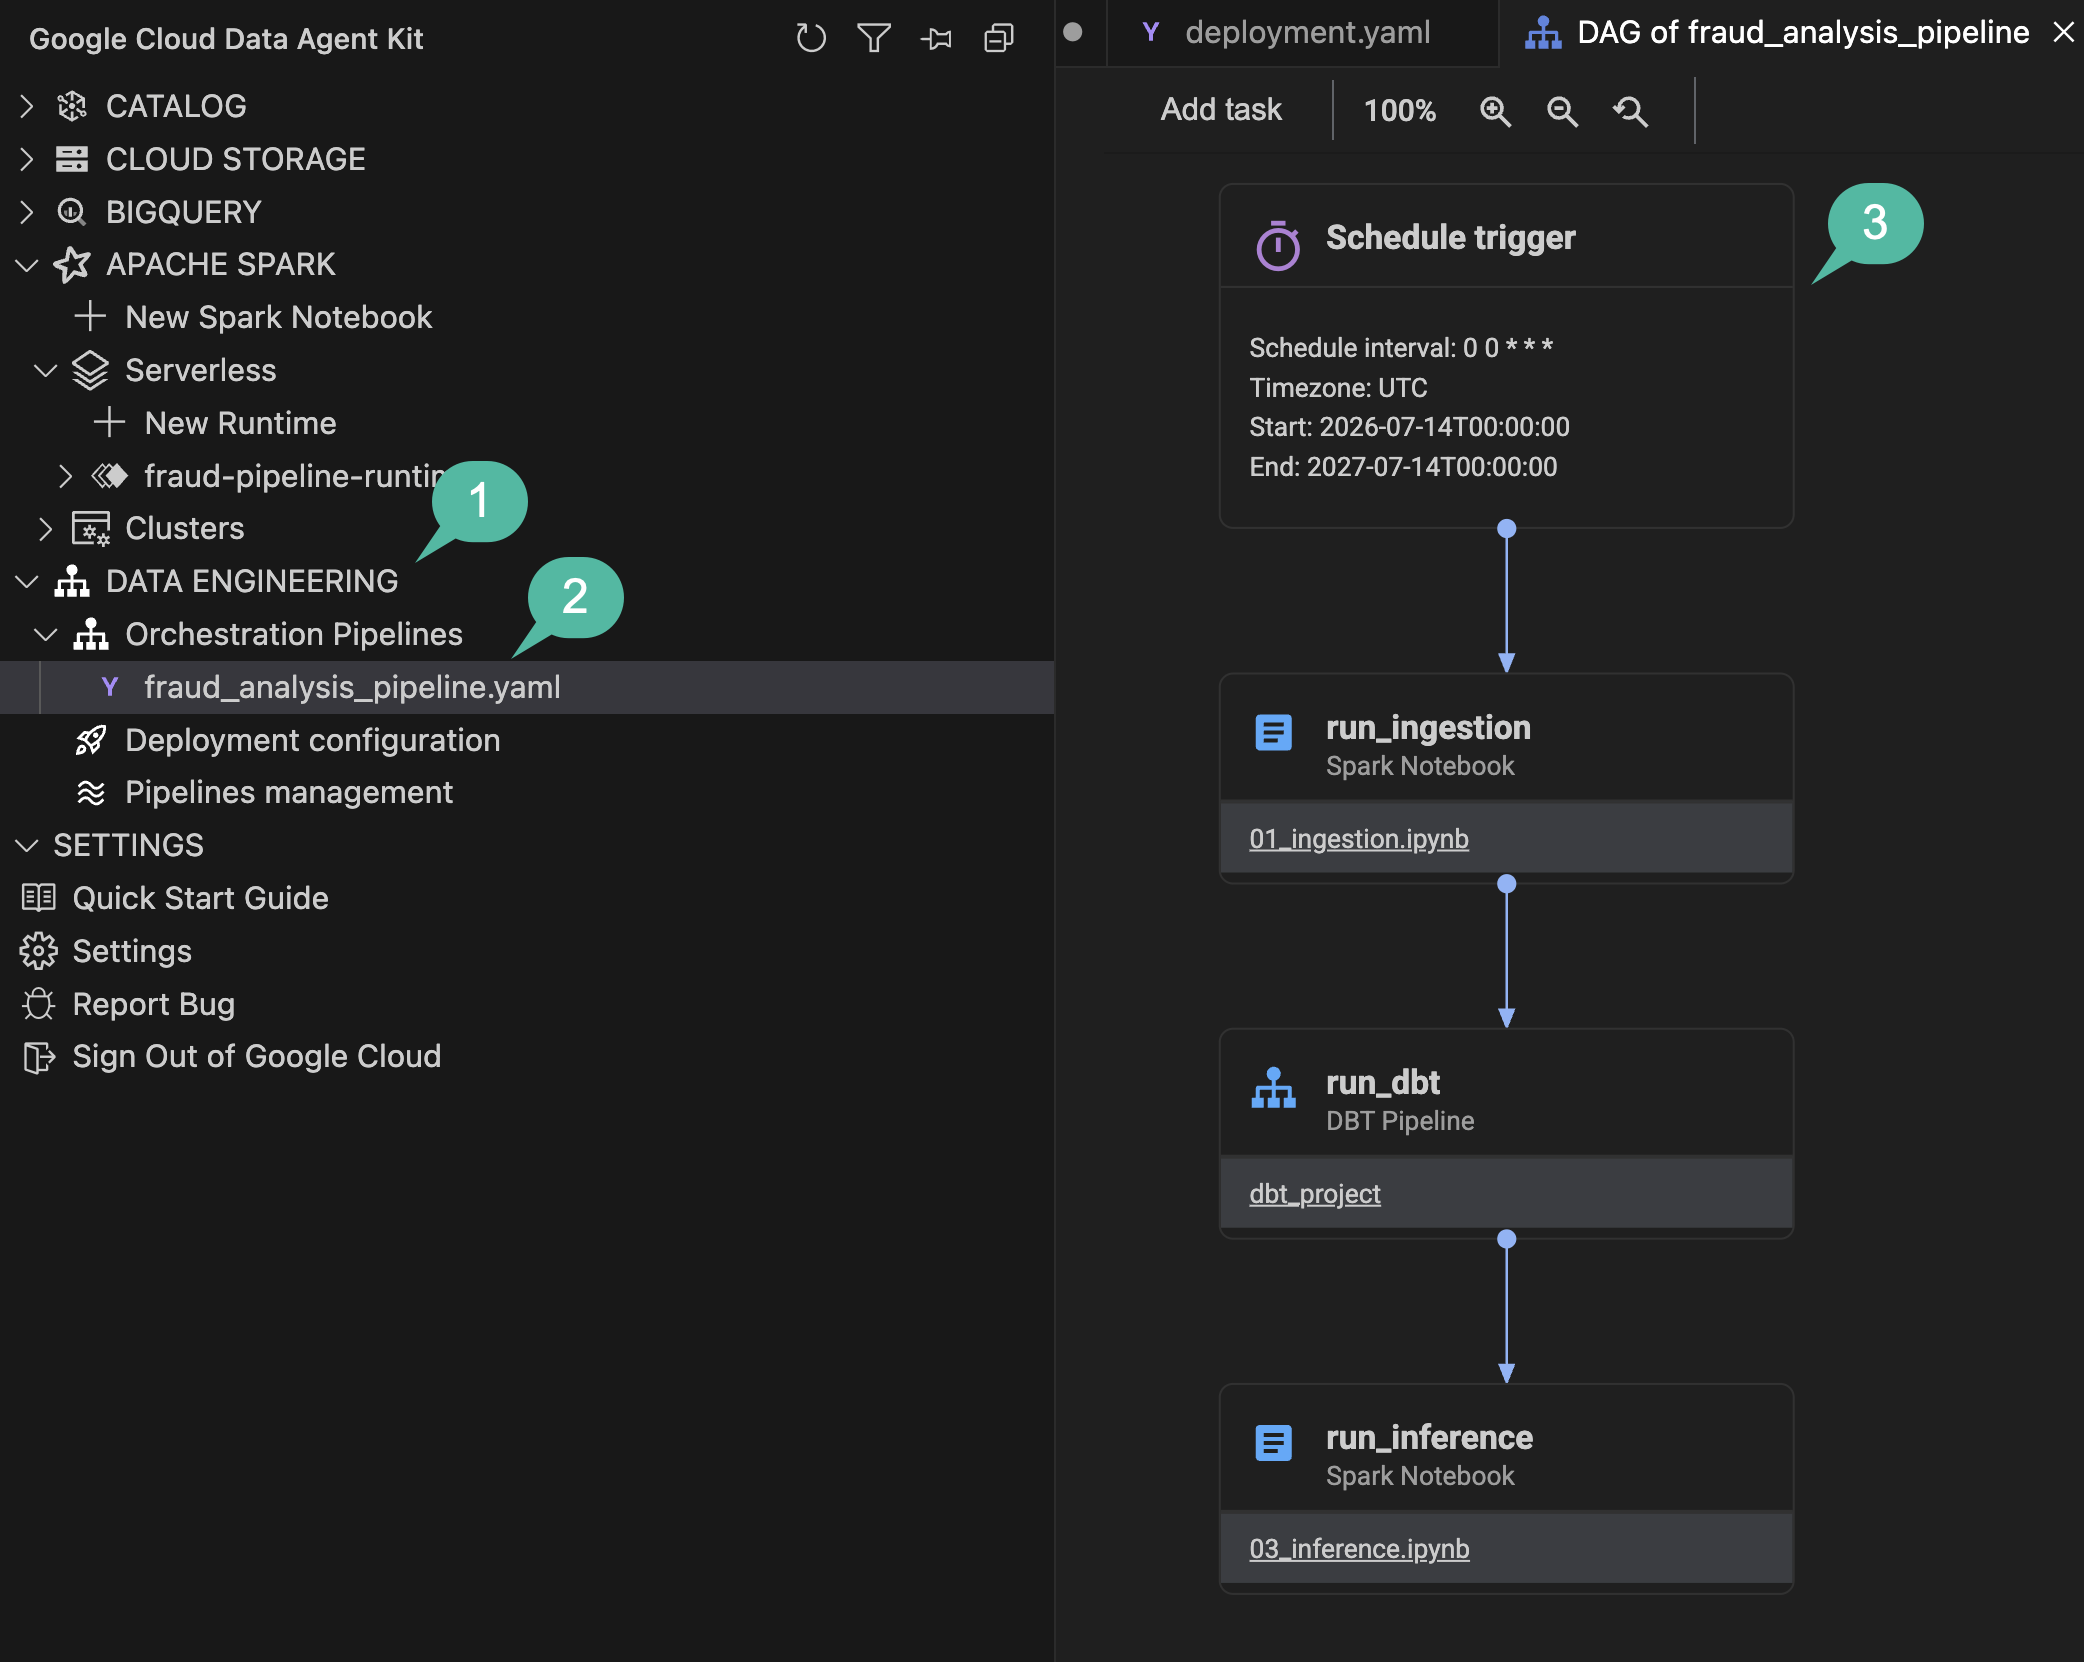
- উপরে থাকা
Schedule triggerনোডটিতে ক্লিক করুন। ডানদিকে একটি কনফিগারেশন ফ্লাইআউট খুলবে, যেখানে পার্স করা ক্রন স্ট্রিং (0 0 * * *) দেখা যাবে এবং আপনি ব্যাকফিল ও ক্যাচআপের মতো প্যারামিটারগুলো পরিবর্তন করতে পারবেন। - নোটবুক টাস্ক নোডগুলোর যেকোনো একটিতে (যেমন ইনজেশন বা ইনফারেন্স স্টেপ) ক্লিক করুন। ফ্লাইআউটটি আপডেট হয়ে নির্দিষ্ট ডেটাপ্রোক সার্ভারলেস এক্সিকিউশন ম্যাপিং এবং কানেক্টর প্রোপার্টিগুলো প্রদর্শন করবে।
- নোড ব্লকের ভিতরে নোটবুক ফাইলের নামের হাইপারলিঙ্কটি (যেমন
01_ingestion.ipynb) লক্ষ্য করুন। এটিতে ক্লিক করলে নোটবুকটি সরাসরি আপনার এডিটরে খুলে যায়। - বাম সাইডবারে ‘Orchestration Pipelines’-এর নিচে,
Deployment configurationএ ক্লিক করুন। এই ভিউটি আপনার টার্গেটdevএনভায়রনমেন্ট ক্লাস্টার এবং আউটপুট GCS বাকেট আর্টিফ্যাক্টগুলো দেখায়।
অধ্যায়ের পুনরালোচনা: আপনি এজেন্টের সাহায্যে একটি অর্কেস্ট্রেশন পাইপলাইন কনফিগারেশন তৈরি করেছেন, যেখানে একটি ইন্টারেক্টিভ ভিজ্যুয়াল ক্যানভাসে ইনজেশন, ডিবিটি এবং ইনফারেন্স টাস্কগুলোর মধ্যেকার নির্ভরতা সংজ্ঞায়িত করা হয়েছে।
৮. স্থাপন, কার্যকর এবং পর্যবেক্ষণ করুন
স্থানীয়ভাবে DAG সংজ্ঞায়িত করা থাকলে, আপনি সেটআপের সময় সরবরাহ করা ম্যানেজড এয়ারফ্লো এনভায়রনমেন্টের সাথে সংযোগ স্থাপন করবেন এবং পাইপলাইনটি ডেপ্লয় করবেন।
অ্যাপাচি এয়ারফ্লো-এর জন্য পরিচালিত পরিষেবা কনফিগার করুন
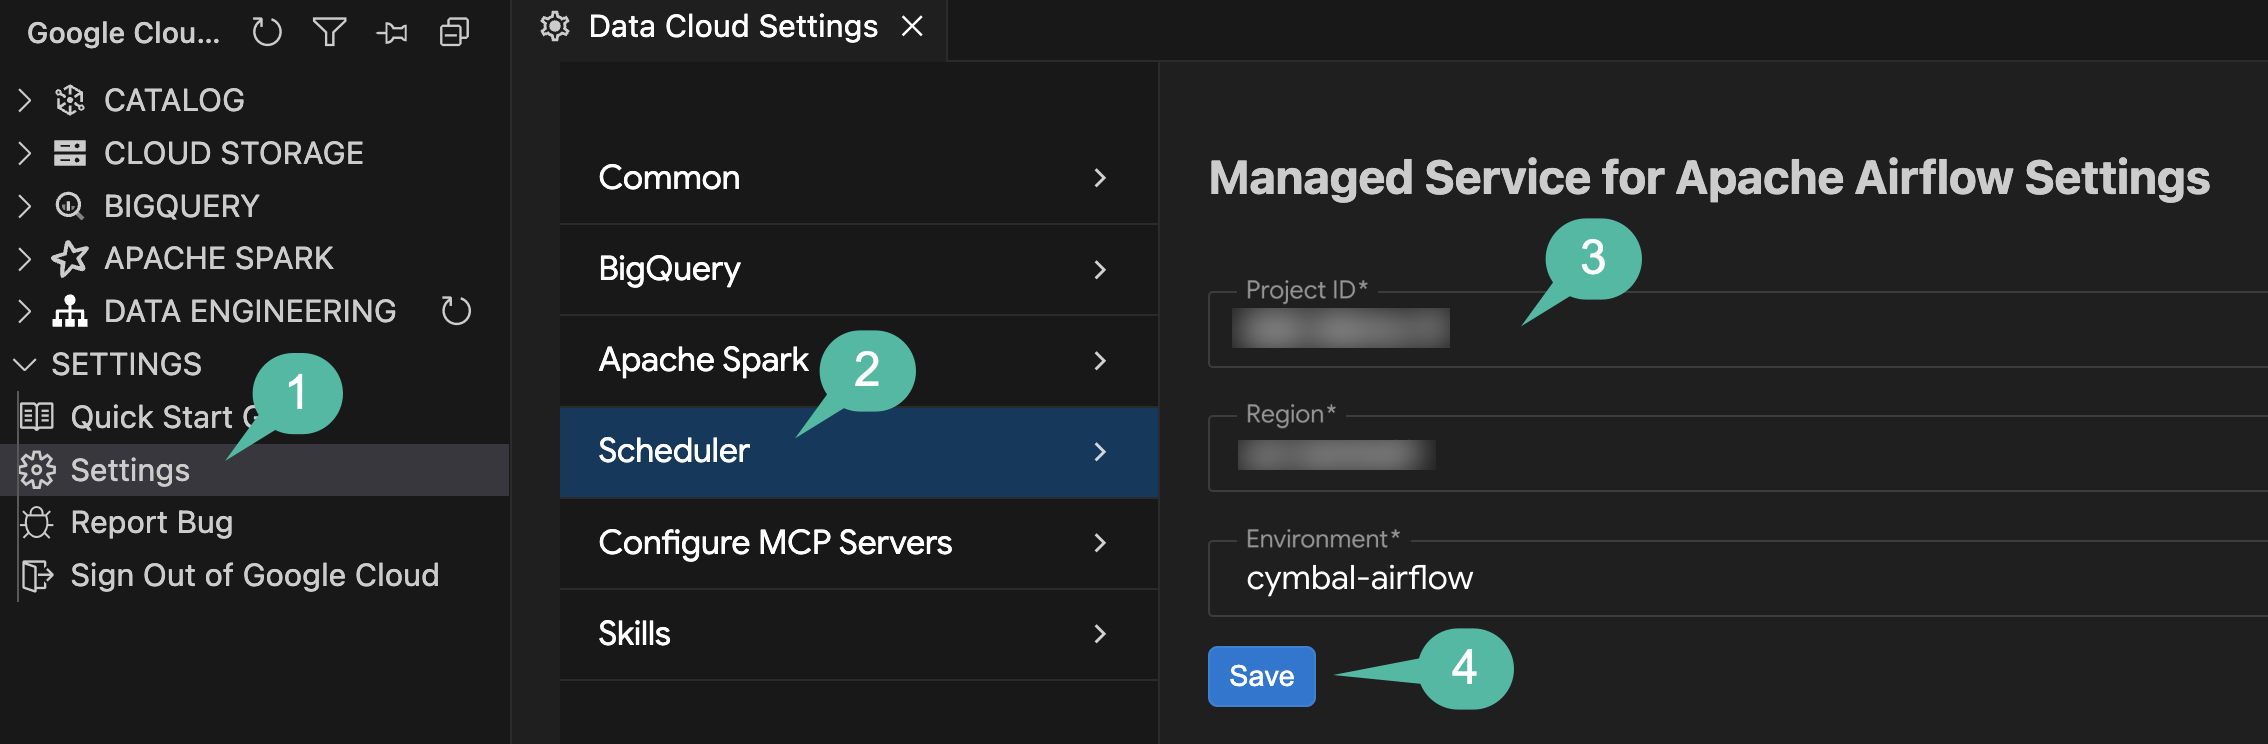
স্থাপন করার আগে, ডেটা এজেন্ট কিট সেটিংসে শিডিউলার সংযোগটি কনফিগার করুন, যাতে এক্সটেনশনটি আপনার পরিচালিত এয়ারফ্লো পরিবেশকে লক্ষ্য করে:
- IDE অ্যাক্টিভিটি বারে, Google Cloud Data Agent Kit প্যানেলটি খুলুন।
-
SETTINGSঅধীনে, সেটিংস-এ ক্লিক করুন। - বাম দিকের মেনু থেকে শিডিউলার নির্বাচন করুন।
- সেটিংসগুলো কনফিগার করুন:
- প্রজেক্ট আইডি : আপনার সক্রিয় প্রজেক্ট আইডিটি নির্বাচন করুন।
- অঞ্চল :
us-central1নির্বাচন করুন। - পরিবেশ :
cymbal-airflowনির্বাচন করুন।
- সংরক্ষণ করুন- এ ক্লিক করুন।
DAG স্থাপন করুন
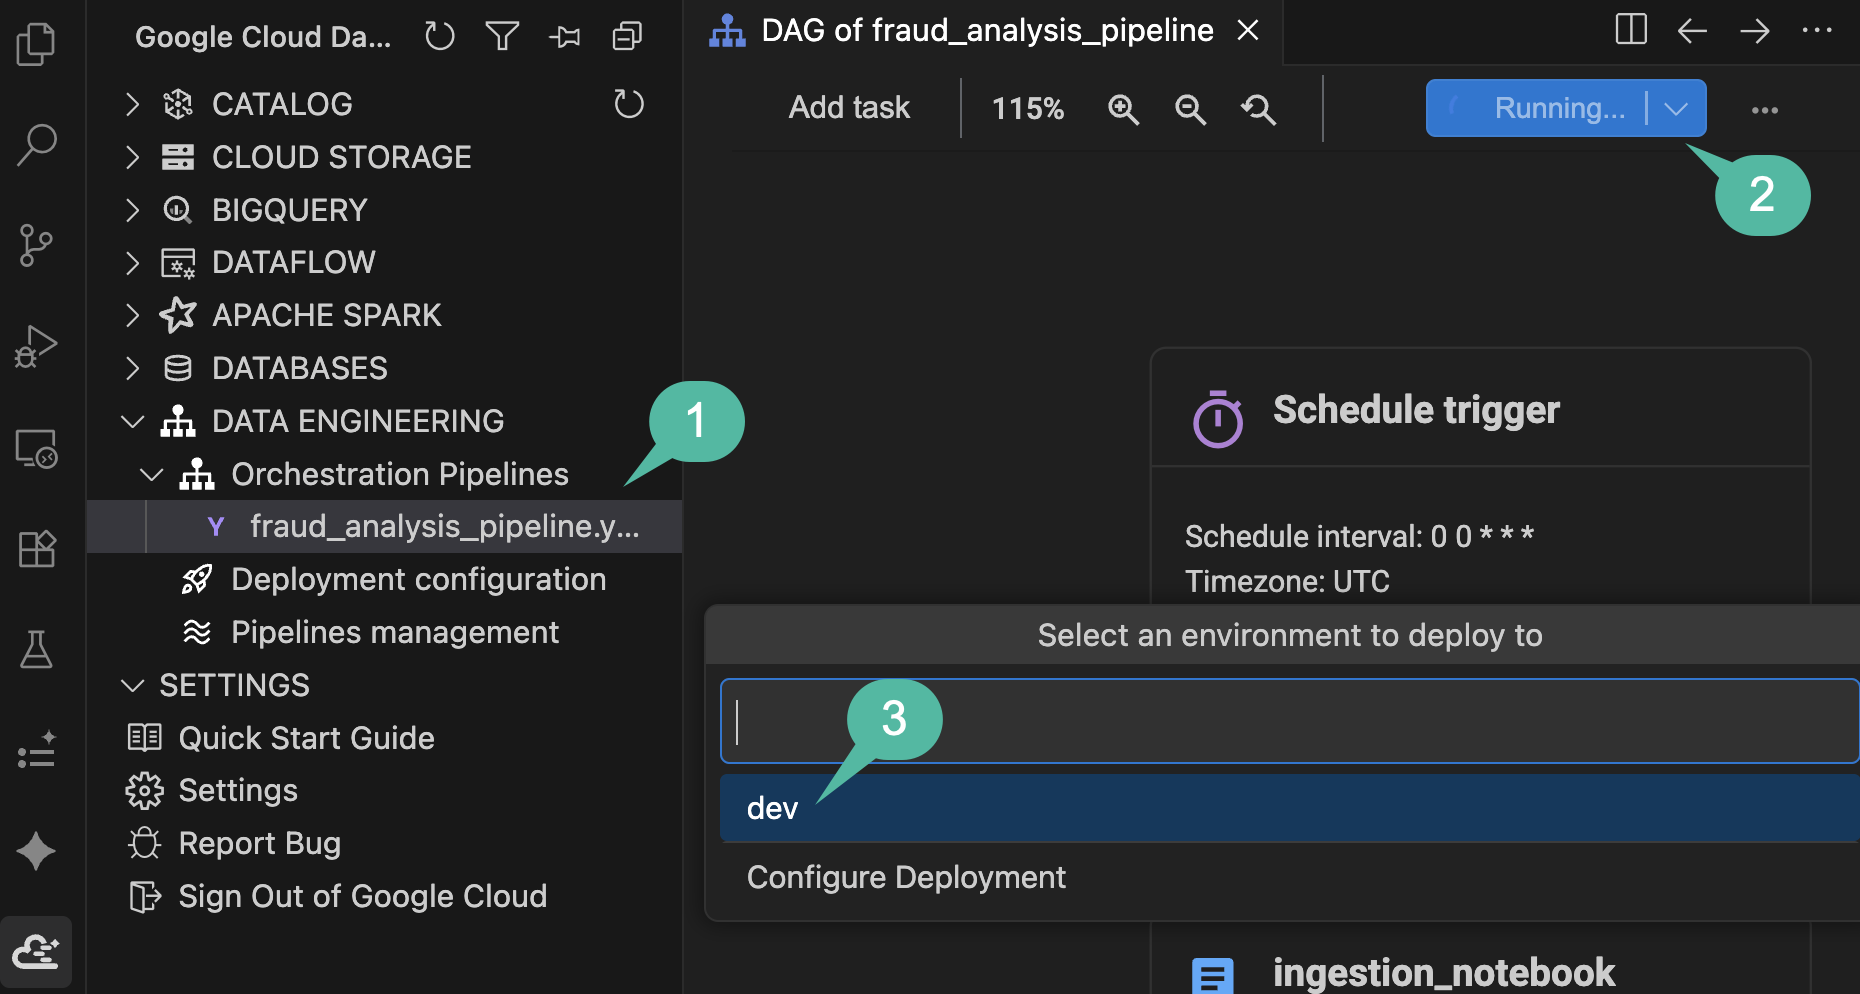
এখন আপনি ভিজ্যুয়াল ক্যানভাস থেকে সরাসরি আপনার ম্যানেজড এয়ারফ্লো এনভায়রনমেন্টে কনফিগার করা পাইপলাইনটি ডেপ্লয় করবেন:
- Google Cloud Data Agent Kit সাইডবারে,
DATA ENGINEERING>Orchestration Pipelinesপ্রসারিত করুন এবং ভিজ্যুয়াল DAG ক্যানভাসটি খুলতেfraud_analysis_pipeline.yamlএ ক্লিক করুন। - ক্যানভাস টুলবারের উপরের ডান কোণায় থাকা নীল রঙের 'রান পাইপলাইন' বোতামটিতে ক্লিক করুন।
- এনভায়রনমেন্ট ড্রপডাউন পিকার থেকে
devনির্বাচন করুন। - নিচের স্ট্যাটাস অংশে অগ্রগতির বিজ্ঞপ্তিটি লক্ষ্য করুন (
Running pipeline: Building pipeline locally...)। এক্সটেনশনটি স্বয়ংক্রিয়ভাবে আপনার DAG কম্পাইল করবে, নোটবুক এবং dbt অ্যাসেটগুলো প্যাকেজ করবে এবং সেগুলোকে আপনার ম্যানেজড এয়ারফ্লো এনভায়রনমেন্টের GCS বাকেটে আপলোড করবে (এই প্রক্রিয়াটি সম্পন্ন হতে প্রায় ৩-৪ মিনিট সময় লাগে)।
রানটি পর্যবেক্ষণ করুন
একবার স্থানীয় কম্পাইলেশন সম্পন্ন হলে এবং পপ-আপ নোটিফিকেশনটি ' Triggered a new run for pipeline... successfully নিশ্চিত করলে, লাইভ এক্সিকিউশন মনিটর করুন:
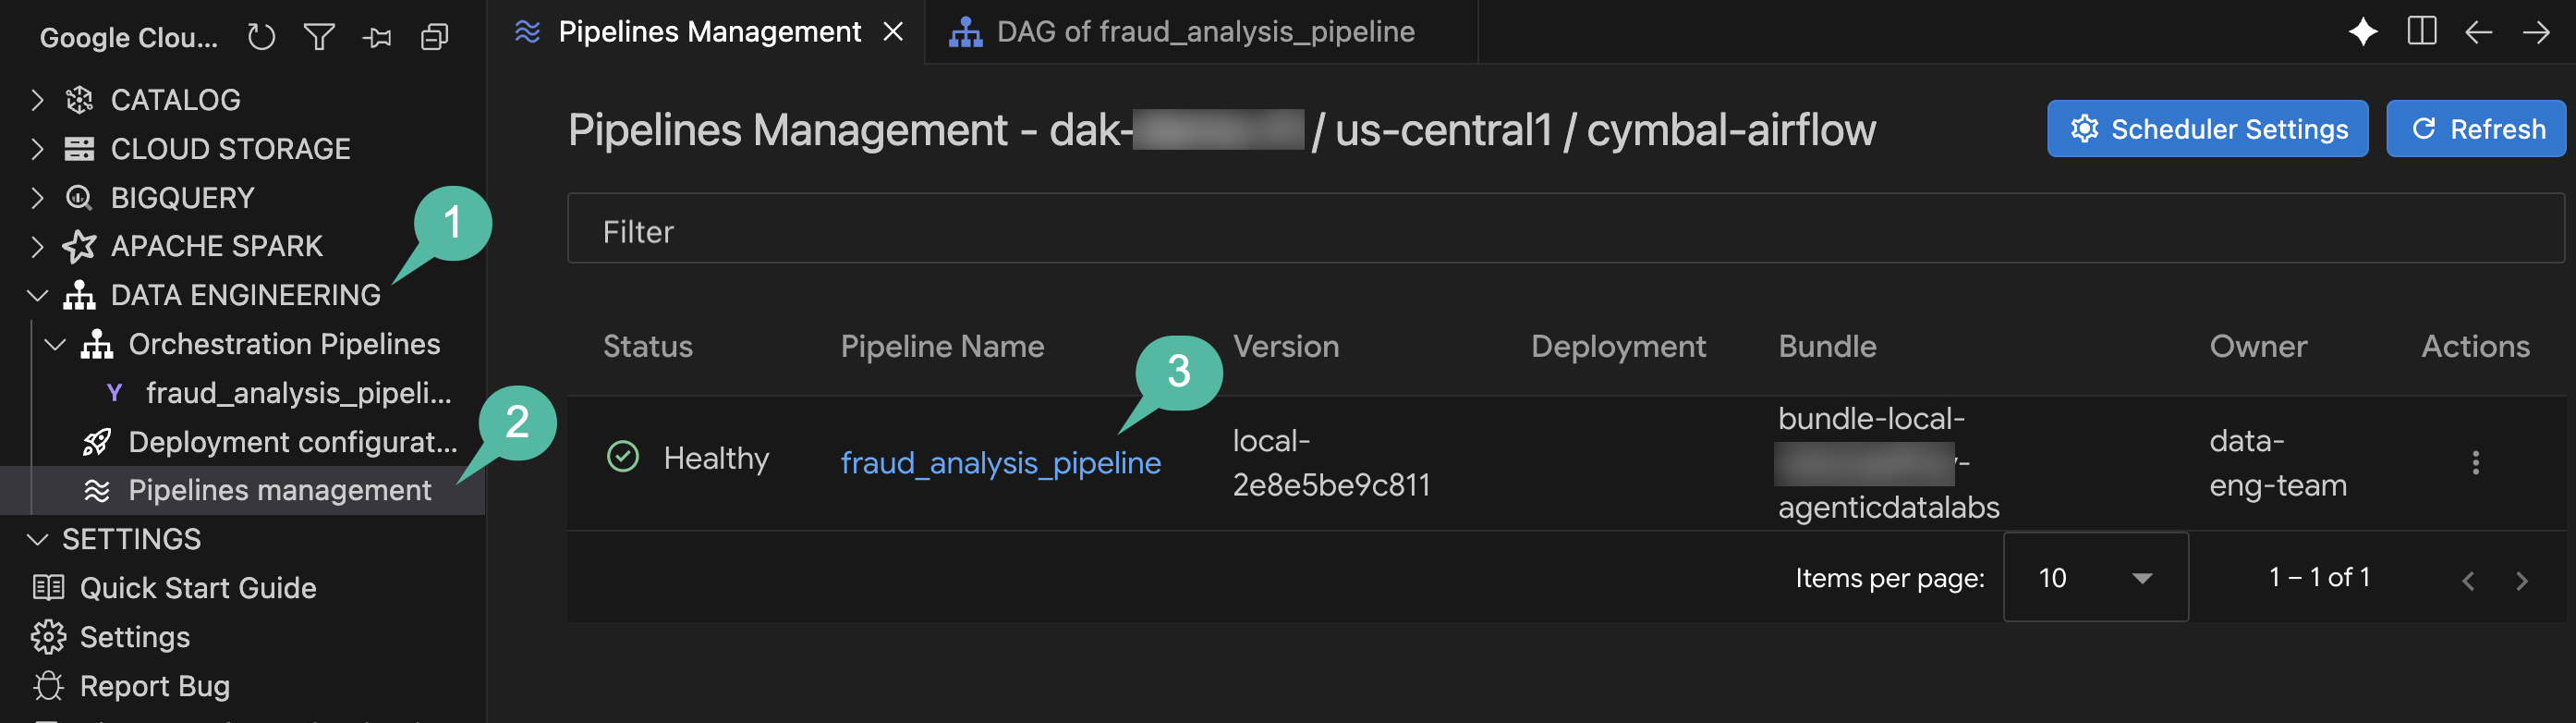
- Google Cloud Data Agent Kit সাইডবারে,
DATA ENGINEERING>Orchestration Pipelinesপ্রসারিত করুন। - পাইপলাইন ব্যবস্থাপনায় ক্লিক করুন।
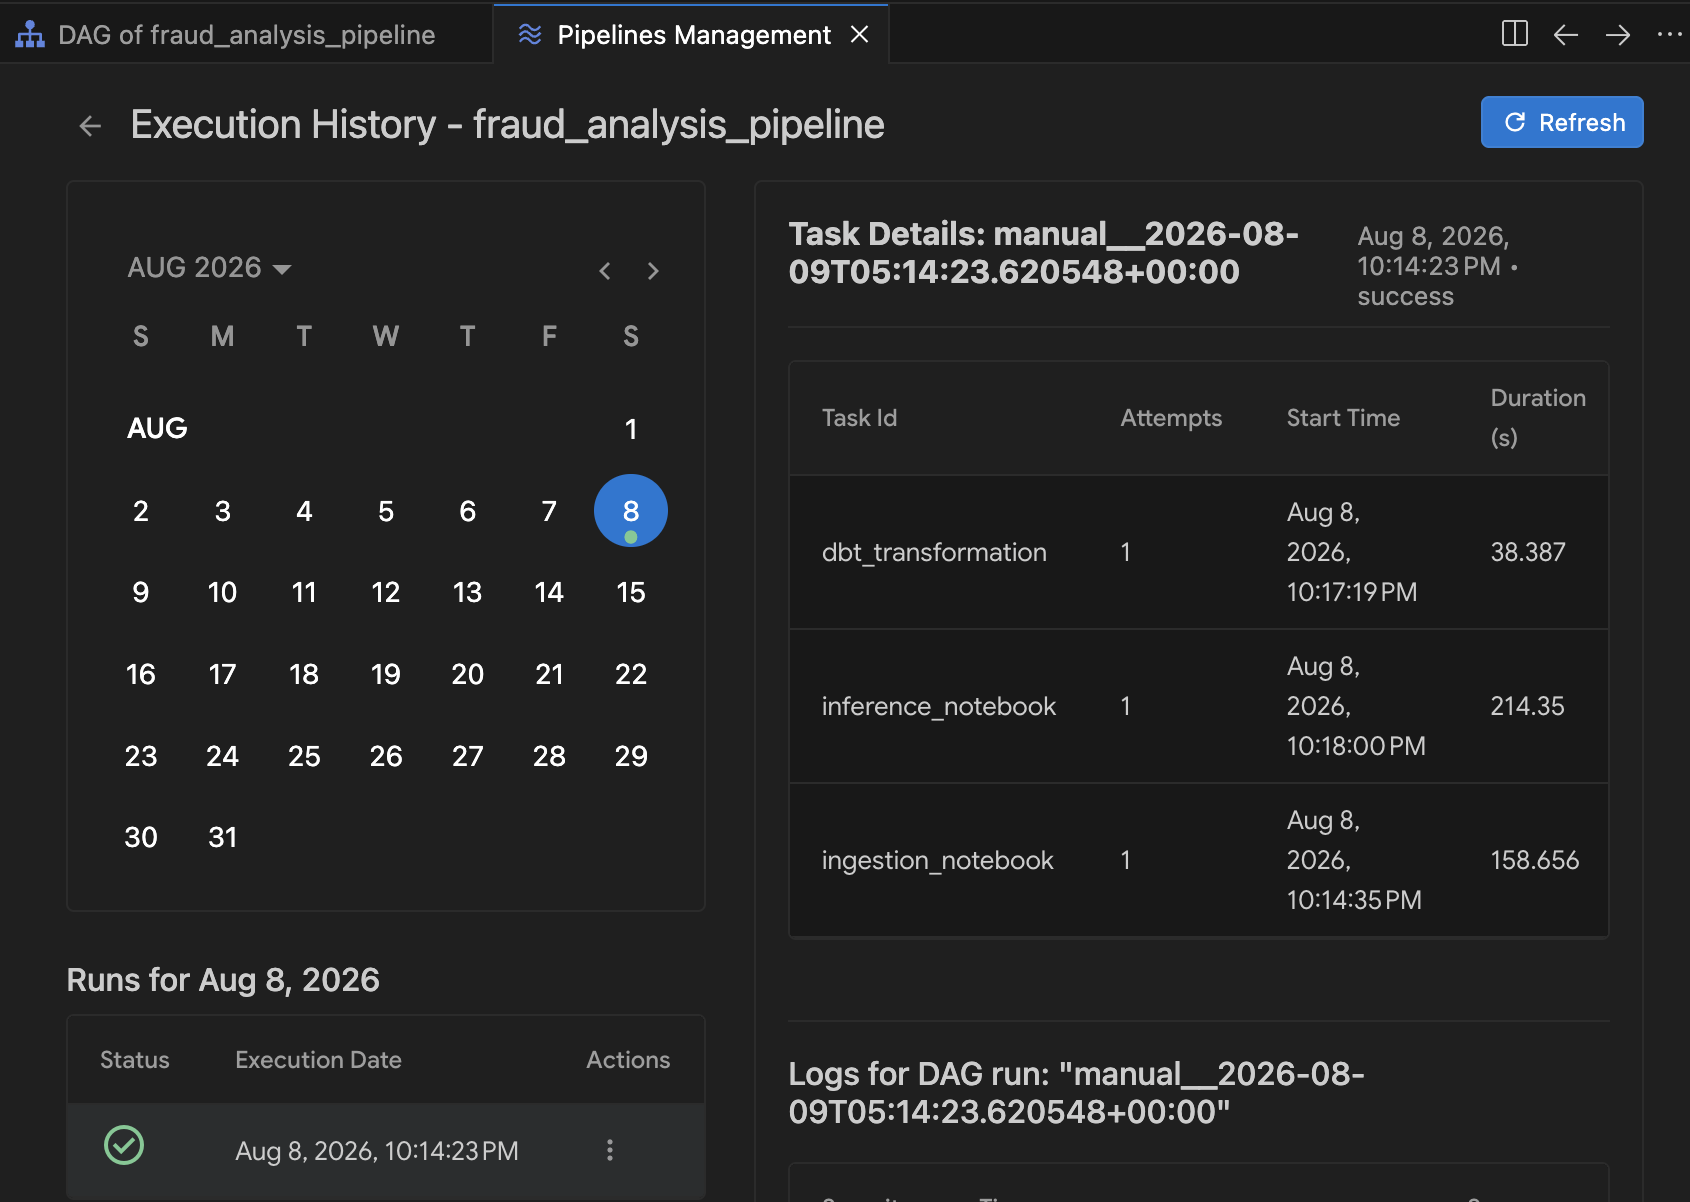
- পাইপলাইন ম্যানেজমেন্ট টেবিলে,
fraud_analysis_pipelineএর এক্সিকিউশন হিস্ট্রি খুলতে সেটিতে ক্লিক করুন।
- এক্সিকিউশন হিস্ট্রি ভিউতে, ক্যালেন্ডার থেকে সক্রিয় রানটি নির্বাচন করুন।
- প্রতিটি পাইপলাইন টাস্ক (ইনজেশন, ডিবিটি ট্রান্সফরমেশন এবং ইনফারেন্স) সম্পাদনের অগ্রগতির সাথে সাথে স্ট্যাটাস ইন্ডিকেটরগুলো আপডেট হয় এবং টাস্কের সময়কাল প্রদর্শিত হয়। যেকোনো টাস্কে ক্লিক করে সেটির লাইভ এক্সিকিউশন আউটপুট এবং এয়ারফ্লো ডিএজি লগগুলো পর্যবেক্ষণ করুন।
অধ্যায়ের সারসংক্ষেপ: আপনি Airflow Scheduler সংযোগটি কনফিগার করেছেন, আপনার এন্ড-টু-এন্ড অ্যানালিটিক্যাল পাইপলাইনটি Managed Airflow-তে স্থাপন করেছেন, এবং একটি লাইভ এক্সিকিউশন পর্যবেক্ষণ করে র লগ থেকে শুরু করে Cloud Spanner-এর চূড়ান্ত পূর্বাভাস পর্যন্ত সিস্টেমটি যাচাই করেছেন।
৯. পরিষ্কার করুন
এই কোডল্যাবে ব্যবহৃত রিসোর্সগুলোর জন্য আপনার গুগল ক্লাউড প্রোজেক্টে চলমান চার্জ এড়ানোর জন্য, স্বয়ংক্রিয় স্ক্রিপ্টটি ব্যবহার করে এনভায়রনমেন্টটি বন্ধ করে দিন।
- টার্মিনাল প্যানেলে (অথবা ক্লাউড শেলে), স্ক্রিপ্ট ডিরেক্টরিতে যান এবং নিম্নলিখিত কমান্ডটি চালান:
cd ~/devrel-demos/codelabs/agentic-data-labs/data-science/scripts
chmod +x teardown.sh
./teardown.sh
- স্ক্রিপ্টটি যে সমস্ত রিসোর্স মুছে ফেলার পরিকল্পনা করছে তার একটি তালিকা দেখাবে এবং নিশ্চিতকরণের জন্য অনুরোধ করবে:
- নিয়ন্ত্রিত বায়ুপ্রবাহ পরিবেশ (
cymbal-airflow) - ক্লাউড স্প্যানার ইনস্ট্যান্স (
cymbal-fraud) - BigQuery ডেটাসেট (
transactions_dataset_evals) - ক্লাউড স্টোরেজ বাকেট (
gs://${PROJECT_ID}-fin-clearing-rawএবংgs://${PROJECT_ID}-models) - কর্মী পরিষেবা অ্যাকাউন্ট (
composer-worker-sa)
- নিয়ন্ত্রিত বায়ুপ্রবাহ পরিবেশ (
- নিশ্চিত করতে
yটাইপ করুন। টিয়ারডাউন স্ক্রিপ্টটি সমস্ত প্রোভিশন করা GCP পরিষেবা মুছে ফেলবে এবং স্থানীয় ফাইলগুলি পরিষ্কার করবে।
১০. অভিনন্দন!
আপনি Antigravity IDE-এর ভিতরে Google Cloud Data Agent Kit-এর সাথে পেয়ার-প্রোগ্রামিং করে Cloud Storage, BigQuery, Managed Service for Apache Spark (Spark Serverless), dbt, Cloud Spanner, এবং Managed Service for Apache Airflow-কে অন্তর্ভুক্ত করে একটি এন্ড-টু-এন্ড জালিয়াতি সনাক্তকরণ পাইপলাইন তৈরি করেছেন।
আপনি যা অর্জন করেছেন
- 📥 অ্যাপাচি স্পার্কের ম্যানেজড সার্ভিস এবং ডেটা এজেন্ট কিট ব্যবহার করে সরাসরি ট্রানজ্যাকশন লগগুলো একটি বিগকোয়েরি টেবিলে অন্তর্ভুক্ত করা হয়েছে ।
- 🧹 ডেটার গুণমান পরীক্ষা সহ একটি dbt প্রজেক্ট তৈরি করে ডেটা থেকে ডুপ্লিকেট বাদ দেওয়া হয়েছে এবং ডেটা স্বাভাবিক করা হয়েছে ।
- 🤖
RandomForestClassifierব্যবহার করে একটি ডিস্ট্রিবিউটেড র্যান্ডম ফরেস্ট মডেলকে প্রশিক্ষণ দিয়েছি এবং প্রশিক্ষিত মডেলটি ক্লাউড স্টোরেজে এক্সপোর্ট করেছি। - ⚡ আগত লেনদেনগুলোর ওপর ব্যাচ ইনফারেন্স কার্যকর করা হয়েছে এবং উচ্চ-ঝুঁকিপূর্ণ রেকর্ডগুলো নিরীক্ষা পর্যালোচনার জন্য ক্লাউড স্প্যানারে পাঠানো হয়েছে।
- 🔄 অ্যাপাচি এয়ারফ্লো-এর ম্যানেজড সার্ভিস এবং IDE-এর ভিজ্যুয়াল DAG ম্যানেজমেন্ট টুল ব্যবহার করে ওয়ার্কফ্লোটিকে একটি নির্ধারিত এয়ারফ্লো DAG হিসেবে অর্কেস্ট্রেট, ডেপ্লয় এবং মনিটর করা হয়েছে ।
মূল ধারণা
ধারণা | আপনি যা শিখেছেন |
IDE-এর ভিতরে স্বাভাবিক ভাষা ব্যবহার করে পেয়ার-প্রোগ্রামিংয়ের মাধ্যমে PySpark নোটবুক তৈরি করা, dbt মডেল কনফিগার করা এবং Airflow DAG সংজ্ঞায়িত করা। | |
বিশ্লেষণমূলক SQL, dbt রূপান্তর, এবং ML প্রশিক্ষণের জন্য পরিমাপযোগ্য সারণীভিত্তিক স্টোরেজ | |
ডিস্ট্রিবিউটেড পাইস্পার্ক ডেটা লোডিং এবং র্যান্ডম ফরেস্ট এমএল প্রশিক্ষণের জন্য সার্ভারলেস এক্সিকিউশন | |
ব্যাচ স্পার্ক ইনফারেন্স প্রেডিকশনগুলো সরাসরি অপারেশনাল ডেটাবেস রিভিউ কিউতে লেখা | |
YAML DAG ঘোষণা | ডিক্লারেটিভ পাইপলাইন ডেফিনিশনগুলো IDE-তে ইন্টারেক্টিভ Airflow ভিজ্যুয়াল গ্রাফ হিসেবে প্রদর্শিত হয়। |
ভিজ্যুয়াল ডিএজি ম্যানেজমেন্ট | পাইপলাইন নির্ভরতা পরিদর্শন করা, ম্যানেজড এয়ারফ্লো- তে ডেপ্লয় করা, এবং IDE-র ভিতরে লাইভ টাস্ক সম্পাদনের ইতিহাস পর্যবেক্ষণ করা। |
পরবর্তী পদক্ষেপ
- গুগল ক্লাউড ডেটা এজেন্ট কিট ডকুমেন্টেশন অন্বেষণ করুন
- অ্যাপাচি স্পার্কের জন্য পরিচালিত পরিষেবা সম্পর্কে আরও জানুন
- অ্যাপাচি এয়ারফ্লো-এর জন্য পরিচালিত পরিষেবা সম্পর্কে আরও জানুন
- Antigravity IDE ব্যবহার করে আপনার নিজস্ব মাল্টি-সার্ভিস পাইপলাইন তৈরি করুন।
১. ভূমিকা
ধরুন, আপনি সাইম্বাল ফিনান্সিয়াল (Cymbal Financial)- এর একজন ডেটা সায়েন্টিস্ট , যা একটি বিপুল পরিমাণ লেনদেন প্রক্রিয়াকারী প্রতিষ্ঠান। সম্প্রতি লেনদেন নিষ্পত্তিতে বিলম্বের একটি ঢেউ দেখা দিয়েছে এবং কমপ্লায়েন্স টিম সমন্বিত জালিয়াতির সন্দেহ করছে। আপনাকে এমন একটি পাইপলাইন তৈরি করতে হবে যা ক্লিয়ারিংহাউসের সরাসরি ট্রানজ্যাকশন লগ গ্রহণ করবে, ডেটা পরিষ্করণ করবে, একটি মেশিন লার্নিং মডেলকে প্রশিক্ষণ দেবে, ব্যাচ ইনফারেন্স চালাবে এবং উচ্চ-ঝুঁকিপূর্ণ ট্রানজ্যাকশনগুলোকে ম্যানুয়াল অডিটিংয়ের জন্য একটি ক্লাউড স্প্যানার (Cloud Spanner) রিভিউ কিউতে অন্তর্ভুক্ত করবে।
Normally, this requires days of writing repetitive setup code (Spark notebooks, dbt configurations, training scripts, Airflow DAGs) and constant context-switching between console interfaces and editors.
In this codelab, you will pair-program with an agent using the Google Cloud Data Agent Kit (DAK) inside the Antigravity IDE . Using conversational natural language, the agent will help you generate Spark notebooks, compile a dbt project, construct an inference loop, and orchestrate the workflow using the Managed Service for Apache Airflow .
আপনি যা করবেন
- Ingest clearinghouse logs from Cloud Storage using Managed Service for Apache Spark (Spark Serverless) into a BigQuery table.
- Deduplicate and normalize transactions using dbt to establish clean data layers (Raw, Staging, Enriched).
- Train a distributed Random Forest classification model (
RandomForestClassifier) on Spark Serverless. - Run batch inference on new transactions and write high-risk alerts directly to Cloud Spanner .
- Orchestrate, visually configure, and deploy the entire pipeline using Managed Service for Apache Airflow and interactive DAG monitoring inside the IDE.
আপনার যা যা লাগবে
- ক্রোমের মতো একটি ওয়েব ব্রাউজার
- A Google Cloud project with billing enabled (we recommend using a new, dedicated project for hands-on labs).
- Basic familiarity with SQL, Python, and PySpark.
- Antigravity IDE with a Google AI Pro subscription (recommended)
The resources created in this codelab should cost less than $5. Be sure to follow the Clean Up instructions at the end of the lab to delete provisioned resources.
2. Environment setup
To kick off the lab, you will run a bootstrap script. This script automatically enables required GCP APIs, creates an ingestion Cloud Storage bucket, generates mock transaction and directory datasets, loads reference directories into BigQuery, and kicks off background provisioning of Cloud Spanner and Managed Service for Apache Airflow (formerly known as Cloud Composer).
একটি প্রকল্প নির্বাচন করুন বা তৈরি করুন
Choose an existing project or create a new project in the Google Cloud Console.
বিলিং যাচাই করুন
আপনার গুগল ক্লাউড প্রোজেক্টের জন্য বিলিং চালু আছে কিনা তা নিশ্চিত করুন। কীভাবে এটি করতে হয়, তা জানতে এই নির্দেশিকাটি অনুসরণ করতে পারেন।
Run the setup script
You will use Google Cloud Shell (or your local shell configured with the Google Cloud CLI) to launch the environment setup.
- গুগল ক্লাউড কনসোল খুলুন।
- Click Activate Cloud Shell in the top-right toolbar.
- In the Cloud Shell terminal, configure your active project:
gcloud config set project <<YOUR_PROJECT_ID>>
export PROJECT_ID=$(gcloud config get-value project)
- Clone the codelab repository and navigate to the scripts folder:
cd ~/
git clone --filter=blob:none --no-checkout https://github.com/GoogleCloudPlatform/devrel-demos.git
cd ~/devrel-demos
git sparse-checkout init --cone
git sparse-checkout set codelabs/agentic-data-labs/data-science
git checkout main
cd codelabs/agentic-data-labs/data-science/scripts
- Run the bootstrap setup script to deploy all resources to
us-central1:
chmod +x setup.sh setup_spanner.sh setup_composer.sh
export REGION=us-central1
./setup.sh
- When the script finishes, you will see a summary output indicating that your BigQuery dataset and Cloud Storage bucket are ready. In the background, Cloud Spanner (takes ~2 minutes) and Managed Airflow (takes ~20 minutes) will continue provisioning. You can monitor their progress at any time by running:
tail -f /tmp/spanner_setup.log
tail -f /tmp/composer_setup.log
Open the Antigravity IDE
- Download and install the Antigravity IDE from the Google Antigravity download page .
- Launch the Antigravity IDE .
- Create a new, empty folder on your local machine (eg named
agentic-data-labs), and open it in the IDE by choosing Open Folder . This will act as your local workspace for the codelab.
Install the Data Agent Kit extension
The Google Cloud Data Agent Kit extension provides deep integration with Google Cloud data services directly within your editor, allowing you to interact with BigQuery, Cloud SQL, Cloud Storage, and more without switching contexts.
- In the Antigravity IDE, click the Extensions icon in the Activity Bar on the far left side of the screen (it looks like four squares).
- In the search bar at the top of the Extensions pane, type
Google Cloud Data Agent Kit. - Locate the extension named Google Cloud Data Agent Kit published by
googlecloudtools - ইনস্টল বোতামে ক্লিক করুন।
- A prompt may appear asking, "Do you trust publisher 'googlecloudtools' and their extensions?". Click Trust Publishers & Install to proceed.
Once installed, you'll see a new Google Cloud Data Agent Kit icon appear in the Activity Bar on the far left of the Antigravity IDE.
- An onboarding page titled "Welcome to Google Cloud Data Agent Kit" should automatically open. If you aren't signed into your Cloud account, follow any prompts to allow access.
- In the Configuration Summary section, locate the project field. Click the dropdown and select your Google Cloud project. Set your region as
us-central1. Then select Configure MCP Servers .
- Select Configure MCP Servers . Under the MCP Configuration pane, ensure you enable the following remote MCP servers:
- বিগকোয়েরি
- স্প্যানার
- নোটবুক
Then click Get Started .
Explore configuration options
Once setup is complete, you'll land on the "Get started with Google Cloud Data Agent Kit" page.
- Under "Setup & Configuration", click Get Started .
- This opens the Data Agent Kit Configuration panel. Explore the tabs:
- Project and Region: Verify your selected Project ID and confirm that the setup script enabled all requisite APIs (Compute Engine, Cloud Storage, BigQuery, Spanner, etc.).
- BigQuery: Configure the default location for your BigQuery queries. Use the region
us-central1. - Configure MCP Servers: View the enabled MCP servers (BigQuery, Notebooks, Spanner, etc.) that allow AI agents to securely interact with your data.
- Skills: Explore pre-built skills that provide agents with specialized capabilities for complex data tasks.
Section Recap: You ran the bootstrap script to create GCS and BigQuery assets while Spanner and Airflow build in the background. You then opened the project in the Antigravity IDE and activated the Google Cloud Data Agent Kit extension. You are now ready to write your first notebook.
3. Ingest raw logs using Spark Serverless
In this section, you will ingest raw JSON transaction logs into the data lake. Managed Service for Apache Spark (Spark Serverless) connects directly with BigQuery 's native storage. You will use the standard BigQuery connector to manage tabular data and enable direct querying and analytics.
Explore the pre-configured Spark Serverless runtime
Before executing Spark code, inspect the Serverless Runtime template that was pre-configured by the setup script. This template defines the target execution environment backend and bundles necessary connector dependencies.
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the Apache Spark drop-down menu, then expand Serverless .
- Right-click
fraud-pipeline-runtimeand select Profile to open its configuration view in the editor. - In the Profile tab, scroll down and expand Properties to inspect the custom dependencies attached to the environment:
-
spark.jars: Containsgs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jar, which uses the Spark Spanner connector to allow Spark jobs to write inference results directly to Cloud Spanner later in the lab. (Note: Dataproc Serverless includes Google Cloud's Spark BigQuery connector by default, requiring no additional jar configuration to read and write BigQuery tables).
-
- Notice the Interactive Sessions tab on the left. It is currently empty because you have not executed any code yet. As soon as you run the notebook in the next step, a live serverless compute session will dynamically provision and appear here!
Ingest data using the Data Agent Kit
Instead of manually configuring a Spark Session or writing PySpark loading scripts from scratch, you will pair-program with an agent using the Data Agent Kit.
- Open the Agent Chat pane by clicking the Toggle Agent icon in the top-right toolbar.
- Paste the following prompt into the chat (be sure to replace
${PROJECT_ID}with your actual Google Cloud Project ID):
Create a PySpark notebook (01_ingestion.ipynb) to ingest JSON transaction logs
from gs://${PROJECT_ID}-fin-clearing-raw/ into a BigQuery table
`${PROJECT_ID}.transactions_dataset_evals.raw_transactions`
using the Spark BigQuery connector (`format("bigquery")`) with overwrite mode.
- If the agent asks for permission to execute background verification commands (eg "Allow running this command?" ), review the proposed command and select Yes, allow this time (or Yes, and always allow ).
- When the agent finishes generating the file, click the blue Accept all button (or the checkmark icon) at the bottom of the chat pane to save
notebooks/01_ingestion.ipynbto your workspace.
Review and execute the notebook
- Open the newly generated
notebooks/01_ingestion.ipynbin the IDE. - Review the PySpark code for the BigQuery connector write logic.
- Click Run All in the IDE's notebook toolbar.
- If this is your first time running a remote Spark notebook, the IDE may prompt you to install local dependencies. If prompted, click Install dependencies for Remote Spark Kernels and confirm the installation dialogs, then click Run All again.
- In the Select Kernel dropdown menu, choose Remote Spark Kernels -> fraud-pipeline-runtime on Serverless Spark . (Tip: If you do not see your pre-configured runtime template listed, click the refresh icon in the top right of the kernel picker dropdown to reload available remote kernels).
- Look at the status bar in the bottom left of the editor. You will see
Connecting to kernel: fraud-pipeline-runtime on Serverless Spark.... Because this is the initial launch of the Spark Serverless runtime kernel backend, it will take a few minutes to provision and boot up. - Once the kernel finishes connecting, the notebook will automatically begin executing all cells sequentially to process the raw transaction logs into your BigQuery dataset.
যাচাইকরণ
Once execution completes, check the Data Agent Kit catalog to verify the table creation:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the CATALOG section.
- Expand your project ID.
- Expand BigQuery .
- Expand the
transactions_dataset_evalsdataset. - Click the
raw_transactionstable to open its detail view in the main editor. - In the left navigation, explore the Data , Schema , and Details tabs to inspect the ingested records and metadata.
Section Recap: You used natural language in the Agent Chat to generate a complete Spark Serverless workload. You then executed it to process unstructured JSON logs into a BigQuery (raw) table.
4. Deduplicate and normalize with dbt
Before training the ML model, you will enforce data quality by removing duplicate streaming logs, isolating bad records (such as empty transaction IDs), and joining dimensional data (payers and payees). This process requires idempotent, reliable SQL transformations, making dbt (data build tool) a great fit.
Scaffold the dbt pipeline
Use the agent to generate a dbt project over the BigQuery dataset:
- Return to the Agent Chat pane.
- Provide the following instruction to generate the dbt project:
Scaffold a us-central1 dbt project in dbt_project/ that maps raw_transactions
through to an enriched_transactions model in dataset transactions_dataset_evals.

Deduplicate by transaction_id in staging. Quarantine null IDs to an invalid_transactions model.
Join the valid staging records with dim_payers and dim_payees for the enriched_transactions model,
preserving the historical `is_fraud` label column, and finally add a transaction uniqueness test.

Create an implementation plan first.
- The agent will present an Implementation Plan artifact in the main editor pane. Review the proposed file structure and SQL logic.
- Click Proceed (and then Accept all ) to allow the agent to generate the files in your workspace.
- Once generation completes, the agent displays a Walkthrough summarizing the new components. Accept all changes if prompted.
তৈরি করুন এবং পরীক্ষা করুন
Although the agent automatically ran dbt compile to ensure the generated SQL was syntactically valid, you will now materialize these views and tables into BigQuery and run the data quality tests for local verification. (Note: Later in the lab, you will automate this dbt step as part of an end-to-end Airflow DAG).
- In the activity bar on the far left, click the Explorer icon (or press
Cmd/Ctrl+Shift+E). - Expand
dbt_project->modelsto inspect the generated SQL models. Click onenriched_transactions.sqlto open and review the transformation and fraud feature logic in the editor. - In the File Explorer, right-click the
dbt_projectfolder and select Open in Integrated Terminal . This automatically opens a terminal pane set directly to the requireddbt_projectworking directory. - If you do not already have
dbtinstalled, create a virtual environment outsidedbt_project/(at your home or workspace root) and install the BigQuery adapter:
python3 -m venv ~/.venv/dbt
source ~/.venv/dbt/bin/activate
pip install dbt-bigquery
- Run the dbt models and their associated data quality tests:
dbt build
- Watch the terminal output. dbt will compile the SQL, materialize the staging and enriched tables in BigQuery, and execute the data tests.
- Once the build finishes, close the terminal pane to free up screen space for the remaining steps.
Section Recap: You generated a dbt project with the agent, ran data quality tests, and transformed the raw records into staging and enriched BigQuery tables.
5. Train distributed fraud detection model with Random Forest
With the enriched transactions materialized in BigQuery, you will build a machine learning model to classify fraudulent events. Random Forest is an ensemble learning method well-suited for tabular classification data. Running a RandomForestClassifier on Spark Serverless distributes model training across worker nodes without requiring you to manage infrastructure.
In this step, you will use the agent to generate the Spark ML training pipeline.
Generate the ML training notebook
- Open the Agent Chat pane.
- Provide the following prompt to design the model training sequence (remember to replace
${PROJECT_ID}with your active project ID):
Create a PySpark notebook (02_training.ipynb) to train a distributed Random Forest
(RandomForestClassifier) model on the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`, predicting the `is_fraud` label.
Train only on historically labeled records where `is_fraud` is not null.

One-hot encode categorical strings, scale amounts, cache the dataset in memory,
evaluate AUC, and save the evaluated model to gs://${PROJECT_ID}-models/fraud_model.
- Review the agent's plan or generated code and click Proceed / Accept all to save
notebooks/02_training.ipynbto your workspace.
Review and execute the notebook
- Open
notebooks/02_training.ipynbin the editor. - Review the PySpark ML pipeline stages for feature encoding, vector assembly, and Random Forest classification logic.
- Click Run All in the IDE's notebook toolbar.
- When the Select Kernel dropdown picker opens, select fraud-pipeline-runtime on Serverless Spark .
যাচাইকরণ
Once execution completes, confirm the model was trained and exported correctly:
- Review the evaluation cell outputs near the bottom of the notebook to verify the reported Area Under ROC (AUC) score.
- To ensure the model artifacts were successfully saved to GCS, expand the STORAGE explorer pane in the Data Agent Kit sidebar.
- Locate the bucket ending in
-models(tied to your active Project ID), expand it, and drill down to verify thefraud_modeldirectory and its pipeline stages exist.
Section Recap: You used the agent to create a PySpark ML training pipeline, trained a Random Forest model on your enriched BigQuery table, and exported the model to Cloud Storage.
6. Batch inference and Cloud Spanner write
With a trained predictive model stored in Cloud Storage, you will run batch inference on new transactions flowing through BigQuery. High-risk transactions need to be routed to an operational system so that a compliance team can review them. Cloud Spanner provides a scalable transactional database for this review queue.
Generate the batch inference notebook
Use the agent to create an inference notebook connecting BigQuery, Cloud Storage, and Cloud Spanner:
- Open the Agent Chat pane.
- Provide the following prompt:
Create an inference notebook (03_inference.ipynb) that loads the RandomForestClassifier
model to score unlabeled records (where `is_fraud` is null) from the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`.

Filter for high-risk transactions with a 50%+ fraud probability score (probability >= 0.50)
and write them to the Cloud Spanner table SparkEvalFraudReviewQueue in the cymbal-fraud instance
under fraud-db.
- Accept the generated notebook to save
notebooks/03_inference.ipynbto your workspace.
Review and execute the notebook
- Open the newly generated
notebooks/03_inference.ipynbin the editor. - Review the PySpark inference sequence:
- Dependencies: The Serverless Runtime template provides the required
cloud-spannerJAR dependencies for Spark execution. - Data Formatting: The script drops complex Spark ML vector columns (such as raw features and probabilities) before writing to match the Spanner table schema.
- Spanner Connector: It writes the flagged rows using
.format("cloud-spanner")to append directly to the review queue.
- Dependencies: The Serverless Runtime template provides the required
- Click Run All in the IDE's notebook toolbar.
- When prompted to select a kernel, select fraud-pipeline-runtime on Serverless Spark .
যাচাইকরণ
Once the inference notebook finishes processing, you can query your operational Spanner database directly inside the IDE:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the CATALOG section.
- Expand your project ID, then expand Spanner .
- Navigate to
cymbal-fraud->fraud-db->Tables->SparkEvalFraudReviewQueue. - Right-click the table and select Query Table , then execute the query:
SELECT *
FROM `SparkEvalFraudReviewQueue`
LIMIT 100;
- In the Query Results pane below, you should see newly inserted rows representing high-risk transactions flagged for manual review.
Section Recap: You used the agent to create a batch inference notebook, scored unlabeled BigQuery records with your trained model, and wrote high-risk transactions directly to Cloud Spanner.
7. Scaffold and orchestrate with Managed Airflow
Your pipeline currently consists of discrete steps: an ingestion notebook, a dbt transformation project, and a batch inference notebook. To make this production-ready, you will stitch them together into a scheduled dependency graph.
Managed Service for Apache Airflow (formerly known as Cloud Composer) provides a managed orchestration engine for this workflow. The Data Agent Kit includes an Orchestration Pipelines feature that translates declarative YAML pipeline definitions directly into Airflow DAGs.
Define the pipeline
Use the agent to generate the orchestration pipeline configuration:
- In the Agent Chat , provide the following prompt (remembering to replace
${PROJECT_ID}):
Initialize and define an orchestration pipeline (fraud_analysis_pipeline) triggering
the ingestion notebook, dbt project, and inference notebook in sequential order.
For Dataproc Serverless engine configs in us-central1, use resourceProfile.inline
(defining properties with spark.jars: "gs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jar"
for inference) rather than resourceProfile.path or overrides.

Set the schedule interval to run daily at midnight, and use
gs://${PROJECT_ID}-airflow-artifacts for artifact storage.
Review the DAG configuration
The Data Agent Kit Orchestrator uses declarative YAML configurations to define and deploy pipelines to Apache Airflow, allowing definitions to be version controlled and deployed via CI/CD.
In the IDE Explorer pane, review the two pipeline files the agent generated at the root of your workspace:
-
deployment.yaml: Open this file. This serves as your environment registry. It maps your logicaldevpipeline to thecymbal-airflowenvironment, sets the execution region (us-central1), and defines theartifact_storagebucket where compiled DAGs and dependencies are staged. -
fraud_analysis_pipeline.yaml: Open this file. This defines the execution graph. It specifies the trigger schedule (interval: '0 0 * * *') and sequences the three steps under theactionsblock:- An ingestion
notebookaction for01_ingestion.ipynbrunning on Dataproc Serverless. - A transformation
pipelineaction targeting thedbt_projectdirectory, with adependsOndependency pointing to the ingestion step. - An inference
notebookaction for03_inference.ipynbwith adependsOndependency pointing to the dbt step, bundling the Spanner JAR property.
- An ingestion
- The agent will also summarize these generated artifacts into a Walkthrough tab in your editor pane, outlining the configurations and validations performed.
Interactive DAG configuration
The Data Agent Kit renders your pipeline configuration as an interactive visual graph for inspecting and editing Airflow DAG properties.
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Under
DATA ENGINEERING, expandOrchestration Pipelines. - Click
fraud_analysis_pipeline.yamlto open the visual DAG canvas in the main editor.
- Click the
Schedule triggernode at the top. A configuration flyout opens on the right, displaying the parsed Cron string (0 0 * * *) and allowing you to adjust parameters like backfill and catchup. - Click either notebook task node (such as the ingestion or inference step). The flyout updates to display the specific Dataproc Serverless execution mappings and connector properties.
- Notice the notebook filename hyperlink (such as
01_ingestion.ipynb) inside the node block. Clicking it opens the notebook directly in your editor. - In the left sidebar underneath Orchestration Pipelines, click
Deployment configuration. This view shows your targetdevenvironment cluster and output GCS bucket artifacts.
Section Recap: You generated an orchestration pipeline configuration with the agent, defining dependencies between ingestion, dbt, and inference tasks in an interactive visual canvas.
8. Deploy, execute, and monitor
With the DAG defined locally, you will connect to the Managed Airflow environment provisioned during setup and deploy the pipeline.
Configure Managed Service for Apache Airflow
Before deploying, configure the Scheduler connection in the Data Agent Kit settings so the extension targets your Managed Airflow environment:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Under
SETTINGS, click Settings . - Select Scheduler from the left menu.
- সেটিংসগুলো কনফিগার করুন:
- Project ID : Select your active project ID.
- Region : Select
us-central1. - Environment : Select
cymbal-airflow.
- সংরক্ষণ করুন- এ ক্লিক করুন।
Deploy the DAG
You will now deploy the configured pipeline directly to your Managed Airflow environment from the visual canvas:
- In the Google Cloud Data Agent Kit sidebar, expand
DATA ENGINEERING>Orchestration Pipelinesand clickfraud_analysis_pipeline.yamlto open the visual DAG canvas. - In the top right corner of the canvas toolbar, click the blue Run pipeline button.
- In the environment dropdown picker, select
dev. - Observe the progress notification in the bottom status area (
Running pipeline: Building pipeline locally...). The extension will automatically compile your DAG, package the notebook and dbt assets, and upload them to your Managed Airflow environment's GCS bucket (this takes about 3–4 minutes to complete).
Monitor the run
Once local compilation completes and the popup notification confirms Triggered a new run for pipeline... successfully , monitor the live execution:
- In the Google Cloud Data Agent Kit sidebar, expand
DATA ENGINEERING>Orchestration Pipelines. - Click Pipelines management .
- In the Pipelines Management table, click on
fraud_analysis_pipelineto open its execution history.
- In the Execution History view, select the active run from the calendar.
- As the execution progresses across each pipeline task (ingestion, dbt transformation, and inference), status indicators update and task durations populate. Click any task to inspect its live execution output and Airflow DAG logs.
Section Recap: You configured the Airflow Scheduler connection, deployed your end-to-end analytical pipeline to Managed Airflow, and monitored a live execution, verifying the system from raw logs to final Cloud Spanner predictions.
৯. পরিষ্কার করুন
To avoid incurring ongoing charges to your Google Cloud project for the resources used in this codelab, tear down the environment using the automated script.
- In the Terminal panel (or in Cloud Shell), navigate to the scripts directory and execute:
cd ~/devrel-demos/codelabs/agentic-data-labs/data-science/scripts
chmod +x teardown.sh
./teardown.sh
- The script will list all the resources it plans to delete and prompt for confirmation:
- Managed Airflow Environment (
cymbal-airflow) - Cloud Spanner Instance (
cymbal-fraud) - BigQuery Dataset (
transactions_dataset_evals) - Cloud Storage Buckets (
gs://${PROJECT_ID}-fin-clearing-rawandgs://${PROJECT_ID}-models) - Worker Service Account (
composer-worker-sa)
- Managed Airflow Environment (
- Type
yto confirm. The teardown script will remove all provisioned GCP services and clean up local files.
10. Congratulations!
You have built an end-to-end fraud detection pipeline spanning Cloud Storage, BigQuery, Managed Service for Apache Spark (Spark Serverless), dbt, Cloud Spanner, and Managed Service for Apache Airflow, pair-programming with the Google Cloud Data Agent Kit inside the Antigravity IDE.
What you accomplished
- 📥 Ingested raw transaction logs into a BigQuery table using Managed Service for Apache Spark and the Data Agent Kit.
- 🧹 Deduplicated and normalized data by creating a dbt project with data quality tests.
- 🤖 Trained a distributed Random Forest model using
RandomForestClassifierand exported the trained model to Cloud Storage. - ⚡ Executed batch inference on incoming transactions and routed high-risk records into Cloud Spanner for audit review.
- 🔄 Orchestrated, deployed, and monitored the workflow as a scheduled Airflow DAG using Managed Service for Apache Airflow and the IDE's visual DAG management tools.
মূল ধারণা
ধারণা | আপনি যা শিখেছেন |
Pair-programming inside the IDE using natural language to generate PySpark notebooks, configure dbt models, and define Airflow DAGs | |
Scalable tabular storage for analytical SQL, dbt transformations, and ML training | |
Serverless execution for distributed PySpark data loading and Random Forest ML training | |
Writing batch Spark inference predictions directly into operational database review queues | |
YAML DAG Declarations | Declarative pipeline definitions rendered as interactive Airflow visual graphs in the IDE |
Visual DAG Management | Inspecting pipeline dependencies, deploying to Managed Airflow , and monitoring live task execution history inside the IDE |
পরবর্তী পদক্ষেপ
- Explore the Google Cloud Data Agent Kit documentation
- Learn more about Managed Service for Apache Spark
- Learn more about Managed Service for Apache Airflow
- Build your own multi-service pipelines using the Antigravity IDE
১. ভূমিকা
Imagine you are a Data Scientist at Cymbal Financial , a high-volume payment processor. A wave of settlement delays has occurred, and the compliance team suspects coordinated fraud. You need to build a pipeline to ingest raw clearinghouse transaction logs, clean the data, train a machine learning model, run batch inference, and sink high-risk transactions into a Cloud Spanner review queue for manual auditing.
Normally, this requires days of writing repetitive setup code (Spark notebooks, dbt configurations, training scripts, Airflow DAGs) and constant context-switching between console interfaces and editors.
In this codelab, you will pair-program with an agent using the Google Cloud Data Agent Kit (DAK) inside the Antigravity IDE . Using conversational natural language, the agent will help you generate Spark notebooks, compile a dbt project, construct an inference loop, and orchestrate the workflow using the Managed Service for Apache Airflow .
আপনি যা করবেন
- Ingest clearinghouse logs from Cloud Storage using Managed Service for Apache Spark (Spark Serverless) into a BigQuery table.
- Deduplicate and normalize transactions using dbt to establish clean data layers (Raw, Staging, Enriched).
- Train a distributed Random Forest classification model (
RandomForestClassifier) on Spark Serverless. - Run batch inference on new transactions and write high-risk alerts directly to Cloud Spanner .
- Orchestrate, visually configure, and deploy the entire pipeline using Managed Service for Apache Airflow and interactive DAG monitoring inside the IDE.
আপনার যা যা লাগবে
- ক্রোমের মতো একটি ওয়েব ব্রাউজার
- A Google Cloud project with billing enabled (we recommend using a new, dedicated project for hands-on labs).
- Basic familiarity with SQL, Python, and PySpark.
- Antigravity IDE with a Google AI Pro subscription (recommended)
The resources created in this codelab should cost less than $5. Be sure to follow the Clean Up instructions at the end of the lab to delete provisioned resources.
2. Environment setup
To kick off the lab, you will run a bootstrap script. This script automatically enables required GCP APIs, creates an ingestion Cloud Storage bucket, generates mock transaction and directory datasets, loads reference directories into BigQuery, and kicks off background provisioning of Cloud Spanner and Managed Service for Apache Airflow (formerly known as Cloud Composer).
একটি প্রকল্প নির্বাচন করুন বা তৈরি করুন
Choose an existing project or create a new project in the Google Cloud Console.
বিলিং যাচাই করুন
আপনার গুগল ক্লাউড প্রোজেক্টের জন্য বিলিং চালু আছে কিনা তা নিশ্চিত করুন। কীভাবে এটি করতে হয়, তা জানতে এই নির্দেশিকাটি অনুসরণ করতে পারেন।
Run the setup script
You will use Google Cloud Shell (or your local shell configured with the Google Cloud CLI) to launch the environment setup.
- গুগল ক্লাউড কনসোল খুলুন।
- Click Activate Cloud Shell in the top-right toolbar.
- In the Cloud Shell terminal, configure your active project:
gcloud config set project <<YOUR_PROJECT_ID>>
export PROJECT_ID=$(gcloud config get-value project)
- Clone the codelab repository and navigate to the scripts folder:
cd ~/
git clone --filter=blob:none --no-checkout https://github.com/GoogleCloudPlatform/devrel-demos.git
cd ~/devrel-demos
git sparse-checkout init --cone
git sparse-checkout set codelabs/agentic-data-labs/data-science
git checkout main
cd codelabs/agentic-data-labs/data-science/scripts
- Run the bootstrap setup script to deploy all resources to
us-central1:
chmod +x setup.sh setup_spanner.sh setup_composer.sh
export REGION=us-central1
./setup.sh
- When the script finishes, you will see a summary output indicating that your BigQuery dataset and Cloud Storage bucket are ready. In the background, Cloud Spanner (takes ~2 minutes) and Managed Airflow (takes ~20 minutes) will continue provisioning. You can monitor their progress at any time by running:
tail -f /tmp/spanner_setup.log
tail -f /tmp/composer_setup.log
Open the Antigravity IDE
- Download and install the Antigravity IDE from the Google Antigravity download page .
- Launch the Antigravity IDE .
- Create a new, empty folder on your local machine (eg named
agentic-data-labs), and open it in the IDE by choosing Open Folder . This will act as your local workspace for the codelab.
Install the Data Agent Kit extension
The Google Cloud Data Agent Kit extension provides deep integration with Google Cloud data services directly within your editor, allowing you to interact with BigQuery, Cloud SQL, Cloud Storage, and more without switching contexts.
- In the Antigravity IDE, click the Extensions icon in the Activity Bar on the far left side of the screen (it looks like four squares).
- In the search bar at the top of the Extensions pane, type
Google Cloud Data Agent Kit. - Locate the extension named Google Cloud Data Agent Kit published by
googlecloudtools - ইনস্টল বোতামে ক্লিক করুন।
- A prompt may appear asking, "Do you trust publisher 'googlecloudtools' and their extensions?". Click Trust Publishers & Install to proceed.
Once installed, you'll see a new Google Cloud Data Agent Kit icon appear in the Activity Bar on the far left of the Antigravity IDE.
- An onboarding page titled "Welcome to Google Cloud Data Agent Kit" should automatically open. If you aren't signed into your Cloud account, follow any prompts to allow access.
- In the Configuration Summary section, locate the project field. Click the dropdown and select your Google Cloud project. Set your region as
us-central1. Then select Configure MCP Servers .
- Select Configure MCP Servers . Under the MCP Configuration pane, ensure you enable the following remote MCP servers:
- বিগকোয়েরি
- স্প্যানার
- নোটবুক
Then click Get Started .
Explore configuration options
Once setup is complete, you'll land on the "Get started with Google Cloud Data Agent Kit" page.
- Under "Setup & Configuration", click Get Started .
- This opens the Data Agent Kit Configuration panel. Explore the tabs:
- Project and Region: Verify your selected Project ID and confirm that the setup script enabled all requisite APIs (Compute Engine, Cloud Storage, BigQuery, Spanner, etc.).
- BigQuery: Configure the default location for your BigQuery queries. Use the region
us-central1. - Configure MCP Servers: View the enabled MCP servers (BigQuery, Notebooks, Spanner, etc.) that allow AI agents to securely interact with your data.
- Skills: Explore pre-built skills that provide agents with specialized capabilities for complex data tasks.
Section Recap: You ran the bootstrap script to create GCS and BigQuery assets while Spanner and Airflow build in the background. You then opened the project in the Antigravity IDE and activated the Google Cloud Data Agent Kit extension. You are now ready to write your first notebook.
3. Ingest raw logs using Spark Serverless
In this section, you will ingest raw JSON transaction logs into the data lake. Managed Service for Apache Spark (Spark Serverless) connects directly with BigQuery 's native storage. You will use the standard BigQuery connector to manage tabular data and enable direct querying and analytics.
Explore the pre-configured Spark Serverless runtime
Before executing Spark code, inspect the Serverless Runtime template that was pre-configured by the setup script. This template defines the target execution environment backend and bundles necessary connector dependencies.
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the Apache Spark drop-down menu, then expand Serverless .
- Right-click
fraud-pipeline-runtimeand select Profile to open its configuration view in the editor. - In the Profile tab, scroll down and expand Properties to inspect the custom dependencies attached to the environment:
-
spark.jars: Containsgs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jar, which uses the Spark Spanner connector to allow Spark jobs to write inference results directly to Cloud Spanner later in the lab. (Note: Dataproc Serverless includes Google Cloud's Spark BigQuery connector by default, requiring no additional jar configuration to read and write BigQuery tables).
-
- Notice the Interactive Sessions tab on the left. It is currently empty because you have not executed any code yet. As soon as you run the notebook in the next step, a live serverless compute session will dynamically provision and appear here!
Ingest data using the Data Agent Kit
Instead of manually configuring a Spark Session or writing PySpark loading scripts from scratch, you will pair-program with an agent using the Data Agent Kit.
- Open the Agent Chat pane by clicking the Toggle Agent icon in the top-right toolbar.
- Paste the following prompt into the chat (be sure to replace
${PROJECT_ID}with your actual Google Cloud Project ID):
Create a PySpark notebook (01_ingestion.ipynb) to ingest JSON transaction logs
from gs://${PROJECT_ID}-fin-clearing-raw/ into a BigQuery table
`${PROJECT_ID}.transactions_dataset_evals.raw_transactions`
using the Spark BigQuery connector (`format("bigquery")`) with overwrite mode.
- If the agent asks for permission to execute background verification commands (eg "Allow running this command?" ), review the proposed command and select Yes, allow this time (or Yes, and always allow ).
- When the agent finishes generating the file, click the blue Accept all button (or the checkmark icon) at the bottom of the chat pane to save
notebooks/01_ingestion.ipynbto your workspace.
Review and execute the notebook
- Open the newly generated
notebooks/01_ingestion.ipynbin the IDE. - Review the PySpark code for the BigQuery connector write logic.
- Click Run All in the IDE's notebook toolbar.
- If this is your first time running a remote Spark notebook, the IDE may prompt you to install local dependencies. If prompted, click Install dependencies for Remote Spark Kernels and confirm the installation dialogs, then click Run All again.
- In the Select Kernel dropdown menu, choose Remote Spark Kernels -> fraud-pipeline-runtime on Serverless Spark . (Tip: If you do not see your pre-configured runtime template listed, click the refresh icon in the top right of the kernel picker dropdown to reload available remote kernels).
- Look at the status bar in the bottom left of the editor. You will see
Connecting to kernel: fraud-pipeline-runtime on Serverless Spark.... Because this is the initial launch of the Spark Serverless runtime kernel backend, it will take a few minutes to provision and boot up. - Once the kernel finishes connecting, the notebook will automatically begin executing all cells sequentially to process the raw transaction logs into your BigQuery dataset.
যাচাইকরণ
Once execution completes, check the Data Agent Kit catalog to verify the table creation:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the CATALOG section.
- Expand your project ID.
- Expand BigQuery .
- Expand the
transactions_dataset_evalsdataset. - Click the
raw_transactionstable to open its detail view in the main editor. - In the left navigation, explore the Data , Schema , and Details tabs to inspect the ingested records and metadata.
Section Recap: You used natural language in the Agent Chat to generate a complete Spark Serverless workload. You then executed it to process unstructured JSON logs into a BigQuery (raw) table.
4. Deduplicate and normalize with dbt
Before training the ML model, you will enforce data quality by removing duplicate streaming logs, isolating bad records (such as empty transaction IDs), and joining dimensional data (payers and payees). This process requires idempotent, reliable SQL transformations, making dbt (data build tool) a great fit.
Scaffold the dbt pipeline
Use the agent to generate a dbt project over the BigQuery dataset:
- Return to the Agent Chat pane.
- Provide the following instruction to generate the dbt project:
Scaffold a us-central1 dbt project in dbt_project/ that maps raw_transactions
through to an enriched_transactions model in dataset transactions_dataset_evals.

Deduplicate by transaction_id in staging. Quarantine null IDs to an invalid_transactions model.
Join the valid staging records with dim_payers and dim_payees for the enriched_transactions model,
preserving the historical `is_fraud` label column, and finally add a transaction uniqueness test.

Create an implementation plan first.
- The agent will present an Implementation Plan artifact in the main editor pane. Review the proposed file structure and SQL logic.
- Click Proceed (and then Accept all ) to allow the agent to generate the files in your workspace.
- Once generation completes, the agent displays a Walkthrough summarizing the new components. Accept all changes if prompted.
তৈরি করুন এবং পরীক্ষা করুন
Although the agent automatically ran dbt compile to ensure the generated SQL was syntactically valid, you will now materialize these views and tables into BigQuery and run the data quality tests for local verification. (Note: Later in the lab, you will automate this dbt step as part of an end-to-end Airflow DAG).
- In the activity bar on the far left, click the Explorer icon (or press
Cmd/Ctrl+Shift+E). - Expand
dbt_project->modelsto inspect the generated SQL models. Click onenriched_transactions.sqlto open and review the transformation and fraud feature logic in the editor. - In the File Explorer, right-click the
dbt_projectfolder and select Open in Integrated Terminal . This automatically opens a terminal pane set directly to the requireddbt_projectworking directory. - If you do not already have
dbtinstalled, create a virtual environment outsidedbt_project/(at your home or workspace root) and install the BigQuery adapter:
python3 -m venv ~/.venv/dbt
source ~/.venv/dbt/bin/activate
pip install dbt-bigquery
- Run the dbt models and their associated data quality tests:
dbt build
- Watch the terminal output. dbt will compile the SQL, materialize the staging and enriched tables in BigQuery, and execute the data tests.
- Once the build finishes, close the terminal pane to free up screen space for the remaining steps.
Section Recap: You generated a dbt project with the agent, ran data quality tests, and transformed the raw records into staging and enriched BigQuery tables.
5. Train distributed fraud detection model with Random Forest
With the enriched transactions materialized in BigQuery, you will build a machine learning model to classify fraudulent events. Random Forest is an ensemble learning method well-suited for tabular classification data. Running a RandomForestClassifier on Spark Serverless distributes model training across worker nodes without requiring you to manage infrastructure.
In this step, you will use the agent to generate the Spark ML training pipeline.
Generate the ML training notebook
- Open the Agent Chat pane.
- Provide the following prompt to design the model training sequence (remember to replace
${PROJECT_ID}with your active project ID):
Create a PySpark notebook (02_training.ipynb) to train a distributed Random Forest
(RandomForestClassifier) model on the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`, predicting the `is_fraud` label.
Train only on historically labeled records where `is_fraud` is not null.

One-hot encode categorical strings, scale amounts, cache the dataset in memory,
evaluate AUC, and save the evaluated model to gs://${PROJECT_ID}-models/fraud_model.
- Review the agent's plan or generated code and click Proceed / Accept all to save
notebooks/02_training.ipynbto your workspace.
Review and execute the notebook
- Open
notebooks/02_training.ipynbin the editor. - Review the PySpark ML pipeline stages for feature encoding, vector assembly, and Random Forest classification logic.
- Click Run All in the IDE's notebook toolbar.
- When the Select Kernel dropdown picker opens, select fraud-pipeline-runtime on Serverless Spark .
যাচাইকরণ
Once execution completes, confirm the model was trained and exported correctly:
- Review the evaluation cell outputs near the bottom of the notebook to verify the reported Area Under ROC (AUC) score.
- To ensure the model artifacts were successfully saved to GCS, expand the STORAGE explorer pane in the Data Agent Kit sidebar.
- Locate the bucket ending in
-models(tied to your active Project ID), expand it, and drill down to verify thefraud_modeldirectory and its pipeline stages exist.
Section Recap: You used the agent to create a PySpark ML training pipeline, trained a Random Forest model on your enriched BigQuery table, and exported the model to Cloud Storage.
6. Batch inference and Cloud Spanner write
With a trained predictive model stored in Cloud Storage, you will run batch inference on new transactions flowing through BigQuery. High-risk transactions need to be routed to an operational system so that a compliance team can review them. Cloud Spanner provides a scalable transactional database for this review queue.
Generate the batch inference notebook
Use the agent to create an inference notebook connecting BigQuery, Cloud Storage, and Cloud Spanner:
- Open the Agent Chat pane.
- Provide the following prompt:
Create an inference notebook (03_inference.ipynb) that loads the RandomForestClassifier
model to score unlabeled records (where `is_fraud` is null) from the BigQuery table
`transactions_dataset_evals`.`enriched_transactions`.

Filter for high-risk transactions with a 50%+ fraud probability score (probability >= 0.50)
and write them to the Cloud Spanner table SparkEvalFraudReviewQueue in the cymbal-fraud instance
under fraud-db.
- Accept the generated notebook to save
notebooks/03_inference.ipynbto your workspace.
Review and execute the notebook
- Open the newly generated
notebooks/03_inference.ipynbin the editor. - Review the PySpark inference sequence:
- Dependencies: The Serverless Runtime template provides the required
cloud-spannerJAR dependencies for Spark execution. - Data Formatting: The script drops complex Spark ML vector columns (such as raw features and probabilities) before writing to match the Spanner table schema.
- Spanner Connector: It writes the flagged rows using
.format("cloud-spanner")to append directly to the review queue.
- Dependencies: The Serverless Runtime template provides the required
- Click Run All in the IDE's notebook toolbar.
- When prompted to select a kernel, select fraud-pipeline-runtime on Serverless Spark .
যাচাইকরণ
Once the inference notebook finishes processing, you can query your operational Spanner database directly inside the IDE:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Expand the CATALOG section.
- Expand your project ID, then expand Spanner .
- Navigate to
cymbal-fraud->fraud-db->Tables->SparkEvalFraudReviewQueue. - Right-click the table and select Query Table , then execute the query:
SELECT *
FROM `SparkEvalFraudReviewQueue`
LIMIT 100;
- In the Query Results pane below, you should see newly inserted rows representing high-risk transactions flagged for manual review.
Section Recap: You used the agent to create a batch inference notebook, scored unlabeled BigQuery records with your trained model, and wrote high-risk transactions directly to Cloud Spanner.
7. Scaffold and orchestrate with Managed Airflow
Your pipeline currently consists of discrete steps: an ingestion notebook, a dbt transformation project, and a batch inference notebook. To make this production-ready, you will stitch them together into a scheduled dependency graph.
Managed Service for Apache Airflow (formerly known as Cloud Composer) provides a managed orchestration engine for this workflow. The Data Agent Kit includes an Orchestration Pipelines feature that translates declarative YAML pipeline definitions directly into Airflow DAGs.
Define the pipeline
Use the agent to generate the orchestration pipeline configuration:
- In the Agent Chat , provide the following prompt (remembering to replace
${PROJECT_ID}):
Initialize and define an orchestration pipeline (fraud_analysis_pipeline) triggering
the ingestion notebook, dbt project, and inference notebook in sequential order.
For Dataproc Serverless engine configs in us-central1, use resourceProfile.inline
(defining properties with spark.jars: "gs://spark-lib/spanner/spark-3.5-spanner-1.4.0.jar"
for inference) rather than resourceProfile.path or overrides.

Set the schedule interval to run daily at midnight, and use
gs://${PROJECT_ID}-airflow-artifacts for artifact storage.
Review the DAG configuration
The Data Agent Kit Orchestrator uses declarative YAML configurations to define and deploy pipelines to Apache Airflow, allowing definitions to be version controlled and deployed via CI/CD.
In the IDE Explorer pane, review the two pipeline files the agent generated at the root of your workspace:
-
deployment.yaml: Open this file. This serves as your environment registry. It maps your logicaldevpipeline to thecymbal-airflowenvironment, sets the execution region (us-central1), and defines theartifact_storagebucket where compiled DAGs and dependencies are staged. -
fraud_analysis_pipeline.yaml: Open this file. This defines the execution graph. It specifies the trigger schedule (interval: '0 0 * * *') and sequences the three steps under theactionsblock:- An ingestion
notebookaction for01_ingestion.ipynbrunning on Dataproc Serverless. - A transformation
pipelineaction targeting thedbt_projectdirectory, with adependsOndependency pointing to the ingestion step. - An inference
notebookaction for03_inference.ipynbwith adependsOndependency pointing to the dbt step, bundling the Spanner JAR property.
- An ingestion
- The agent will also summarize these generated artifacts into a Walkthrough tab in your editor pane, outlining the configurations and validations performed.
Interactive DAG configuration
The Data Agent Kit renders your pipeline configuration as an interactive visual graph for inspecting and editing Airflow DAG properties.
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Under
DATA ENGINEERING, expandOrchestration Pipelines. - Click
fraud_analysis_pipeline.yamlto open the visual DAG canvas in the main editor.
- Click the
Schedule triggernode at the top. A configuration flyout opens on the right, displaying the parsed Cron string (0 0 * * *) and allowing you to adjust parameters like backfill and catchup. - Click either notebook task node (such as the ingestion or inference step). The flyout updates to display the specific Dataproc Serverless execution mappings and connector properties.
- Notice the notebook filename hyperlink (such as
01_ingestion.ipynb) inside the node block. Clicking it opens the notebook directly in your editor. - In the left sidebar underneath Orchestration Pipelines, click
Deployment configuration. This view shows your targetdevenvironment cluster and output GCS bucket artifacts.
Section Recap: You generated an orchestration pipeline configuration with the agent, defining dependencies between ingestion, dbt, and inference tasks in an interactive visual canvas.
8. Deploy, execute, and monitor
With the DAG defined locally, you will connect to the Managed Airflow environment provisioned during setup and deploy the pipeline.
Configure Managed Service for Apache Airflow
Before deploying, configure the Scheduler connection in the Data Agent Kit settings so the extension targets your Managed Airflow environment:
- In the IDE activity bar, open the Google Cloud Data Agent Kit panel.
- Under
SETTINGS, click Settings . - Select Scheduler from the left menu.
- সেটিংসগুলো কনফিগার করুন:
- Project ID : Select your active project ID.
- Region : Select
us-central1. - Environment : Select
cymbal-airflow.
- সংরক্ষণ করুন- এ ক্লিক করুন।
Deploy the DAG
You will now deploy the configured pipeline directly to your Managed Airflow environment from the visual canvas:
- In the Google Cloud Data Agent Kit sidebar, expand
DATA ENGINEERING>Orchestration Pipelinesand clickfraud_analysis_pipeline.yamlto open the visual DAG canvas. - In the top right corner of the canvas toolbar, click the blue Run pipeline button.
- In the environment dropdown picker, select
dev. - Observe the progress notification in the bottom status area (
Running pipeline: Building pipeline locally...). The extension will automatically compile your DAG, package the notebook and dbt assets, and upload them to your Managed Airflow environment's GCS bucket (this takes about 3–4 minutes to complete).
Monitor the run
Once local compilation completes and the popup notification confirms Triggered a new run for pipeline... successfully , monitor the live execution:
- In the Google Cloud Data Agent Kit sidebar, expand
DATA ENGINEERING>Orchestration Pipelines. - Click Pipelines management .
- In the Pipelines Management table, click on
fraud_analysis_pipelineto open its execution history.
- In the Execution History view, select the active run from the calendar.
- As the execution progresses across each pipeline task (ingestion, dbt transformation, and inference), status indicators update and task durations populate. Click any task to inspect its live execution output and Airflow DAG logs.
Section Recap: You configured the Airflow Scheduler connection, deployed your end-to-end analytical pipeline to Managed Airflow, and monitored a live execution, verifying the system from raw logs to final Cloud Spanner predictions.
৯. পরিষ্কার করুন
To avoid incurring ongoing charges to your Google Cloud project for the resources used in this codelab, tear down the environment using the automated script.
- In the Terminal panel (or in Cloud Shell), navigate to the scripts directory and execute:
cd ~/devrel-demos/codelabs/agentic-data-labs/data-science/scripts
chmod +x teardown.sh
./teardown.sh
- The script will list all the resources it plans to delete and prompt for confirmation:
- Managed Airflow Environment (
cymbal-airflow) - Cloud Spanner Instance (
cymbal-fraud) - BigQuery Dataset (
transactions_dataset_evals) - Cloud Storage Buckets (
gs://${PROJECT_ID}-fin-clearing-rawandgs://${PROJECT_ID}-models) - Worker Service Account (
composer-worker-sa)
- Managed Airflow Environment (
- Type
yto confirm. The teardown script will remove all provisioned GCP services and clean up local files.
10. Congratulations!
You have built an end-to-end fraud detection pipeline spanning Cloud Storage, BigQuery, Managed Service for Apache Spark (Spark Serverless), dbt, Cloud Spanner, and Managed Service for Apache Airflow, pair-programming with the Google Cloud Data Agent Kit inside the Antigravity IDE.
What you accomplished
- 📥 Ingested raw transaction logs into a BigQuery table using Managed Service for Apache Spark and the Data Agent Kit.
- 🧹 Deduplicated and normalized data by creating a dbt project with data quality tests.
- 🤖 Trained a distributed Random Forest model using
RandomForestClassifierand exported the trained model to Cloud Storage. - ⚡ Executed batch inference on incoming transactions and routed high-risk records into Cloud Spanner for audit review.
- 🔄 Orchestrated, deployed, and monitored the workflow as a scheduled Airflow DAG using Managed Service for Apache Airflow and the IDE's visual DAG management tools.
মূল ধারণা
ধারণা | আপনি যা শিখেছেন |
Pair-programming inside the IDE using natural language to generate PySpark notebooks, configure dbt models, and define Airflow DAGs | |
Scalable tabular storage for analytical SQL, dbt transformations, and ML training | |
Serverless execution for distributed PySpark data loading and Random Forest ML training | |
Writing batch Spark inference predictions directly into operational database review queues | |
YAML DAG Declarations | Declarative pipeline definitions rendered as interactive Airflow visual graphs in the IDE |
Visual DAG Management | Inspecting pipeline dependencies, deploying to Managed Airflow , and monitoring live task execution history inside the IDE |
পরবর্তী পদক্ষেপ
- Explore the Google Cloud Data Agent Kit documentation
- Learn more about Managed Service for Apache Spark
- Learn more about Managed Service for Apache Airflow
- Build your own multi-service pipelines using the Antigravity IDE