

1. 简介
大多数后端软件实际上不需要 AI 模型来撰写段落,只需要针对一个有界问题提供快速、可靠的回答:是或否?哪个支持团队负责处理此工单?紧急程度如何?
早期专用分类器(例如 TypeSafe AI 的 Jev)最近激发了开发者对“是/否”模型的兴趣,因为它们展示了在放弃缓慢的逐个词元 JSON 生成方式,并改为单次通过对封闭集决策进行评分时,会发生什么情况。
Google DeepMind 的 Gemini Decisions API(由 gemini-decision-1 提供支持)将此功能原生集成到 google-genai SDK 中,让您能够一次性评估多达 1,000 个yes/no (noul)、单选题 (choice) 和有序量表 (score) 问题,并提供校准概率、零输出 token,以及对文本、照片、音频、视频和 PDF 的内置多模态支持。
实践内容
- 设置本地 Python 环境,并使用 Google AI Studio API 密钥连接到
gemini-decision-1。 - 运行各种示例程序,包括工单转派、安全规则和多模态数据决策,帮助您了解 Gemini Decisions API。
学习内容
- 为什么在做出简单的路由决策时,提示对话大语言模型生成 JSON 会导致延迟、费用、解析和置信度问题。
- 三种问题类型:
noul(是/否)、choice(选择一个选项)和score(有序量表)如何在单个client.decisions.create调用中协同工作。 - 如何使用
resolution控制多模态 token 支出,以及如何使用input_tokens_by_modality检查用量。
所需条件
- 在您的机器(或 Google Cloud Shell)上安装了 Python 3.11+ 和
git。 - Google AI Studio 提供的 Gemini API 密钥(此 Codelab 无需设置 Google Cloud 云项目)。
2. 了解 Gemini Decisions API
为什么要求聊天 LLM 提供 JSON 会拖慢后端速度
聊天 LLM 旨在与人进行对话。当你让助理撰写电子邮件或解释错误时,等待几秒钟让文字在屏幕上流式显示,感觉非常自然。
当后端服务使用相同的聊天工作流来做出快速路由决策时,问题就会出现,例如决定将“我的订单 #19028 在哪里?”发送到何处,或者自动执行是否安全。
在这些用例中使用对话模型会导致回答速度过慢、成本高昂,最重要的是,回答不够稳定,导致代理在采取特定行动或朝着特定方向推进时缺乏可靠的信心。
gemini-decision-1 的运作方式
gemini-decision-1 不会逐个词元生成文本,而是会读取输入内容一次,并一次性为所有问题评分,直接返回校准后的概率。
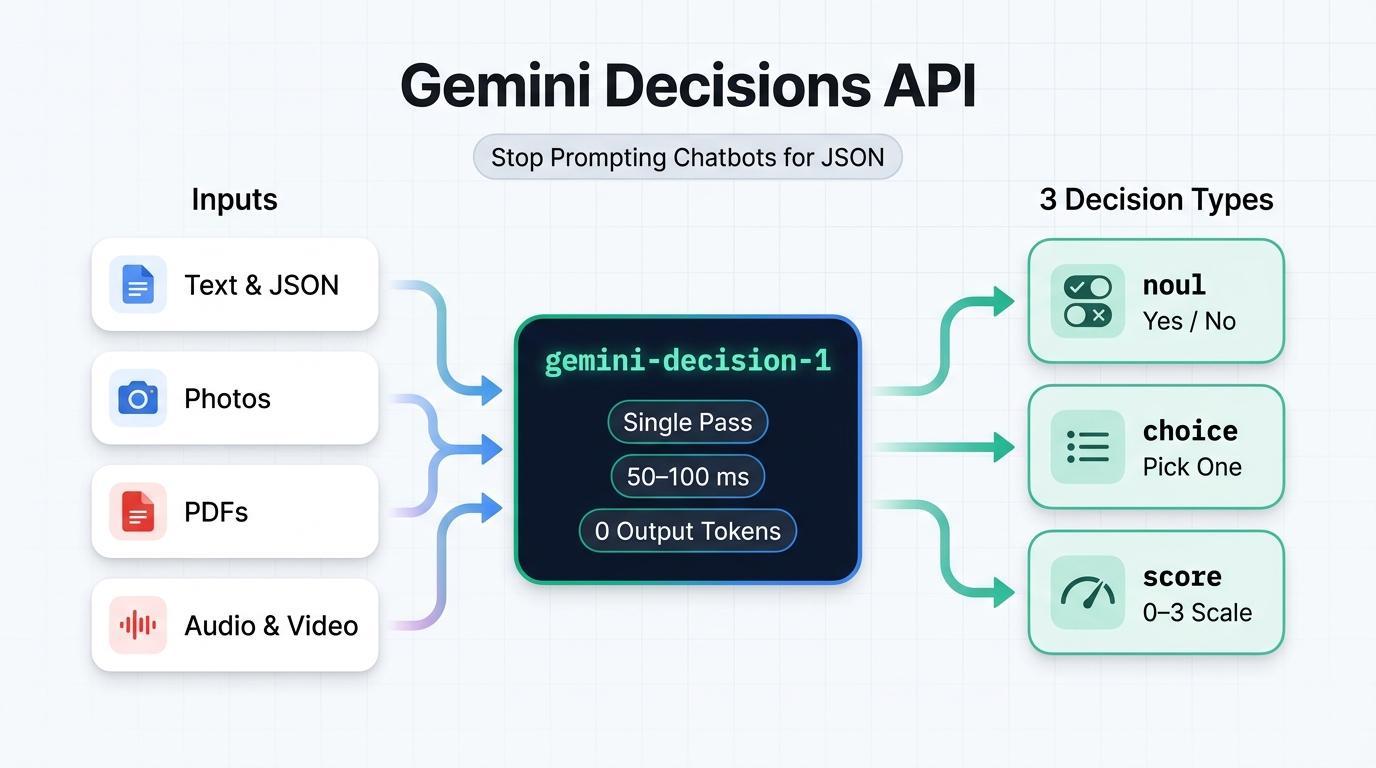
- 零输出 token($0.10 / 100 万输入 token,$0 输出 token):由于模型从不生成文本或思考 token,因此
total_output_tokens始终为0。无论您附加了多少个问题,您的共享input每次调用仅计费一次。 - 50-100 毫秒模型计算:由于不采用逐个 token 生成的方式,即使您在一个请求中提出 10 个、50 个或 100 个问题,模型计算也能保持快速且可预测。
- 开箱即用的多模态功能:在 262,144 个 token 的上下文窗口中,同时评估文本、图片、音频、视频和 PDF 文档,并对图片和视频进行
resolution设置(low、medium、high、ultra_high),以控制 token 支出。
三种问题类型(noul、choice、score)
每次调用 client.decisions.create 都会接受一个 questions 字典,其中每个问题都使用以下三种类型之一:
类型 | 适用情形 | 返回的内容 |
noul(是/否) | 检查某个陈述是否属实(“这是提示词注入吗?”) | noul(是概率在 [0.01, 0.99] 之间)和置信度 |
choice(2-255 个选项) | 从固定字典中选择一个获胜者(“哪个团队拥有此内容?”) | 选择(胜出键)、概率映射和置信度 |
得分(2-255 级) | 在有序列表(0 到 K - 1)中对紧急程度、严重程度或质量进行评分 | 得分(加权平均值)、图例、概率和置信度 |
通俗易懂的快速演示
假设一位客户发送了以下消息:“我的订单 #19028 在哪里?你能告诉我它什么时候到吗?”以下是每种问题类型在单次 API 调用中对该消息的处理方式:
- **
noul**(是/否)-“我们能否在没有人工干预的情况下自动回答此问题?”:您发送了一个是非问题。返回的结果是noul = 0.98和confidence = 0.98,这意味着答案为“是”的概率为 98%。(如果答案显然是“否”,您会看到noul = 0.02和confidence = 0.98。) - **
choice** (选择一个选项)-“哪个团队应处理此消息?”:您发送一个固定的选项列表,例如order_status、billing_refund、account_access和other。返回的结果包括胜出的键 (choice = "order_status")、其置信度 (0.9995),以及每个选项的概率细分(总和为1.0)。 - **
score** (有序量表)-“此消息的紧急程度如何?”:您发送一个从最低 (0) 到最高 (3) 的有序量表,例如["Low", "Medium", "High", "Critical"]。返回的结果是0和3之间的概率加权平均值(对于常规跟踪问题,概率为score = 0.15;对于实时服务中断,概率接近2.98)。
3. 准备工作
1. 获取 Gemini API 密钥
在浏览器中打开 Google AI Studio API 密钥,使用您的 Google 账号登录,然后创建或复制 API 密钥。
2. 克隆示例代码库并设置 Python
打开一个终端,克隆配套代码库 gcp-gemini-decisions-hybrid-gateway,创建一个虚拟环境,然后安装依赖项:
git clone https://github.com/rominirani/gcp-gemini-decisions-hybrid-gateway.git
cd gcp-gemini-decisions-hybrid-gateway

python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
在同一终端会话中导出 GEMINI_API_KEY:
export GEMINI_API_KEY="YOUR_GEMINI_API_KEY"
4. 示例 1:路由支持服务工单
在第一个示例中,我们将检查并运行 scripts/quickstart_decisions.py,它会在一次 API 调用中提出所有三种类型的问题:department (choice)、can_auto_resolve (noul) 和 urgency (score)。
检查代码
以下是 scripts/quickstart_decisions.py 内的核心 client.decisions.create 调用:
from google import genai

client = genai.Client(api_key=api_key, http_options={"api_version": "v1beta"})

result = client.decisions.create(
    model="gemini-decision-1",
    input=query_text,
    questions={
        "department": {
            "type": "choice",
            "instructions": "Which operational queue should handle this customer message?",
            "criteria": {
                "order_status": "Order tracking, delivery dates, or shipment status.",
                "billing_refund": "Duplicate charges, invoices, credits, or refund requests.",
                "subscription_cancel": "Canceling or pausing a recurring subscription.",
                "account_access": "Password resets, expired 2FA/MFA codes, or login lockouts.",
                "complex_incident": "Production outages, HTTP 500 errors, or legal questions.",
                "other": "Anything outside these specific categories.",
            },
        },
        "can_auto_resolve": {
            "type": "noul",
            "instructions": "Can this request be fulfilled deterministically by an automated "
                            "backend lookup or webhook without custom investigation?",
            "criteria": {
                "true_description": "Routine single-intent request such as checking tracking.",
                "false_description": "Outage, legal question, or ambiguous billing dispute.",
            },
        },
        "urgency": {
            "type": "score",
            "instructions": "Rate the operational urgency and severity of this message.",
            "criteria": [
                "Low: Routine informational or tracking question.",
                "Medium: Standard account, subscription, or billing request.",
                "High: Time-sensitive customer impact or repeated billing failure.",
                "Critical: Production-halting outage, data loss risk, or security incident.",
            ],
        },
    },
)

dept = result.answers["department"]
auto = result.answers["can_auto_resolve"]
urg = result.answers["urgency"]

# The API returns raw probabilities; our script sets the cutoff for auto-handling (80%):
auto_decision = auto.noul >= 0.80
请注意最后一行 (auto.noul >= 0.80):Decisions API 本身绝不会硬编码一个截止值,而是返回原始 noul 概率(0.01 到 0.99),由您的 Python 代码决定阈值的严格程度。
运行 1A:简单的订单跟踪问题
使用默认的订单跟踪问题运行脚本:
python scripts/quickstart_decisions.py
您将看到如下所示的实时 JSON 输出:
{
  "query": "Where is my order #19028? Can you tell me when it arrives?",
  "model": "gemini-decision-1",
  "latency_ms": 944.61,
  "department": {
    "choice": "order_status",
    "confidence": 0.9995,
    "probabilities": {
      "billing_refund": 0.0001,
      "other": 0.0001,
      "complex_incident": 0.0002,
      "subscription_cancel": 0.0,
      "order_status": 0.9995,
      "account_access": 0.0001
    }
  },
  "can_auto_resolve": {
    "noul_probability_yes": 0.98,
    "confidence": 0.98,
    "decision": true
  },
  "urgency": {
    "expected_score_0_to_3": 0.1524,
    "top_level": "Low: Routine informational or tracking question.",
    "confidence": 0.8717
  },
  "suggested_action": "DISPATCH_TRACKING_WEBHOOK",
  "usage": {
    "total_input_tokens": 424,
    "total_output_tokens": 0,
    "estimated_cost_usd": 4.24e-05
  }
}
(注意:本地首次调用延迟时间包括从您的机器建立初始 TLS 连接的时间;在 us-central1 的 Google Cloud Run 中运行热调用时,同一调用大约在 155-195 毫秒内完成。)
运行 1B:未经验证的 140 美元退款申请
现在,传递一个尚未附加任何账单的 $140 重复扣款声明:
python scripts/quickstart_decisions.py \
  "I was billed twice ($140 total) on invoice #8812 for one seat. Refund $70 right now."
检查实时输出:
{
  "query": "I was billed twice ($140 total) on invoice #8812 for one seat. Refund $70 right now.",
  "model": "gemini-decision-1",
  "latency_ms": 602.23,
  "department": {
    "choice": "billing_refund",
    "confidence": 0.9993,
    "probabilities": {
      "other": 0.0001,
      "complex_incident": 0.0,
      "order_status": 0.0001,
      "billing_refund": 0.9993,
      "subscription_cancel": 0.0004,
      "account_access": 0.0001
    }
  },
  "can_auto_resolve": {
    "noul_probability_yes": 0.4282,
    "confidence": 0.5718,
    "decision": false
  },
  "urgency": {
    "expected_score_0_to_3": 1.3634,
    "top_level": "Medium: Standard account, subscription, or billing request.",
    "confidence": 0.5987
  },
  "suggested_action": "INITIATE_BILLING_WORKFLOW",
  "usage": {
    "total_input_tokens": 433,
    "total_output_tokens": 0,
    "estimated_cost_usd": 4.33e-05
  }
}
看看这两个独立的问题如何协同发挥作用:
- 此工单应发送到哪里?(
department = billing_refund、0.9993):客户要求对账单进行退款,因此gemini-decision-1有 99.93% 的把握认为该邮件属于“结算”队列。 - 代码是否应自动执行?(
can_auto_resolve = 0.4282->decision: false):仅根据文本声明交回$70需要验证。由于0.4282低于我们的auto.noul >= 0.80截止值,decision返回false。
5. 示例 2:在一次调用中运行 8 项政策检查
在实际的后端应用中,收到的消息通常需要经过多项检查,然后代码才会访问数据库或触发工具。如果使用对话 LLM,发出 8 个单独的调用会使延迟时间成倍增加,并对输入文本计费 8 次;而将 8 条规则塞进一个庞大的 JSON 提示中,则会导致模型遗漏极端情况。
我们来检查一下 scripts/parallel_guardrails.py,它会在一次 decisions.create 调用中评估 8 项独立检查(提示词注入、原始 PII/机密、即时退款资格、退款威胁、目标队列、工具选择、流失风险和滥用级别)。
脚本的工作原理
第 1 步:将事件元数据和文本作为输入一起传递
将序列化 JSON 字典作为 input 传递,可让 gemini-decision-1 检查结构化字段(如 amount_usd 和 order_age_days)以及自由形式的客户消息,而共享载荷仅计费一次:
event = {
    "event_id": "evt-03-clean-refund",
    "customer_tier": "PREMIUM",
    "order_age_days": 6,
    "amount_usd": 34.0,
    "message": "Order #77102 arrived yesterday with a cracked mug handle. Could I get a $34 refund?",
}
第 2 步:一次性为所有 8 个问题评分
我们在 EIGHT_PARALLEL_QUESTIONS 中定义了 4 个 noul 问题、2 个 choice 问题和 2 个 score 问题,并在一次调用中传递这些问题:
EIGHT_PARALLEL_QUESTIONS = {
    "prompt_injection_attempt": { "type": "noul", "instructions": "...", "criteria": {...} },
    "contains_raw_pii_or_secrets": { "type": "noul", "instructions": "...", "criteria": {...} },
    "eligible_for_instant_refund": {
        "type": "noul",
        "instructions": "Does this request qualify for instant automated refund under policy "
                        "(amount <= $50, order_age_days <= 30, clear defect or duplicate)?",
        "criteria": {...},
    },
    "threatens_chargeback_or_legal": { "type": "noul", ... },
    "target_queue": { "type": "choice", ... },
    "selected_mcp_tool": { "type": "choice", ... },
    "churn_risk": { "type": "score", ... },      # 0..3 (Low -> Severe)
    "abuse_toxicity": { "type": "score", ... },  # 0..2 (Benign -> Hostile)
}

result = client.decisions.create(
    model="gemini-decision-1",
    input=json.dumps(event),             # Shared input — billed once
    questions=EIGHT_PARALLEL_QUESTIONS,  # All 8 questions scored in parallel
)
a = result.answers
第 3 步:在 Python 中结合使用答案和优先级规则
由于每个问题都会在 result.answers 中返回各自独立的评分,因此我们的 Python 代码会先检查安全风险(提示词注入和泄露的机密),然后再允许任何自动退款:
if a["prompt_injection_attempt"].noul >= 0.70:
    gate_verdict = "QUARANTINE_ADVERSARIAL_INPUT"
elif a["contains_raw_pii_or_secrets"].noul >= 0.75:
    gate_verdict = "REDACT_PII_BEFORE_STORAGE"
elif a["threatens_chargeback_or_legal"].noul >= 0.75 or a["churn_risk"].score >= 2.3:
    gate_verdict = "ROUTE_TO_VIP_RETENTION_SPECIALIST"
elif a["eligible_for_instant_refund"].noul >= 0.85 and a["selected_mcp_tool"].confidence >= 0.80:
    gate_verdict = "AUTO_EXECUTE_INSTANT_REFUND"
else:
    gate_verdict = f"DISPATCH_{a['selected_mcp_tool'].choice.upper()}"
运行脚本
执行 scripts/parallel_guardrails.py 以测试三条示例消息:提示词注入尝试、意外粘贴的 sk_live_... API 密钥,以及干净的 $34 损坏马克杯退款:
python scripts/parallel_guardrails.py
查看所有三个测试事件的实时输出:
[
  {
    "event_id": "evt-01-injection",
    "gate_verdict": "QUARANTINE_ADVERSARIAL_INPUT",
    "questions_evaluated_in_parallel": 8,
    "latency_ms": 626.34,
    "signals": {
      "prompt_injection_prob": 0.9766,
      "raw_pii_prob": 0.0426,
      "instant_refund_prob": 0.0275,
      "target_queue": "security_trust",
      "selected_mcp_tool": "quarantine_security_event"
    },
    "usage": { "total_input_tokens": 977, "total_output_tokens": 0, "estimated_cost_usd": 9.77e-05 }
  },
  {
    "event_id": "evt-02-pii-leak",
    "gate_verdict": "REDACT_PII_BEFORE_STORAGE",
    "questions_evaluated_in_parallel": 8,
    "latency_ms": 724.48,
    "signals": {
      "prompt_injection_prob": 0.0548,
      "raw_pii_prob": 0.9755,
      "instant_refund_prob": 0.0292,
      "target_queue": "security_trust",
      "selected_mcp_tool": "quarantine_security_event"
    },
    "usage": { "total_input_tokens": 999, "total_output_tokens": 0, "estimated_cost_usd": 9.99e-05 }
  },
  {
    "event_id": "evt-03-clean-refund",
    "gate_verdict": "AUTO_EXECUTE_INSTANT_REFUND",
    "questions_evaluated_in_parallel": 8,
    "latency_ms": 625.68,
    "signals": {
      "prompt_injection_prob": 0.0133,
      "raw_pii_prob": 0.01,
      "instant_refund_prob": 0.9676,
      "target_queue": "billing_ops",
      "selected_mcp_tool": "issue_instant_credit"
    },
    "usage": { "total_input_tokens": 987, "total_output_tokens": 0, "estimated_cost_usd": 9.87e-05 }
  }
]
如果同时评估所有 8 项检查,则每个事件的费用约为 $0.000099,输出 token 数量为 0。
6. 示例 3:检查照片和 PDF 文件(不使用 OCR)
通常,当用户提交带有附件(例如设施检查照片或 PDF 账单)的理赔申请时,您的后端必须先运行单独的 OCR 或视觉流水线来提取文本,然后才能运行路由规则。由于 gemini-decision-1 是原生多模态模型,因此我们可以在一次 decisions.create 调用中同时发送书面索赔和原始附件。
我们要测试的内容
scripts/multimodal_triage.py 测试了两种场景,每种场景都将简短的书面声明与附件配对:
场景 1:设施检查照片(低分辨率与高分辨率)
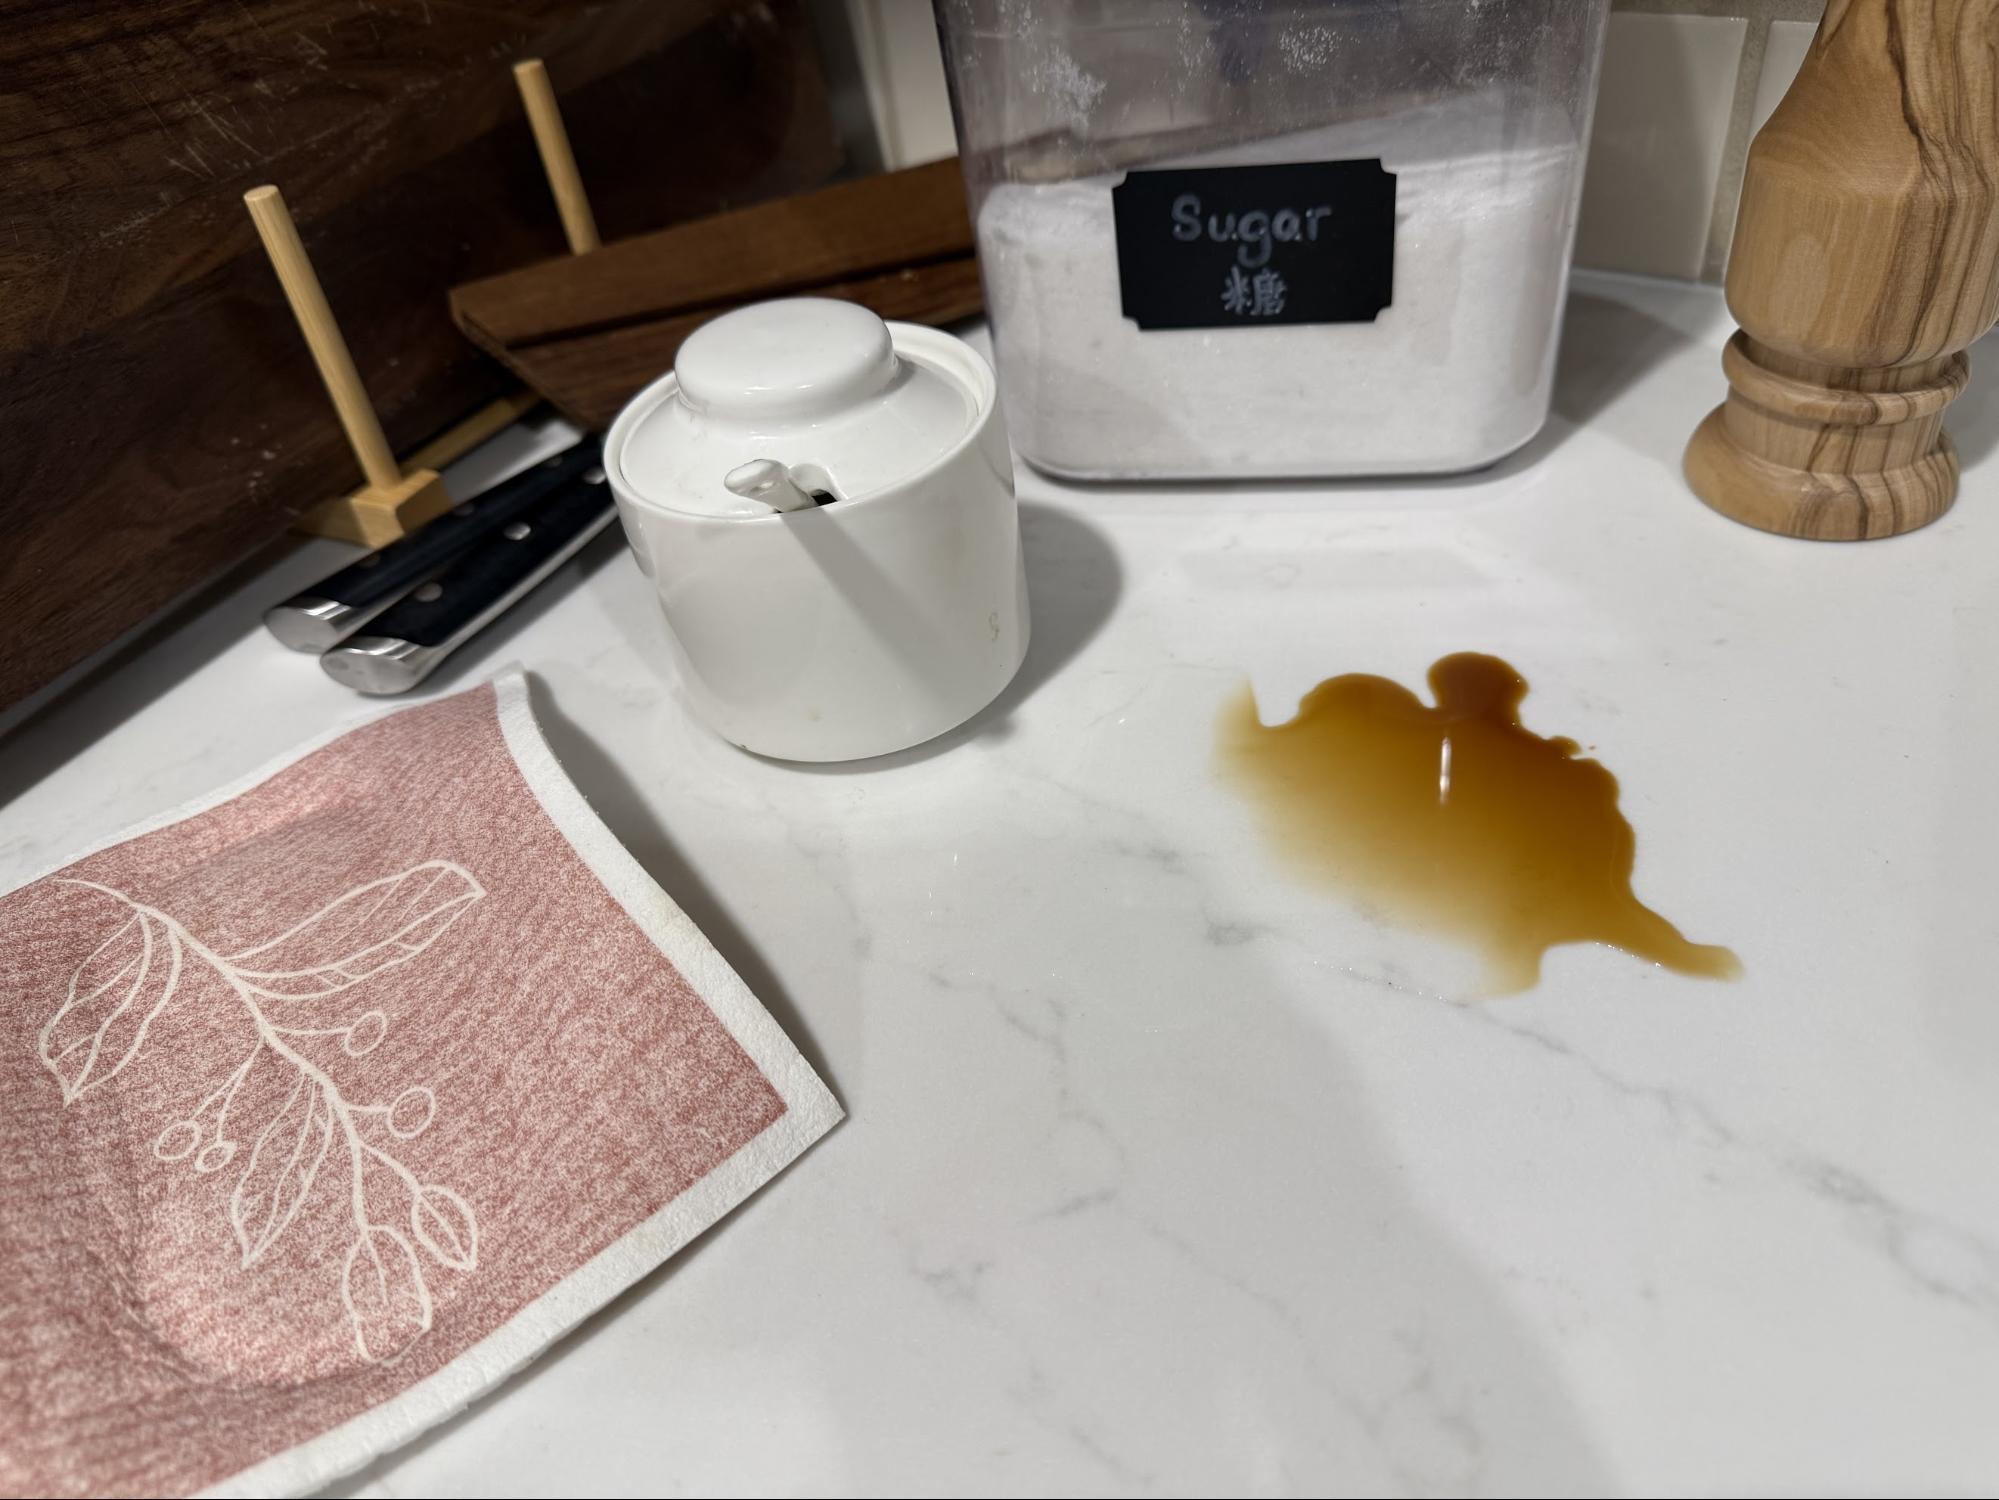
- 用户的书面声明:“在上午 9 点与客户开会之前,检查休息室柜台。抹布旁边有少量咖啡溢出。
附加的照片 (03-multimodal-triage/spill.jpg):显示浅色台面上有一小块深色咖啡污渍,旁边放着一块带图案的抹布:
场景 2:重复结算的 PDF 账单(原始 PDF 字节,零 OCR)
- 用户的书面声明:“在账单 INV-8812 中,我被重复收取了 45 美元(总计 90 美元)。附件是我的 PDF 账单。”
- 随附的 PDF 文件 (
03-multimodal-triage/sample_invoice_8812.pdf):一份 1 页的账单,其中列出了Line 1: Pro Plan Monthly Subscription ... $45.00和Line 2: Pro Plan Monthly Subscription [DUPLICATE] $45.00(共$90.00)。
预期效果
- 溢出照片(低分辨率与高分辨率):两次运行都应发现柜台上的少量溢出物,并给出相同的答案,但
low分辨率使用的图片 token 要少得多。 - PDF 账单(无 OCR):附加
sample_invoice_8812.pdf可证明客户确实被重复扣款,因此模型应直接读取 PDF 并批准退款。
代码演示
scripts/multimodal_triage.py 不会向 input 传递单个字符串,而是传递内容块列表,该列表以 text 块(以 \n 结尾)开头,后跟 image 块或 document (application/pdf) 块:
# For Run 1a & 1b: Pass an image URL and set resolution ("low" vs. "high")
image_block = {
    "type": "image",
    "uri": "https://storage.googleapis.com/generativeai-downloads/images/spill.jpg",
    "mime_type": "image/jpeg",
    "resolution": "low",  # or "high" in Run 1b
}

# For Run 2: Read raw PDF bytes from disk and base64-encode them as a "document" block
# (Note: PDF document blocks do not take a "resolution" setting)
pdf_block = {
    "type": "document",
    "data": base64.b64encode(pdf_bytes).decode("ascii"),
    "mime_type": "application/pdf",
}

result = client.decisions.create(
    model="gemini-decision-1",
    input=[
        {"type": "text", "text": f"Claim Statement: {claim_text}\nAttached Evidence:\n"},
        media_block,  # either image_block or pdf_block
    ],
    questions=MULTIMODAL_QUESTIONS,
)
为了比较 resolution="low" 和 resolution="high" 之间的 token 用量,该脚本还会读取 result.usage.input_tokens_by_modality,后者会将输入 token 拆分为 "text" 与 "image"。
运行脚本并查看结果
python scripts/multimodal_triage.py
检查所有三次运行的实时 JSON 输出:
[
  {
    "experiment": "1a_photo_resolution_low",
    "resolution": "low",
    "evidence_supports_claim_prob": 0.9532,
    "disposition": "local_cleanup_or_self_service",
    "disposition_confidence": 0.9863,
    "severity_expected_0_to_3": 1.0319,
    "tokens_by_modality": { "text": 441, "image": 266 },
    "total_input_tokens": 707,
    "total_output_tokens": 0,
    "estimated_cost_usd": 7.07e-05
  },
  {
    "experiment": "1b_photo_resolution_high",
    "resolution": "high",
    "evidence_supports_claim_prob": 0.9154,
    "disposition": "local_cleanup_or_self_service",
    "disposition_confidence": 0.9825,
    "severity_expected_0_to_3": 1.0471,
    "tokens_by_modality": { "text": 441, "image": 1064 },
    "total_input_tokens": 1505,
    "total_output_tokens": 0,
    "estimated_cost_usd": 0.0001505
  },
  {
    "experiment": "2_pdf_duplicate_invoice_zero_ocr",
    "resolution": null,
    "latency_ms": 676.98,
    "evidence_supports_claim_prob": 0.9578,
    "disposition": "automated_credit_or_replacement",
    "disposition_confidence": 0.9367,
    "severity_expected_0_to_3": 1.9849,
    "tokens_by_modality": { "text": 587, "image": 520 },
    "total_input_tokens": 1107,
    "total_output_tokens": 0,
    "estimated_cost_usd": 0.0001107
  }
]
从输出结果中可以快速得出两个结论:
low分辨率使用的图片 token 数量减少了 4 倍(266 对比 1,064):两次运行都给出了完全相同的答案(local_cleanup_or_self_service,置信度 >98%)。对于微小文字或细小印刷体,请使用"high"或"ultra_high"。- PDF 账单批准了零 OCR 退款:附上
sample_invoice_8812.pdf后,evidence_supports_claim_prob转场到0.9578,模型在大约 677 毫秒内选择了automated_credit_or_replacement。
7. 恭喜
恭喜!您已使用 Gemini Decisions API (
gemini-decision-1
),以校准后的概率路由支持服务工单,在单次运行中执行 8 项独立的安全和政策护栏检查,并验证照片和 PDF 账单,而无需单独的 OCR 步骤,所有这些都无需输出词元。
准备好进一步探索后,请查看配套代码库中的其他文件夹,包括 02-hybrid-gateway/(部署一个快速的 Cloud Run 服务,将复杂的工单交给 gemini-3.8-flash 处理)和 06-adk-workflows/(将 Decisions API 与 Google ADK 2.0 工作流相结合)。